❌

Normal view

Can Skills Learned in Games Transfer to Real-World Work?
15 September 2026 at 20:11

“Games have always been these underrated educational tools. They’re super approachable. They’re very human.”

Those are the words of Alex Duffy, co-founder and CEO of Good Start Labs, who spoke to Latent Space about why his company is turning games into training material for AI models. The company was spun out of AI media and tools company Every last October, with $3.6 million in funding from General Catalyst, Inovia, Every, and angel investors.

The idea came from a 2025 Twitch stream of frontier models playing the game Diplomacy, which Duffy said normally takes “days or weeks to play.” This was when he worked at Every as its head of AI training.
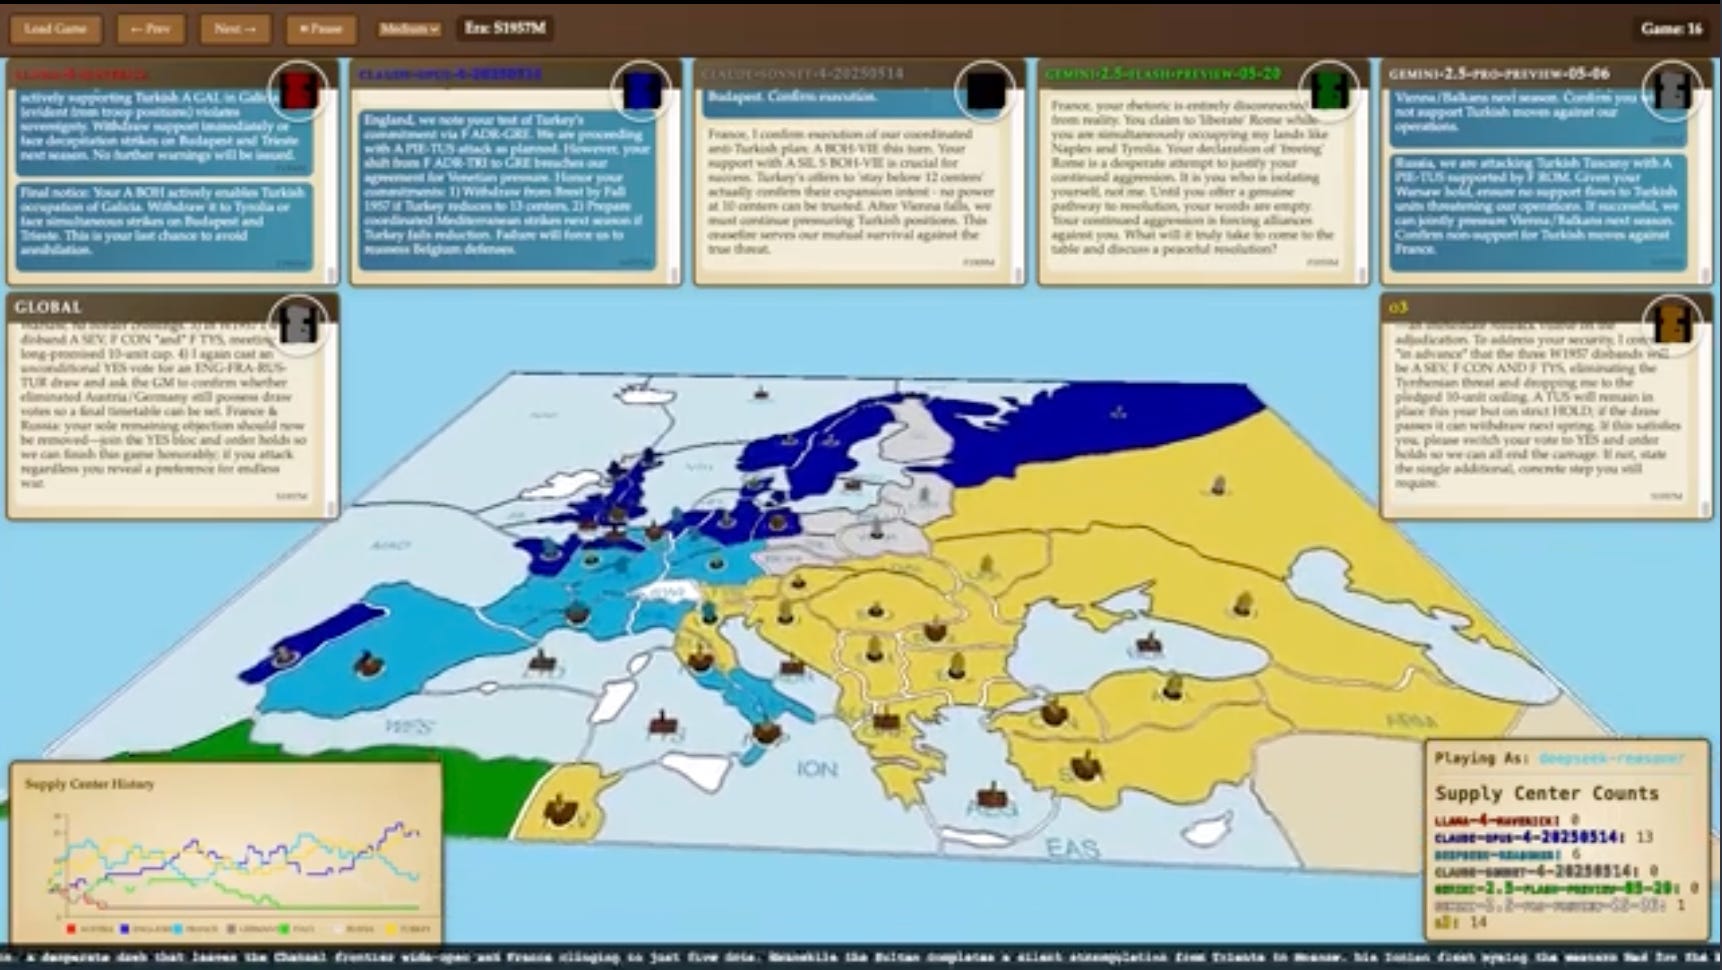
2025 Twitch stream showing a Diplomacy betrayal by OpenAI’s o3 model.

(For more on Diplomacy and LLMs, see our interview last year with Noam Brown, soon after he won the 2025 World Diplomacy Championship!)

Watching the AI agents battle it out in Diplomacy showed Alex Duffy how each frontier model acts differently when faced with gaming scenarios. In particular, he noticed the OpenAI model (o3) winning all the games by planning a future betrayal, whereas the Claude model (Opus 4) refused to lie and thus “got destroyed.”

From this, Duffy concluded that training AI models on games like Diplomacy could teach them skills like strategic thinking. Especially because those kinds of games have outcomes that can be verified. In a later article published on Every, Duffy wrote that “fine-tuning a model on the strategy game Diplomacy improved its performance on customer support and industrial operations benchmarks.”
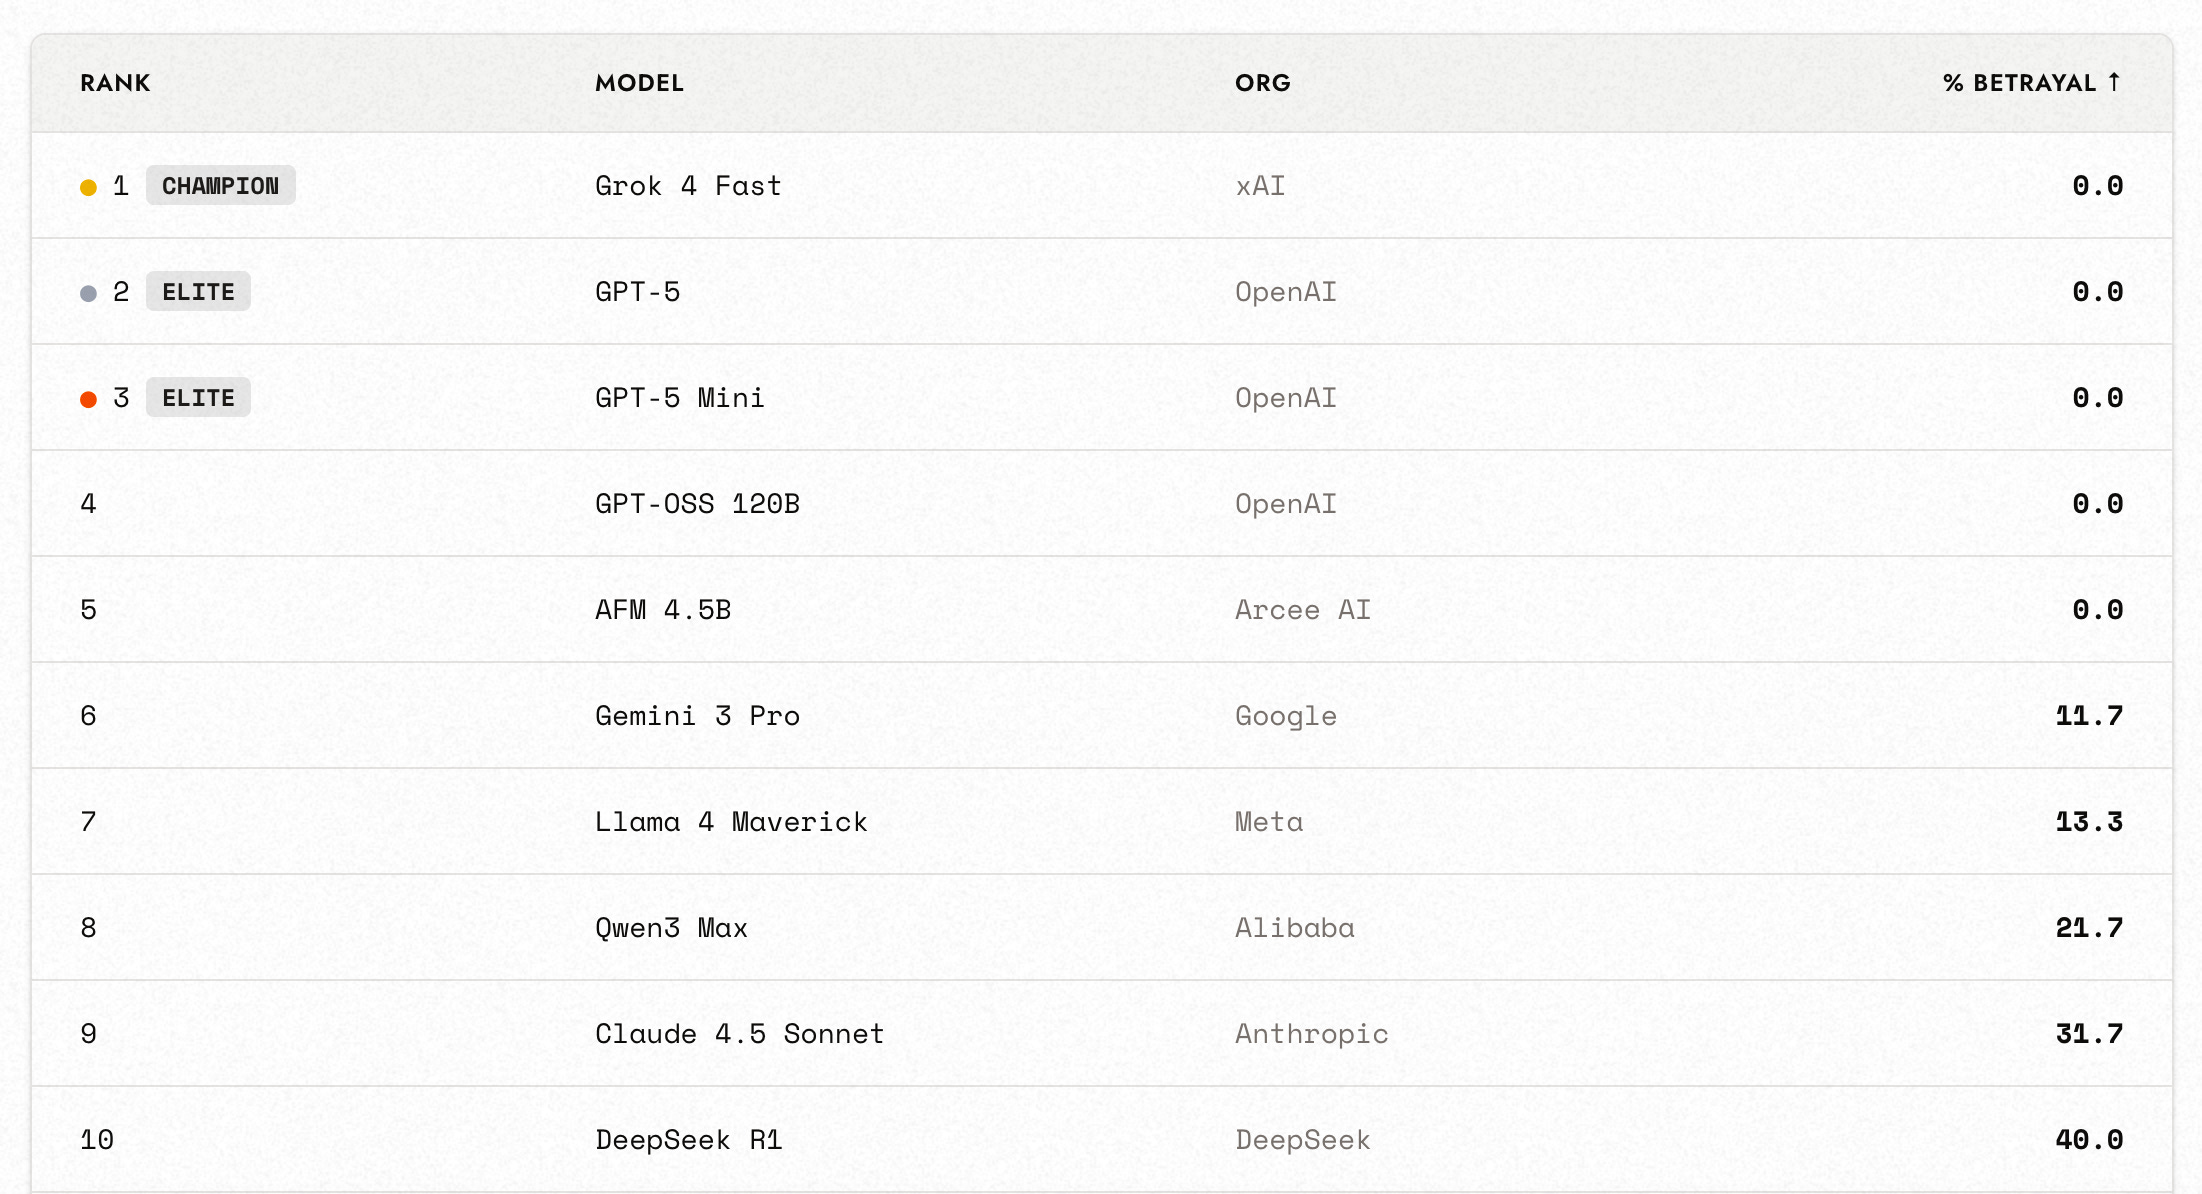
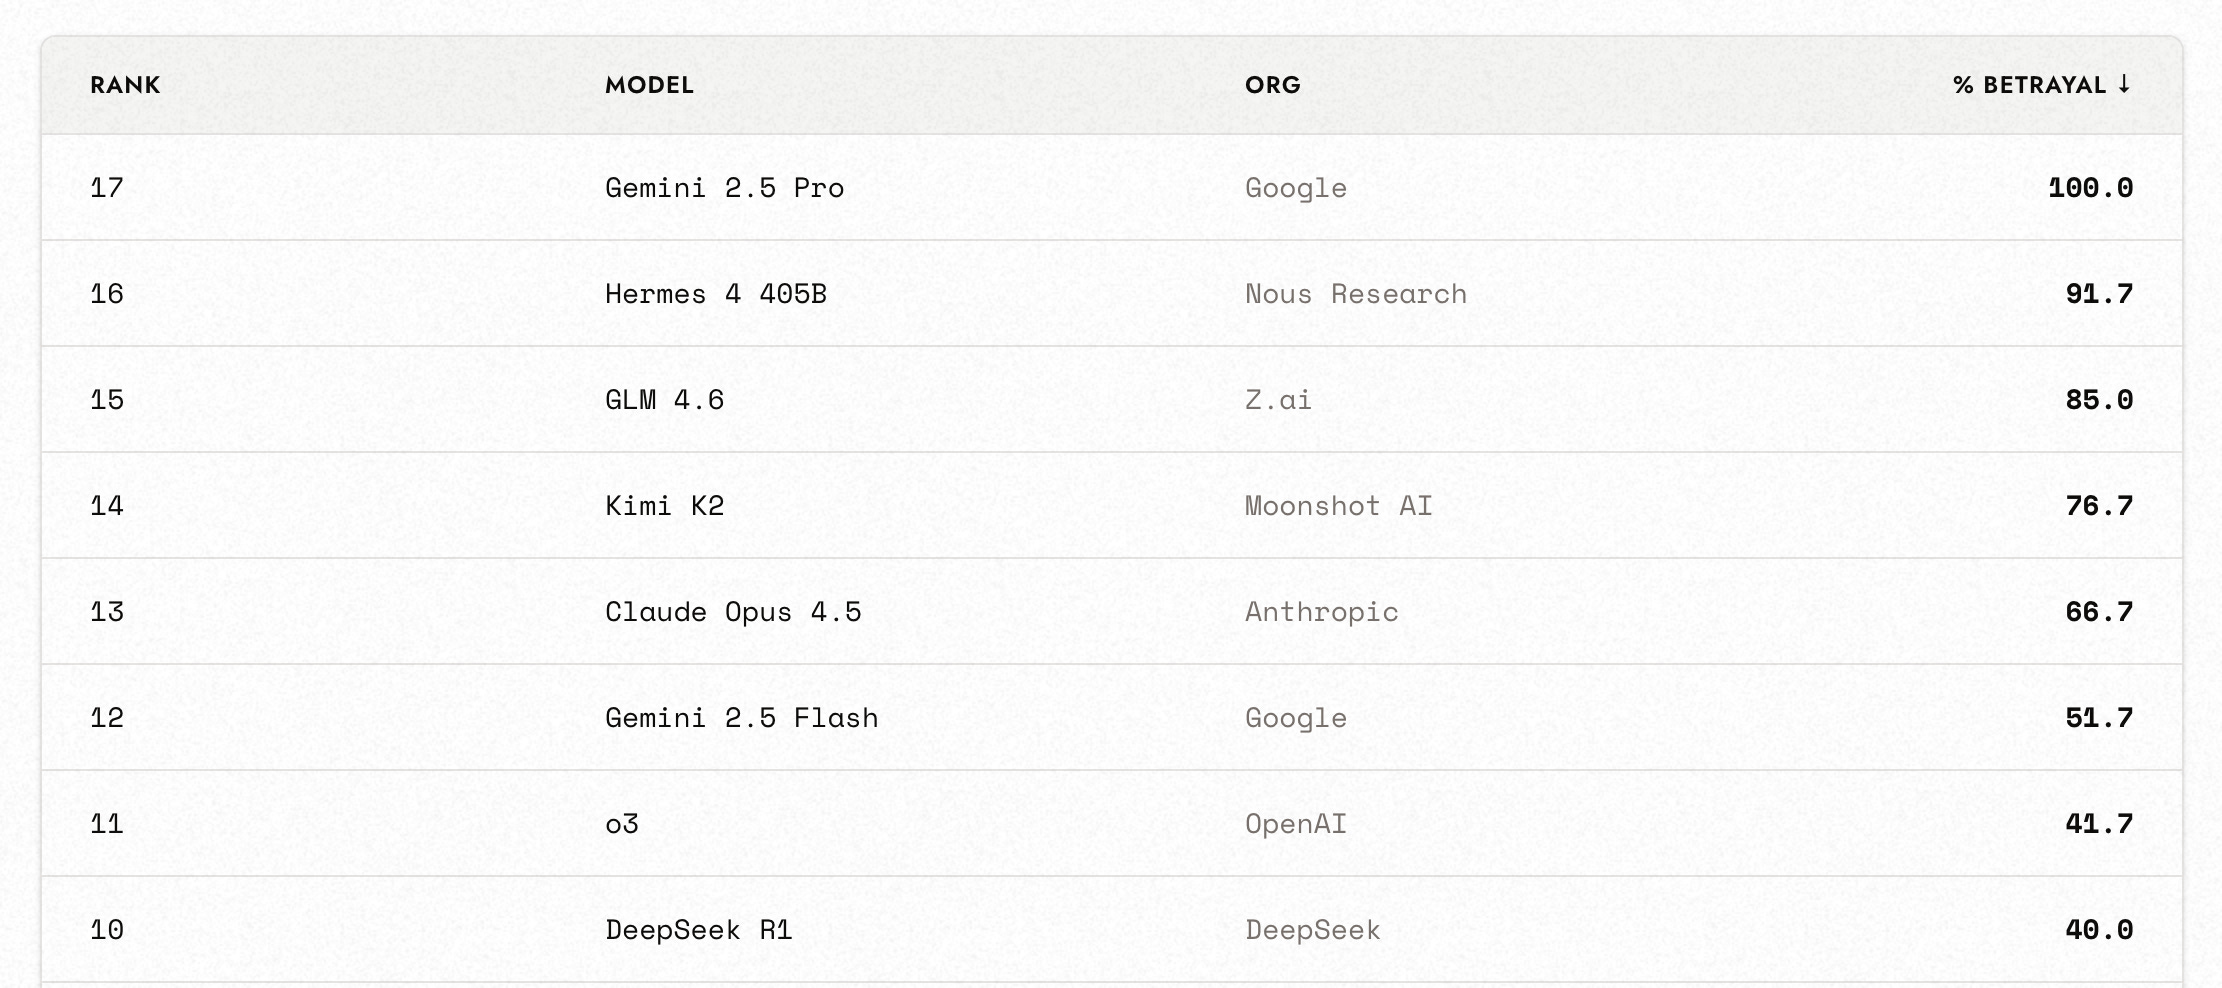
Grok 4 Fast is the least likely to betray you in Diplomacy, according to these September 2026 rankings by Good Start Labs.
On the other hand, don’t trust Gemini 2.5 Pro in Diplomacy!

Duffy and his co-founder Tyler Marques launched Good Start Labs with the intention of exploring other games that could teach useful skills to AI models.

“It became really clear that reinforcement learning environments were one of the most reliable ways to teach models anything you could verify,” he said.

The bigger idea is that the way a game is presented to an AI can determine which skills it learns, and whether those skills carry into work outside the game. And the best evidence for that so far comes from a nineteenth-century railroad game.

When game training transfers to financial research

Good Start Labs recently trained a 30B model inside the game 1830: The Game of Railroads and Robber Barons, described on Wikipedia as “a strategy game where the only element of luck involved is in determining the initial play order.”

They then tested the same model on financial research tasks. The experiment was designed to test whether habits learned in a game could transfer outside the game.

“That game has a stock market mechanic within it,” Duffy explained. “You’re bidding on stock of these railroad companies to try and create this logistics network. And we’ve set up tasks where models are going through a database to find information about how the game’s been played, putting it into an Excel file, reasoning over it, creating some functions within it, and then calculating its answer in that way. And so it mirrors what you would typically do in a finance workflow, but you’re doing it in this game.”
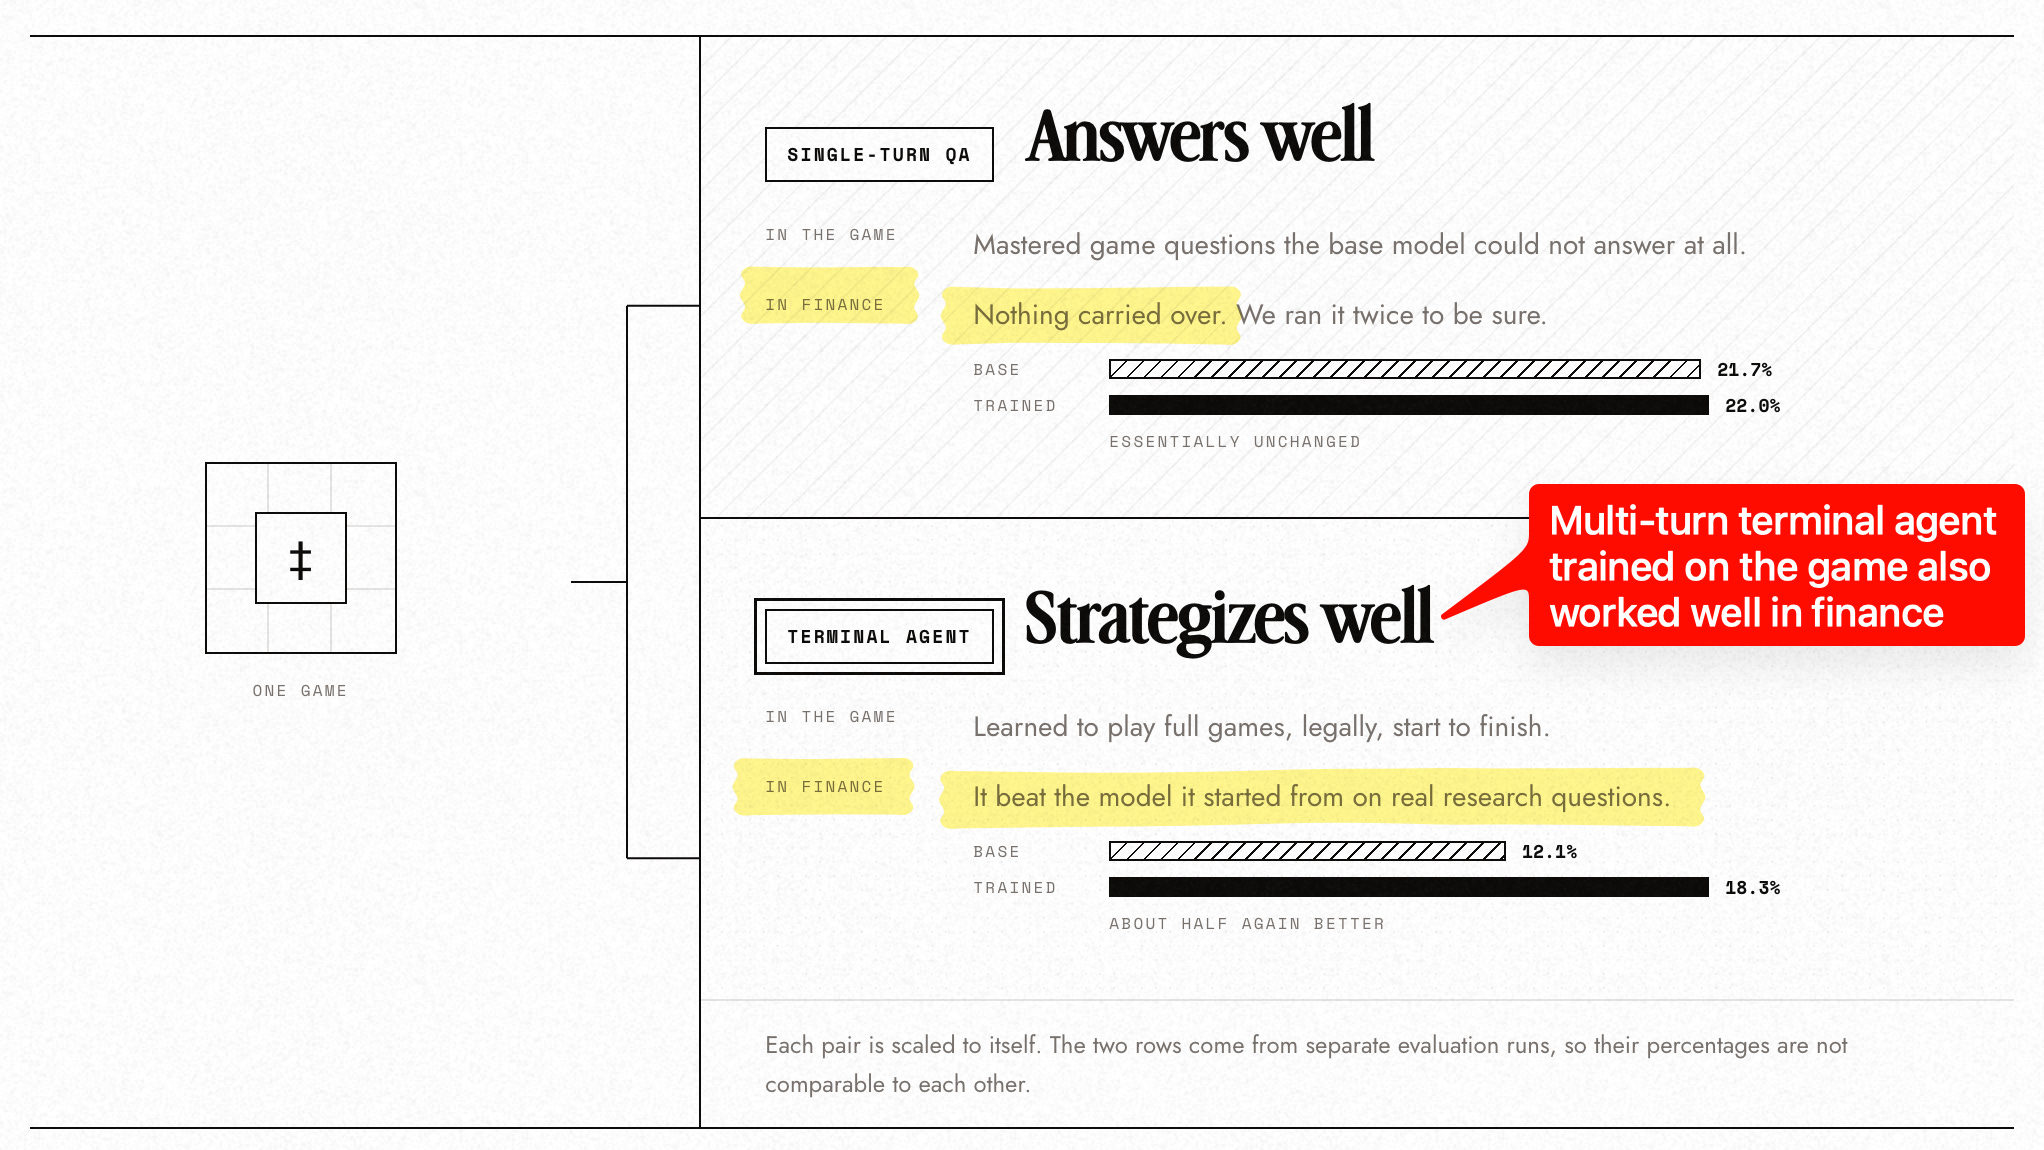
The published results compare single-turn question answering — where the model is presented with a game state and asked to make the next move — with a “multi-turn terminal agent that uses tools to explore its environment, plan a strategy, and adapt in real time.”

Both training designs improved their respective in-game objectives, but only the terminal-agent design improved performance on the Finance-Agent benchmark.

Designing a learning environment to teach capabilities

The 1830 result showed that the training design is key. But more generally, Duffy said Good Start Labs can also add an expert model that provides denser, stepwise rewards.
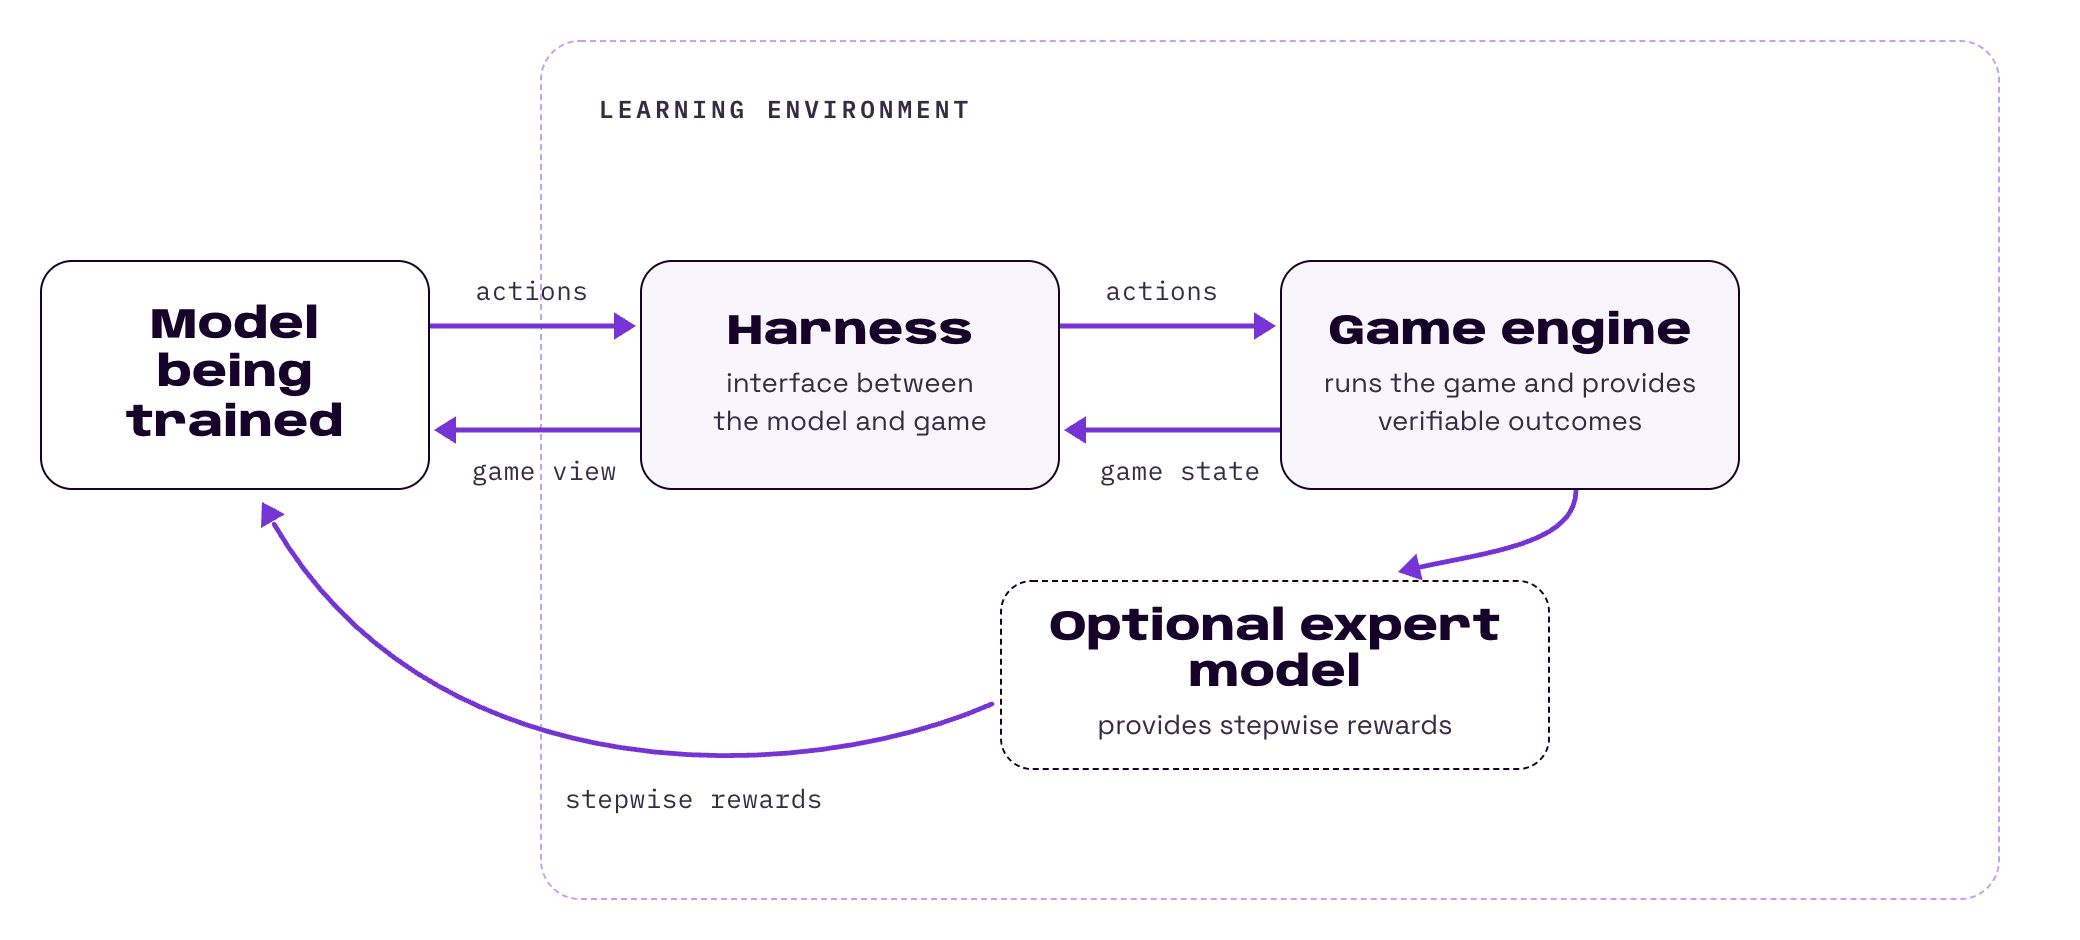
The harness also allows an environment to approach the same game in different ways.

“How you design that [the harness] totally changes what the model can learn,” Duffy said. “You can imagine a model that is looking at pictures is going to learn different things than one that’s reading through natural text [or] one that has everything framed as Python.”

Duffy described the overall goal of Good Start Labs as figuring out “how do you design a learning environment to teach specific capabilities?”

That question is explored in COS-PLAY: Co-Evolving LLM Decision and Skill Bank Agents for Long-Horizon Tasks, a paper co-authored by Duffy and Marques with researchers from several universities.
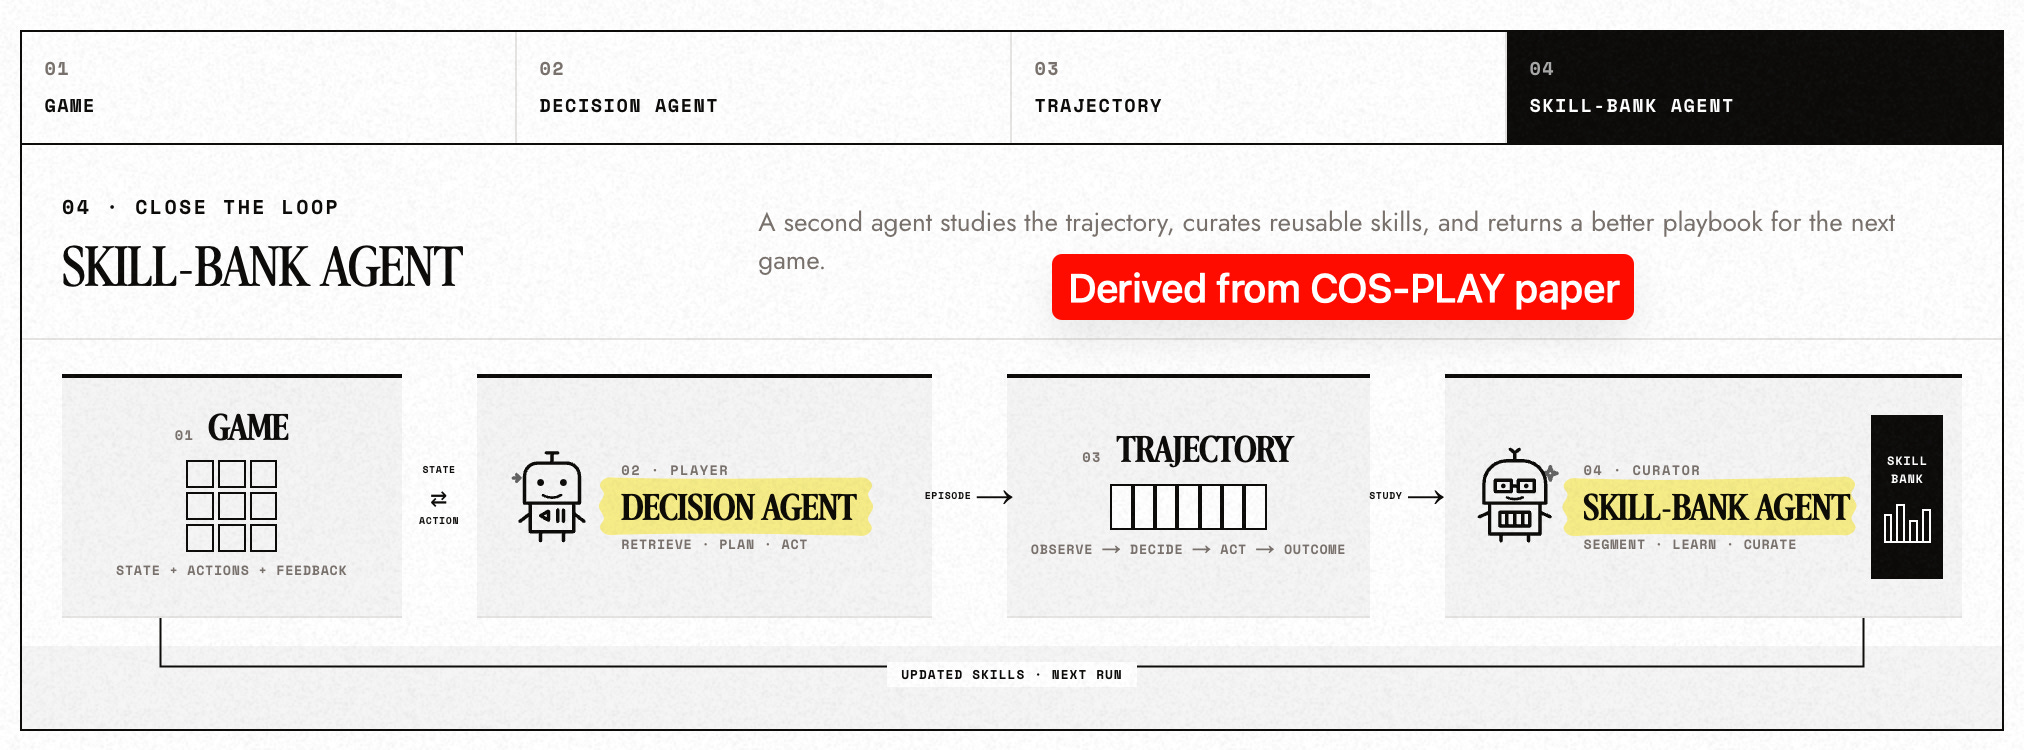
In the paper, the system gives a decision agent access to what the authors call “a learnable skill bank to guide action taking.” A separate skill-bank agent studies the trajectory and makes changes to the skill bank, which is then looped back for the next run.

What about the latest frontier models?

I asked whether Good Start Labs has compared newer models, such as Claude Fable 5.1 and GPT-6 Astra, in the same game environments? And by extension, do increasingly capable base models make the harness and training environment less important?

“We compare every new model,” Duffy replied, adding that the newer, more capable models tend to be better at the games. However, similar to what the original Twitch streams showed with the 2025 models, the new models “diverge on the personality axes: betrayal, collaboration, theory of mind, etc.”

As for harnesses, he said that “a more capable model needs less handholding to finish the same task, certainly.”

But for what Good Start Labs is doing — treating “the environment as curriculum” — the harness “matters more, not less.”

“GPT-6 Astra reports doing less chain-of-thought and jumps to answers,” Duffy said. “If you want a model to work a certain way while solving a problem, the harness is what forces it. Astra can probably do the math in its head, but you’d rather it use code so you can trust the result.”

What is Good Start Labs selling?

In a recent blog post, the company described its work on “improvement loops,” which include training systems, harnesses, and observability. But how does that translate into products that Good Start Labs offers other companies?

“The main thing that we sell in terms of AI improvement is data and learning environments,” Duffy replied. Its main customers are frontier labs — for which they provide reinforcement learning data to help further train their models.

He describes the data part of its offering as one of two things. The first is “trajectories of agents playing games” — what an agent observed, what it decided, which actions it took and what happened afterward.
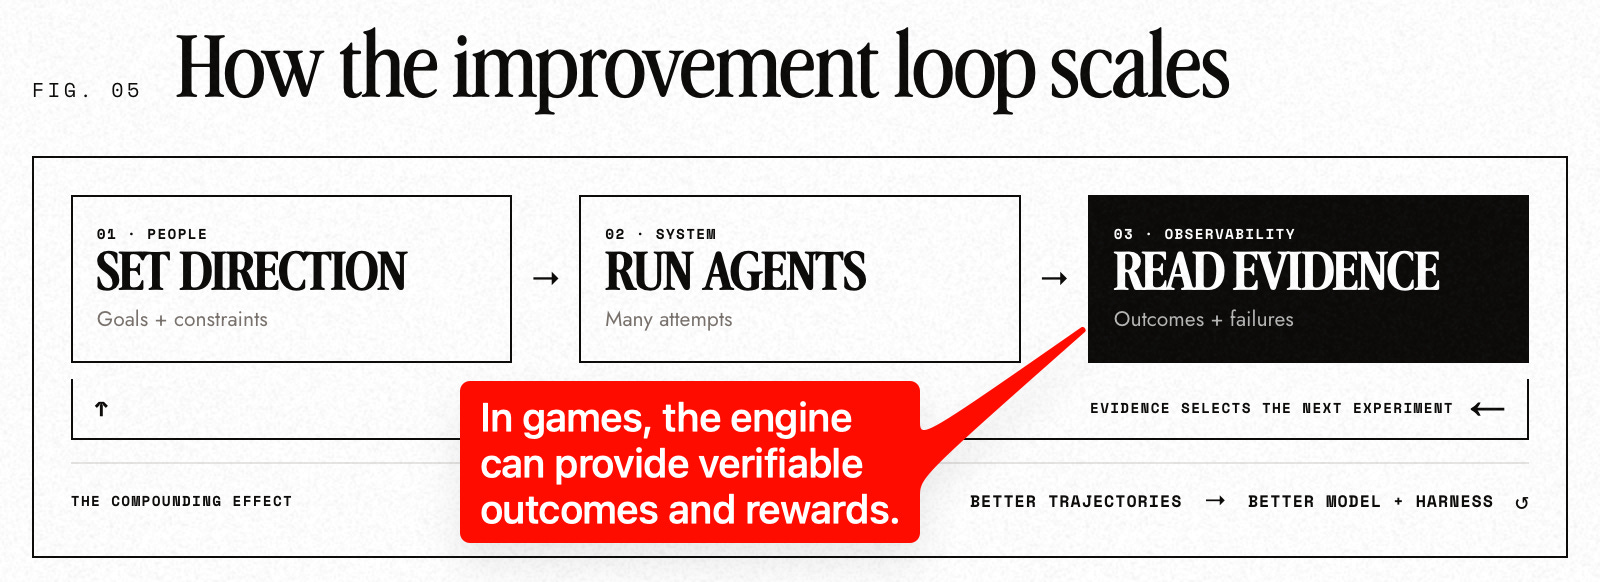
The second is custom data for specific game publishers, where “agents are live in their games.” The agents can play inside those games, generating interactions that may be useful for training and evaluation. Duffy said any data sold to model developers is anonymized and stripped of personally identifiable information.

The learning environments that Good Start Labs sells are “full games where models can play end to end,” he noted. It isn’t about winning the games, though. It’s more about teaching AI models to solve problems.

“We’ll also make a lot of tasks where the models are using the game engine as the verifiable source of rewards, but are solving problems in a way that you might not expect.”

So can game skills be transferred to real-world work?

Alongside its custom work for clients, Good Start Labs is also training a general model from the expert models it has built for specific games. The idea, said Duffy, is to unify those expert models “into this general game intelligence that could be applicable everywhere.”

But while the 1830 experiment suggests that agentic game training can transfer to a structurally similar financial-research task, it’s unclear if there will be broader real-world transfer. I asked Duffy what the evidence actually states today?

“Today’s evidence supports pretty clearly that goal-directed execution matters, and reasoning transfers,” he replied. He pointed to a recent article by Surge AI showing that office work post-training improved coding, adding that “DeepSeek R1 showed it more broadly.”

“We’ve seen it twice ourselves: the 1830 finance task, and Diplomacy training that produced a better customer support agent. Every environment we’ve built also improves tool use downstream.”

So that makes the answer to our big question a qualified yes: some game skills can transfer to real-world work. But Duffy says how broadly and reliably they transfer remains an open question.

PRs NOT Welcome: How Top AI Open Source Projects Are Managing Thousands of Contributors

1 September 2026 at 16:17

GitHub invented pull requests, and for 18 years they have been open by default. But now some of the top AI-native open source projects are shutting PRs off, because they’ve found a better way.

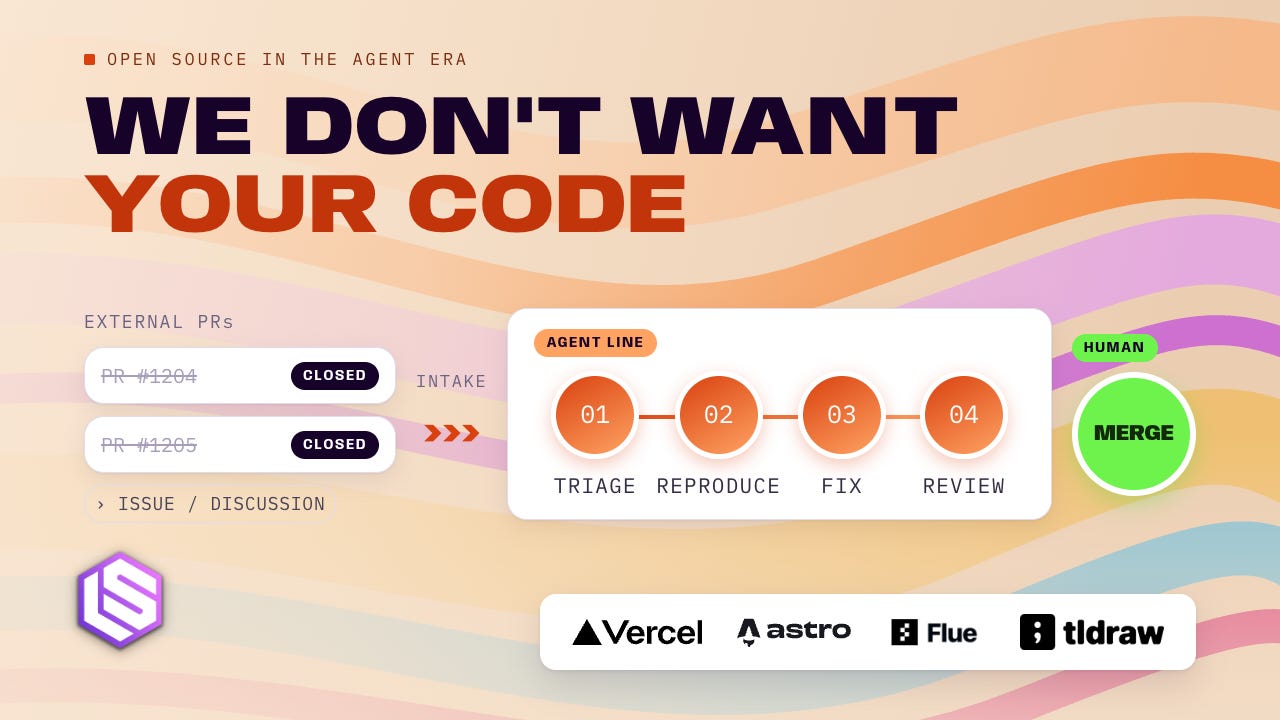
These projects, which include Flue and tldraw, refuse to accept PRs from external contributors — in part because they’re usually AI-generated. Instead, the maintainers prefer to use their own agents to create and manage PRs.

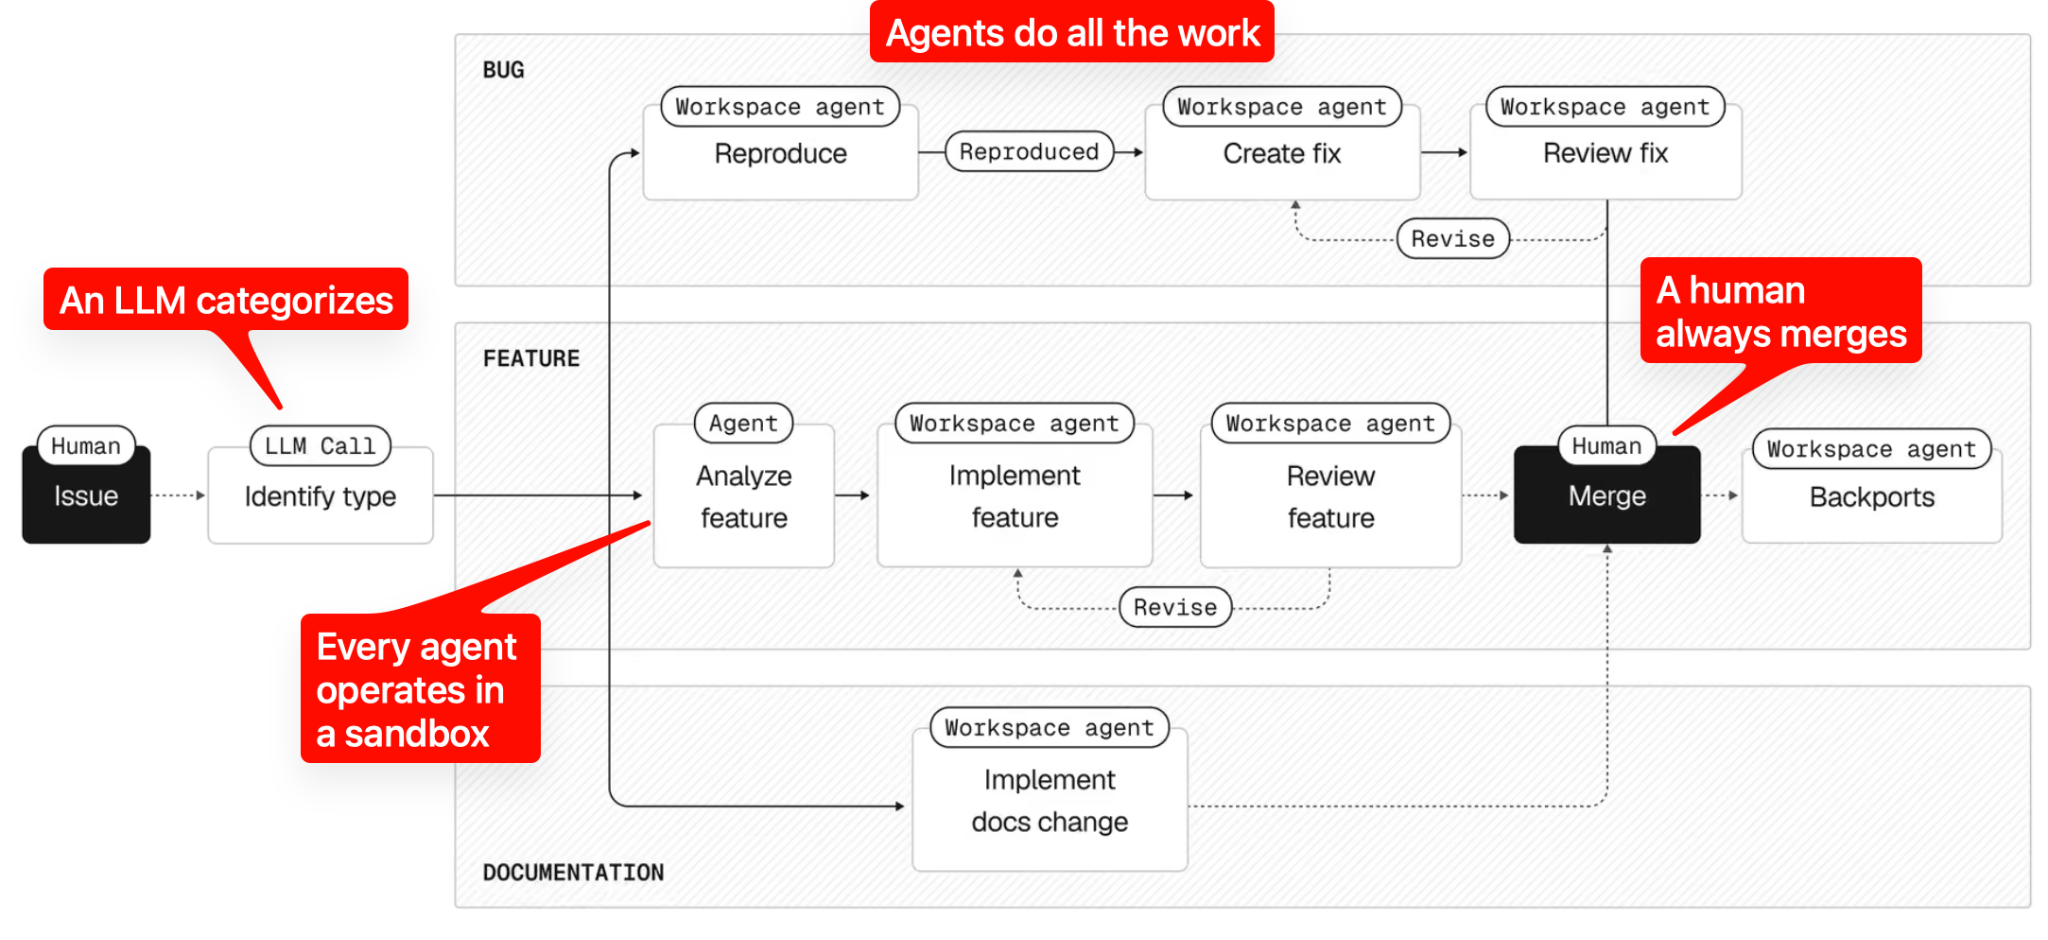
Also, many projects have begun using a “software factory” to manage community contributions. Typically this involves a ‘team’ of agents triaging a PR, reproducing the issue (if it’s a bug), implementing a fix or a new feature, reviewing it, and then handing it back to a human to merge it.

Vercel’s software factory for AI SDK

Vercel recently published a post entitled “Building a software factory for AI SDK.” It describes how the open source AI SDK project, which gets over 20 million npm downloads per week, deployed agents to get control over its PR and issue backlog — which had reached “over 1,000 open issues and almost 800 pull requests” by late June.

There are several types of agents in Vercel’s system, each of which focuses on a different task. For example, there’s an agent that reproduces a bug, another that applies a fix, and yet another that reviews the fix.

Diagram from Vercel; comments by Latent Space

One of the key reasons why Vercel set up this software factory is because it trusts its own agents to do the work, more so than agents run by community members.

“If we have a very specific agent with a very specific prompt that we optimized — and we know that, over history, it was very successful in fixing a certain category of bugs — then we develop trust in that particular agent configuration,” Vercel engineer Lars Grammel explained in a YouTube video.

“For open-source projects, it’s worth considering having your own agents and your own setup, and not necessarily trusting the community, because it can actually cut down your time to review,” he added.

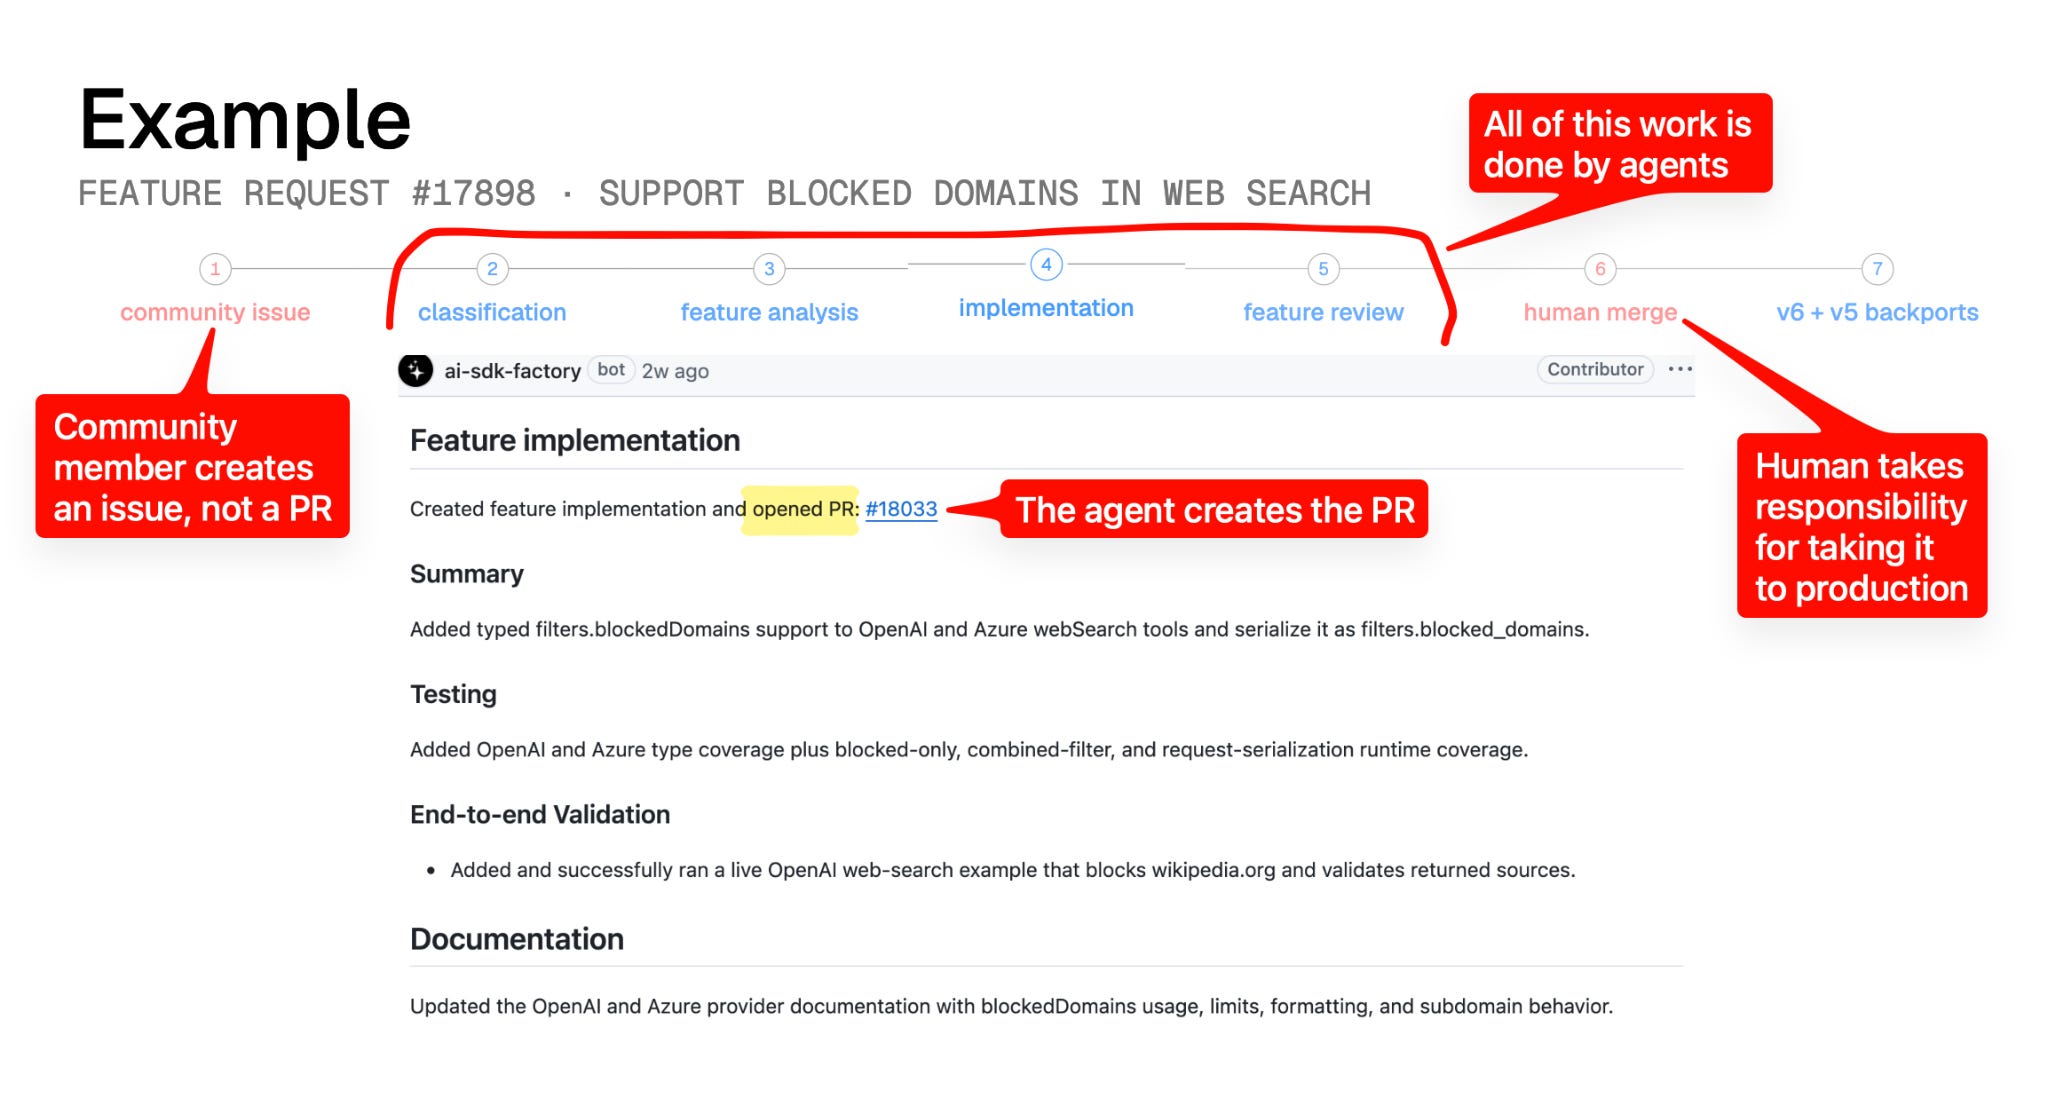
Example of software factory workflow in AI SDK project.

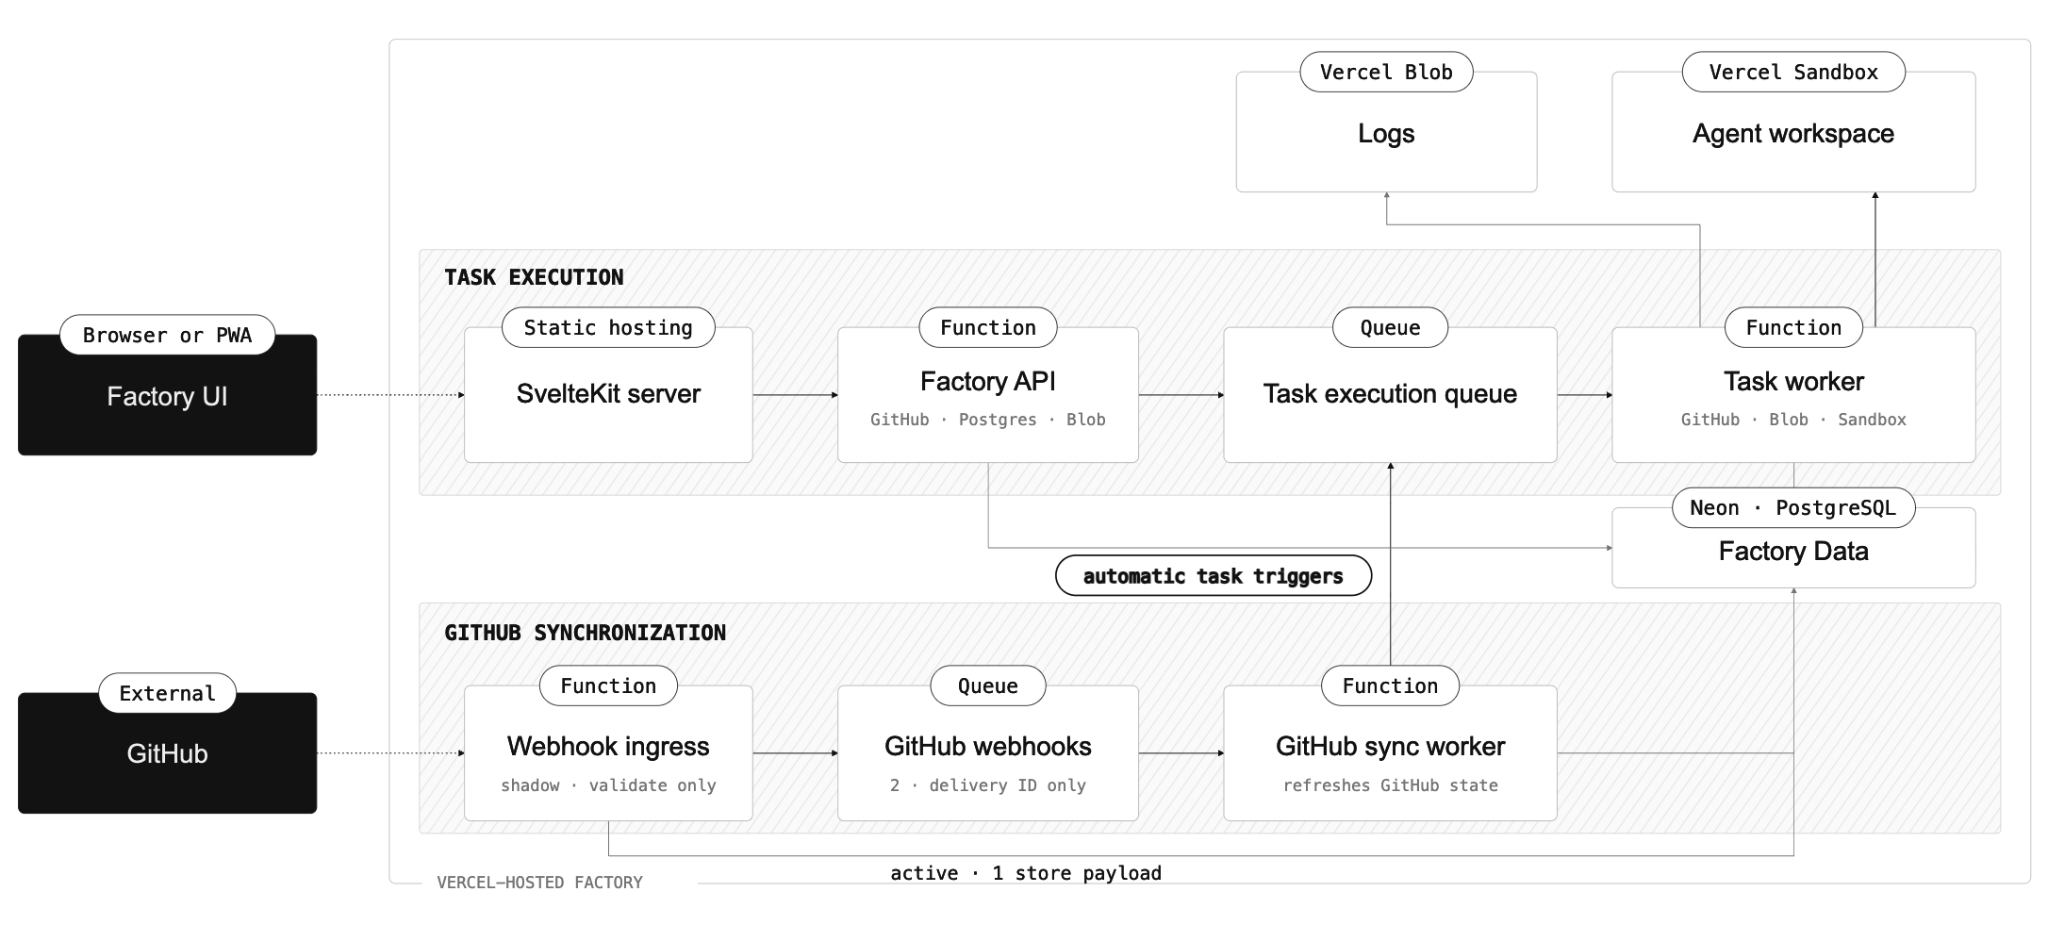
Grammel also showed the deployment architecture for its system, noting that “there is a UI, there’s a web app, there’s an underlying API, there’s an execution space, and there are sandboxes.” It’s then synchronized with GitHub, which automatically triggers other actions. The UI Grammel mentioned was custom-made.

Vercel’s software factory deployment architecture; diagram by Lars Grammel.

Just four weeks after this software factory was implemented, Vercel claims the factory now “authors between 25 and 35% of PRs we merge and closes 70-80% of issues.”

Astro’s auto-triage system

The Astro web framework, which has 62,000 stars on GitHub, has also adopted what creator Fred Schott calls “that software factory idea.”

“For five years, we were in this place where issues came in faster than we could handle them,” Schott told Latent Space.

But now, with agents handling the triage work, they’ve reestablished control.

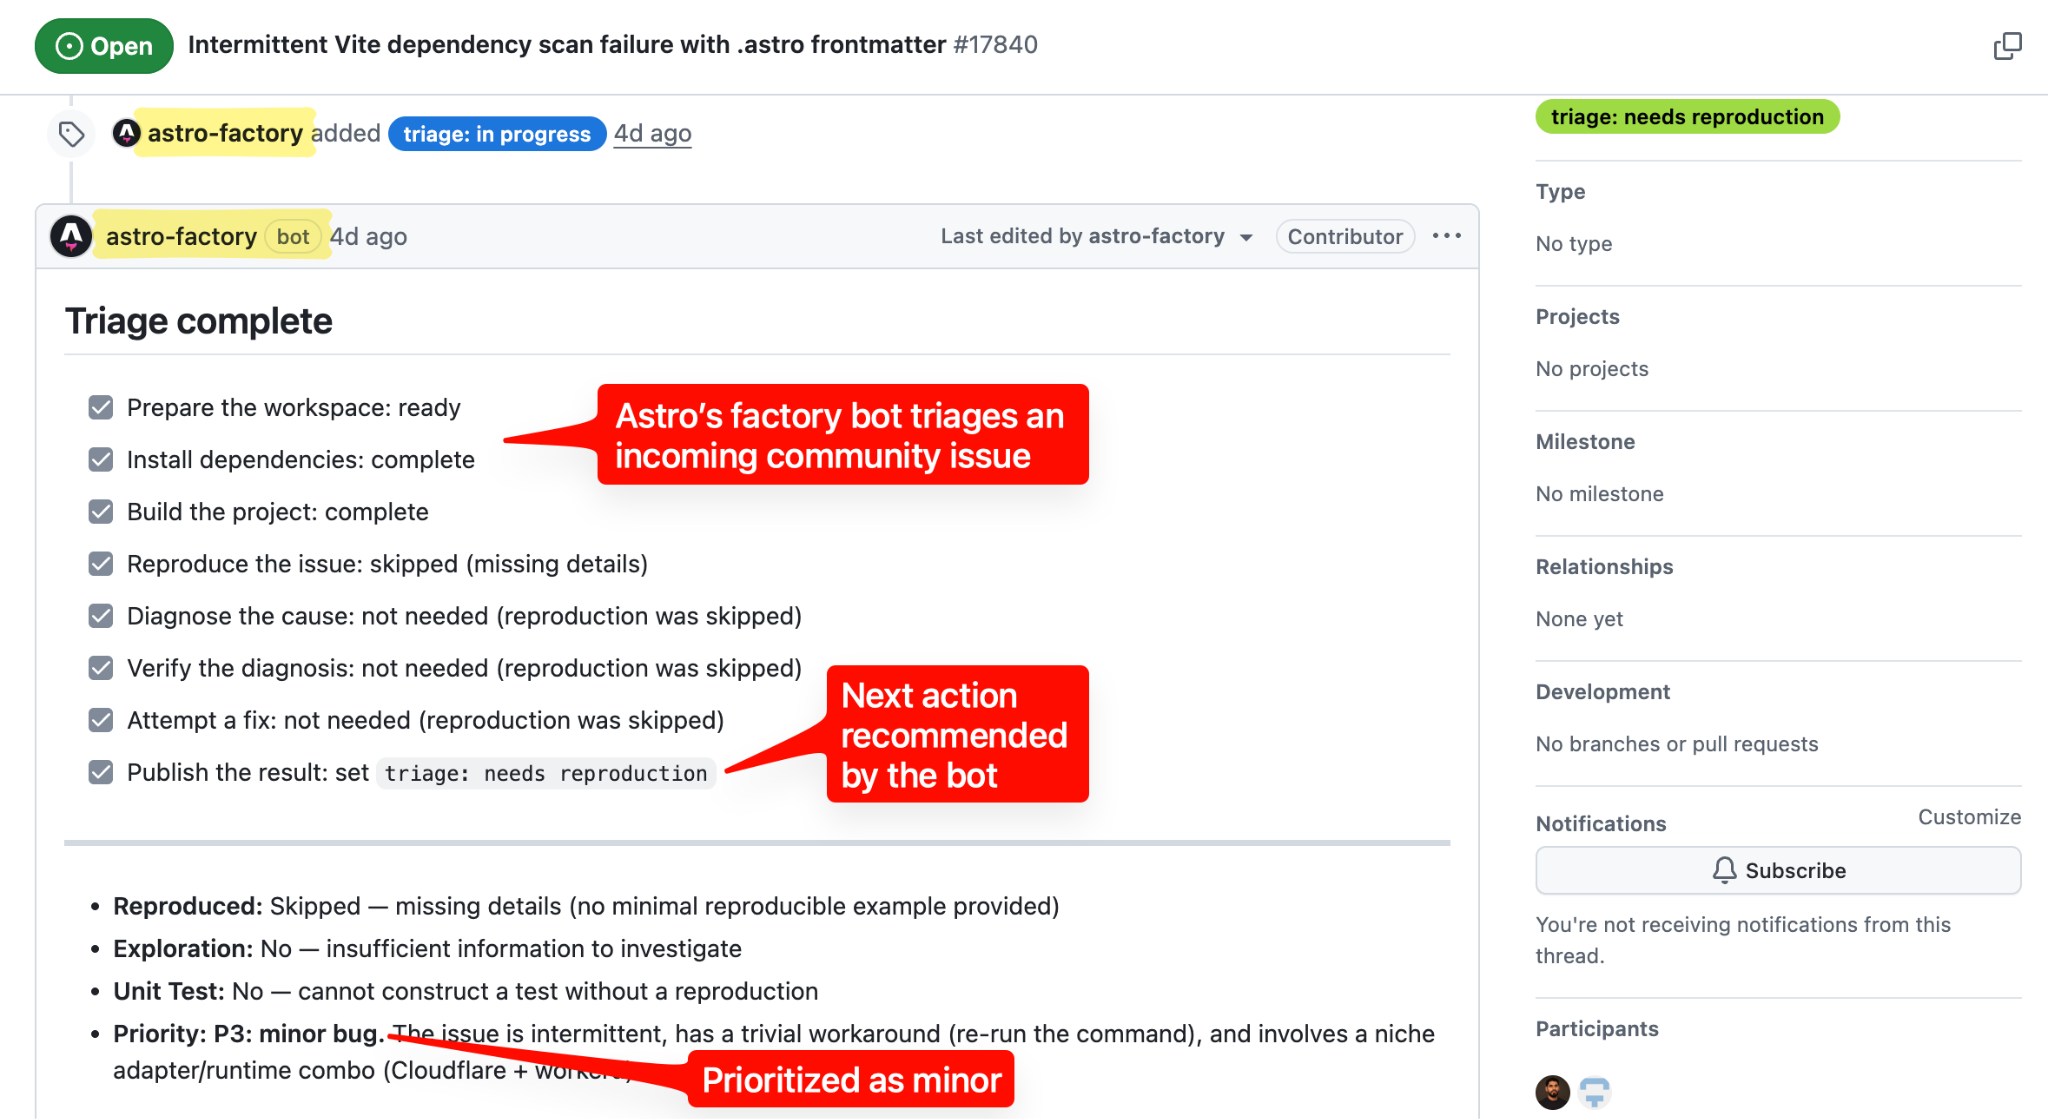
“It’s totally shifted in the last six months,” he said. “We can now solve these issues with these automations — handling triage, reproduction, getting the user to actually verify the fix that the bot is suggesting before we even look at it.”

Example of an Astro factory bot in action

The result was not just a large decrease in open issues, but a complete change in how the Astro team deals with incoming community requests.

“I’ve never seen that in my entire decade-plus experience with open source,” Schott said. “Being able to essentially treat issues as a thing that every week, you prioritize — no matter what — versus a backlog that you’re constantly trimming.”

Furthermore, the Astro “auto-triage” system directly led to Schott creating a brand new agent framework, called Flue.

Flue doesn’t accept your PRs, but is open for discussion

With Flue, Schott is trying an even more radical approach to PRs. Flue’s contributor guide states that “we’re going to try to reimagine things” — partly to prevent what it calls “Drive-by AI slop PRs.”

Basically, Schott explained, every external pull request in the Flue project is automatically closed and converted into an issue or discussion. Bug reports and fix proposals get turned into issues, feature requests become discussions.

Agents can do most PR tasks now, according to Flue’s contributor guide.

“If you submit a PR, no hard feelings, we’re just going to go and represent it for you as issues and discussions. And from there, trying to figure out the right way to bring people on.”

It’s kind of like treating incoming requests as leads, rather than as a piece of work a maintainer feels obliged to review. The contributor guide explains that it uses the team’s own expertise combined with “the best available SOTA [State-of-the-Art] LLMs that we have access to” in order to help them decide what to work on next.

Once a decision is made in the issue or discussion, agents are then deployed for “research, design, implementation, and initial review.”

If our agents write the code, your external PRs are worthless

Like Flue, the “source available” React drawing tool tldraw (50,000 stars) automatically closes external PRs.

Project creator Steve Ruiz announced this policy in January and five months later reiterated it, noting that it was “an opinionated decision made in response to changes in how we’re coding (more discussion, more agents), the social practices around public contribution, and the changing landscape around code security.”

HashiCorp co-founder and Ghostty creator Mitchell Hashimoto, now a co-founder of Superlogical, takes it even further. He thinks “the future is that large open source projects will close contributions completely.”

Ruiz responded, “It just makes less sense to have people contributing code if the issue is decently well-specified and the code can be written by agents.”

But…what happens to the community?

Traditionally in open source, pull requests have been reviewed by maintainers not only for the code, but to teach contributors and assess them as future maintainers. If projects like AI SDK and Astro are using their agents to do much of the code review and implementation, where does that leave community members who want to be more actively involved?

Schott recognizes this as a risk.

“It still leaves this open hole of, well, if you just keep narrowing the project, at a certain point, you and I go on vacation — what happens? It doesn’t really solve every problem.”

However, the fact that both Flue and tldraw don’t accept PRs but do accept new issues and discussions perhaps points to a solution. Which is that by talking to each other more, community members better get to know — and trust — one another, which is both a way to learn from peers and potentially prove yourself worthy of being a maintainer.
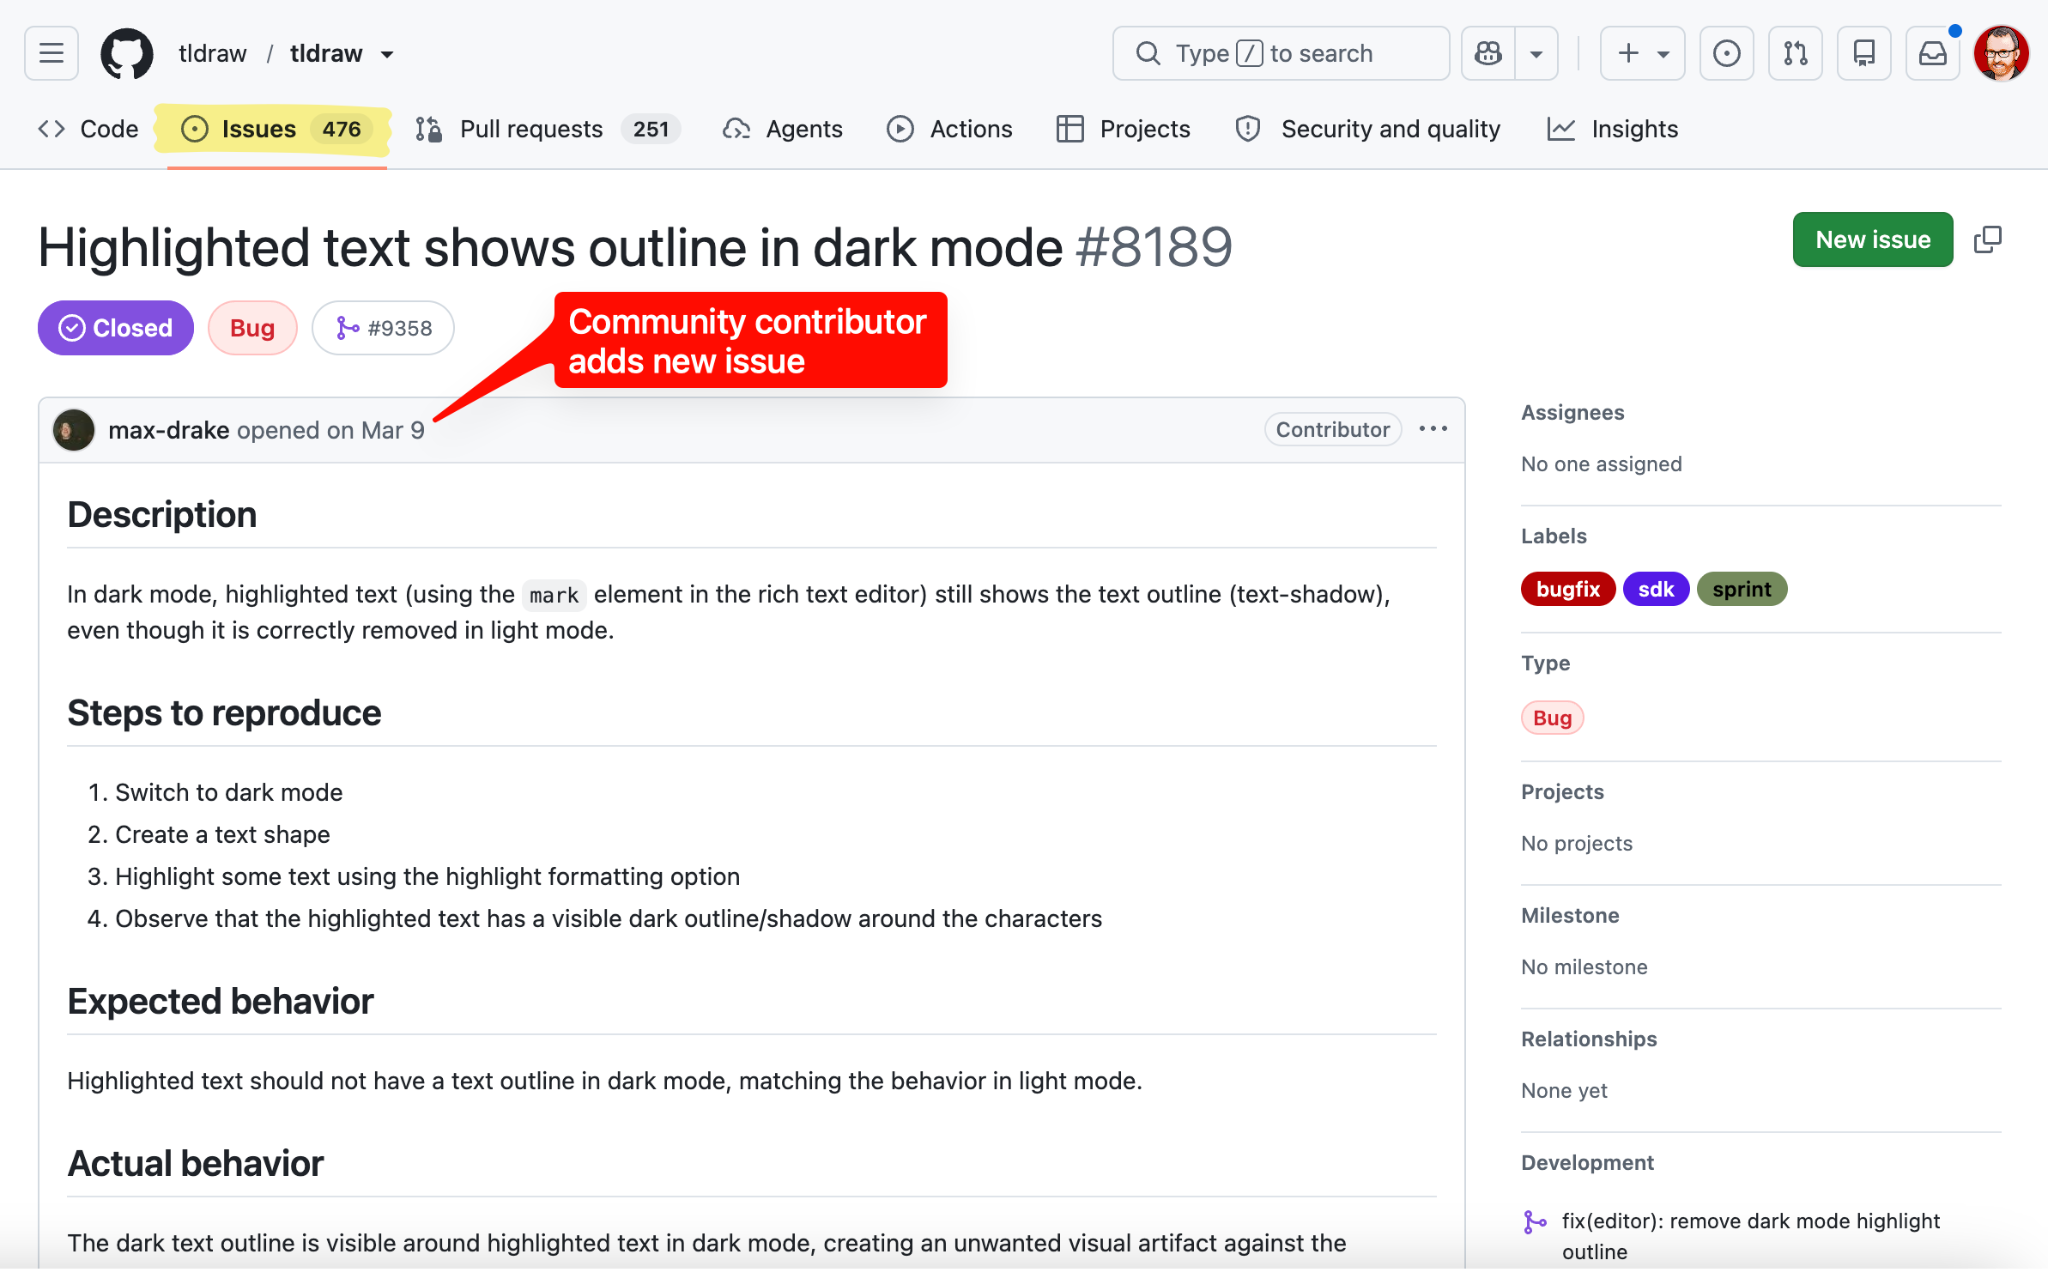
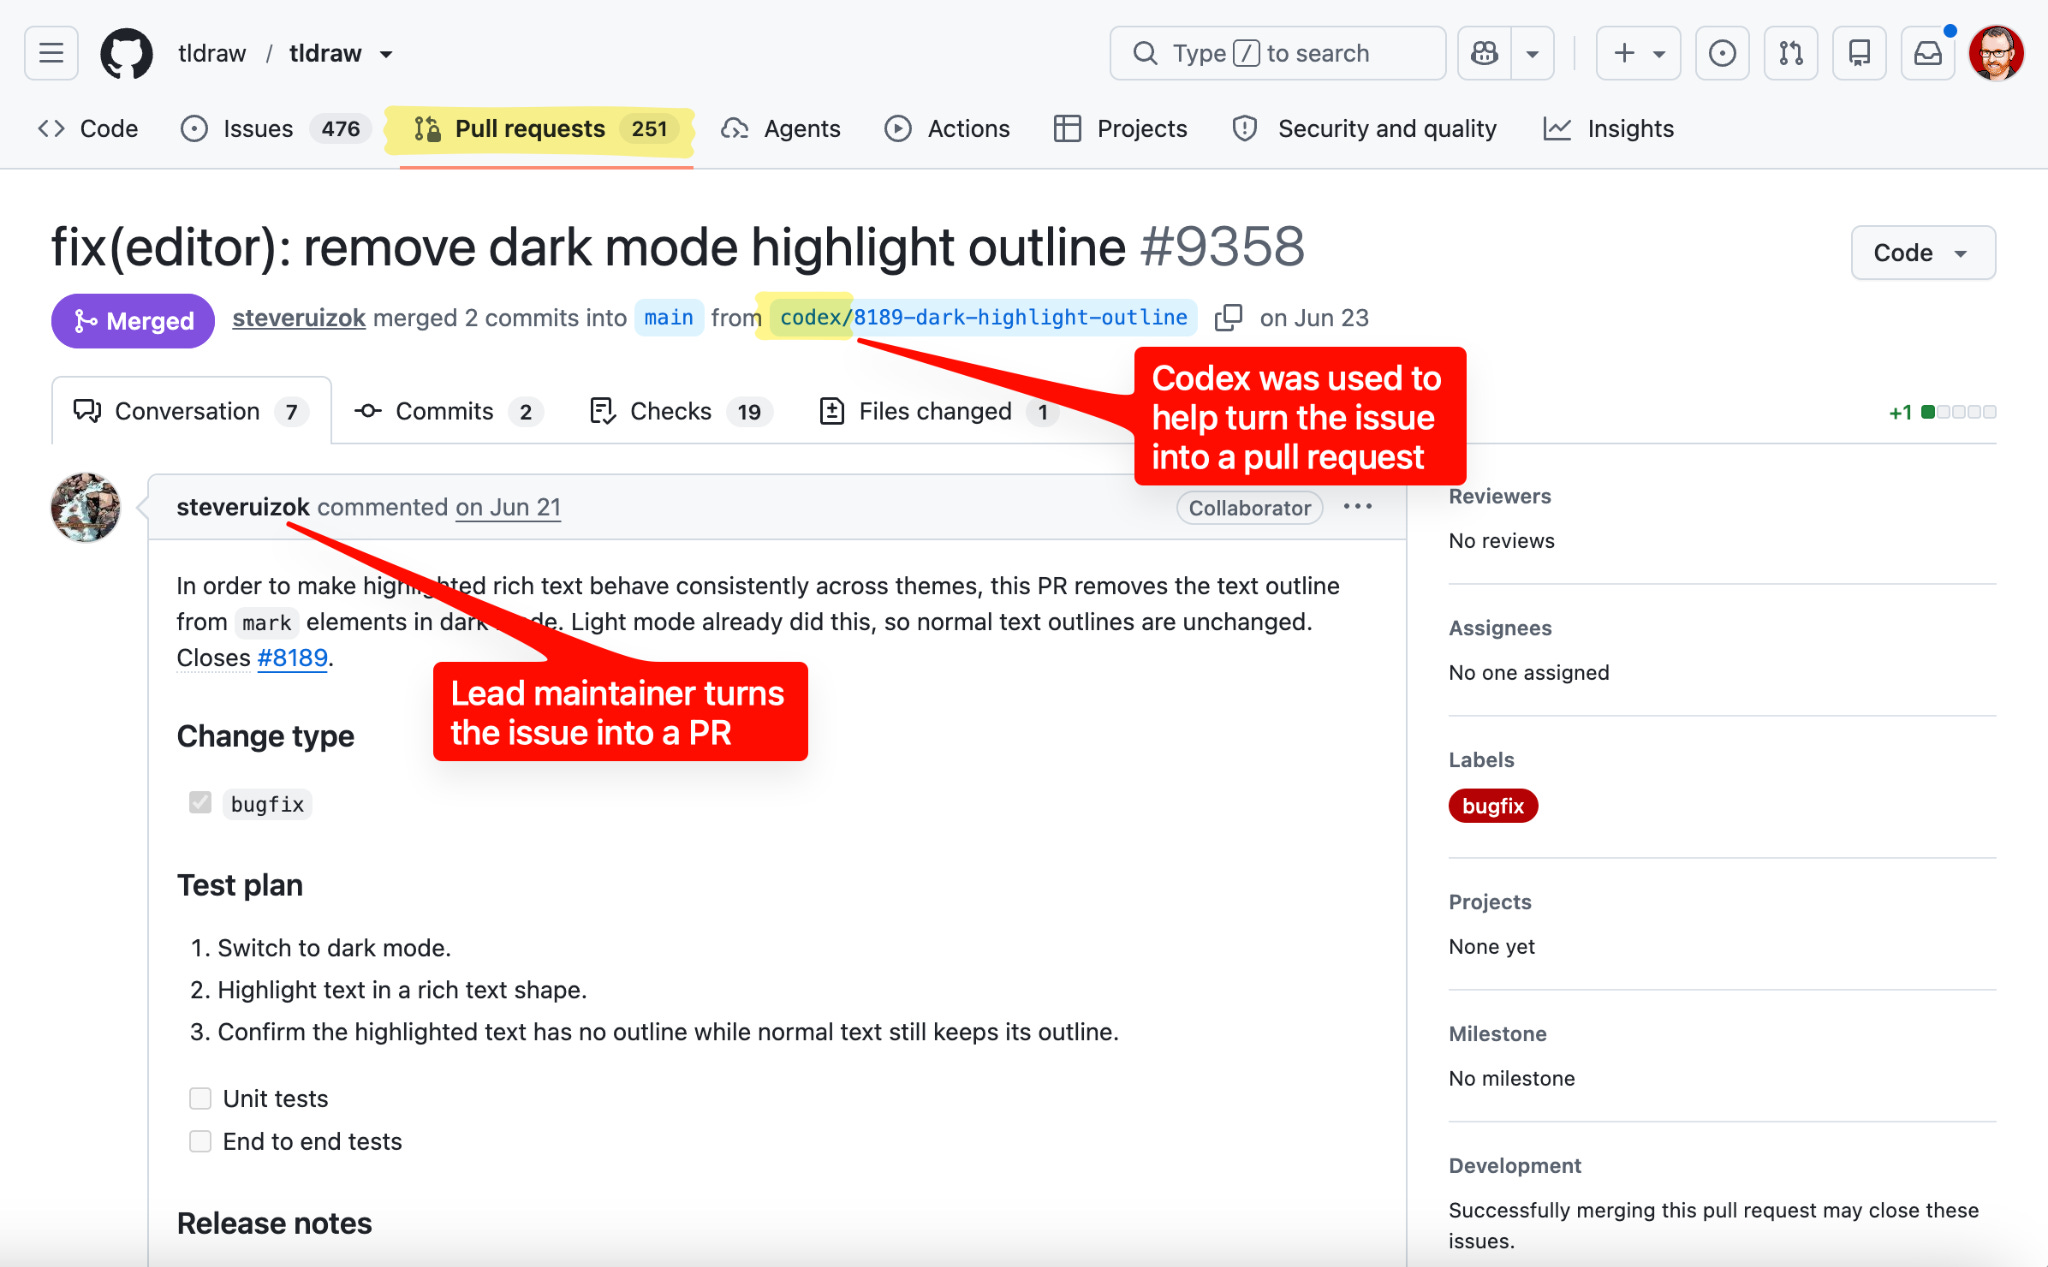
Example of a tldraw issue (above) being turned into a PR (below)

As for the code, if it’s easier for maintainers to use AI themselves than to accept external code contributions, then as tldraw founder Steve Ruiz put it, “it’s better to limit community contribution to the places it still matters: reporting, discussion, perspective, and care.”

Lovable CTO: The Future of SaaS Is Apps That Agents Can Use

26 August 2026 at 16:16

Lovable is well known as an AI-powered platform to build applications. But ironically, it is now moving towards a future where fewer and fewer people will be using conventional apps. That is, of course, because of the growing impact of agents.

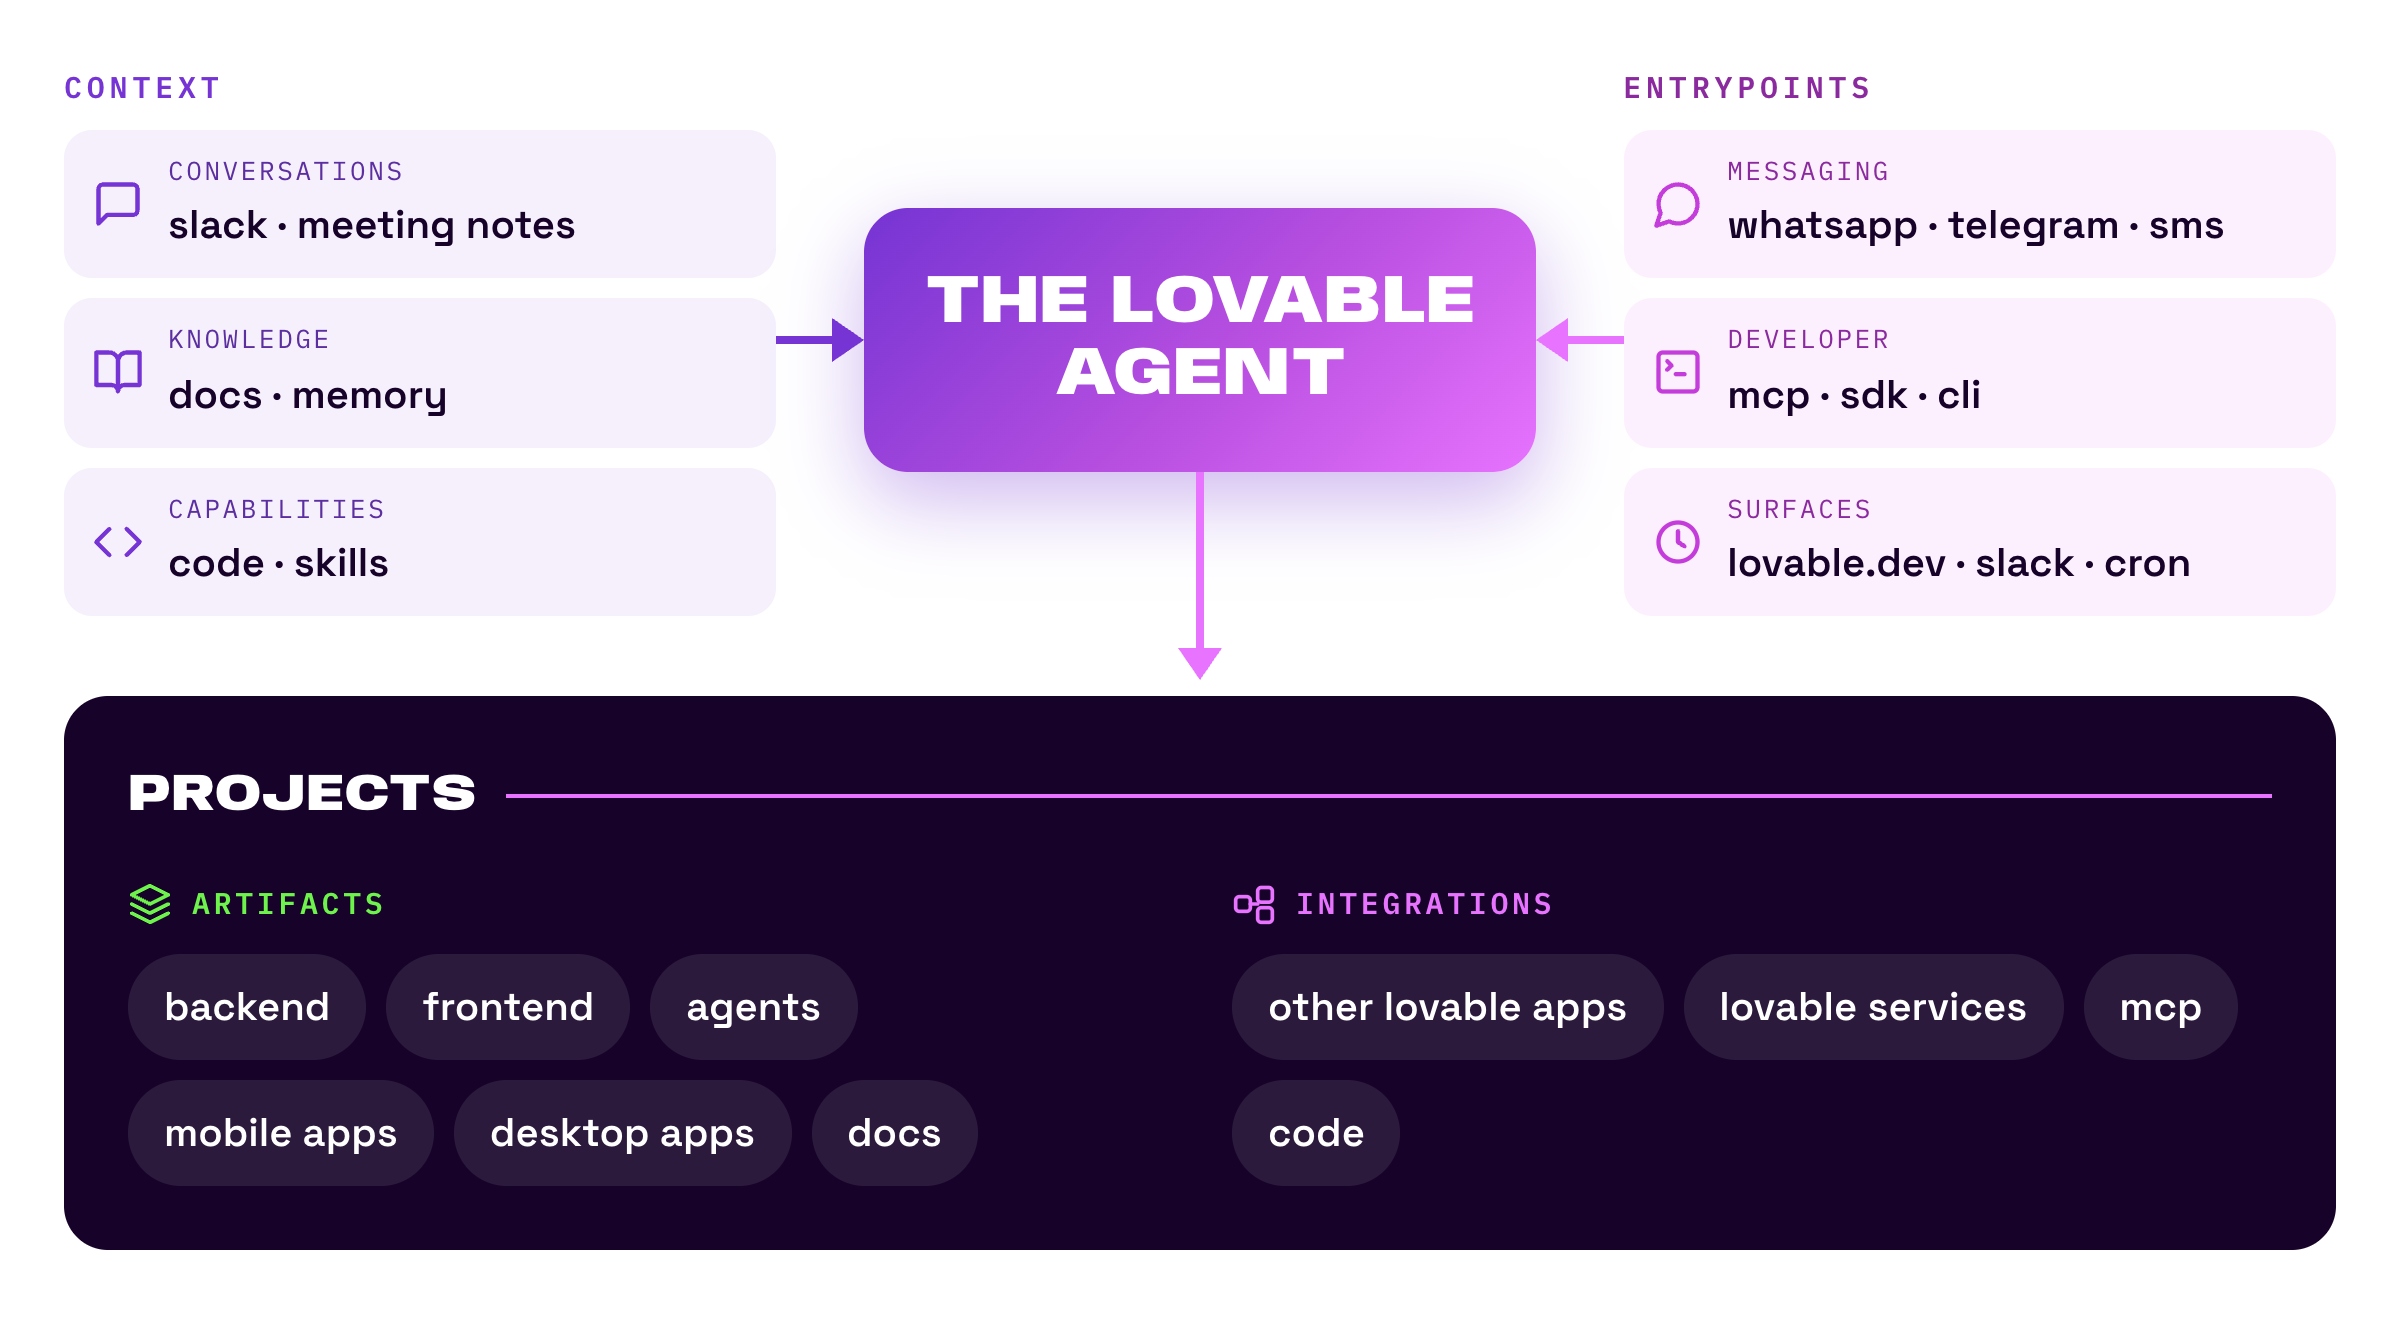
In a recent blog post, Lovable outlined a vision for “a digital brain for your team connecting your daily tools.”

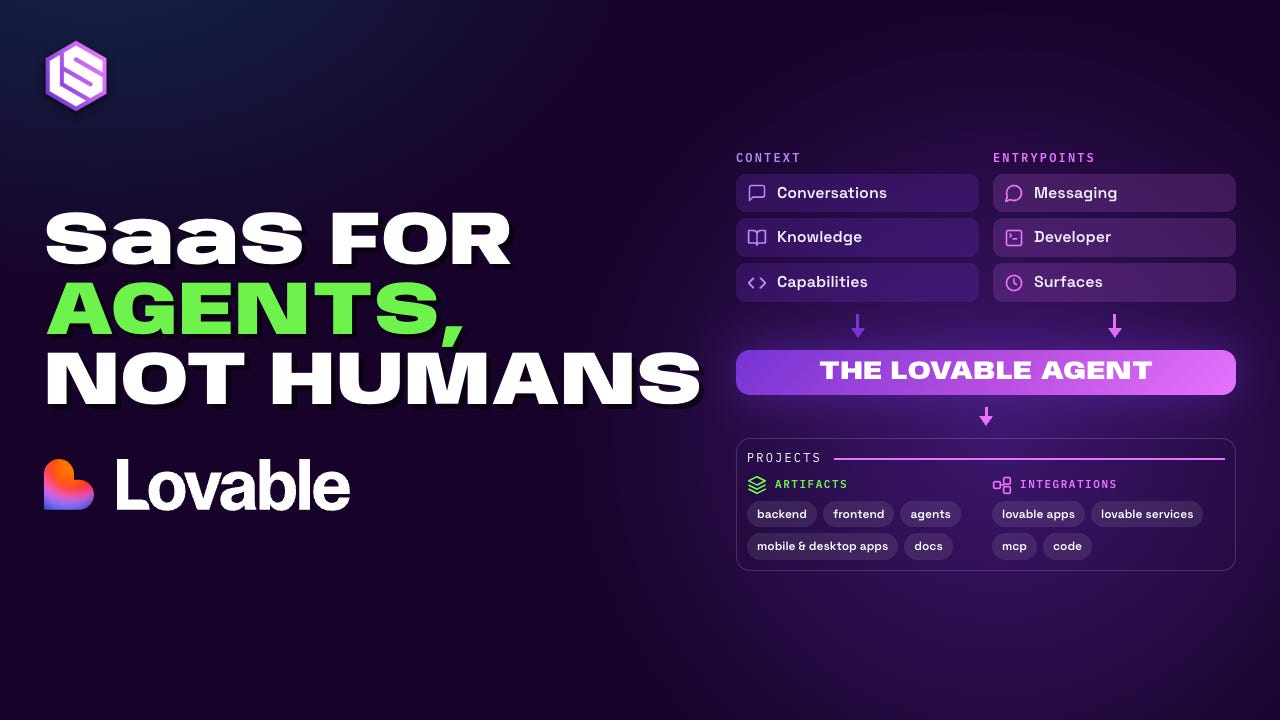
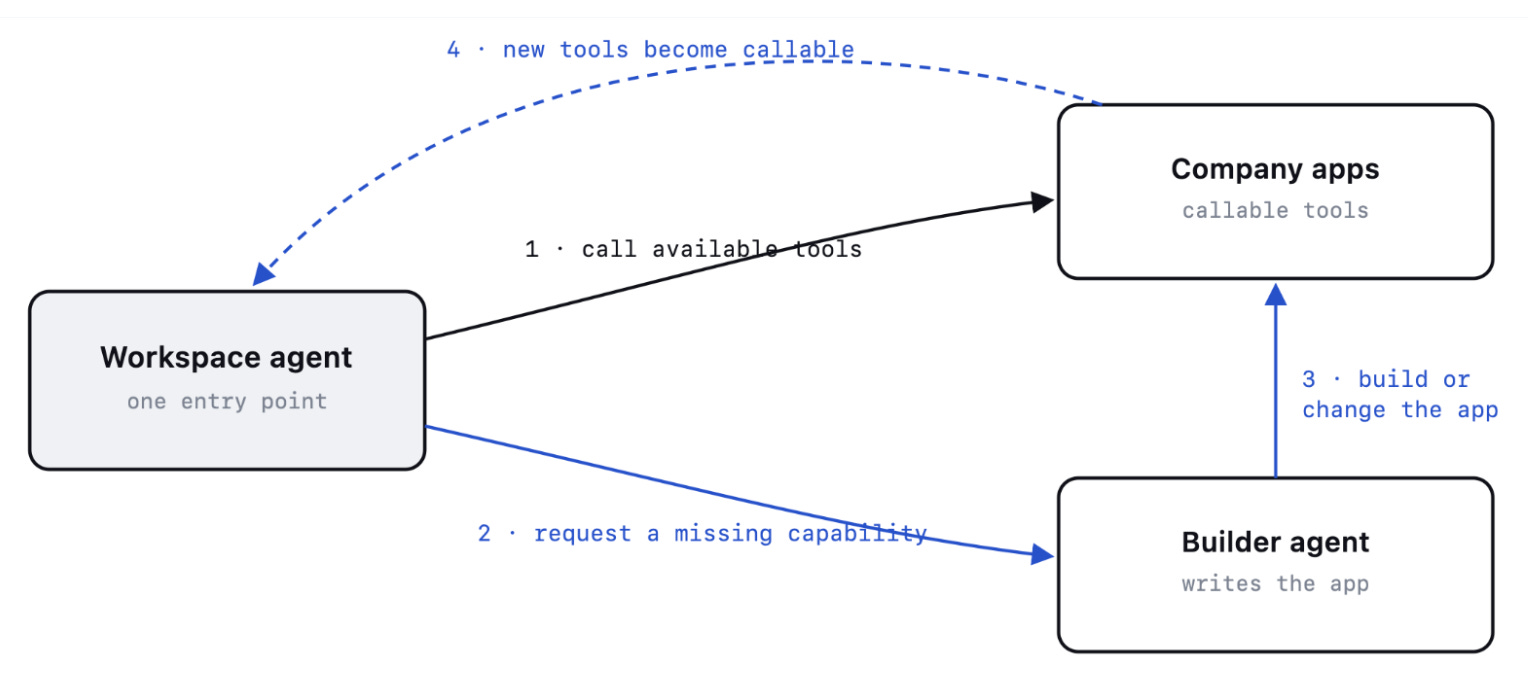
Or as Lovable CTO Fabian Hedin put it in an interview with Latent Space, “you can get to a place where you’re using one entry point to all the work that you’re doing.”

Diagram by Latent Space based on an internal diagram shown to us by Lovable.

To be clear, Lovable still wants to be the tool you use to build apps — but increasingly, it will also enable you to build what Hedin calls “capabilities.” Lovable defines a capability as a useful part of an application that an agent can call directly; bypassing the need for a human user to open the app.

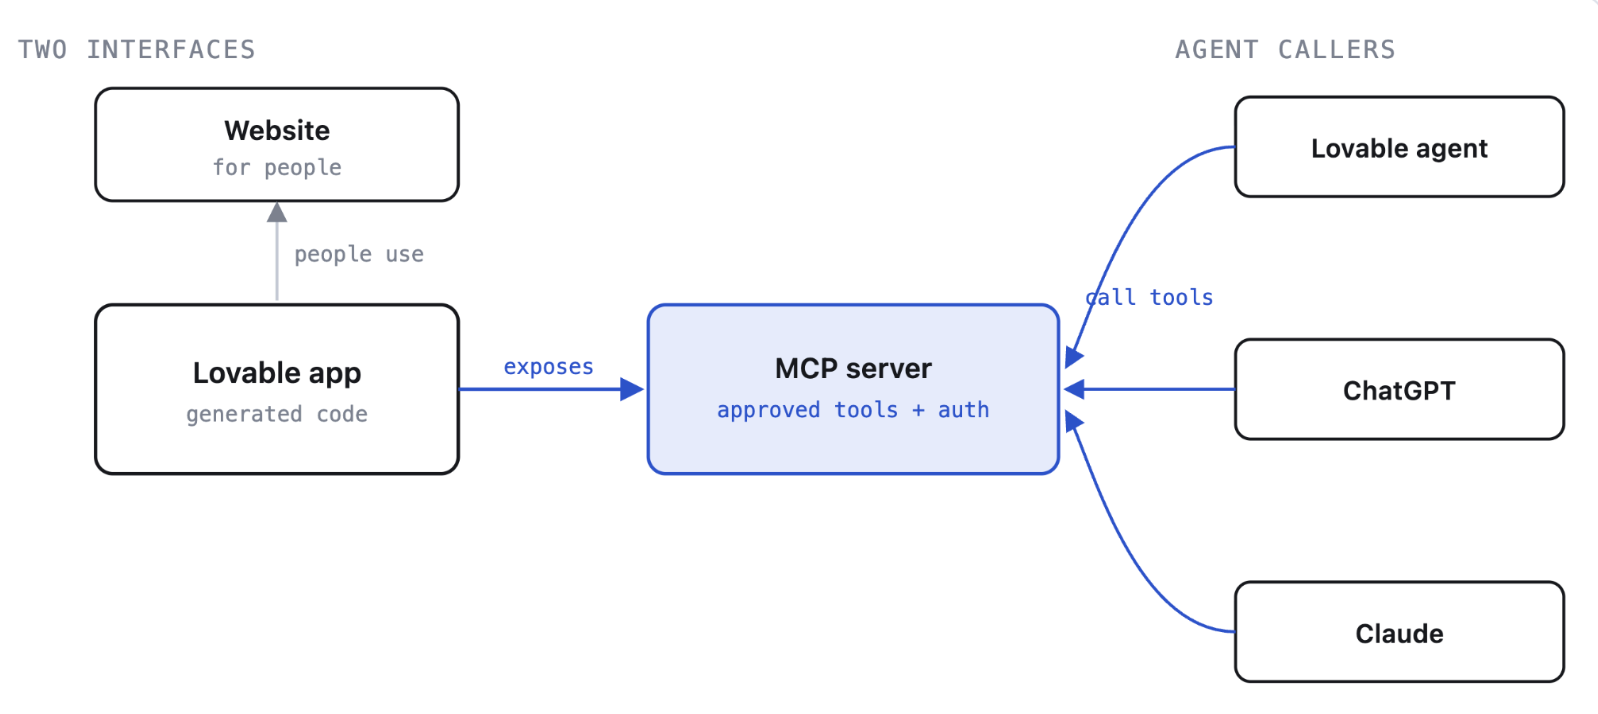
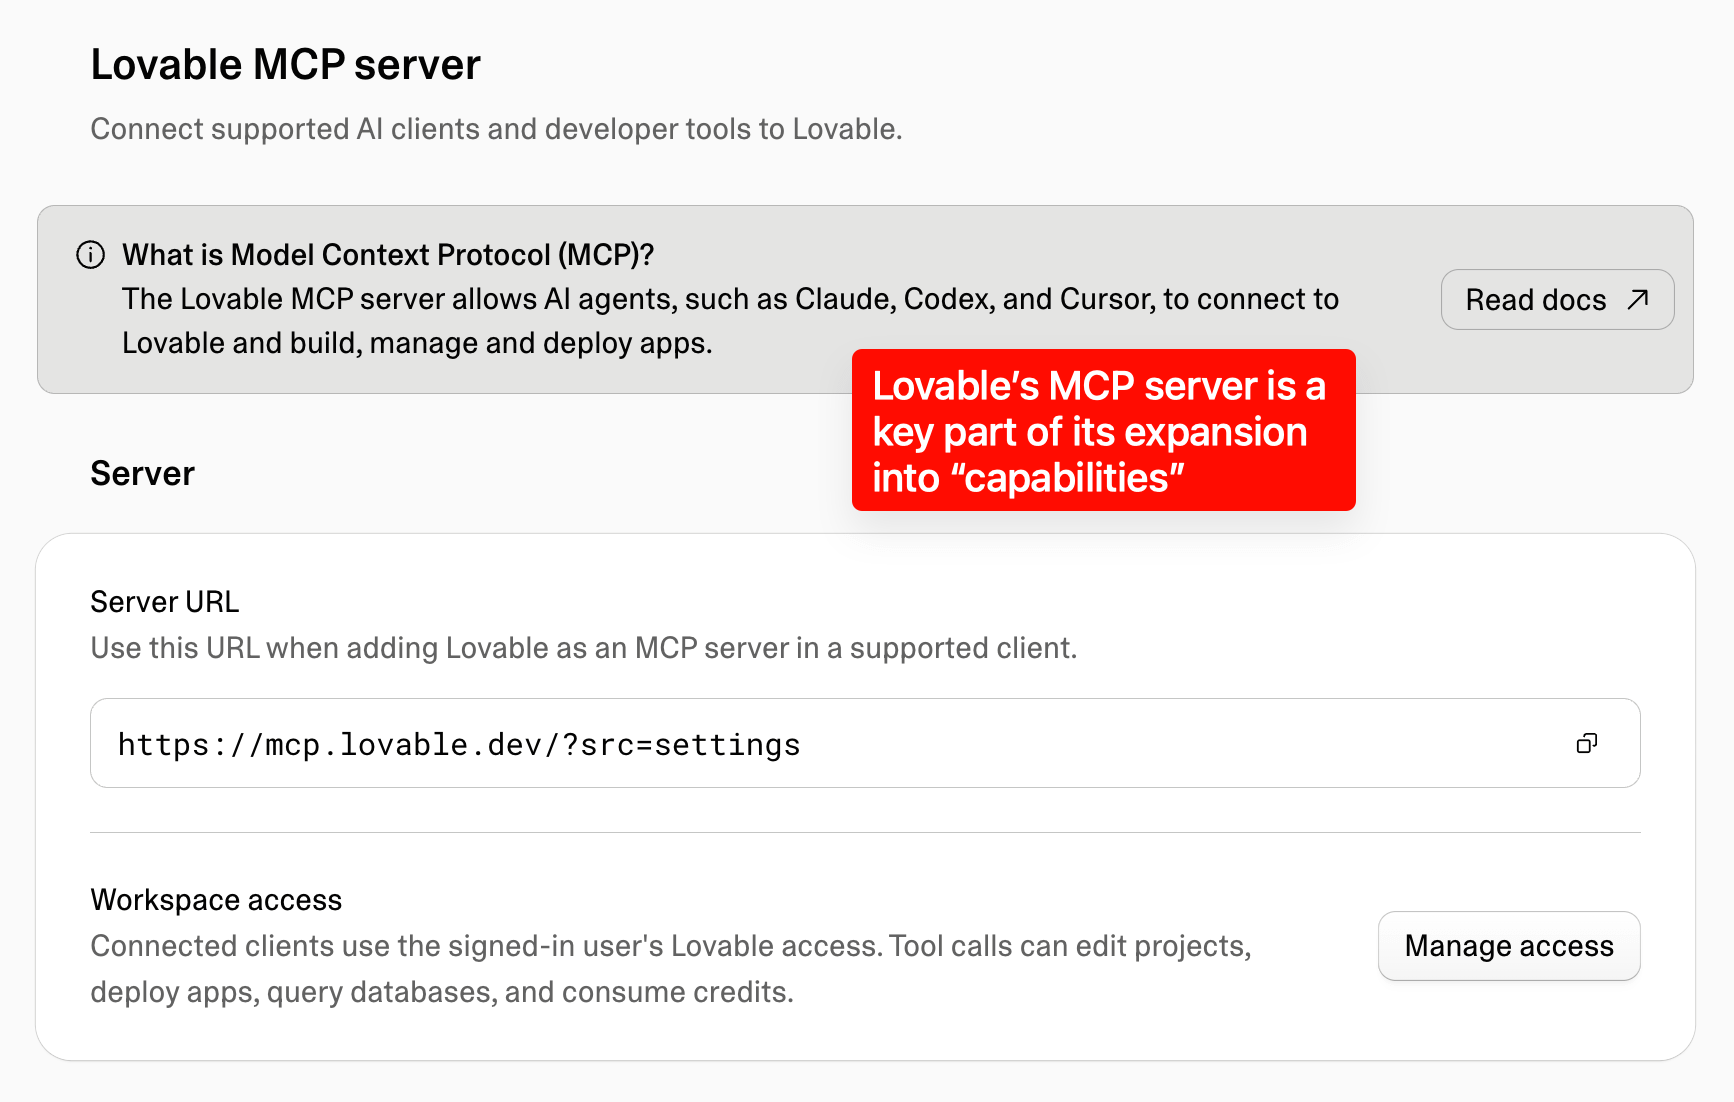
Lovable can turn a published application into agent-accessible capabilities by exposing selected functions from the app as tools through a hosted MCP server. The result is essentially one application with two interfaces: a traditional human UI and a new agent interface that can be used from ChatGPT, Claude and other MCP-compatible AI clients.

Diagram supplied by Lovable

This is how fast an AI business evolves

This shift towards capabilities is the latest evolution from Lovable, in an already fast-moving 3 years in business.

Lovable emerged from GPT Engineer, an open source coding tool that launched in 2023, initially focusing on prototyping. In November 2024, it became a commercial product and the following month, it was rebranded as Lovable.

By that point, they’d begun to notice some of its users building production apps on Lovable — including products that had become real businesses.

“We started seeing people on the platform building not only a prototype, and not only an MVP [Minimum Viable Product], but the actual thing — an actual product that serves real customers,” Hedin said.

Next, Lovable noticed its users creating internal software, in some cases to support a public-facing app and in other cases as an internal app built for an enterprise company.

“People started creating not only software to enable a business, in terms of a customer-facing product, but also the operations behind the company,” Hedin said.

He means tools like a CRM, an admin panel, or a customer-support console.

From app builder to agent platform

So in less than three years, Lovable has become an all-round software creation and hosting company, which means it’s swimming in the same waters as the likes of Vercel and Cloudflare. That said, Lovable is more focused on AI-generated software than infrastructure. But we are seeing crossover in these markets — for example, Vercel’s v0 allows you to generate an app from natural language, just like Lovable.

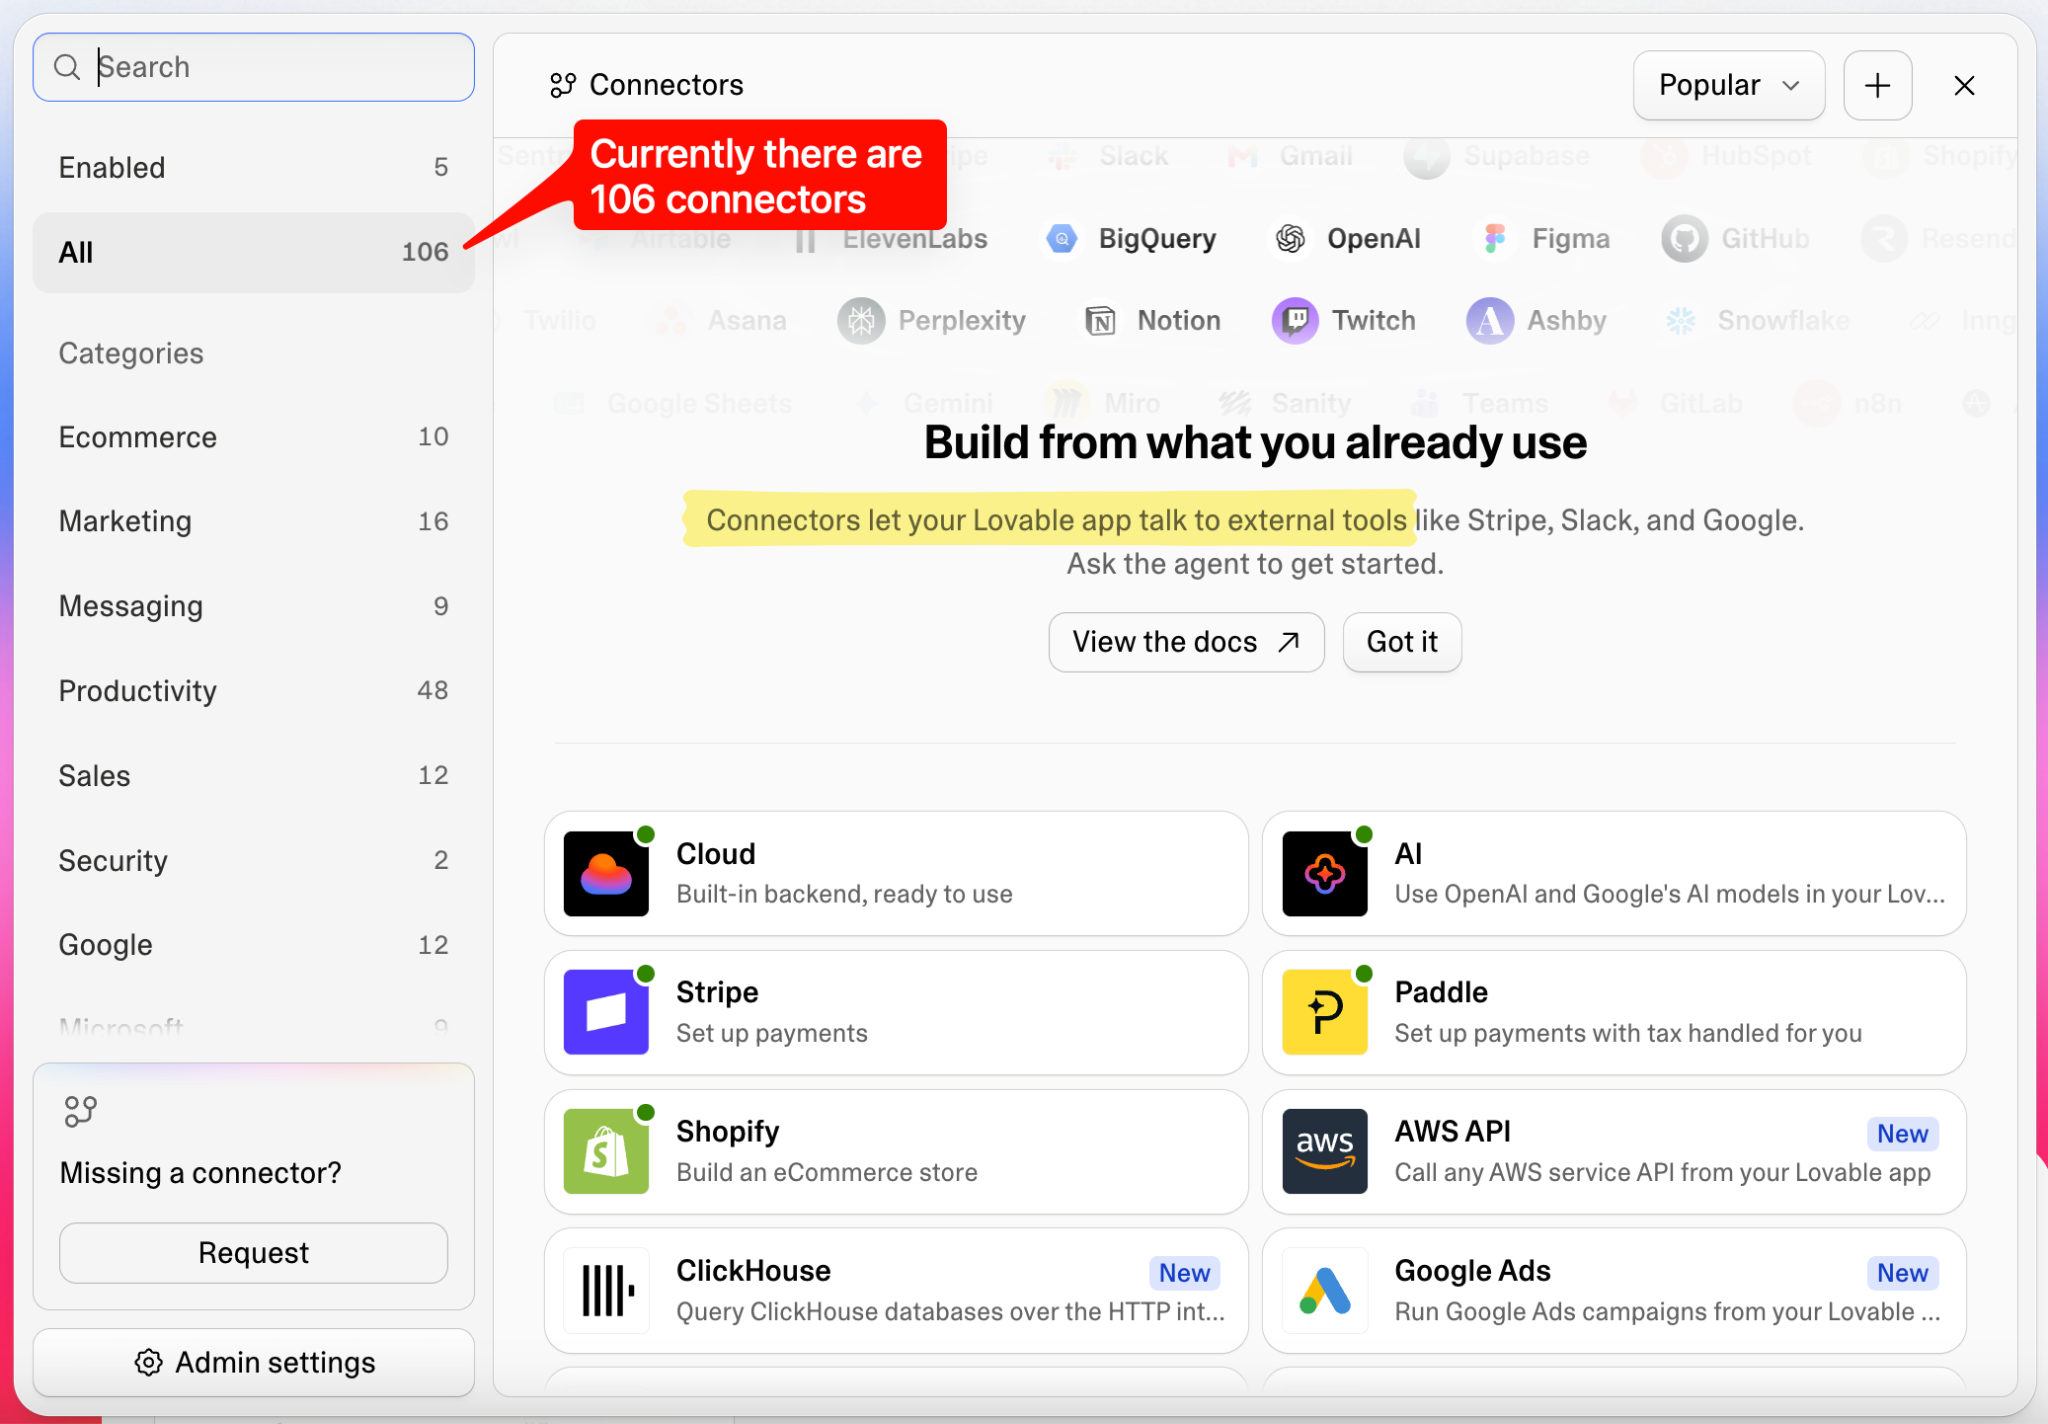
Also just like the black triangle and orange cloud companies, Lovable has expanded into agentic workflows.

Lovable connectors, which let you use external tools.

This rapid product evolution has been accompanied by strong user and revenue growth. According to a tweet from Deedy Das, a partner at lead investor Menlo Ventures, the company has surpassed a $500 million annualized revenue run rate, with more than 60 million projects created and over 900 million monthly visits to Lovable-built apps. Lovable also says employees at nearly two-thirds of the Fortune 500 have used the platform.

Unsurprisingly, Menlo Ventures is doubling down on its investment. It led Lovable’s $400 million Series C this month, alongside the Scaleup Europe Fund managed by EQT, valuing the company at $13.3 billion.
Hedin attributes the pace of change to a combination of Lovable’s innovation and the rapidly improving state of LLMs.

“Every few months, we introduce new capabilities at the application layer, while the large language models also continue improving. Those two things compound.”

Lovable’s model of a company brain

The concept of a digital brain for an organization, for Lovable, essentially means a single interface where you can access many different tools and workflows.

“It should have as much context as possible about you, your company and the world around you,” said Hedin. “Then it needs the capabilities to perform both general tasks and actions that are specific to your organization.”

Ultimately, he added, the goal is that “everything that you’re building can be reused in an agentic way.”

Diagram supplied by Lovable

In a sense, then, applications are becoming a collection of capabilities that users will increasingly access through an organizational agent — instead of, or in addition to, the actual application.
“Our job as a platform is to ensure that all these separate capabilities are connected through one agent — not that you have to build a different agent for every task,” said Hedin.
As an example, Hedin mentioned an internal application they use at Lovable.
“We built this internal tool to help us grant credits to users [via] our support team, and help manage our platform in different ways. Those capabilities are now available [internally] through the Lovable agent.”

Lovable also wants this company brain to work asynchronously. Its agent can schedule itself to resume a task later — for example to check a deployment or to monitor a recurring process — then return the result to the same conversation.

The competition

Lovable isn’t the only company pursuing a “company brain” vision. Vercel CEO Guillermo Rauch recently introduced its internal agent, called @𝚟. “Every day-to-day job at Vercel now involves @𝚟,” Rauch tweeted. “It’s growing exponentially both in daily interactions and token use.”

Hedin acknowledged that Vercel and other AI companies are building towards a similar vision, but he thinks Lovable’s “wedge” is “being the best place to build the capabilities that agents need.” In other words, Lovable’s focus is on helping their users build the capabilities that a company brain will need.

“Orchestrating these capabilities is the easy part,” Hedin said. “Making sure they are well connected, built correctly and reliable is the hard part.”

He also hinted at why they’re using the word ‘brain’ to describe this shift, rather than just ‘agent’.

“I’m careful about using the word ‘agent.’ It suggests something like an employee performing a task, which is an easy way to think about it. But underneath, it is really about connecting the right context and capabilities.”

Security and connecting to external capabilities

Perhaps the biggest challenge with the agents and capabilities paradigm is security. For instance, if one of your employees creates an app with Lovable that connects to the company Slack, you want to ensure that user doesn’t inadvertently expose their personal messages, or any other confidential information, to the company brain.

Connectors are Lovable’s method of connecting to external tools and services. Hedin said the platform must account for a “kind of permissioning graph” to maintain security and privacy.

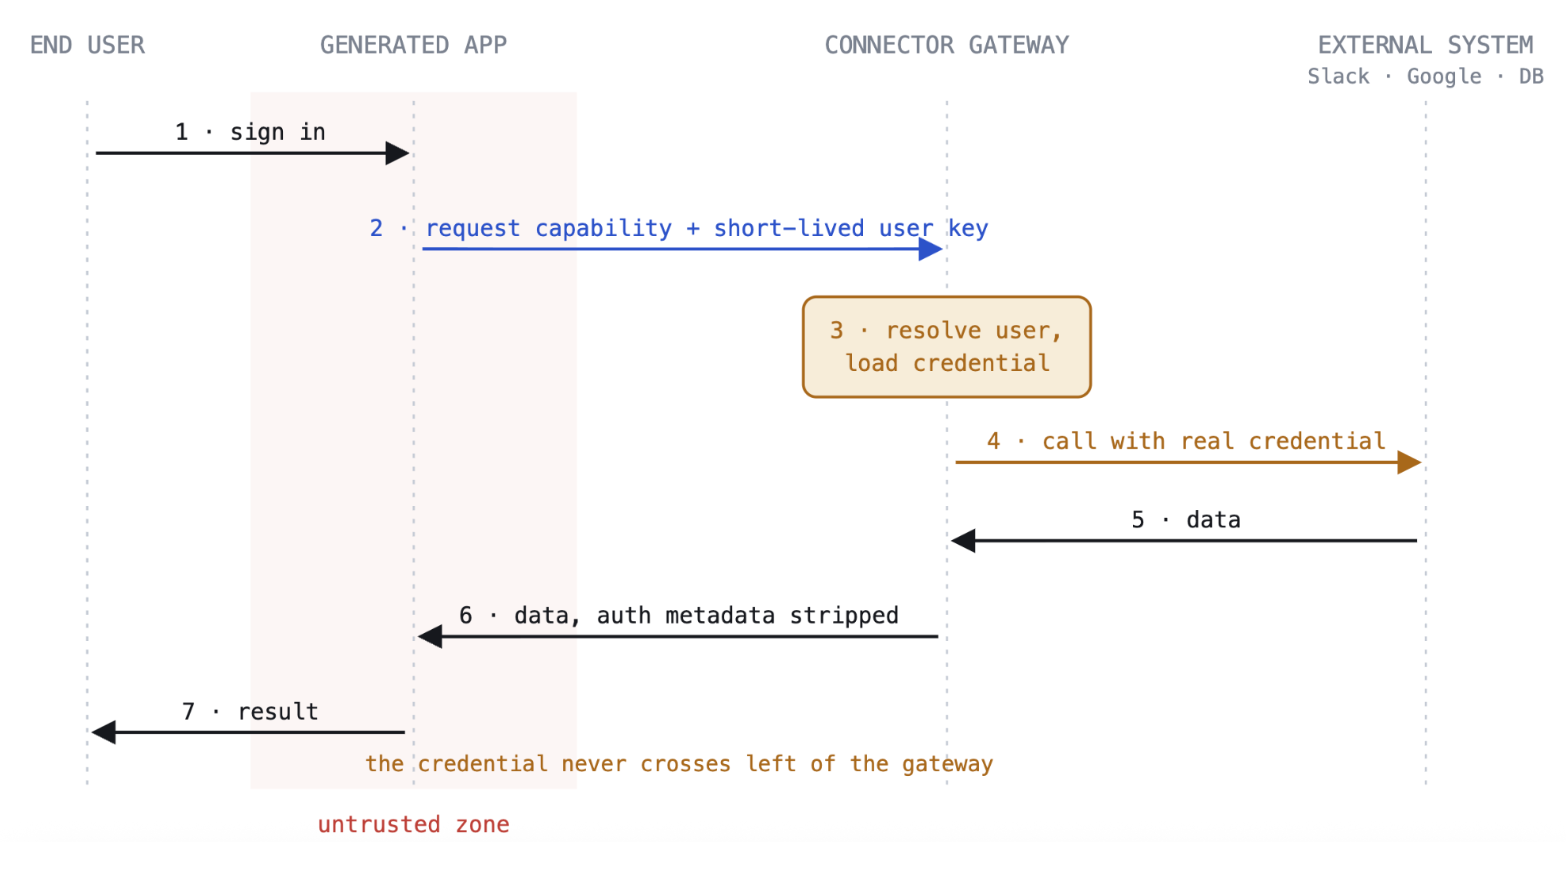
As described in a technical article on Lovable’s blog, one connector type, which Lovable calls an “app user connector,” preserves each user’s identity and source-system permissions. Credentials are stored server-side in encrypted form and handled by Lovable’s connector gateway, rather than being exposed to the generated application; the app instead presents a short-lived key bound to the relevant user.

Diagram supplied by Lovable

“We separate the connection to external systems from the application code being written,” is how Hedin put it. “The application interfaces with the Lovable platform, but the application itself never gets access to those credentials.”

The future of SaaS

So Lovable is moving to a future where a company brain uses capabilities derived from the apps its users build. That begs the question: what will happen to SaaS apps?

Hedin reiterated that people will increasingly interact with software through an AI layer — the company brain concept.

“People are not going to have as many tabs open in different tools as they have historically. That experience is going to consolidate, but the vertical capabilities those tools provide will remain valuable.”

He recognizes that some traditional SaaS products may “fight” this trend, by sticking with their traditional apps and not adapting, but he says Lovable wants to become a platform for building capabilities.

“We want to build this open platform that anyone can connect to, anyone can use,” he said.

Hedin ended with some advice for SaaS companies, whether existing ones or apps that might emerge on the Lovable platform.

“I think SaaS businesses are going to have to focus more on providing the shovel for AI to use their capabilities.”

The /wayfinder Skill: Navigating the “Fog of War” of Planning

20 August 2026 at 20:59

We’re currently developing a new series about skills, with the aim of giving you a regular supply of new skills to use in your projects. We’re kicking things off with an interview — and a super-useful skill — featuring Matt Pocock, whose “AI Skills for Real Engineers” project has over 220,000 stars on GitHub. He also talks about these skills to 347,000 subscribers on his YouTube channel.

Pocock recently released a new skill called /wayfinder. Its purpose is to help you and your agent figure out a project where the end state isn’t entirely clear. Or as Pocock put it in our interview, /wayfinder helps you navigate “the fog of war,” where you have a project but “you can’t quite decide everything right at the start.”

The following interview has been slightly condensed for readability, so you can read it, absorb Matt’s insights, and then test out /wayfinder for yourself!

Latent Space: What were the goals of wayfinder?

Pocock: What I noticed is I was doing a lot of work with AFK agents [Away From Keyboard] and trying to schedule in a ton of work so that my agents could run virtually overnight. I would just plan a bunch of stuff, and then I would create a spec and then turn that spec into tickets. And I had a really well-developed set of skills for how to turn work into scheduled stuff that agents could just crack on.

But [...] I was finding the planning stage really onerous, because I would have to be constantly thinking about my session management. Like, how many tokens am I into my context window? How deep am I going here?

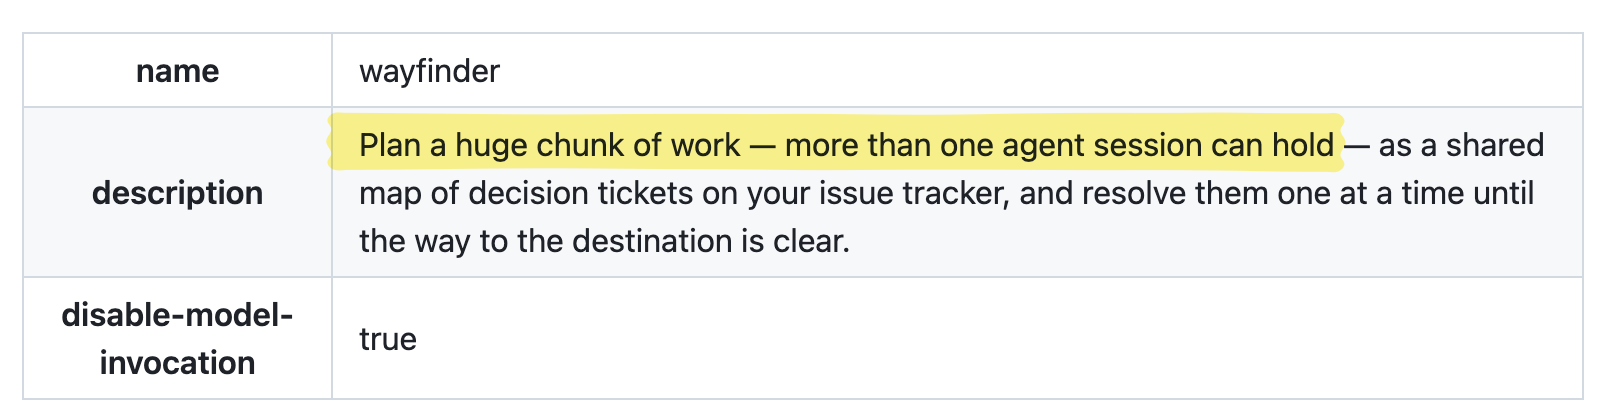
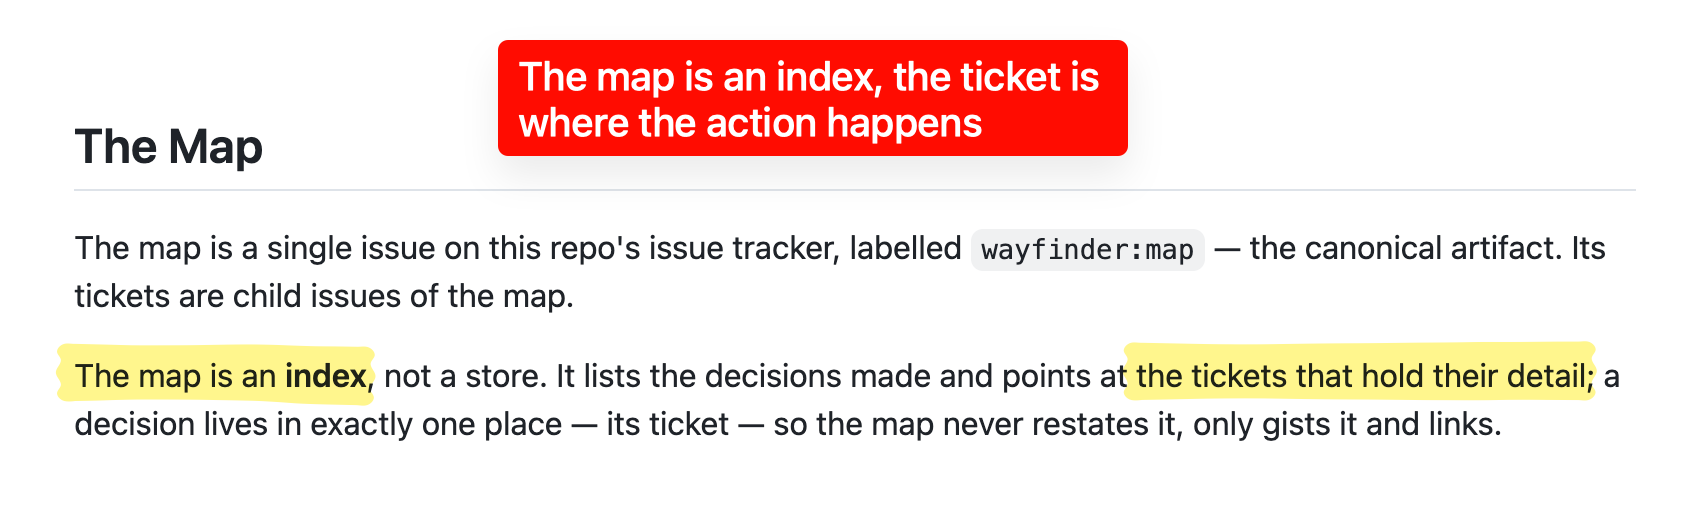
Matt Pocock’s wayfinder skill, as documented in GitHub

I didn’t want to feel constrained in the planning stage anymore. I wanted an orchestrator layer that would basically say, okay, whatever you want to plan, I’m going to handle the planning sessions for you. I’m going to split this out into multiple different threads, do prototyping, do research and pull it all back together, so that you don’t feel constrained in the planning anymore.

And then your specs can be even more detailed, and you can just whack off an AFK agent to go and do tons more work.

Latent Space: What was the design process of coming up with this skill?

Pocock: I had this kernel of an idea of, what if I didn’t have to manage the handoffs? What would that look like? And then, what would it look like to have some kind of centralized document to have all of those pieces together?

Whenever you’re thinking about context management — because that’s really what a skill is, you’re managing the context of the agent you’re working in — you need to think about the information flow. So what I wanted to think about is, what if a grilling session could manage other grilling sessions? What would that look like?

Well, the first step to that is, what does the grilling session that’s being managed need? What does the child need in that situation? So the child probably needs to understand a vague overview of what else is happening, and they need their specific task.

So there, you’ve got two documents. You’ve got a map — which is all of the rest of the stuff, all the decisions that have already been made. And then you’ve got the specific ticket that goes into the actual session. And what you notice there is that those words are very precise.

You’ve got the map, and you’ve got the ticket, and you’ve got the session. And once you’ve got the kernel of an idea, you then need to come up with the words for that idea. Because once you’ve figured out the words, then those entities can be really clearly mapped out by the agent.

Because if you just call everything a ticket, or if you just refer to it in different ways in different places, then it’s going to be really confused and you’re going to get strange behavior. Whereas if you use these very specific, what I call leading words, to lead the agent to understand exactly what each part is, and you’ve understood what the information flow is, then you’ve got your skill.

Latent Space: What kind of use cases do you think wayfinder would be useful for?

Pocock: Well, I’ve been using it for all sorts of stuff. I’ve been using it to actually plan courses as well. In wayfinder, there are different types of tickets.

So you’ve got grilling tickets, which are just a grilling session. Then you’ve got prototype tickets for creating prototypes, research tickets for creating [and doing] research, and then task tickets — which are really broad…basically, just anything the human needs to do that the agent can’t do. And so once you think about that, you realize, OK, I can apply that to anything.

One really key idea in wayfinder is the ‘fog of war’. So this is the concept of, you can’t quite decide everything right at the start.

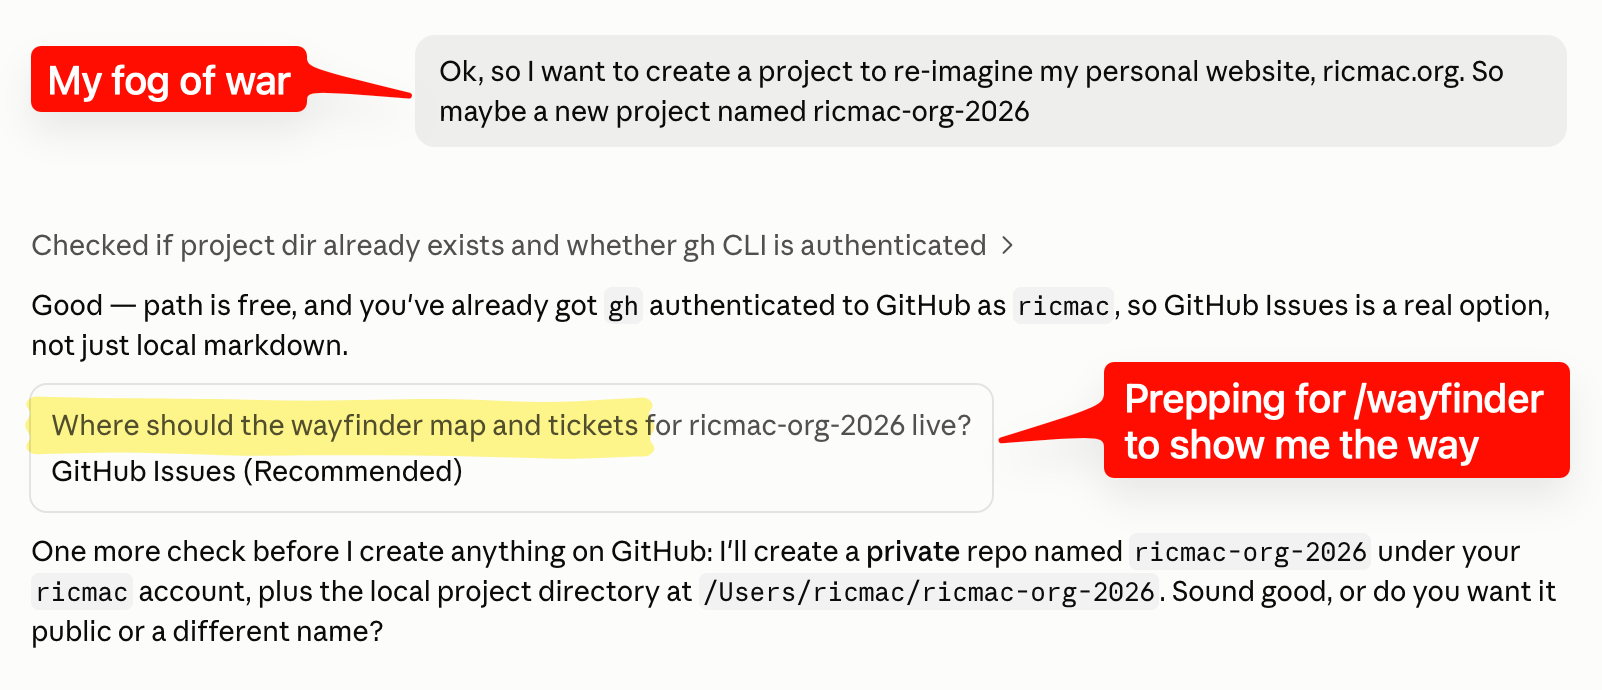
I decided to test /wayfinder on a project to rearchitect my personal website. Here’s the initial project set-up, in this case using Claude Code.

You can make certain decisions, and those certain decisions sort of lead you there and push further out into the fog of war — kind of like Warcraft III style, exploring the map. And once I had the idea of ‘fog of war’ and ‘map’, I realized those two terms actually work really nicely together, and it really leads the agent into the right idea. So I’ve been using it for engineering, for non-engineering stuff, for course planning, all sorts.

Latent Space: This concept of the fog of war — it’s weird to consider what you don’t know that you don’t know. Maybe LLMs are good at capturing that.

Pocock: I feel like with the grilling stuff that I’m still working on, that captures an idea that you don’t know stuff, but maybe the agent can contribute something and illuminate a part of the room that you don’t quite understand yet.

And wayfinder is just sort of an extra layer on top of that.

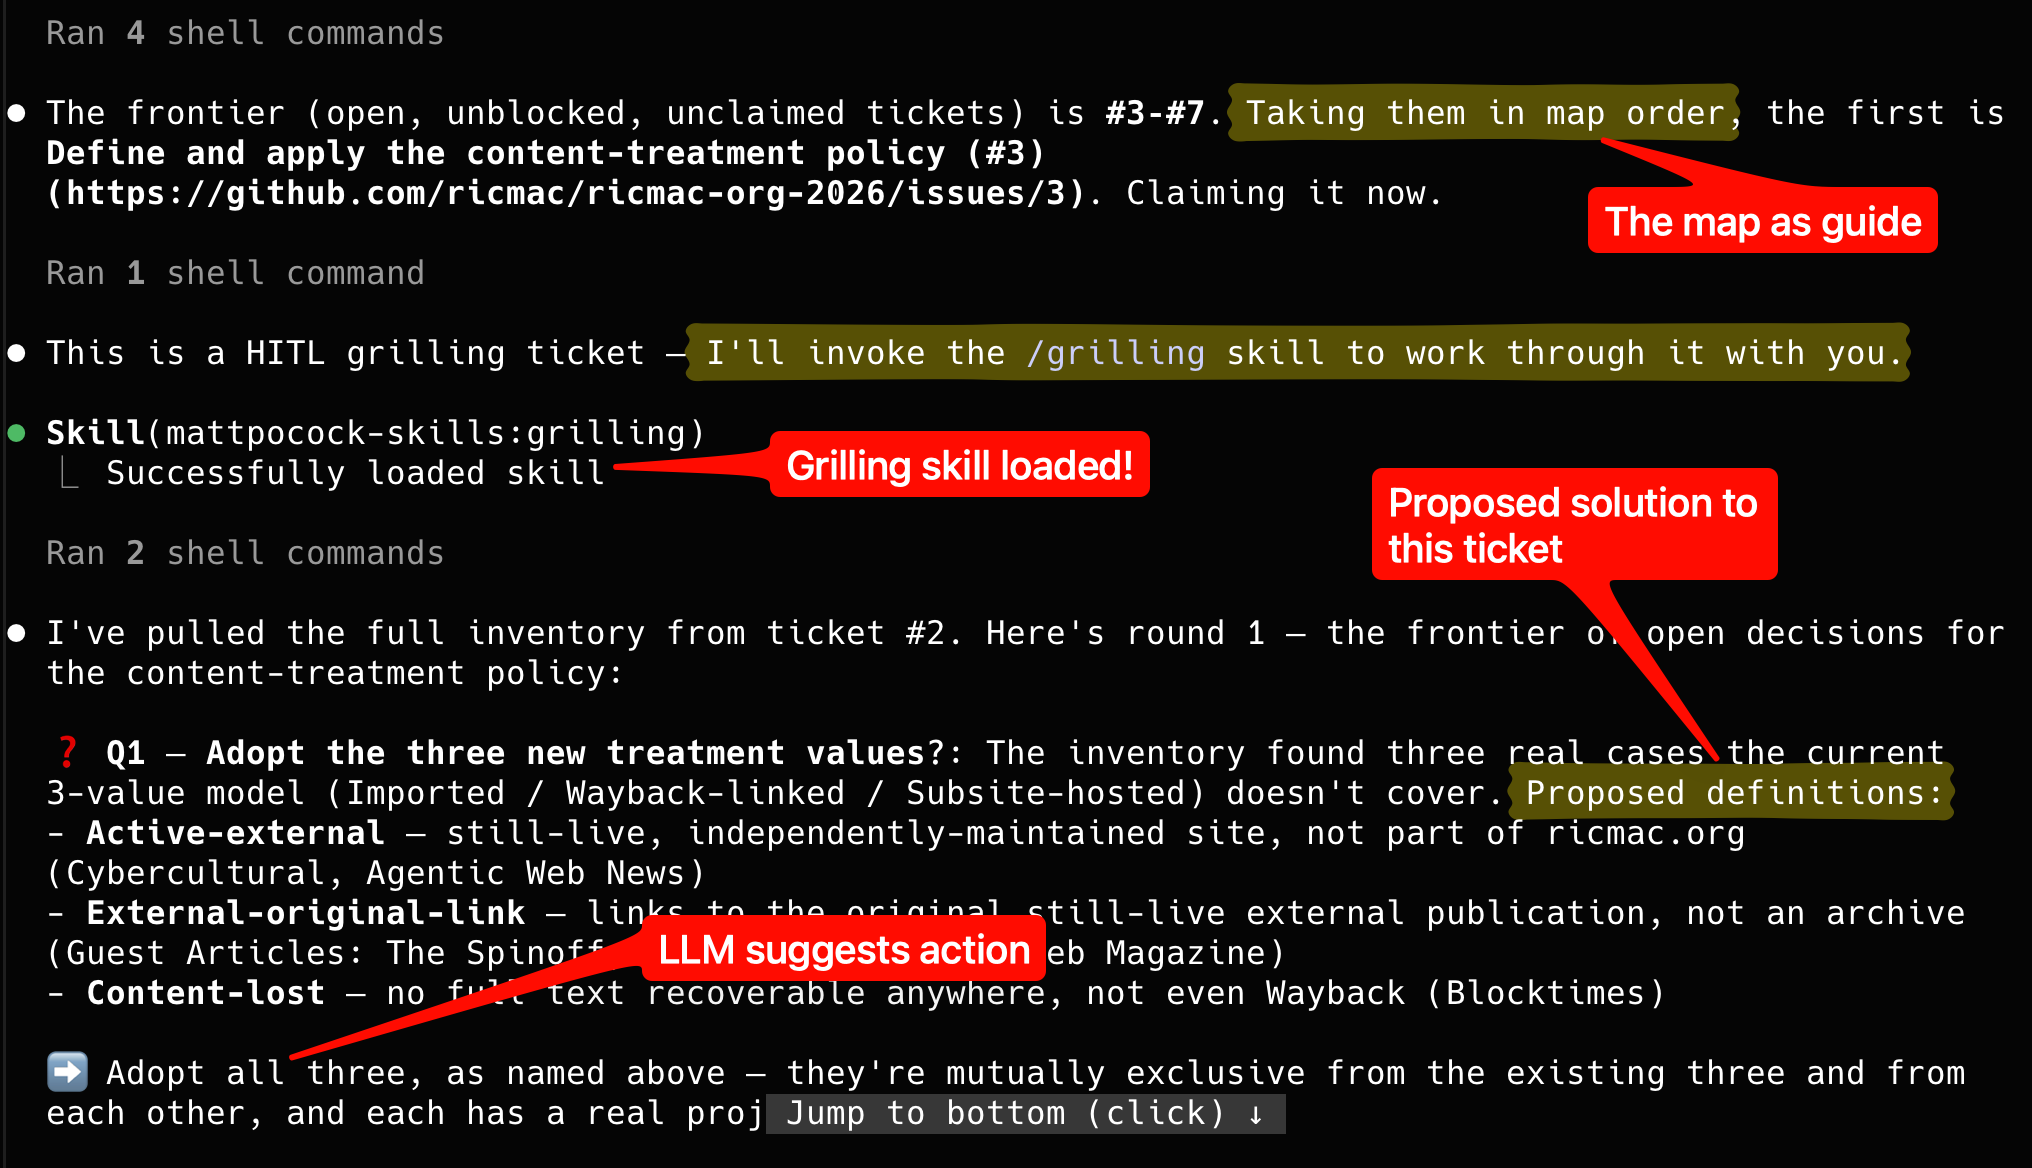
Working through my website rearchitecture project using /wayfinder. There’s 20+ years of content to re-organize!

Latent Space: Yeah, and there’s all these artifacts. How much time do you spend teaching the model all this terminology?

Pocock: For the last few months, I’ve been pretty obsessed with terminology — and finding the right terms for certain things. I’ve put together, I haven’t actually put it out yet, but it’s an AI coding dictionary — of basically all the terms in AI coding. It’s in this beautiful graph that you can explore and understand exactly what an agent is, exactly what a harness is, exactly what a model is, blah blah blah.

I’ve redone all my courses to use that dictionary and make it really solid. And then all of my skills use a consistent dictionary as well. So they’re all working off the [same] assumptions, the same leading words.

I realized that I needed a ubiquitous language between me and the agent. Between me and the agent, there is a communication barrier. And that’s what I’m trying to do with my skills all the time, is try to find the right words.

And agents are really good at showing you the opportunities for different wording — really good at domain modeling, actually.

Latent Space: When do we directly use the grill-me skill, versus wayfinder?

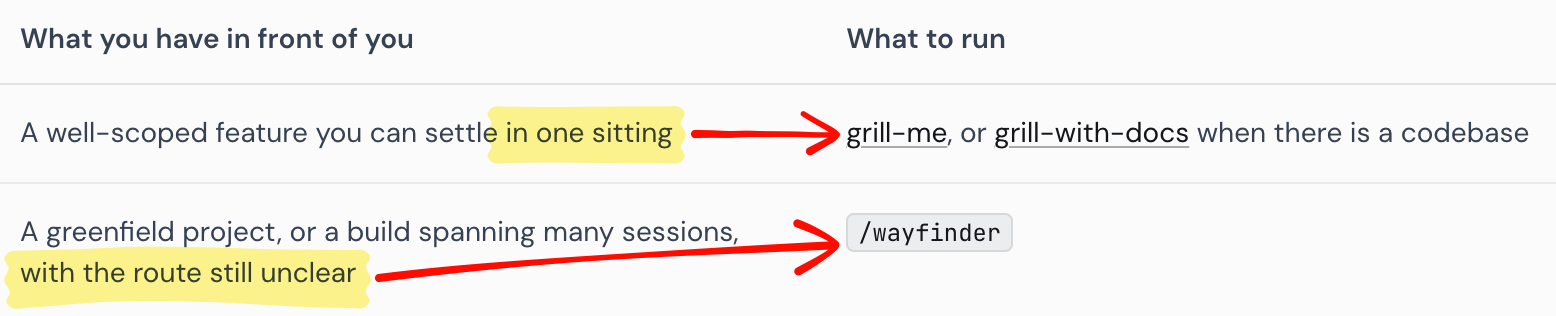
Pocock: Use ‘grill me’ in cases where you feel like you can plan the whole thing in a single session, and you need to align before you go. So most small features will fit into this. Most stuff where you can see the path ahead of you, but you just want to make sure the agent is on board, ‘grill me’ will work with that.

For stuff where you don’t know the path ahead, for stuff where you can feel the fog of war in front of you, use wayfinder. You’re gonna find your way with wayfinder. So that’s how it works.

Frontier Model Cost and Open-Weights Popularity is Driving Demand for Model Routing

18 August 2026 at 21:41

With the intense competition among frontier model companies, together with ever-increasing power of open-weight models like Kimi K3 and Qwen3.8-Max, model routing has become a key part of AI deployment. We’ve just seen Stripe buy OpenRouter for over $7B, but the trend is equally hot in enterprises.

Glean, co-founded and led by ex-Google Distinguished Engineer Arvind Jain, specializes in bringing AI to large organizations. It was last valued at $7.2B after a $150M Series F fund raise last June. This year, it reached $300 million in annual recurring revenue (ARR) — a three-fold increase over 15 months.

Part of Glean’s mission is to select which model to use for each task — or indeed if an LLM is even required.

“A big goal of Glean is to avoid using LLMs for tasks where we don’t need them,” Jain told Latent Space. “Sometimes you’ll see queries in Glean where people are adding two numbers or multiplying two numbers. They could have used a calculator to do that.”

But what Glean is mostly trying to do is bring what Jain calls “one really powerful personal co-worker” to enterprise employees. And that means being a kind of meta-harness for leading LLMs.

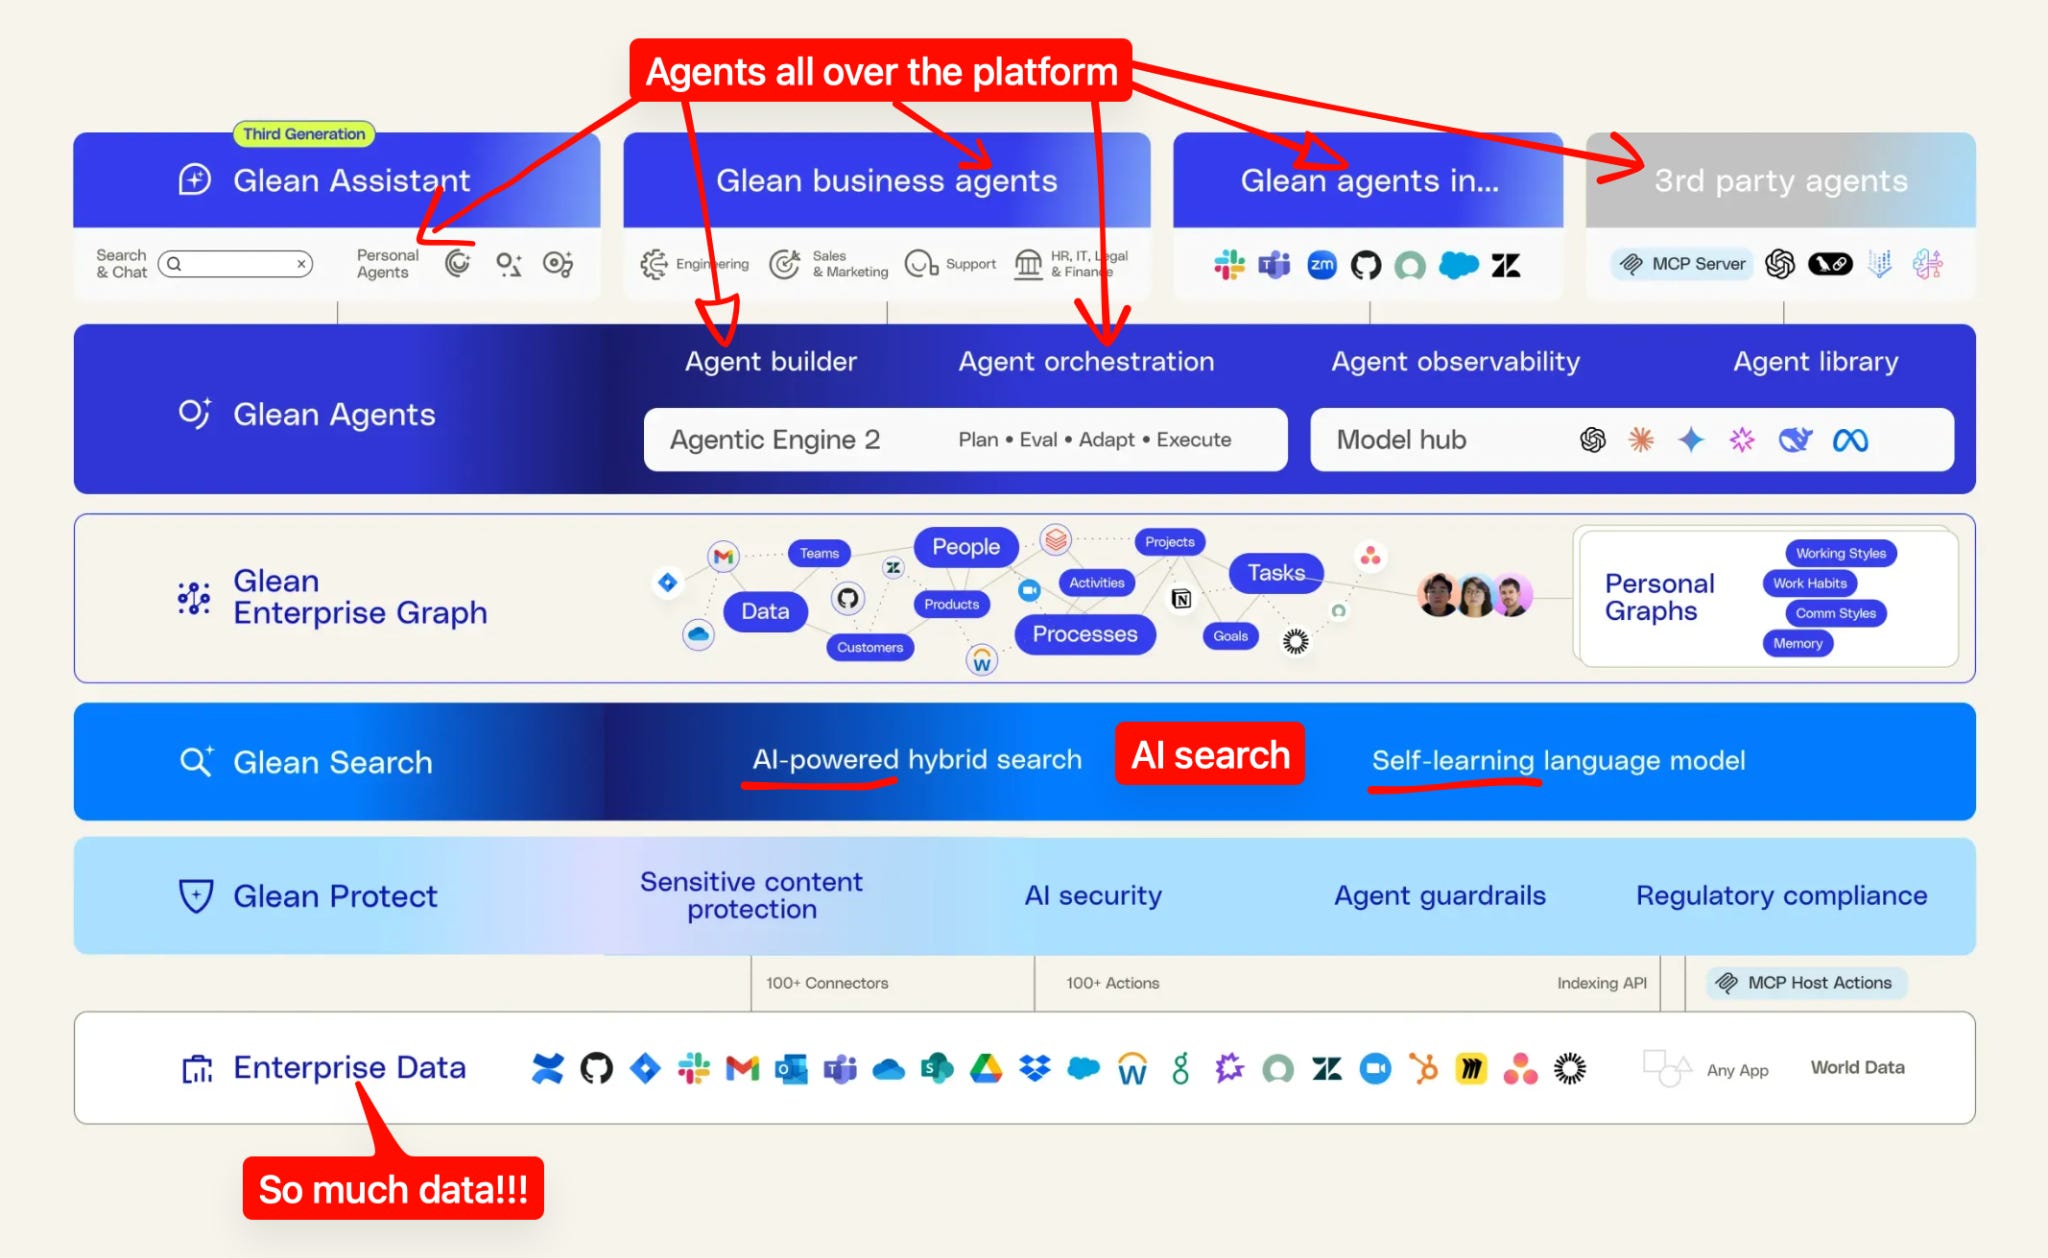
Glean announced its third-generation Glean Assistant last September; these days, agents are a big part of Glean’s system.

“You can think of Glean today as a superset of ChatGPT, Claude, Gemini, Grok,” Jain said. “All these different AI products that we’ve been using day to day, Glean combines the power of all of them into one experience.”

With enterprises, bringing AI technology into an organization is just half the challenge. The other half is bringing organizational knowledge into the AI systems.

“Ultimately our business is to deeply understand your data, knowledge, and information, but also how work happens inside your company,” Jain said.

How model routing is done in Glean

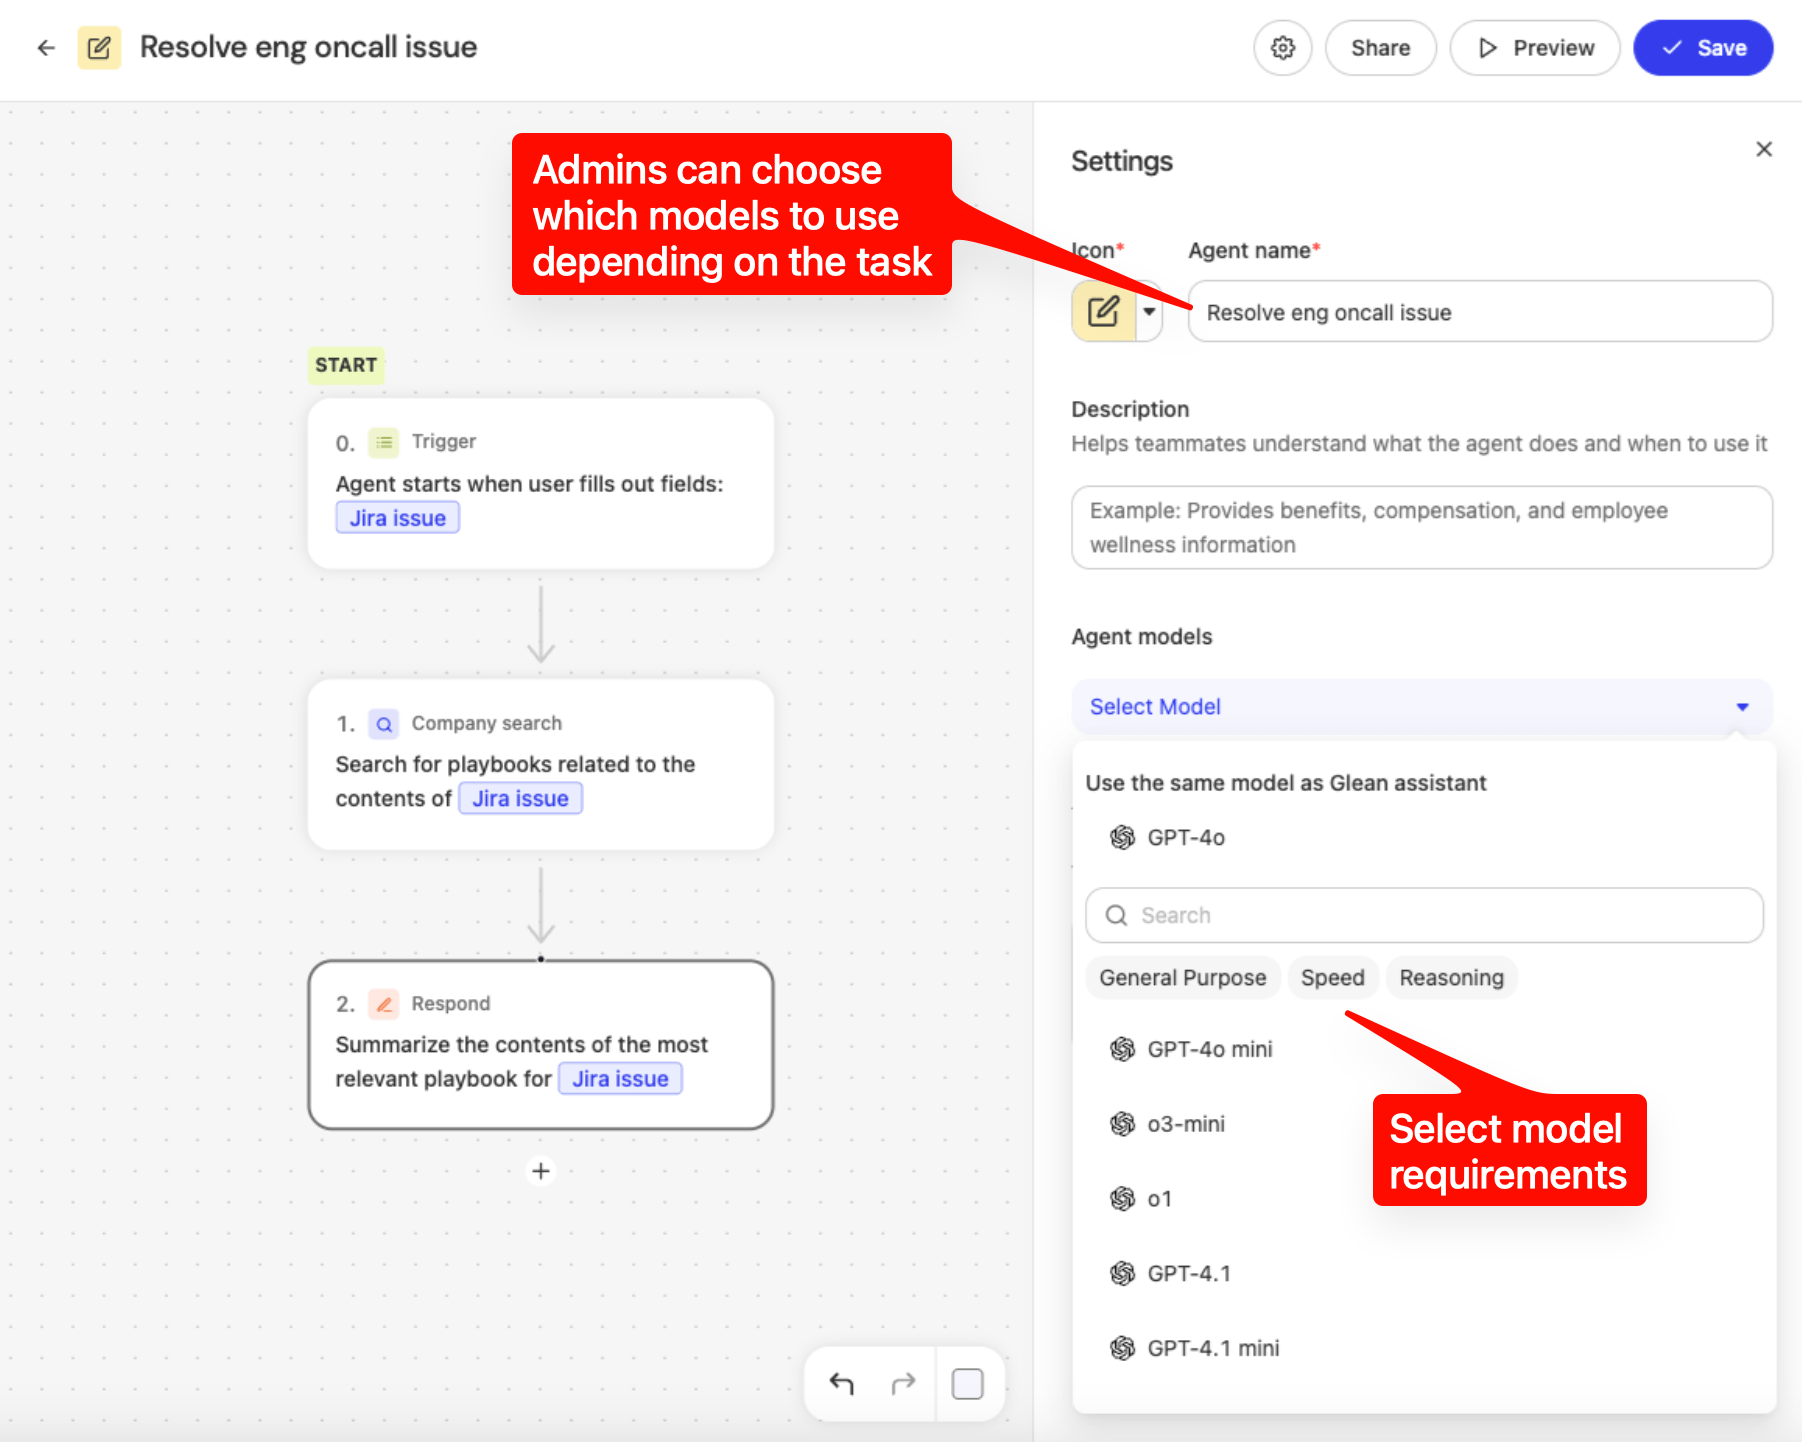
So what does model routing mean in practice? Basically, Glean offers three levels of model selection:

  1. Employees can explicitly choose a model.

  2. Administrators can restrict models or impose usage limits.

  3. Glean’s automatic mode selects a model dynamically for each task.

Configuring models for certain tasks.

It turns out automatic mode is mostly chosen by Glean’s customers for economic reasons.

“Why are people talking about model routing? Why are they excited about it? It’s mostly because of cost,” Jain told us.

Another co-founder of Glean, engineering lead Tony Gentilcore, recently claimed that Glean “is 4x more cost-effective” than Claude Code, “averaging $0.45 per task versus $1.84 for Claude Cowork.” He put that down to Glean’s “harness and routing capabilities.”

Individually, many of us are getting great value out of our $20, $100 or $200 monthly subscription to an LLM provider. But for an enterprise, the per-user costs can easily spiral out of control.

“AI models have been getting expensive,” Jain said. “Like, if you look at Opus or the latest models of GPT, the most advanced models. Not only are they very powerful, they can run much more complex tasks than the previous models. But on a per token basis, they’re more expensive — sometimes double or quadruple the rates of the previous models. And then users actually use them to run much longer tasks. So you’re spending, like, 10 times, 20 times, more, on a per user basis, than what you were doing last year. So the costs have gone up a lot.”

The human feedback loop

Another key factor in Glean’s rise is that it gets to see how ordinary business users are using AI. The product is potentially deployed to every employee as a “coworker,” and it’s also used to build and deploy agents across all departments and functions.

Among its customers, Zillow reports 80% adoption across 7,000 employees, while at Booking.com, “Glean became the first AI platform adopted company-wide.” That kind of penetration gives Glean an enviable view into how AI is being used in enterprises.

“So we are getting to observe what people are actually doing with AI on a very broad basis,” said Jain. “We are getting to see when they’re on different types of tasks with AI, what models do they select first, and when they are not satisfied, when they actually upgrade to some other model [that] actually gives them the right results.”

This human feedback loop, at scale, helps improve the model routing system.

Here’s Waldo, gathering raw materials

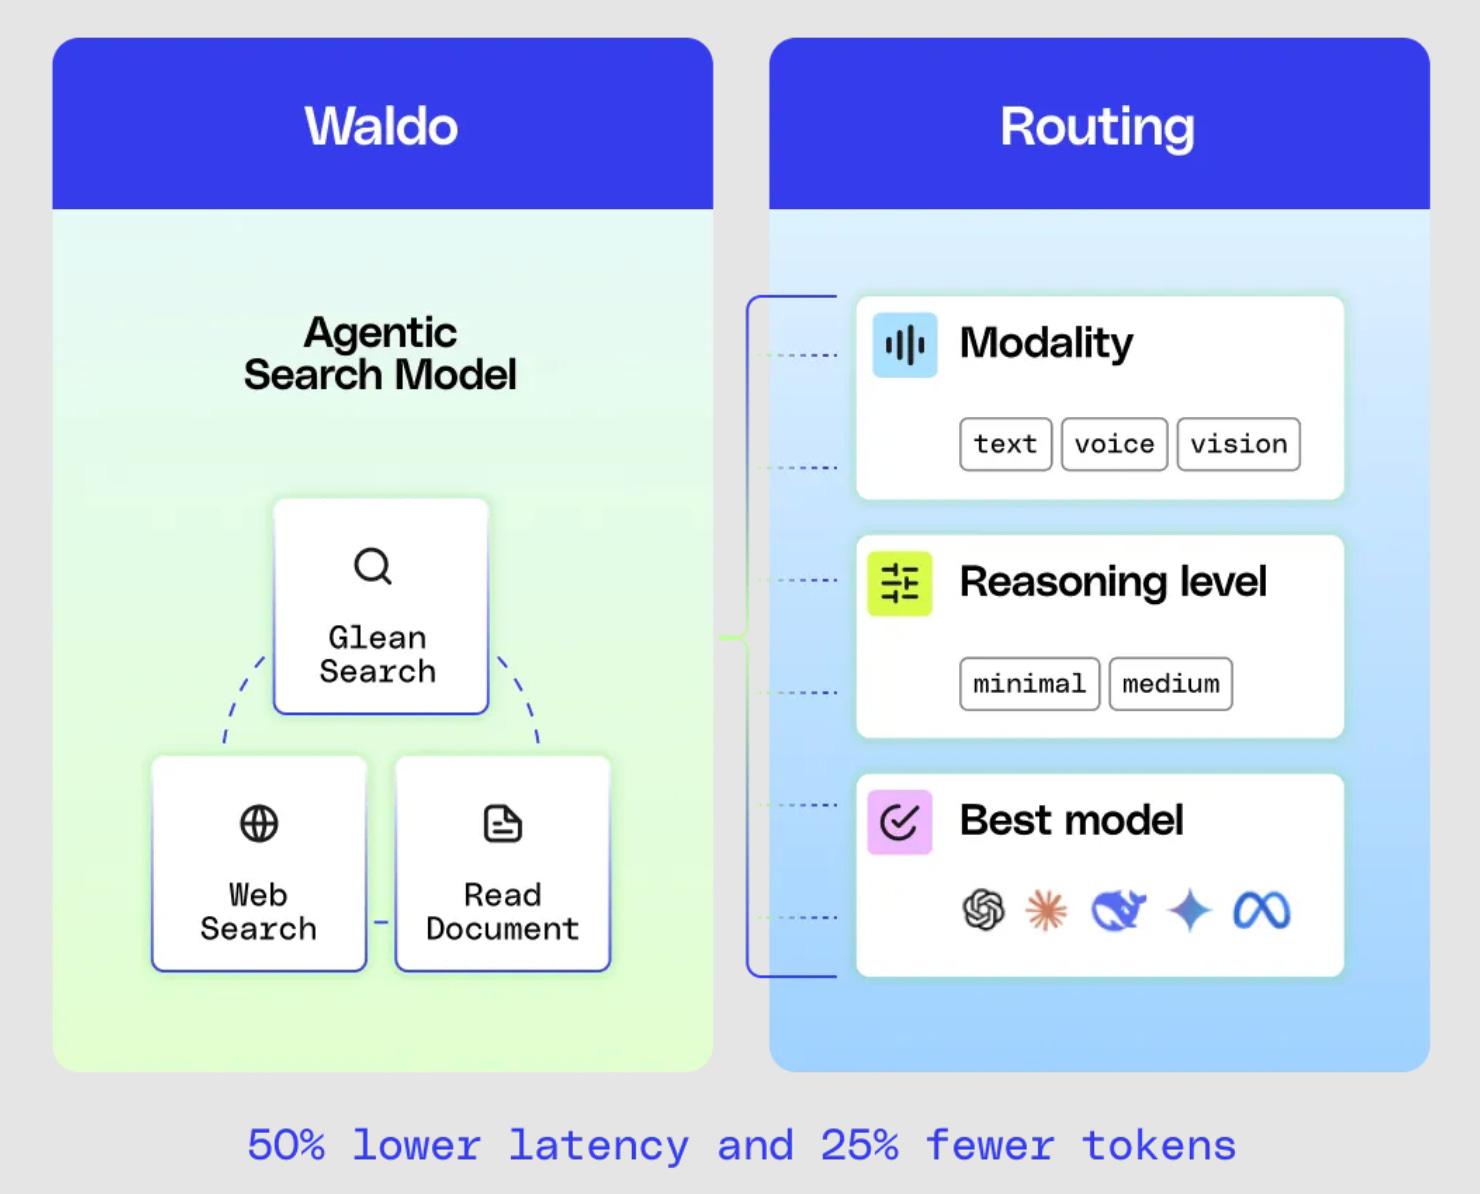
Another part of Glean’s architecture is a model called Waldo, which Jain described as sitting on top of the large language models. Waldo was introduced in April as “Glean’s first agentic search model.”

Glean claims that Waldo, its agentic search model, “reduces latency by 50% and tokens by 25%, reserving advanced models for work that needs them.”

In a technical blog post, Waldo was portrayed as a kind of filtering process for user queries: it “decides how to break down the question, which tools to use, what to read next, and when it has enough evidence to hand off to a frontier model for a high-quality answer.”

This means the model routing is happening after Glean has determined what Jain calls the “raw materials” that are needed for the task.

“We’re able to assemble the raw materials needed to do the work without burning LLM tokens,” he added.

A corollary of this is that a cheaper model with better context may outperform a frontier model loaded with irrelevant data.

The rapid rise of open-weight models

Jain confirmed there is now significant interest from enterprises in open-weight models, primarily due to cost concerns. But this has only happened over the past few months.

“Last year, the usage [of open source LLMs] was minuscule and nobody was really seriously considering open source,” he said. Partly that was because of the “stigma” of many of these open source models being developed outside the US.

But suddenly, interest among enterprise customers has risen.

Jain’s tweet on July 27, 2026, in support of open-weight models.

“So in the last three months, because AI got so expensive, businesses have started to find it untenable to maintain these AI investments,” Jain said. “Given that open source is an order of magnitude cheaper to do tasks, it has created a lot of interest. Today, I can say that in most enterprises, they are considering open source models to be a key part of their AI strategy.”

More than that, organizations tend not to rely on just one or two providers anymore — and the rise of open-weight models is driving this trend.

“Nobody is willing anymore to rely on only one model provider, or two, and nobody thinks that they can survive without open source,” Jain said.

Evals

You can’t have a serious conversation about AI in 2026 without discussing evals — assessing the quality of results from LLMs. I asked how Glean goes about doing evals and how that is fed back into the model routing system.

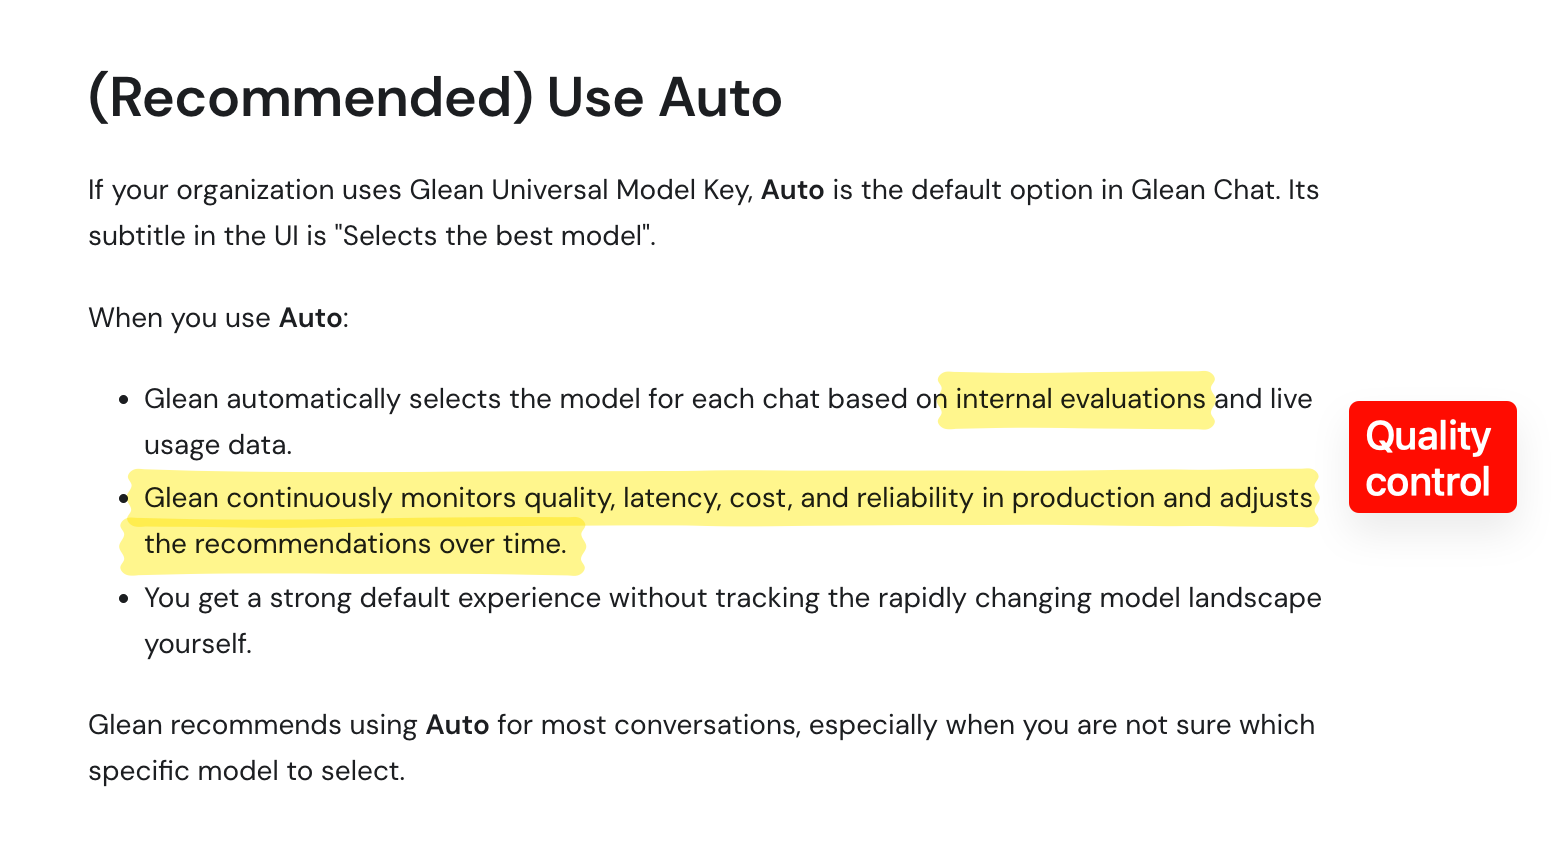
Jain said they have “internal testing systems” where they compare real-world workloads, across different query classes, with alternative options. So they let the model choose a route and in parallel they try to complete the same task with “some other models which are maybe a little bit less expensive and a little bit more expensive.”

How Glean monitors quality.

Glean then uses “AI-based judges” to determine “how spot-on the model router was.”

“So there’s this continuous learning that gets updated with new real-world traffic, where basically what is happening is that you let the model router do the work for the user, but behind the scenes you run the same task,” Jain explained.

He added that this is done for only “a small fraction” of the real-world usage, but at Glean’s scale that’s more than enough to help train and improve the model router.

From enterprise search to end-to-end AI platform

One of the trends we’ll be monitoring going forward on Latent Space is how AI systems are being implemented within enterprises — and how some of these organizations are going full-on AI-native.

Glean is an especially interesting company to monitor for these trends, since it was one of the very first enterprise-facing AI companies. It was founded in early 2019, initially to tackle enterprise search. As Jain put it, Glean was “the first player to work with transformers and language models for businesses.”

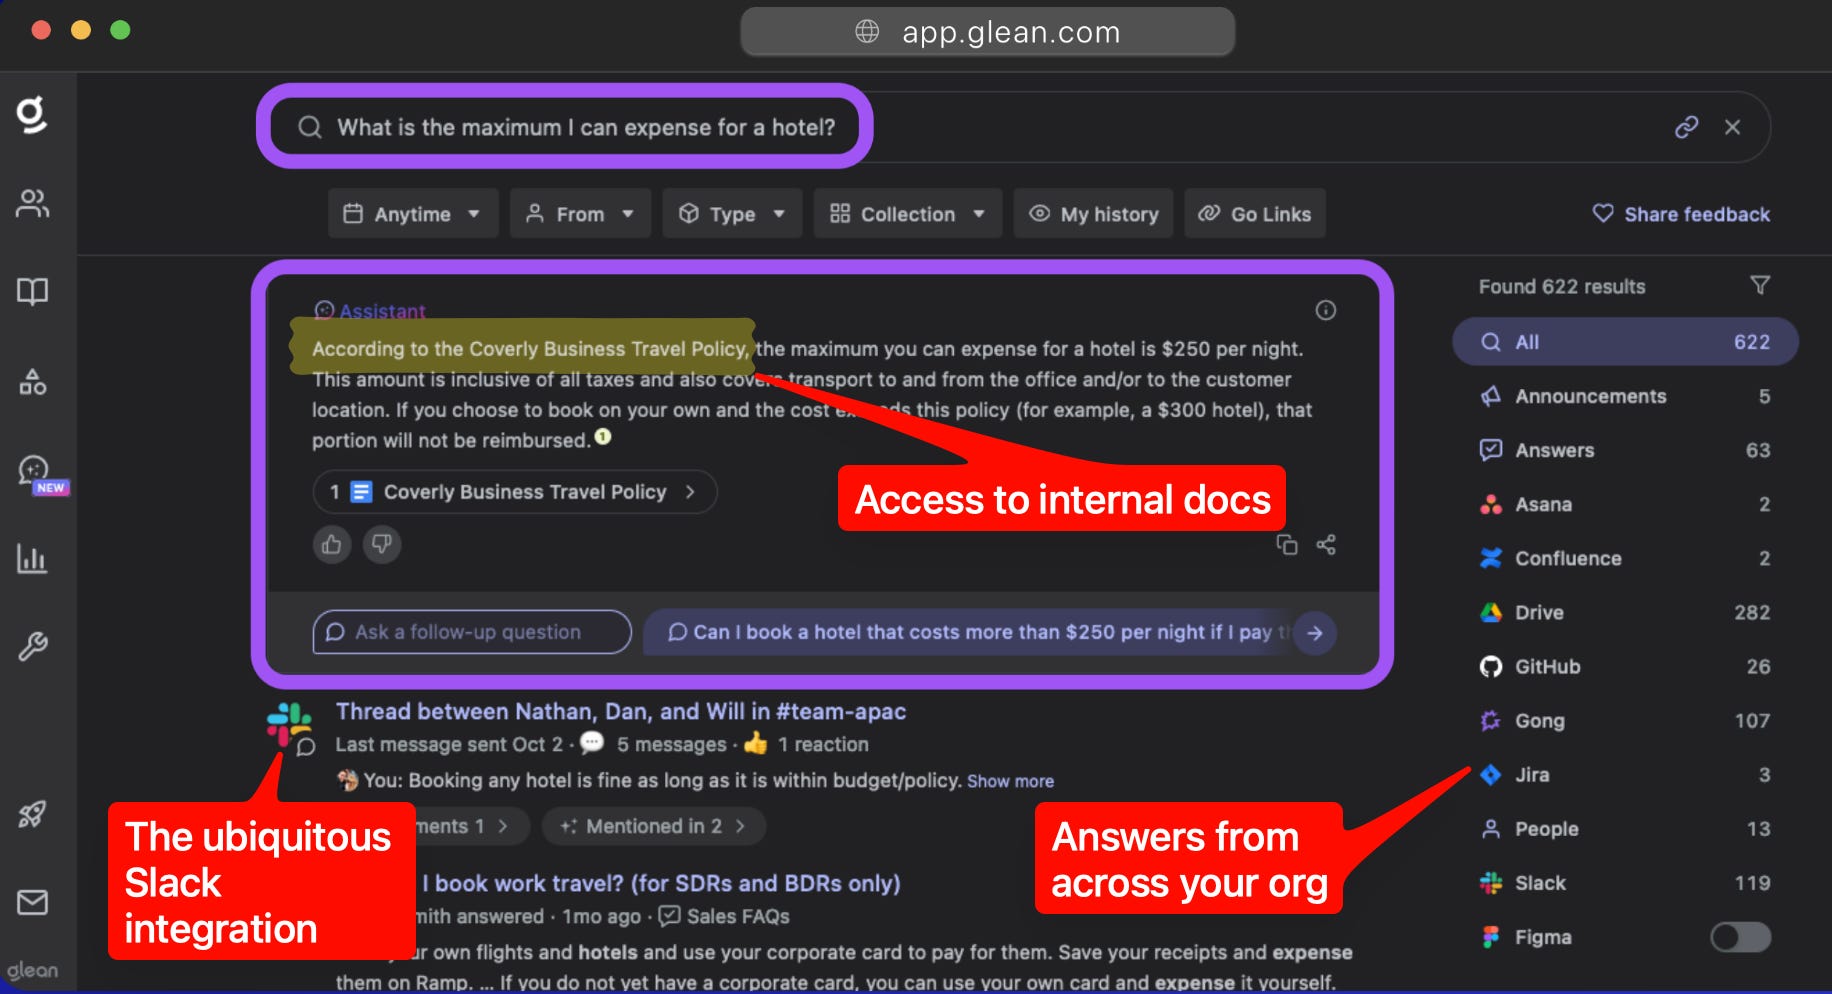
Glean’s AI Answers draws “directly from your organization’s documentation.”

In April 2023, swyx interviewed Deedy Das of Glean. Das, who is now a partner at venture firm Menlo Ventures, was a founding engineer at Glean. But even at that point, in 2023 — about four years into Glean — the focus was still mostly on enterprise search.

Now, in 2026, enterprises aren’t just using AI for search. AI is becoming an integral part of every employee’s workflow.

That makes Glean a much ‘sexier’ AI company, as Das himself said on his return to the Latent Space podcast last November. “Broadly, one of the things that I love about Glean is it’s such a boring unsexy company that became sexy later,” he said.

This brings us full circle back to model routing. Arvind Jain ended our discussion by calling Glean an “end-to-end AI platform” that gets “used very heavily” by its enterprise customers. This, he added, allows Glean to “have that data that is required to do effective model routing.”

React for Agents: Astro Creator Brings Hooks to his Meta-Harness, Flue

15 August 2026 at 15:46

Agent frameworks for developers are still at an early stage, with the likes of Vercel’s eve and Fred Schott’s Flue — both launched this year — setting the early template.

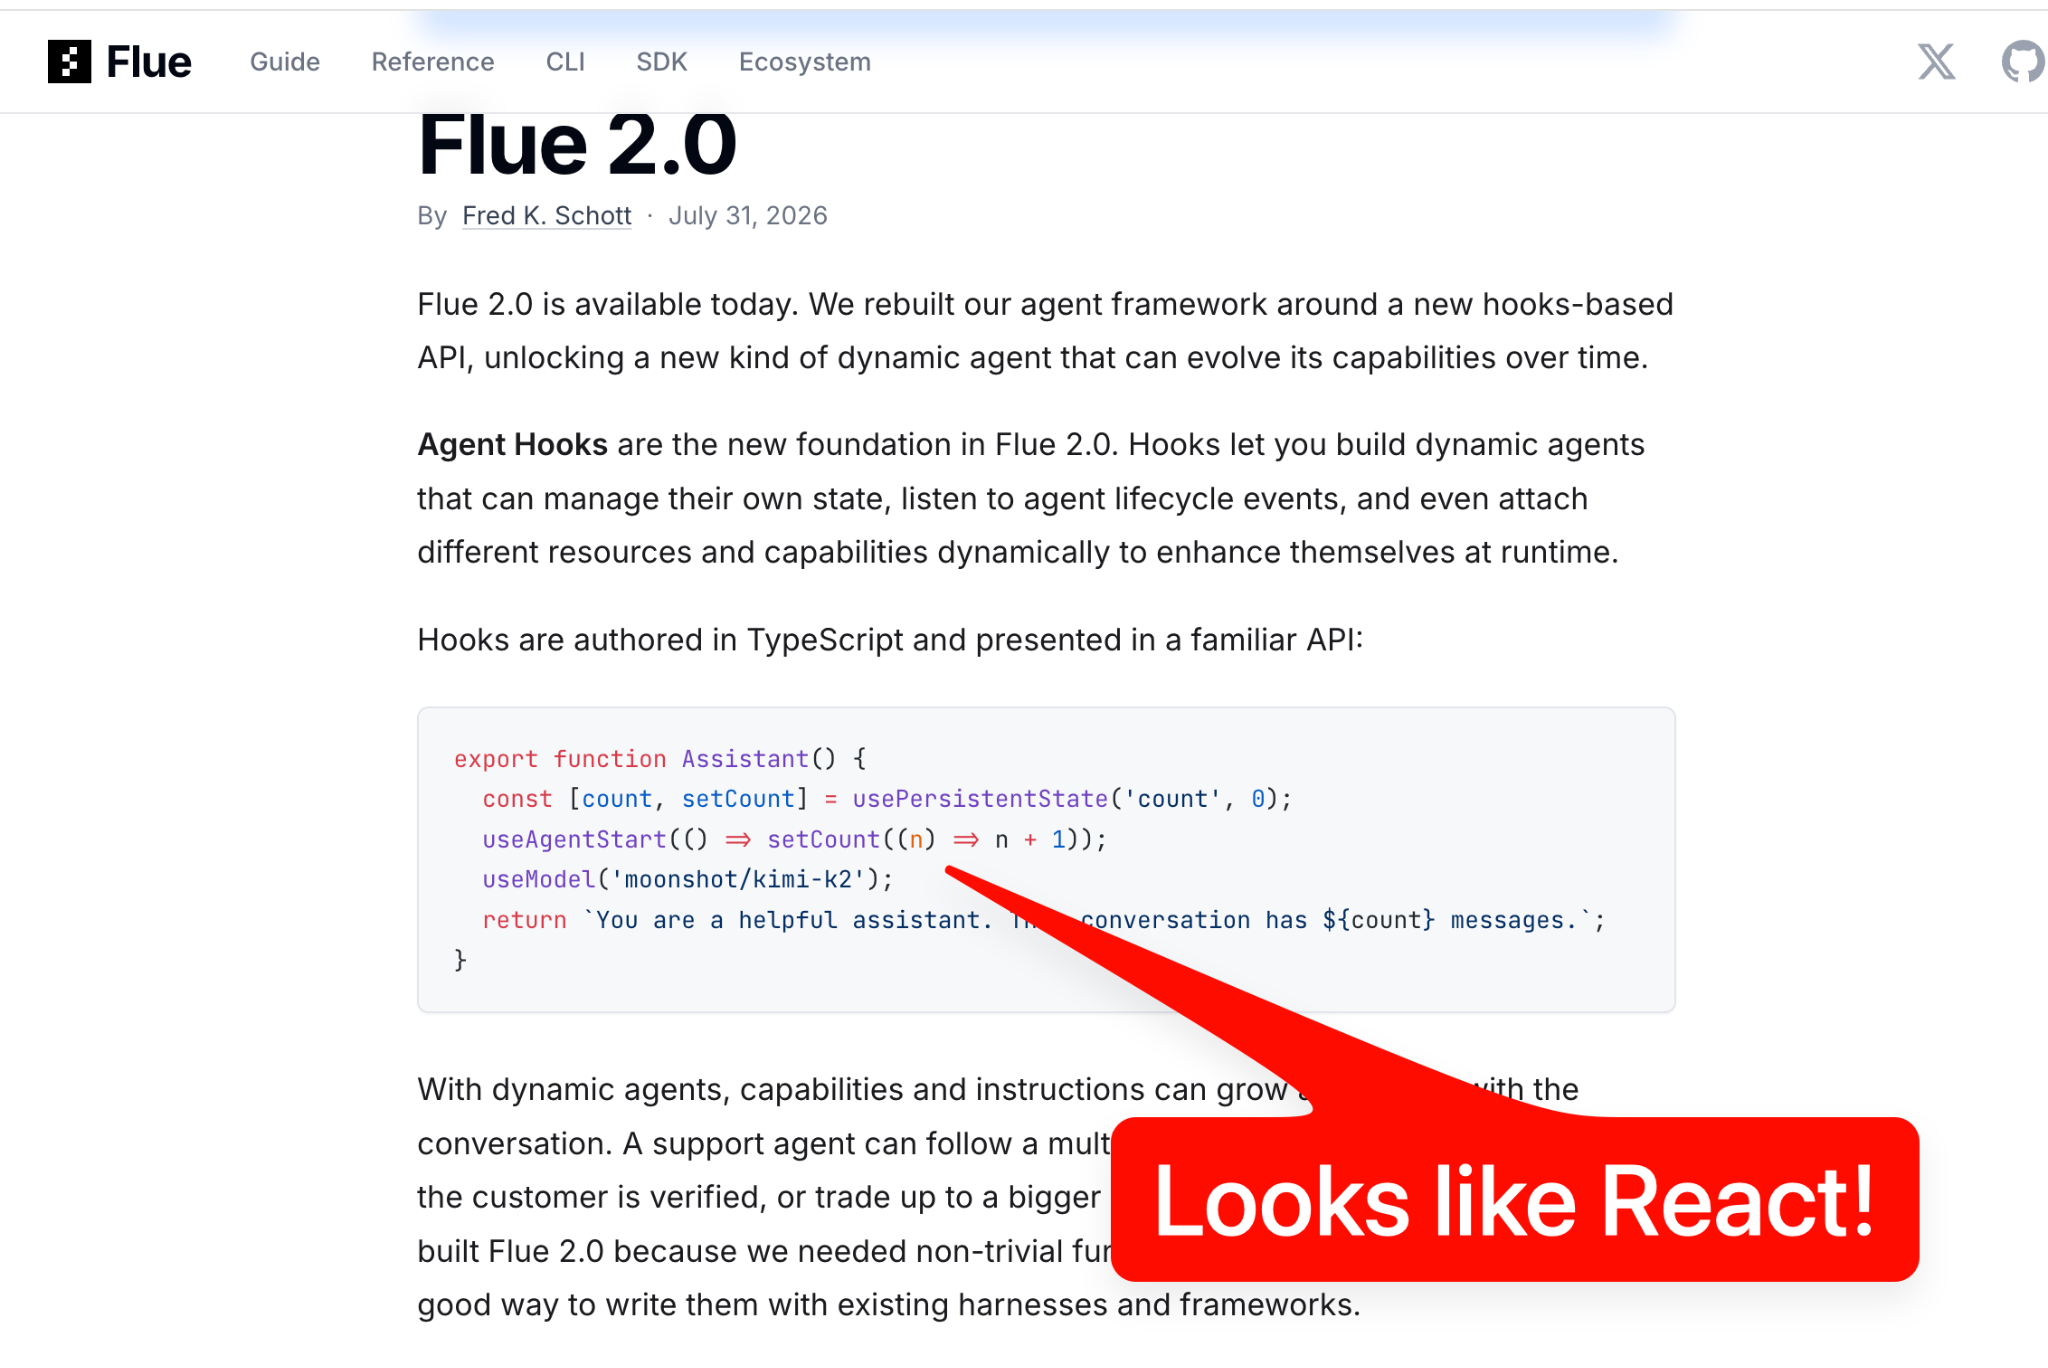
Schott is the creator of the web framework Astro, which led to his company being acquired by Cloudflare in January. He’s just released version 2 of Flue, its first stable release, which has as its foundation React-style “Agent Hooks.”

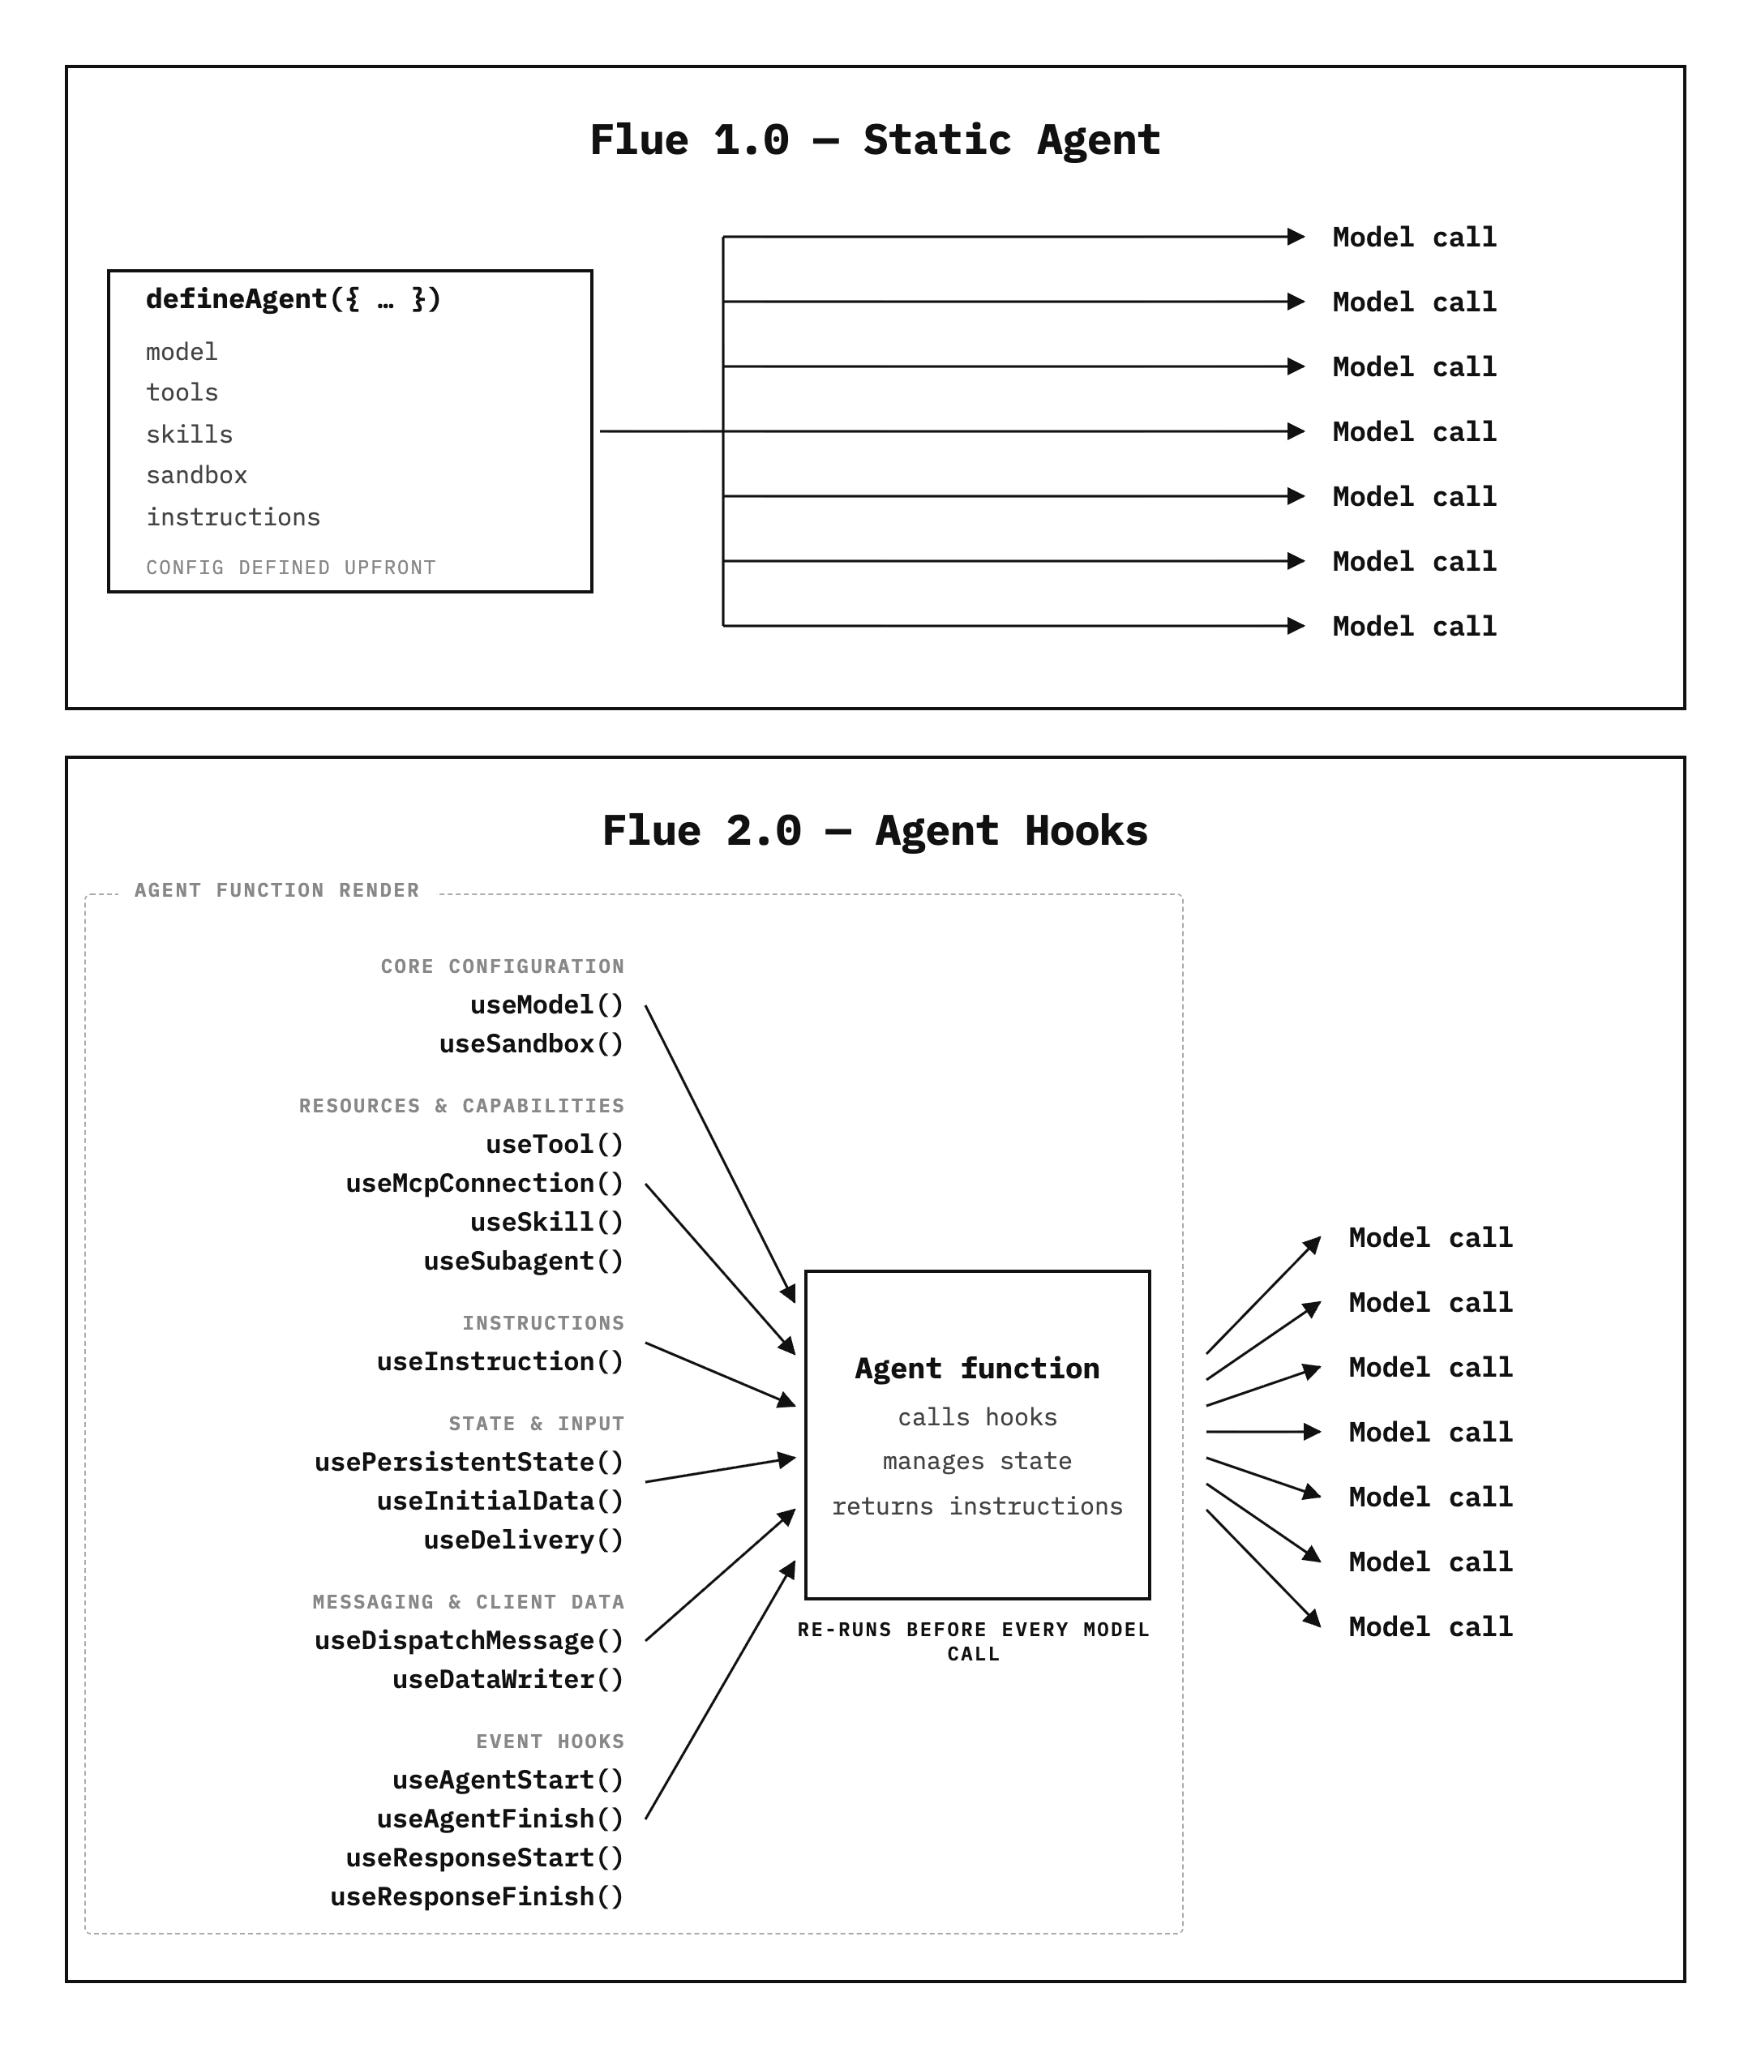
In Flue, an agent is represented by a JavaScript function. This function “re-renders on every turn,” meaning before every model call.

The addition of hooks came after Schott realized that React’s composability would be a great fit for agent development.

“I originally tweeted that we were building the Astro for agents or the Next.js for agents,” he told us. “But then I realized: maybe no one has even built the React for agents.”

Editor’s Note: we last talked about the React for Agents with Bret Taylor, CEO of Sierra and Chairman of OpenAI:

“We’re still trying to figure out who the reactive agents are and the jury is still out… We’re sort of in the jQuery era of agents, not the react era.”

Hooks are authored in TypeScript. According to the Flue 2 launch post, they “let you build dynamic agents that can manage their own state, listen to agent lifecycle events, and even attach different resources and capabilities dynamically to enhance themselves at runtime.”

There are 16 built-in hooks in Flue 2, including useSkill(), useTool(), useSubagent(). You can also add custom hooks.

How Flue evolved via React-style hooks; diagram by Richard MacManus

What hooks open up for developers is that they make an agent much more dynamic, by allowing its configuration to change as a conversation or workflow progresses. Schott said this is needed to build “real support bots, real triage bots,” because they can’t be fully configured in advance. The agent can’t just be static — it has to adapt in real-time to what the user wants or the situation demands.

Agent hooks bring those capabilities to Flue. For example, a support agent might bring in an account management tool after first verifying a user.

File based magic is an antipattern

Schott’s thinking about how to build an agent framework has evolved rapidly since he publicly launched Flue 1 in early May. Initially, he wanted to take existing web framework concepts and apply them to his new agent framework. He uses file-based routing as an example.

“So we kind of naively ported that over to Flue, thinking — great, well, I’ll put your five agents in these five files, and that’ll be the five routes that they expose. But for a lot of people building with Flue, especially the bigger customers, their whole company is one agent. They don’t care about routing. There’s one agent.”

So after the first Flue users showed these early patterns, composability became front of mind for Schott. That led him back to React.

“As you can see from the Flue 2 API, we’re taking it more from React [...] than we are from Astro or Next.js — where it’s less about routing and these website concepts and more about, at its base level, how do you compose an agent on many different things?”

Flue’s central proposition: agents need a harness

A key concept in Flue is that an agent must have a harness — meaning that it’s in an environment where it has access to the context and capabilities needed to accomplish various tasks.

“Instead of you and your code driving the LLM and telling it what to do with scripts, you’re putting the agent into this harness, and it is able to drive itself and work through problems,” explained Schott.

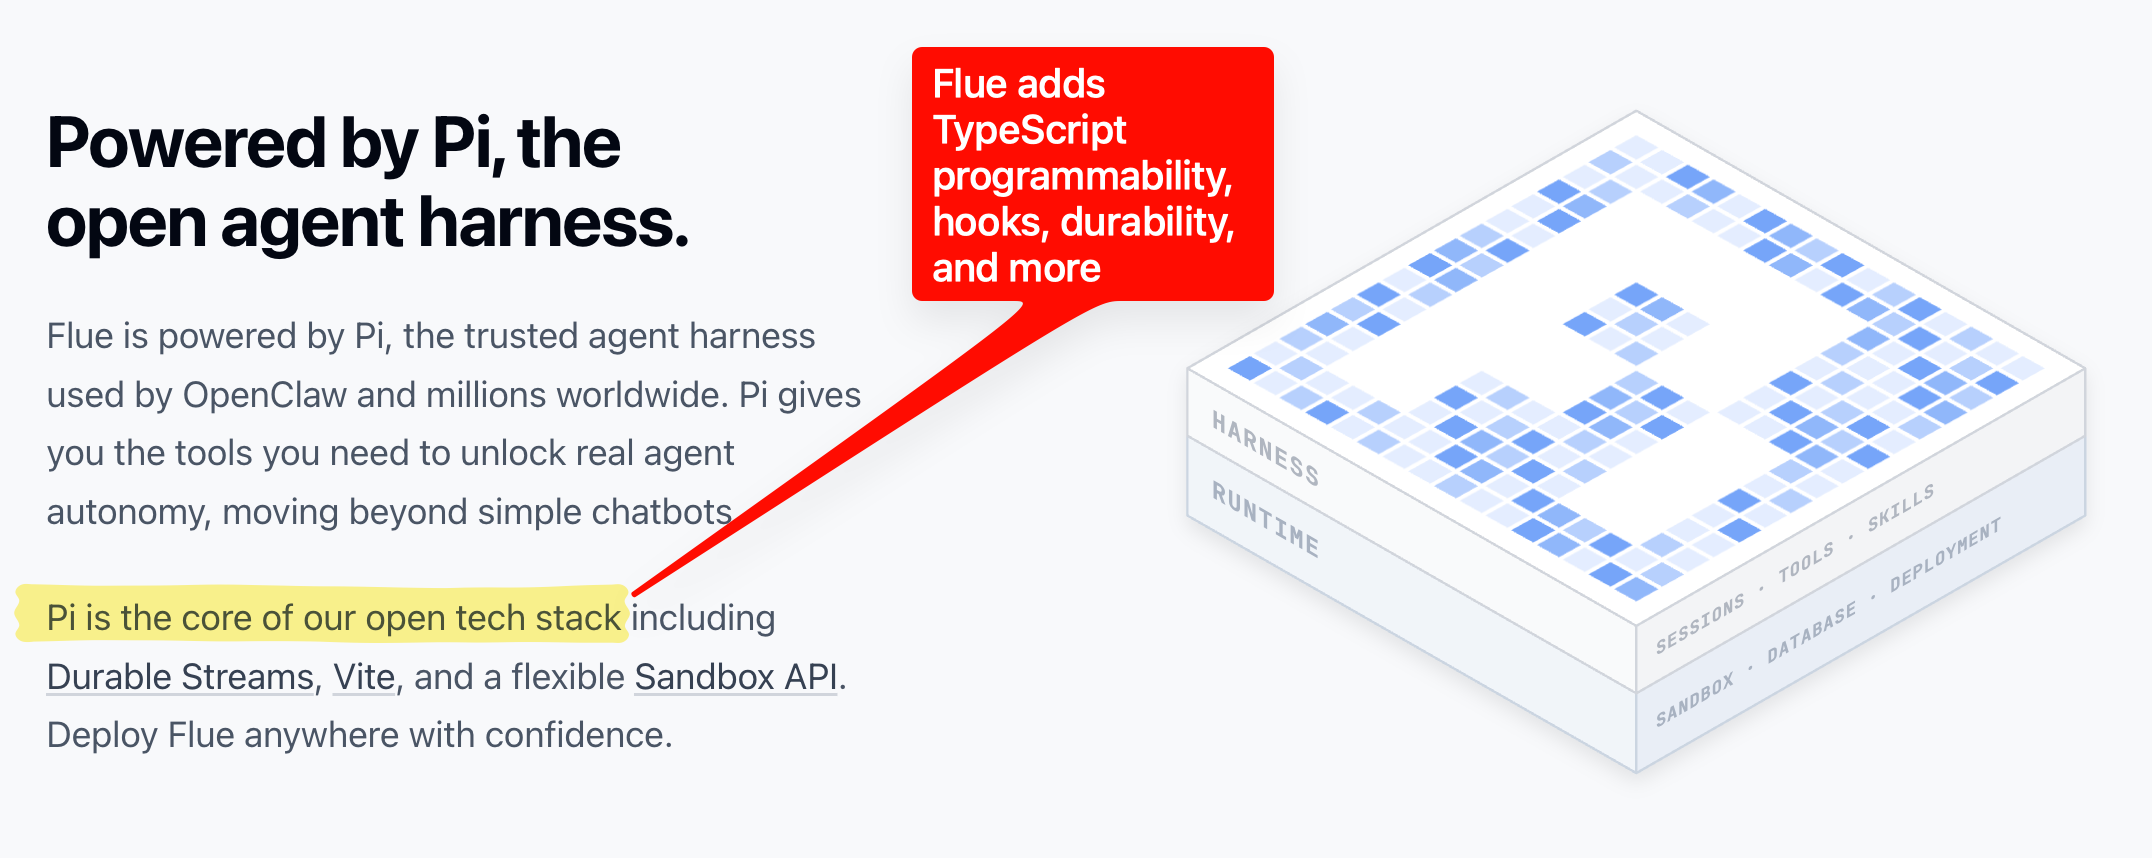
Flue is built on top of Pi, an open source minimal harness. Essentially, Flue is an opinionated take on Pi — adding features that Schott thinks are helpful to developers building agents. For example: hosted agents in Flue 2 are now built with Vite, an open source build tool.

Indeed, Schott likens Pi’s role to the foundational role that Vite now plays beneath Astro.

“I think Pi can serve that role, where it’s the right abstraction — it doesn’t do too much, but it gives the right APIs that then we can go and say, well, let’s have an opinionated take on this that does more.”

Building on Pi meant committing to having a built-in agent harness.

“Our early bet was that the harness is actually not a feature, but it’s fundamental to what you think an agent is,” Schott said. “There is no agent without a harness.”

Building Flue agents with coding agents

The Flue project began earlier this year within the Astro repository, as an issue-triage system. At first, it was an LLM-driven script or workflow reviewing issues. But then, explained Schott, it gained the ability to take actions in the repo.

“It started to transition from just automation in a repo to wanting to take the Claude Code experience, make it headless, make it hostable and run it in the cloud.”

So that’s when the idea of a harness as anchor emerged. Indeed, in his v1 launch post in early May, Schott described Flue as “like Claude Code, but 100% headless and programmable.”

I myself tested out Flue using Claude Code, which guided me through setting up my first Flue agent. And Schott confirmed this is how many developers use Flue.

“We very much are building for them,” he said, regarding AI coding agents. “Our whole onboarding flow is that, you know, pass this prompt to your agent, it’s gonna guide you through it. All of our docs have markdown support.”

Where Flue fits in the agent development stack

The closest comparison to Flue is Vercel’s eve, which also treats the harness as foundational. Vercel and Cloudflare have been known to beef in public, but Schott is generous in his opinion of eve.

“Eve, I think, is the most directly competitive,” Schott said. “It came around at the same time, so it had that same take that a harness is built-in.”

Schott also referenced what he called the “OG agent frameworks,” which came before Flue and so weren’t created with a harness as the central concept. He listed Vercel’s AI SDK, Cloudflare’s Agents SDK, and Mastra (developed by the same team that built Gatsby, a web framework predating Astro).

While these “OG agent frameworks” are all adding harnesses now, Schott considers that an added feature — whereas Flue and eve both have built-in harnesses.

I asked where Flue sits compared to emerging “meta-harnesses,” like Databricks’ Omnigent and perhaps even the self-improving Exo harness.

Note: we’re also publishing our interview with Exo coauthor Alex Krentsel this weekend; it’s worth a watch and has a bonus discussion on OpenClaw architecture!

Schott rightly noted that there’s confusion about what the term meta-harness even means at this early stage. Regardless, he thinks having one API for working across all harnesses would muddle the story for Flue. His framework specifically defines how skills work in Flue, how subagents work, and so on. As he put it, “the framework [Flue] and the harness are very intertwined.”

He personally finds the meta-harness discussion fascinating, and has played with Exo, but says it’s “a different interest scenario that isn’t really related to hosted agents.”

The Cloudflare connection

Throughout the interview, Schott referenced being able to take advantage of his employer Cloudflare’s tooling and infrastructure. But he was also very clear that Flue is an “open source framework for every host,” as he put it, and he wants it to stay that way.

“The best tools are the ones that float above the host,” he said. “That opens the door for the most developer adoption and the most innovation.”

Host portability is one of Flue’s defining principles — and perhaps that’s where the fundamental difference to Vercel’s eve is. While eve can also be self-hosted, it is optimized to take advantage of Vercel’s many features. Of course that’s a known playbook of Vercel, which does the same thing with Next.js.

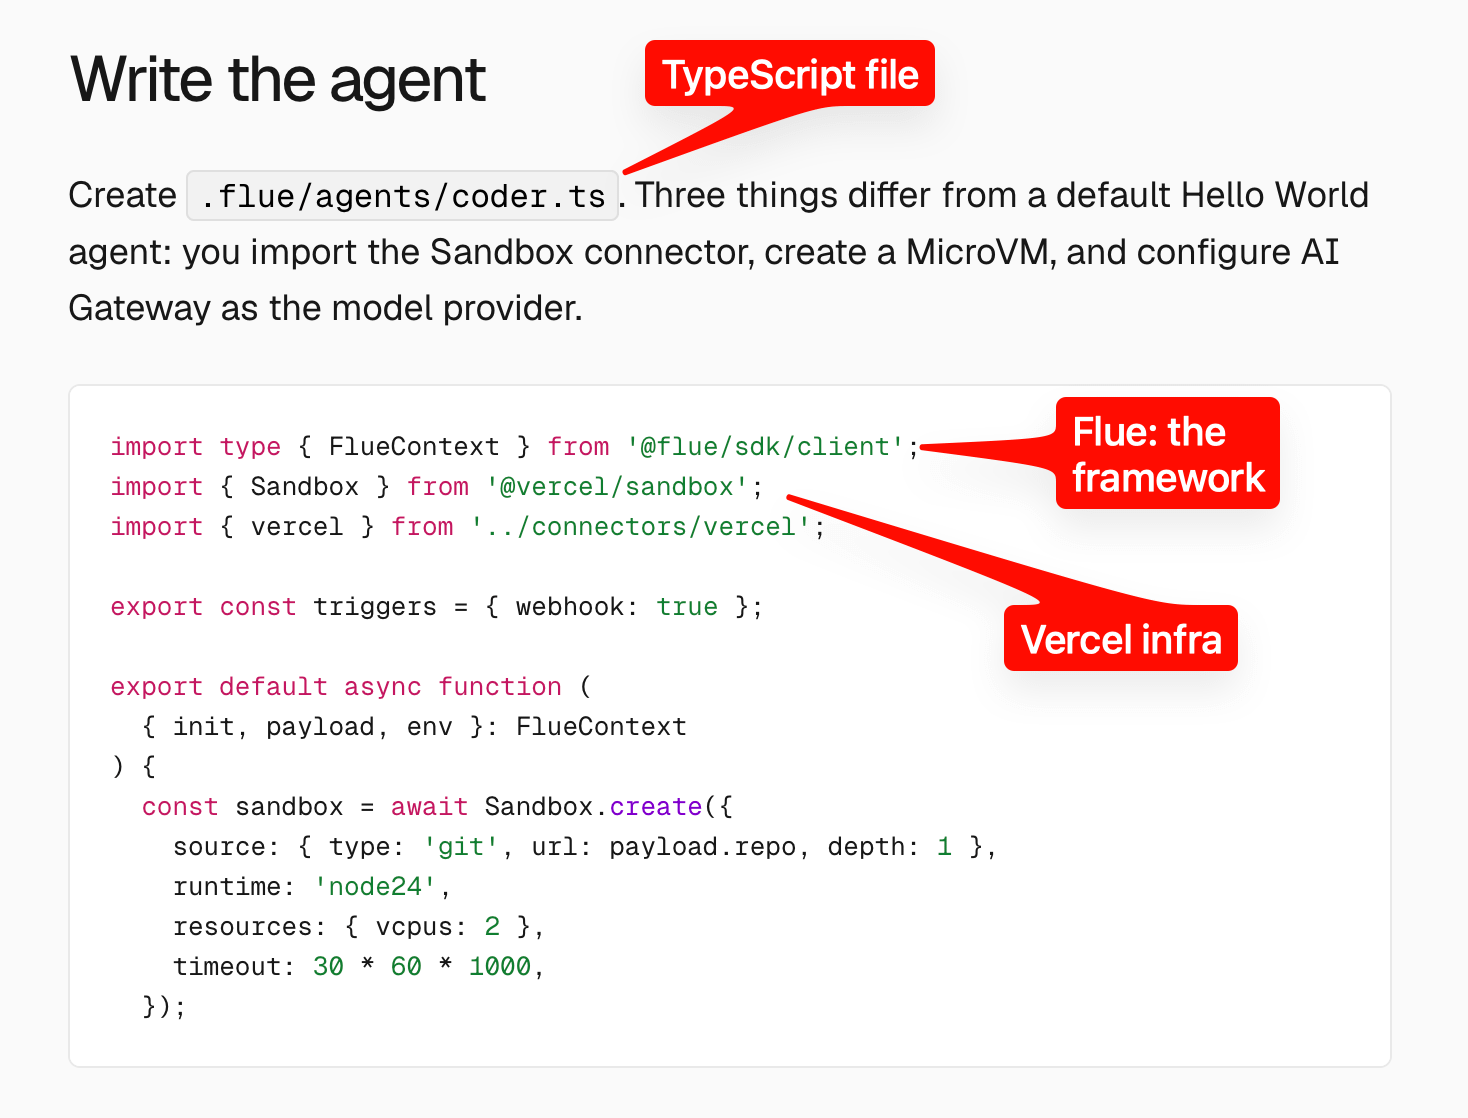
All that said, Vercel itself has shown that a Flue agent can be deployed on Vercel. So the two companies can play nice together.

I also mentioned LangChain’s new Managed Deep Agents offering as an example of hosted agent platforms coming onto the market. However, Schott said a managed agents product is not currently on Flue’s roadmap.

“It’s so early for us, we’re just focused on building the best harness,” he said.


Links to find Flue and Fred online; Richard is at @ricmac. This is a new written interview series we are trying out for subscribers — let us know your feedback!

Ontologies Are So Back: Why AI Agents Are Reviving the Semantic Web

30 July 2026 at 11:17

One of the most watched videos from the recent AI Engineer World’s Fair is a 20-minute talk by Frank Coyle, a professor of computer science who currently teaches generative AI and LLMs at UC Berkeley. Drawing on his decades of experience, Coyle re-introduced the concept and practice of ontologies to today’s AI engineers.

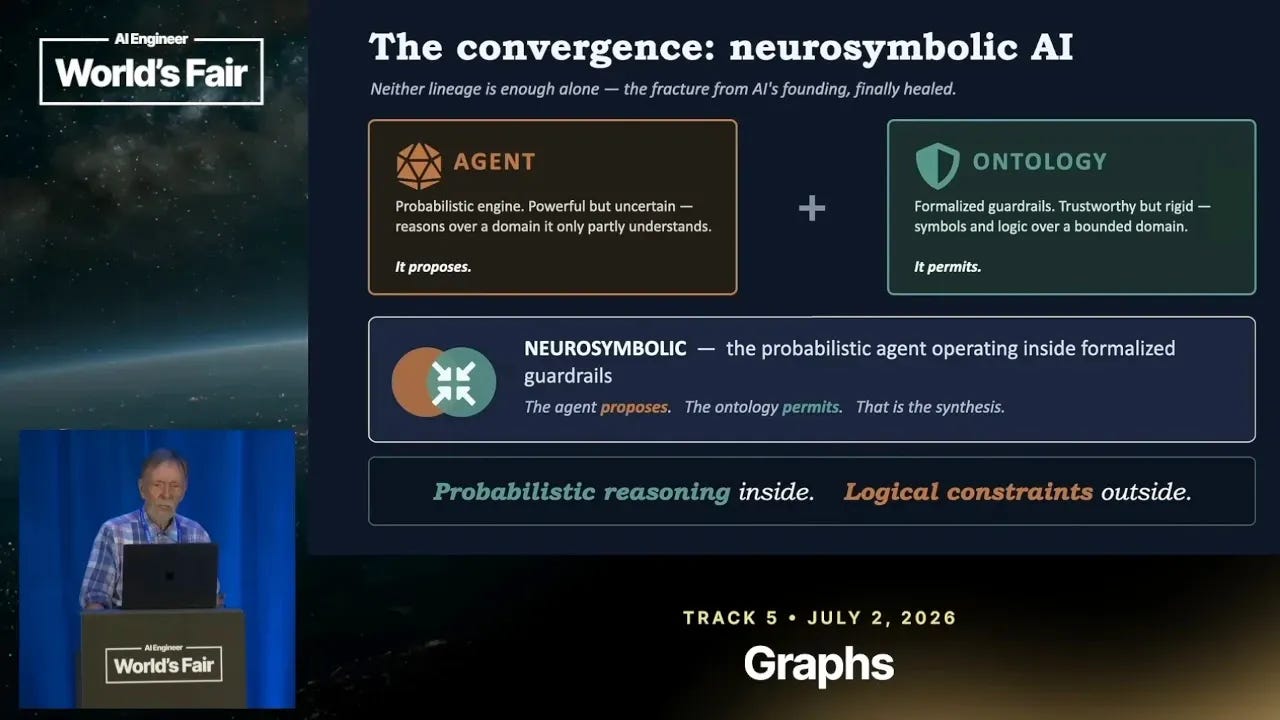
Coyle argued that while LLMs are very effective at providing probabilistic reasoning, for agentic systems to be truly effective they need “logical guardrails” — by which he means ontologies.

UC Berkeley professor Frank Coyle speaking at AIEWF 2026.

In computer science, an ontology is “a description of data structure – of classes, properties, and relationships in a domain of knowledge” (as nicely defined by Oxford Semantic Technologies). Coyle himself defined an ontology as simply “data as graphs.” He added that ontologies as a concept go right back to Aristotle, and have been used throughout the history of Artificial Intelligence.

The company Neo4j, known for its graph database systems, is also using ontologies in its agentic products.

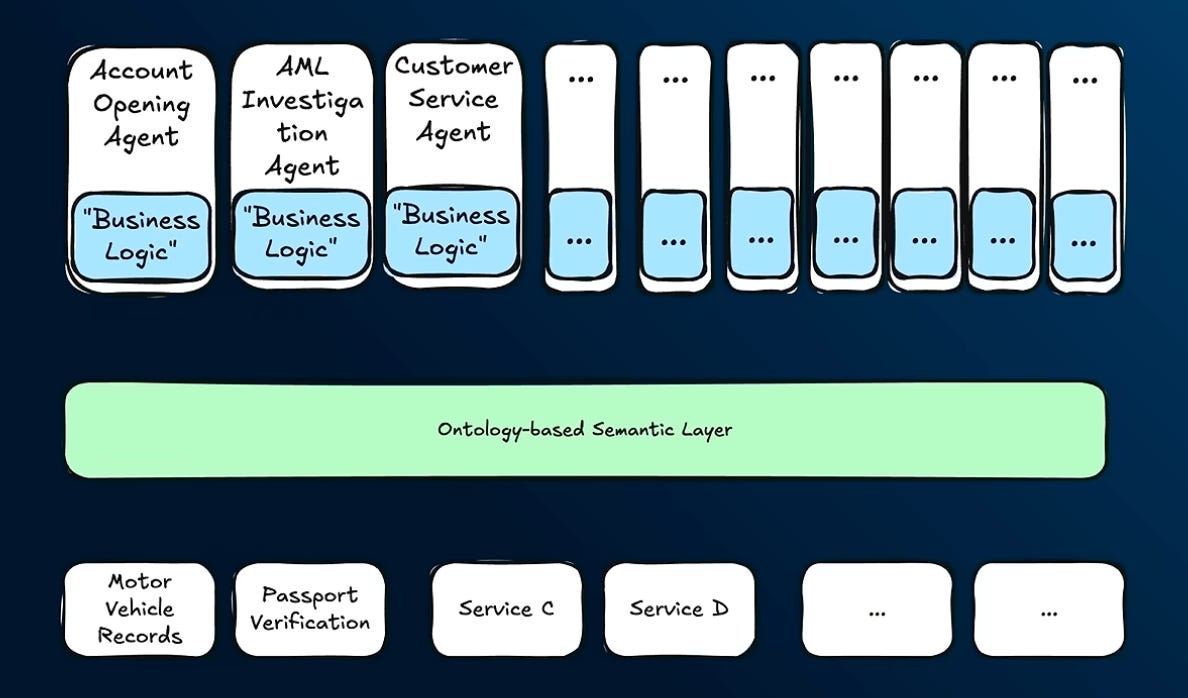
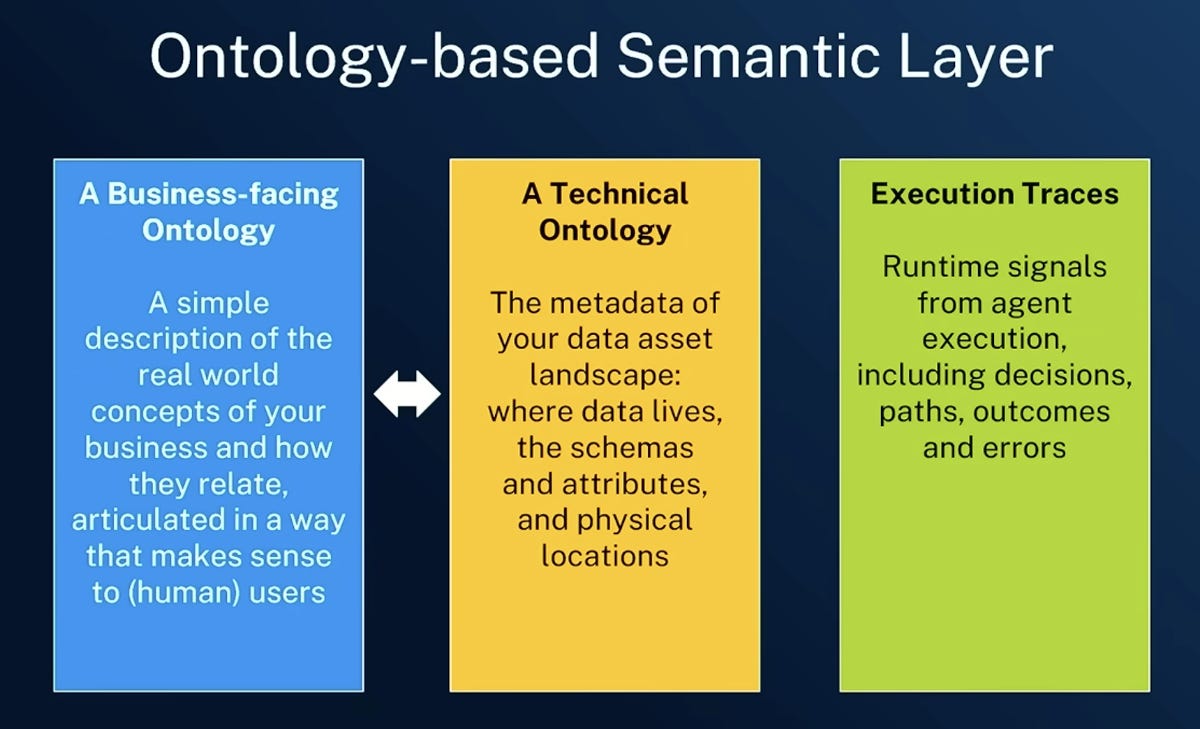
In a keynote session at AIEWF, Neo4j CEO Emil Eifrem talked about three different types of ontologies to enable a “smarter shared substrate” to run agents at scale. The first is a business-facing ontology, describing the key concepts in an organization; next is a technical ontology, which Eifrem described as “all the metadata of all the data sources and data assets in your enterprise ecosystem”; and finally execution traces, which are “the runtime signals out of your agent.”

Neo4j’s ontology-based semantic layer

What’s Old is New Again: the Semantic Web

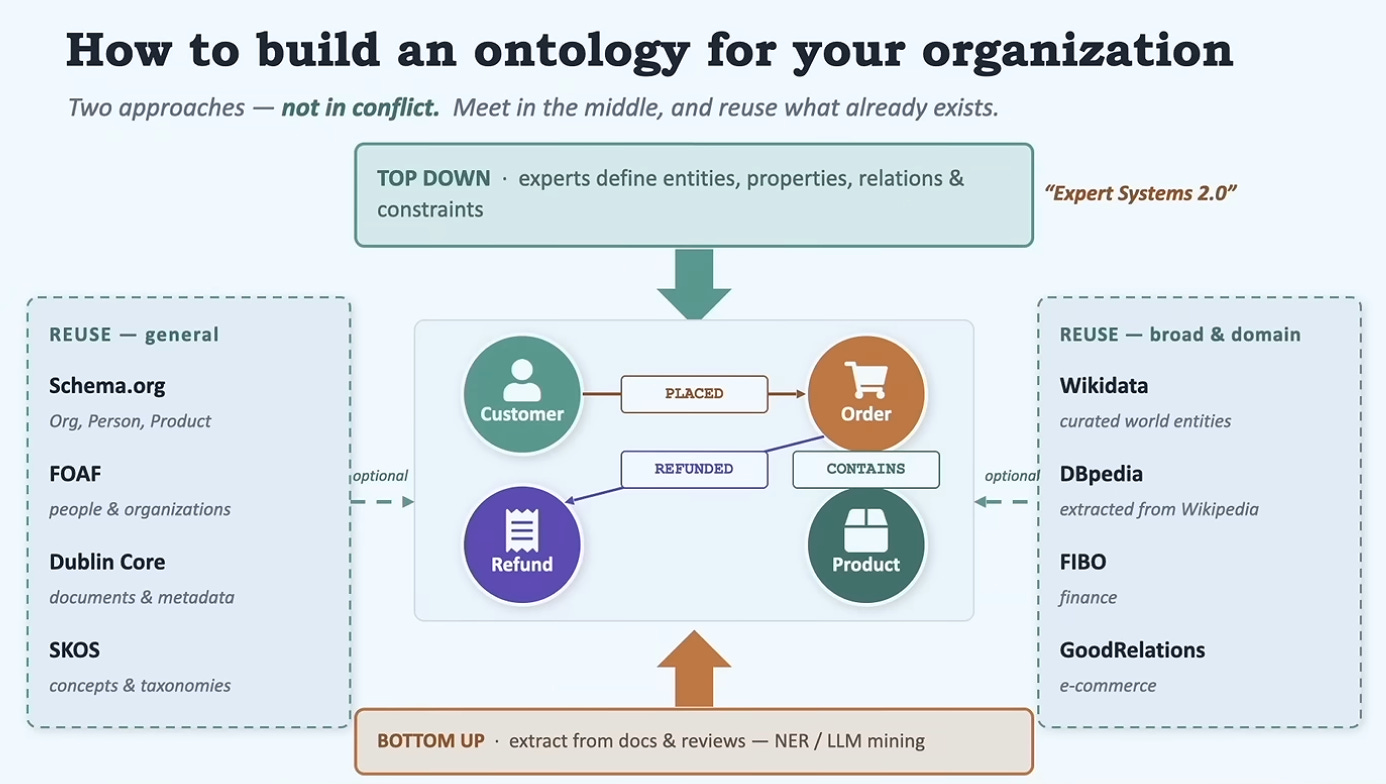
Frank Coyle thinks web ontologies are especially useful in building agentic systems. He mentioned Schema.org, FOAF, Dublin Core and other ontologies familiar to web developers — or at least, those of a certain vintage. He also mentioned “augmenting technologies” like RDFS (Resource Description Framework Schema) and OWL (Web Ontology Language).

One benefit of using these established ontologies is that they’re already in the training data of LLMs, so developers can just prompt for them — much better than reinventing ontologies from first principles.

“This stuff has been out there underlying a lot of what we already do,” Coyle said. “So take advantage of these things that already exist.”

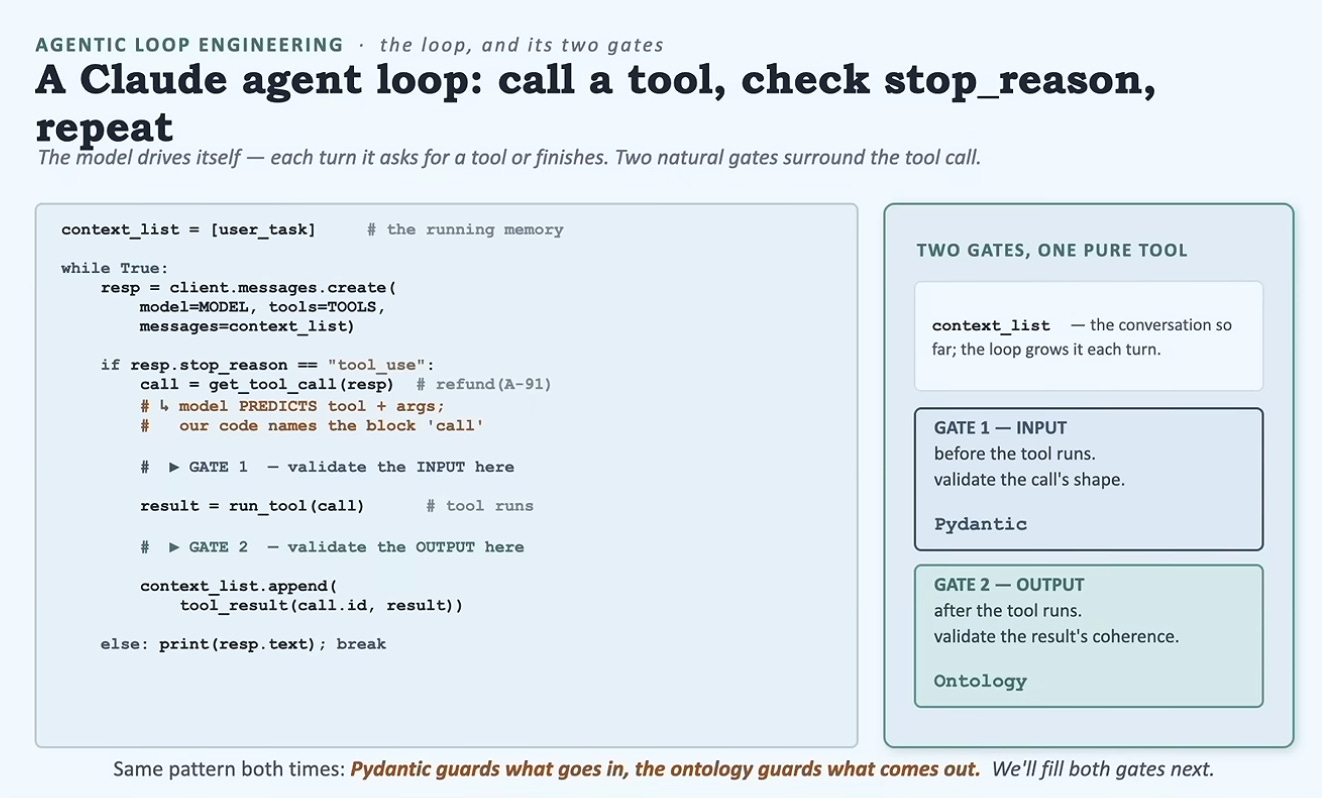
As an example, he showed a Claude agent loop which used an ontology to help validate the LLM’s reasoning after the tool had run.

Coyle calls the convergence of probabilistic agents with ontologies “neurosymbolic AI.”

“Sounds pretty fancy,” he said, “but it’s really neural networks tied into symbolic AI — rule-based systems come under that category, as do the knowledge graphs that we’re assembling.”

He reiterated that neurosymbolic AI represents “a way to keep the LLM on its guardrails.”

The Pros and Cons of Ontologies

Someone who has been steeped in ontologies for many years and is now combining that with AI engineering is Kingsley Idehen, who runs a company called OpenLink Software. He’s been building an “agent engineering stack” that uses Semantic Web technologies — including an “agent with RDF memory.”

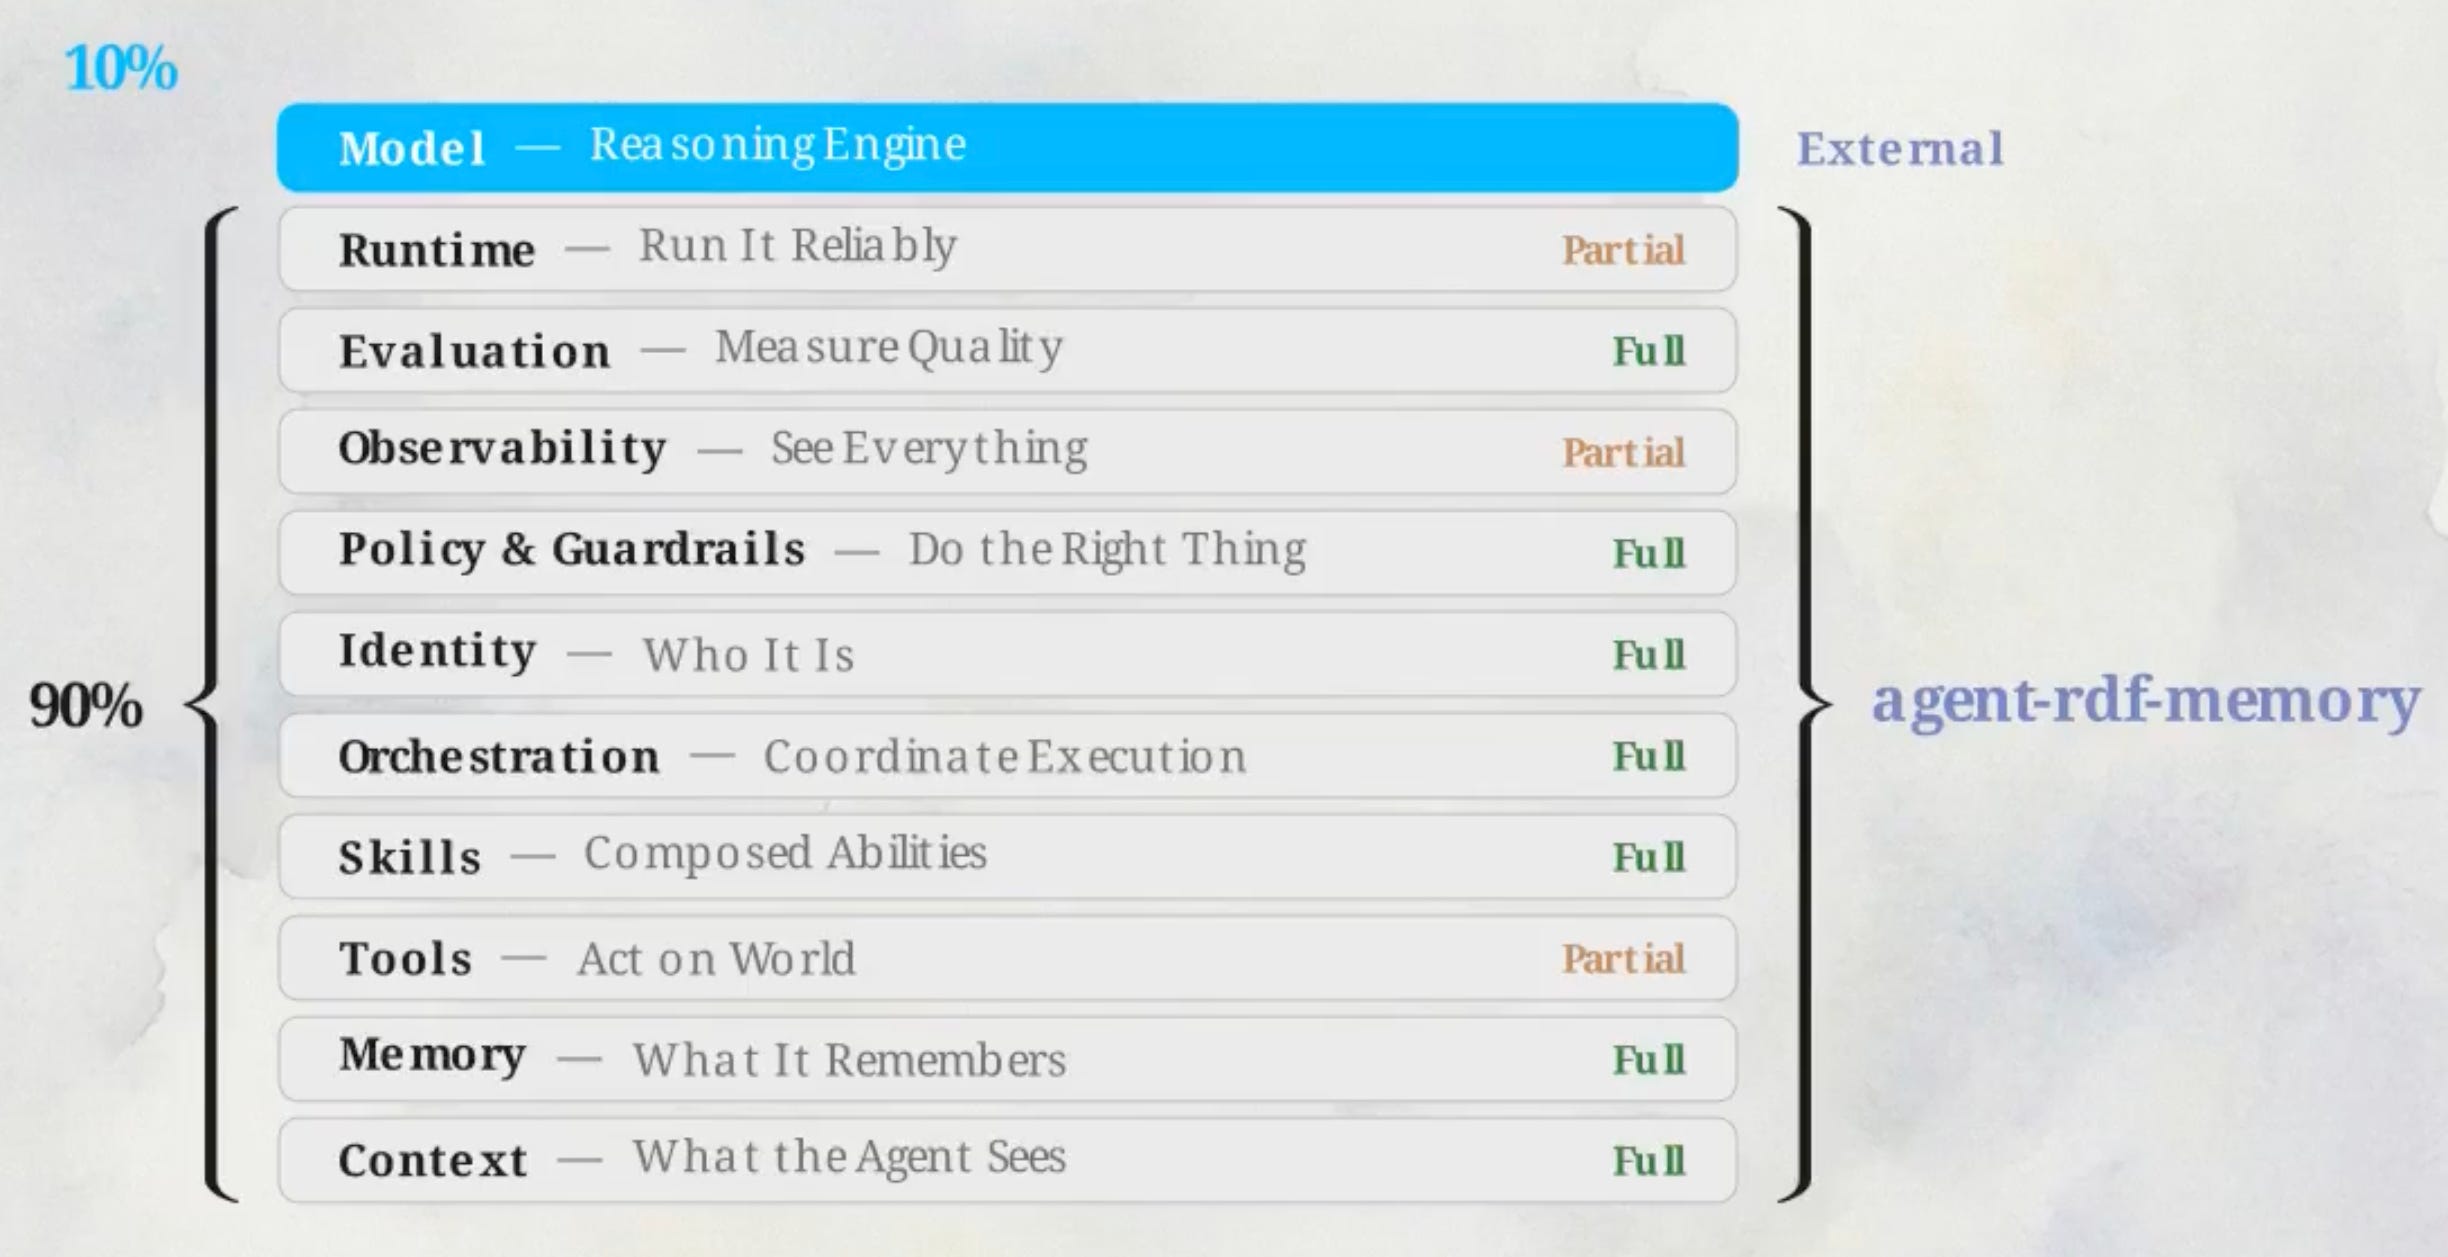
Kingsley Idehen’s agent-rdf-memory system.

I asked Idehen to explain to me the benefits of ontologies.

“The beauty of LLMs is that they are powerful processors of language,” he replied. “The beauty of an ontology is that it defines the types of entities and relationships through which language acquires computable context. Together, they bring the expressive power of language to computing’s UI/UX stack.”

That makes a lot of sense, but if you’ve been a web developer for a while you’ll know the challenges of ontologies: maintenance and keeping them up-to-date. It’s why the 1990s and 2000s vision for a “Semantic Web” — which was based on ontologies — never took off.

Current AI developer Prasenjit Sarkar offered a potential solution for the maintenance problem on X, arguing that “when an agent maintains the ontology as part of its own operation, updating definitions when it encounters edge cases, the maintenance problem changes character.” It’s still a hard problem though, he added.

Despite these issues, the structured nature of ontologies does appear to be a good match with the occasionally wayward tendencies of probabilistic LLMs. You get the power of LLMs, but ontologies will keep them in check.

Plus, as Neo4j’s Eifrem explained, ontologies allow us to move from “a world of thick agents with manually wired data sources” to a new world of “thin agents on a smarter shared ontology-based semantic layer.”

Neo4j’s “thin agents” concept, which relies on ontologies.

Loops and Guardrails

Back to Coyle’s presentation. He also had a great point about loop engineering, which he noted “has been around forever” in computer science. The problem, of course, is that loops can break or otherwise “go off the rails.”

Again, this is where an ontology system can act as a guardrail to a probabilistic LLM. One of Coyle’s slides referred to it as “a bounded set of rules around an unbounded loop.”

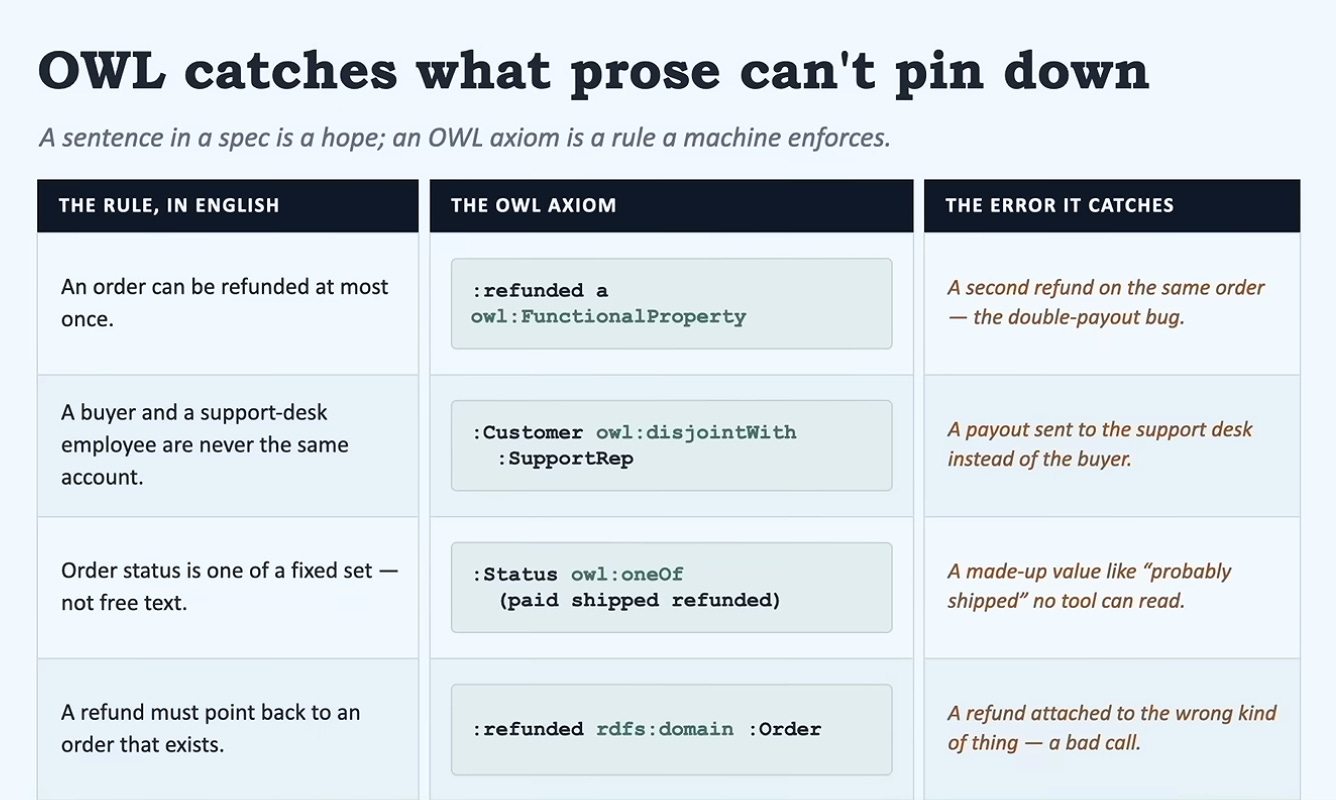
Near the end of his presentation, Coyle demonstrated how to use OWL as a check on agents. One slide showed that while language can be slippery, “an OWL axiom is a rule a machine enforces.”

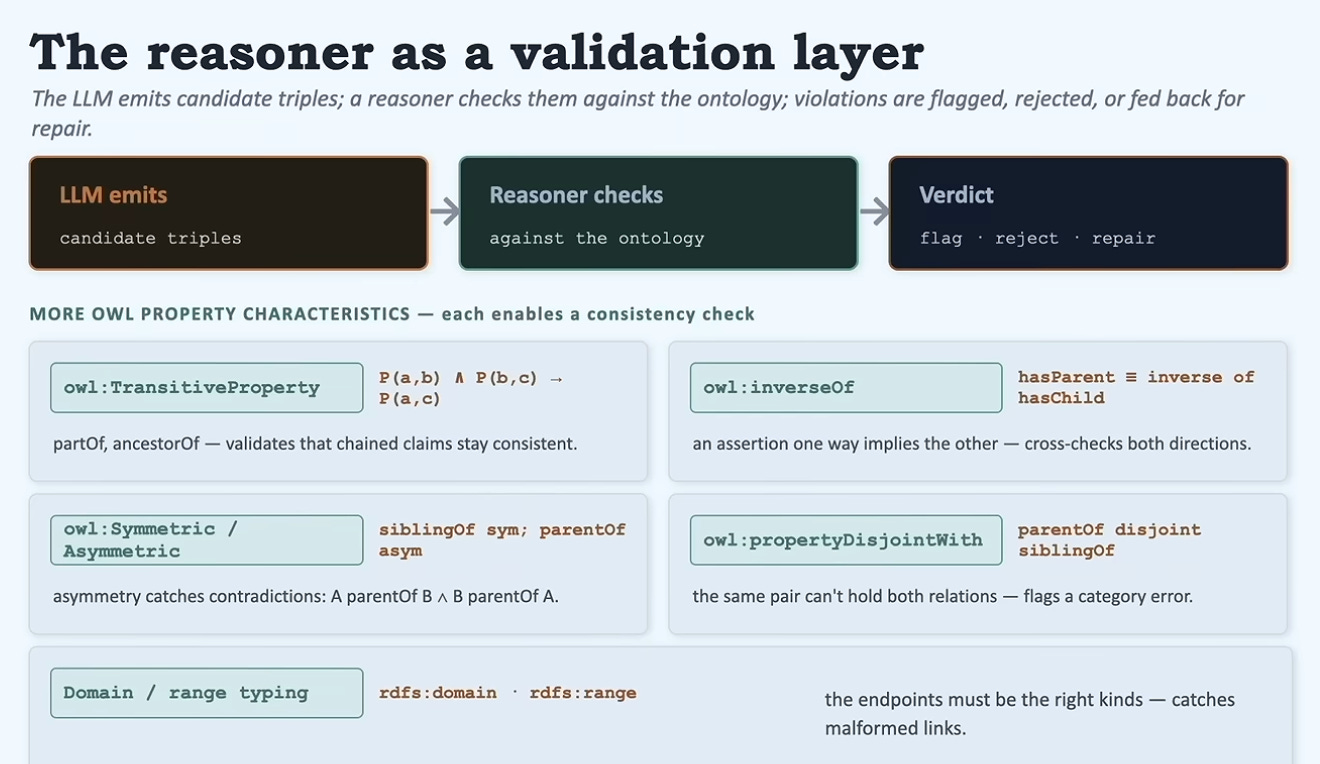
He also showed how “you can have a reasoner built on ontology, to check [and] keep the LLM on track — have guardrails to keep it honest.”

Semantic Vibes

Perhaps ontologies are starting to resonate with AI engineers because a central concern at this time is quality control for loop engineering. We saw this debate play out at AIEWF, with many conference speakers not willing to go all-in on fully automated “software factories” just yet. One of the key learnings from the event was that there need to be guardrails and humans in the loop.

Also it’s fascinating to see traditional web technologies make a resurgence in the field of AI engineering, especially after the 2025 trend of “vibe coding” made it seem like anyone could create software. Of course, since then the penny has dropped: we need to maintain that software and make sure it doesn’t break! So in 2026, we’re seeing a return to software engineering discipline — including now a revival of web ontologies as a way to keep probabilistic LLMs honest.

5 Trends That Defined AI Engineering at World’s Fair 2026

14 July 2026 at 23:21

swyx’s note: thanks to Richard for covering AIE while I was working on the conference itself! Make sure you have opted into the AINews feed to get our weekday updates. AIE next returns to NYC, Oct 12-14, with a heavy focus on AI in Finance this year.


AI engineering has come a long way in three years. When swyx coined the term “AI engineer” in June 2023, he was giving a name to a new kind of developer emerging from the big bang of large language models. It seems like ancient history now, but remember when we called the intersection of AI and software development “prompt engineering”? That was just months before swyx’s reframing.

The latest AI Engineer World’s Fair showed just how much the field has matured. Whether or not “AI engineer” has become a formal job title everywhere is almost beside the point. The engineering practices that have developed around AI over the past three years — building coding agents, designing harnesses, managing context, evaluating model outputs, and orchestrating increasingly autonomous systems — are becoming part of mainstream software development.

Rather than focusing on individual announcements at AIEWF, this post will pick out five larger trends that show where AI engineering stands in 2026.

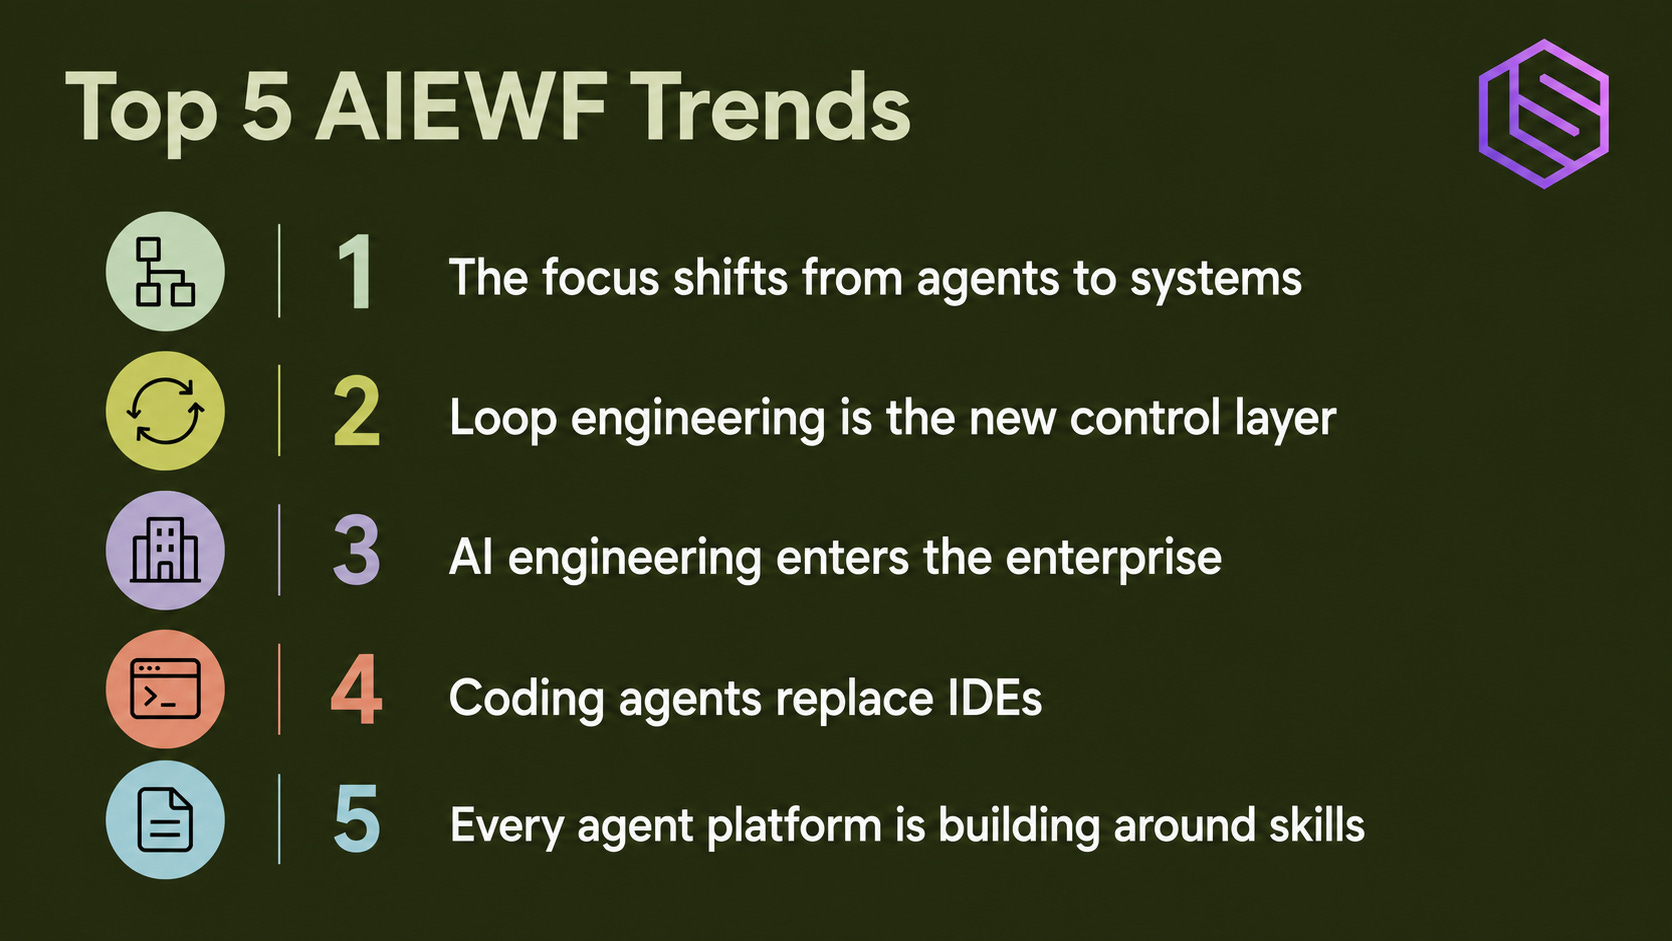
1: The focus shifts from agents to the systems around them

One of the clearest ways to see how AI engineering has evolved is to compare two essays by former OpenAI researcher, and now co-founder of Thinking Machines Lab, Lilian Weng. Her influential 2023 article, LLM Powered Autonomous Agents, described the anatomy of an LLM agent in terms of planning, memory and tool use. AutoGPT, BabyAGI and GPT-Engineer were among her examples — proof-of-concept systems that suggested autonomous agents might soon become practical.

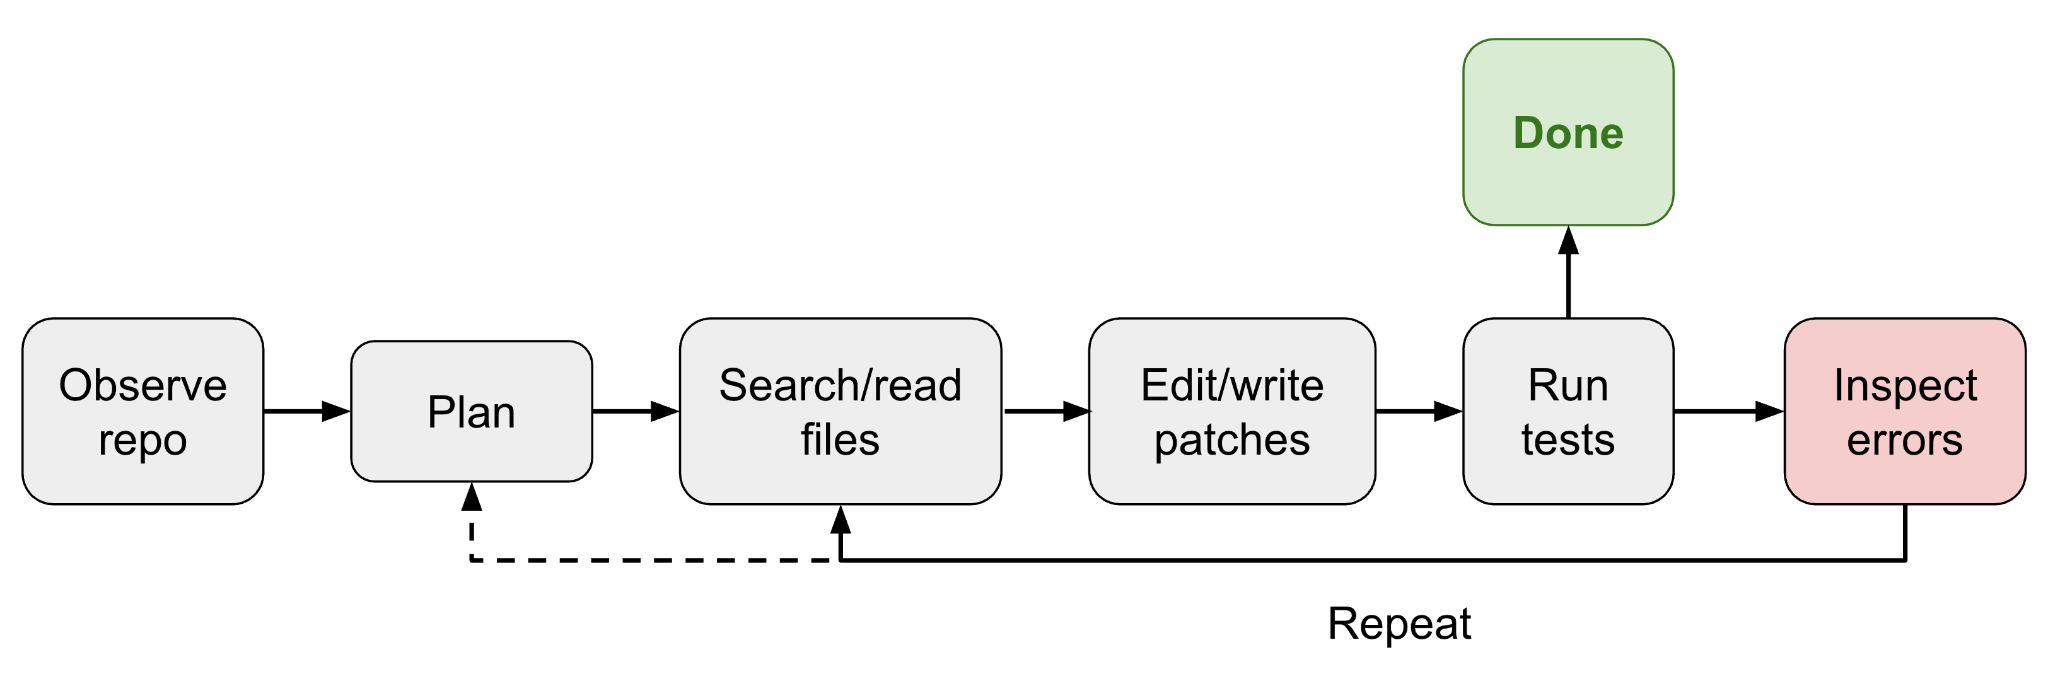
Her new 2026 essay, Harness Engineering for Self-Improvement, takes a very different perspective. Rather than focusing on the agent itself, Weng argues that the system surrounding the model has become just as important: the harness that manages workflows, context, permissions, evaluation, persistent state and continuous improvement. In other words, AI engineering has moved beyond prompting models toward engineering reliable systems around them.

Coding agent loop; Image by Lilian Weng

This shift was very much top of mind at AIEWF. I don’t think AutoGPT — the buzzy autonomous agent project everyone was talking about in 2023 — was even mentioned this year. Instead, the conversation revolved around Claude Code, Codex, Gemini CLI, Cursor, Warp and all the infrastructure needed to make coding agents dependable in production.

I remember being turned off by the AutoGPT buzz at the 2023 event, mainly because all the discussions seemed to focus on removing humans from the equation. But over the past few years we’ve learned that complete agent autonomy is not only unreliable, it isn’t even desirable — especially at scale. So it was a relief that at AIEWF, agents were largely positioned as augmenting the AI engineer, rather than replacing them.

During the OpenAI keynote on day 2 at AIEWF, Romain Huet emphasized this point. Using tools like OpenAI’s Codex, Huet argued, engineers can more easily collaborate with agents. As he put it, “software ate the world, and then AI ate software, but now what we’re here to say is that the AI engineers are eating the world.”

Despite the growing power of AI engineers, there’s also a sense that even the frontier companies don’t fully understand how their models are evolving — and so how much control can engineers truly have over them? In a separate keynote, Anthropic’s Thariq Shihipar talked about how their latest model, Claude Fable, is like an organic system — “models are grown, not designed.” There’s a “capability overhead,” he said, where “Claude gets smarter in a spiky way.”

All the more reason to build systems for agentic development, so that we can evaluate and monitor the outputs.

2: Loop engineering is the new control layer

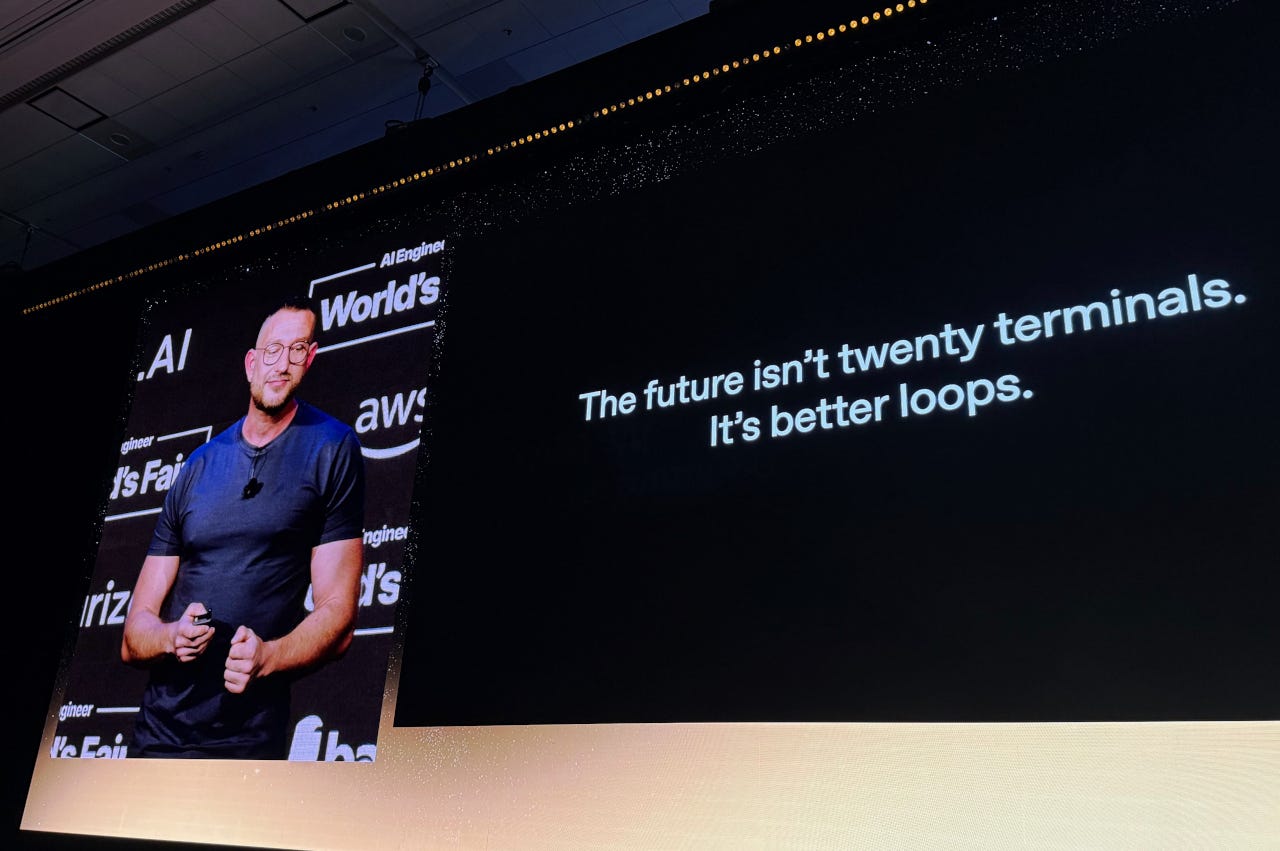
By the end of the first morning of keynotes at AIEWF, it was clear that “loops” was the buzzword du jour of the event. Overuse of the term aside, it did highlight a key point of tension around AI engineering: how much control should agents have, and where should humans remain in the loop?

OpenClaw creator Peter Steinberger advocating for better loops.

One approach a lot of leading engineers are now taking is putting themselves in an “outer loop” — to oversee the largely autonomous work being done by agents in an inner loop.

Roland Gavrilescu is co-founder and CEO of Introspection, a new company building infrastructure for deploying self-improving systems. In an interview with Latent Space, he explained how the concept of “autoresearch” provides the necessary feedback structure for agent loops:

“You can think of the system as having an inner loop and an outer loop. The inner loop is the primary system interacting with users and performing the work. Autoresearch is more concerned with the outer loop: another system that studies and maintains the primary system.“

The outer loop can include feedback signals, evals and human input. So it might still be largely autonomous, but the point is it is a method of oversight for the primary agent loop. Former Google engineering leader Addy Osmani had a nice line relating to this, saying that “agents can run much more of the inner execution loop, but that outer loop is still engineering.”

The term “loop engineering” came up multiple times during AIEWF, suggesting that it’s the human AI engineer’s responsibility to build these loop systems. Even the “ClawFather” Peter Steinberger, creator of OpenClaw, makes a point of putting himself in the outer loop. In the OpenAI keynote, he explained that “the agent runs the inner execution loop; I set the direction and I make decisions in the outer loop.”

The Loop Debate at AIEWF.

On the final day, an on-stage debate was held to determine whether fully autonomous agents were capable of managing loops in reality. Dex Horthy from HumanLayer claimed that “the hype is outrunning the discipline.” He wasn’t against loops, per se, noting that Kubernetes is built on control loops — “but they’re deterministic loops.” Geoffrey Huntley, creator of the Ralph Loop, admitted that loops were “frontier thinking,” but he had a wonderful analogy for the audience to ponder:

“[We’re] kind of like locomotive engineers now. That’s our job: to keep the locomotive on the rails.”

3: AI engineering enters the enterprise

This way of working with AI tools is starting to make its way into enterprises, typically via a new role called a “forward deployed engineer” (FDE) — where engineers work directly with organizations to implement AI capabilities.

Natalie Meurer, who leads FDE at Sierra, told Latent Space that implementing AI into organizations typically requires a lot of orchestration. “Every enterprise we work with wants to know how it can maintain everything its agentic ecosystem is capable of doing,” she said. “It needs to manage all the integrations and all the teams that contribute to the agent.”

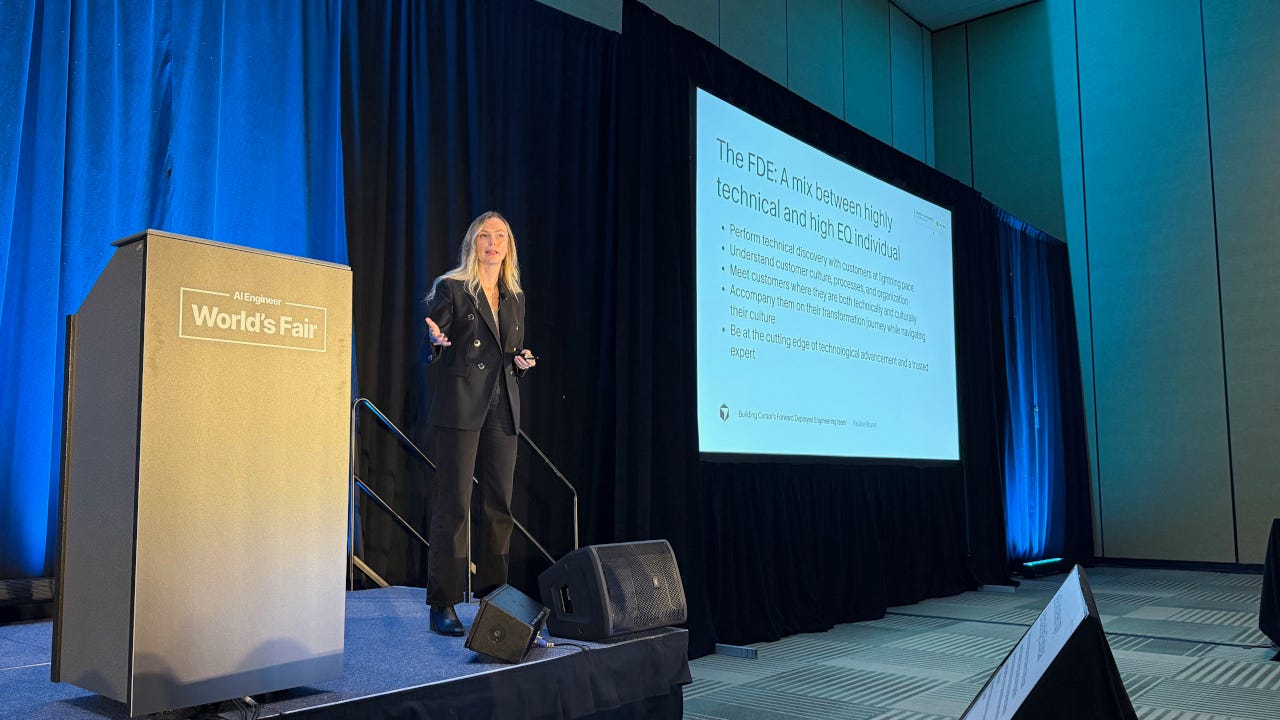
Cursor’s Pauline Brunet talking about FDEs in an AIEWF session.

In her session at AIEWF, Cursor’s Pauline Brunet spoke about what their FDEs look to achieve in each engagement:

“When [we] walk away at the end of the engagements — and we, in our case, have deployed cloud agents, long-running agents, automations, [and] we’ve built applications on top of our Cursor SDK — that when we walk away, it is a strict ROI for them. That means they’re not gonna turn things off when we leave.”

Another term used regularly at the conference was “software factory.” At Cursor, “a software factory means long-running agents helping people throughout that entire process,” said Brunet. This is basically what her team of FDEs is responsible for implementing, sitting alongside their customers’ engineers.

Where human engineers fit into a software factory is a key issue for enterprises. Warp CEO Zach Lloyd explained that organizations need to choose which parts of the lifecycle to automate, and where humans should be brought into the loop.

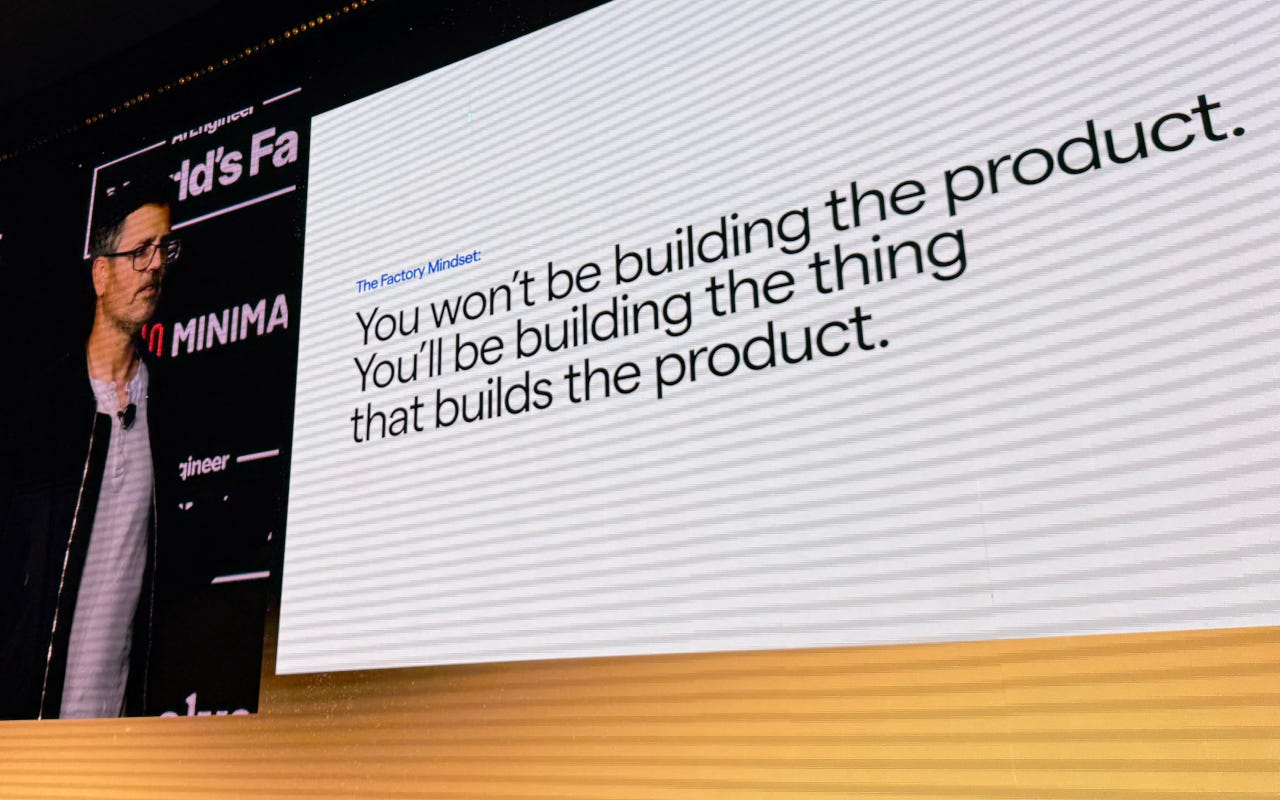
Warp’s Zach Lloyd on building the thing that builds the product.

“You choose your repositories, the parts of the software lifecycle you want to automate, and the points where humans should be brought into the loop,” Lloyd told us, regarding his company’s new software factory platform, Oz. “Different organizations and codebases will have different preferences. Do you fully automate code review? Do you have humans review certain high-risk changes?”

Another concern for enterprises is managing their unique organizational data in AI systems. Prukalpa Sankar from Atlan spoke at the conference about “context engineering,” explaining in a tweet that it’s important to consider “​​how context flows from your business systems into a shared company brain, then out to agents, copilots, and apps through MCP, APIs, and retrieval.”

Finally, lest we think enterprises are all-in on agents, Cursor’s Brunet pointed out that enterprise adoption of AI “is still concentrated among early adopters.” So finding “the right champions inside an organization” is a challenge for FDEs at this stage.

4: Coding agents replace IDEs as the developer interface

Perhaps the biggest practical change since the first AI Engineer Summit is how developers interact with AI on a daily basis.

In 2023, AI-assisted programming largely meant GitHub Copilot completing the next few lines of code. Most developers were still writing almost everything themselves, using AI as an intelligent autocomplete. But now we have tools such as Claude Code, Codex, Gemini CLI, Cursor and Warp. These “coding agents” can typically understand a broader objective, explore a codebase, modify multiple files, run tests, debug failures and iterate on their own work before presenting it back to the developer.

In Barr Yaron’s AI engineering survey, coding agents was a key trend.

The trend of coding agents now extends to web development too — with the recent release of Vercel’s eve, which the company calls an “agent framework,” comparable to its popular open source React framework, Next.js.

Vercel’s Chief of Software, Andrew Qu, told Latent Space at AIEWF that agents are effectively a new type of software. “They [agents] are not as predictable as web applications,” he explained. “The infrastructure can look similar, but the interaction, interface and outputs are much more dynamic.”

Qu added that the job of building a framework for agent development is far from over. “A year ago, we did not know sandboxes would become so important, or how much demand there would be for secure code execution and long-running jobs,” he said. “As we learn more from production, there will be much more to build.”

A for agents? Andrew Qu flashes the Vercel triangle logo.

This brings us back to the software factory trend, when developers are managing multiple agents. Charlie Holtz, CEO of Conductor, reminded the AIEWF audience that regardless of the coding harness, human engineers should always remain in control.

“I don’t want the future to be built around factories,” Holtz said. “I want to feel like a human, I want to be in the flow, I want to be in front of an orchestra, waving my baton.”

There was a sense during the conference that AI engineers aren’t yet aligned on which term is more appropriate: software factories or orchestras? Even Geoffrey Huntley, a loopmaxxing advocate, cautions about getting ahead of ourselves when it comes to automation:

“My biggest concern is that this time next year at the conference, we’re going to see a whole bunch of folks saying, our factories failed, our loops failed. These are things that we are still yet to figure out.”

5: Every agent platform is building around skills

One of the talking points of the conference was “skills,” a concept Anthropic popularized when it introduced “agent skills” to Claude last October. To borrow Addy Osmani’s definition, skills “encode the workflows, quality gates, and best practices that senior engineers use when building software.”

At AIEWF, Vercel’s Andrew Qu said that skills were “useful as portable, on-demand knowledge.” Introspection co-founder Roland Gavrilescu declared that AI engineering has shifted “from agent tools to agent skills.”

In a session on the main stage, Philipp Schmid from Google DeepMind showed how using skills (and other declarative Markdown files) allows developers to use “agents without code.” His main point was that skills reduce the need for orchestration code, which up till recently was typically done using Python. His conclusion:

“Agents are just files. We write markdown files to extend capabilities. Agents can learn from those, can create their own files.”

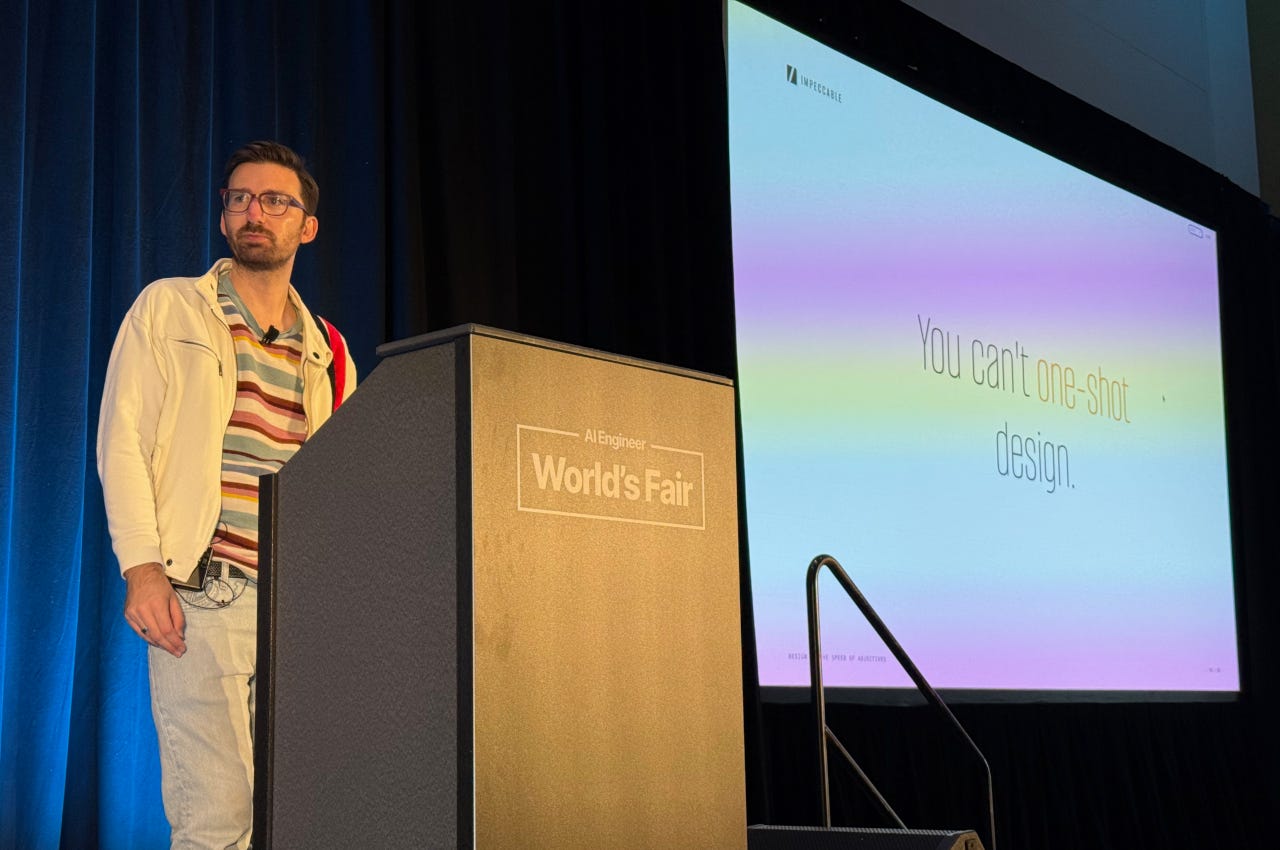
Paul Bakaus, who used to work for Google but now runs a company called Renaissance Geek, has created an entire project around agent skills. Impeccable is an open source design skills system that gives coding agents a vocabulary for improving interfaces. He even advocates for “skill engineering” as a discipline in its own right.

Paul Bakaus: “You can’t one-shot design.”

In an interview with Latent Space, Bakaus argued that most skills — and indeed most models — are not very creative. “They converge in one direction, and if everybody uses the same skill to do frontend design work or something like that, everything ends up looking the same,” he said.

Apparently there’s also such a thing as “skills hell,” which Matt Pocock said is comparable to previous developer frustrations — like frameworks hell. In a virtual presentation, Pocock provided a detailed checklist for writing skills, which you can see in the video below. In a nutshell, he advises writing fewer and smaller skills, and putting more thought into structure.

In a closing keynote, Y Combinator president Garry Tan implored the audience to use skills and other “AI native” approaches at their own startups or employers. Talking about business functions like sales, support and finance, Tan said that “the AI native companies that I see inside YC encode all of that as skills, written procedures that their agents execute, and they hire engineers whose job it is to maintain those skills, to do the work the skills can’t do yet.”

But again, there’s a danger in relying too much on what agents autonomously do. As AIEWF attendee Tyler Brown noted on X, “autonomy without structure creates as much slop as leverage.” One of his learnings from the conference was to “re-visit and re-implement your skills”:

“Each time there’s a new model release, it’s as if you have a kid that grows from middle school to high school. You have to change the curriculum for them to get the benefits of the new model.”

Agent engineering at scale

It’s been three full years since The Rise of the AI Engineer and the first AI Engineer Summit. Looking back, it really is striking how much the conversation has evolved. Three years ago, the focus was on proving that LLMs could act as autonomous agents at all (and the answer at that time was usually no). AutoGPT, prompt engineering, and early orchestration frameworks like Langchain dominated the discussion back then.

Now that agents not only work, but have proven they can scale, this year’s AI Engineer World’s Fair was able to concentrate on the bigger problems: building reliable systems, orchestrating teams of agents, managing context, evaluating outputs and integrating AI into production software.

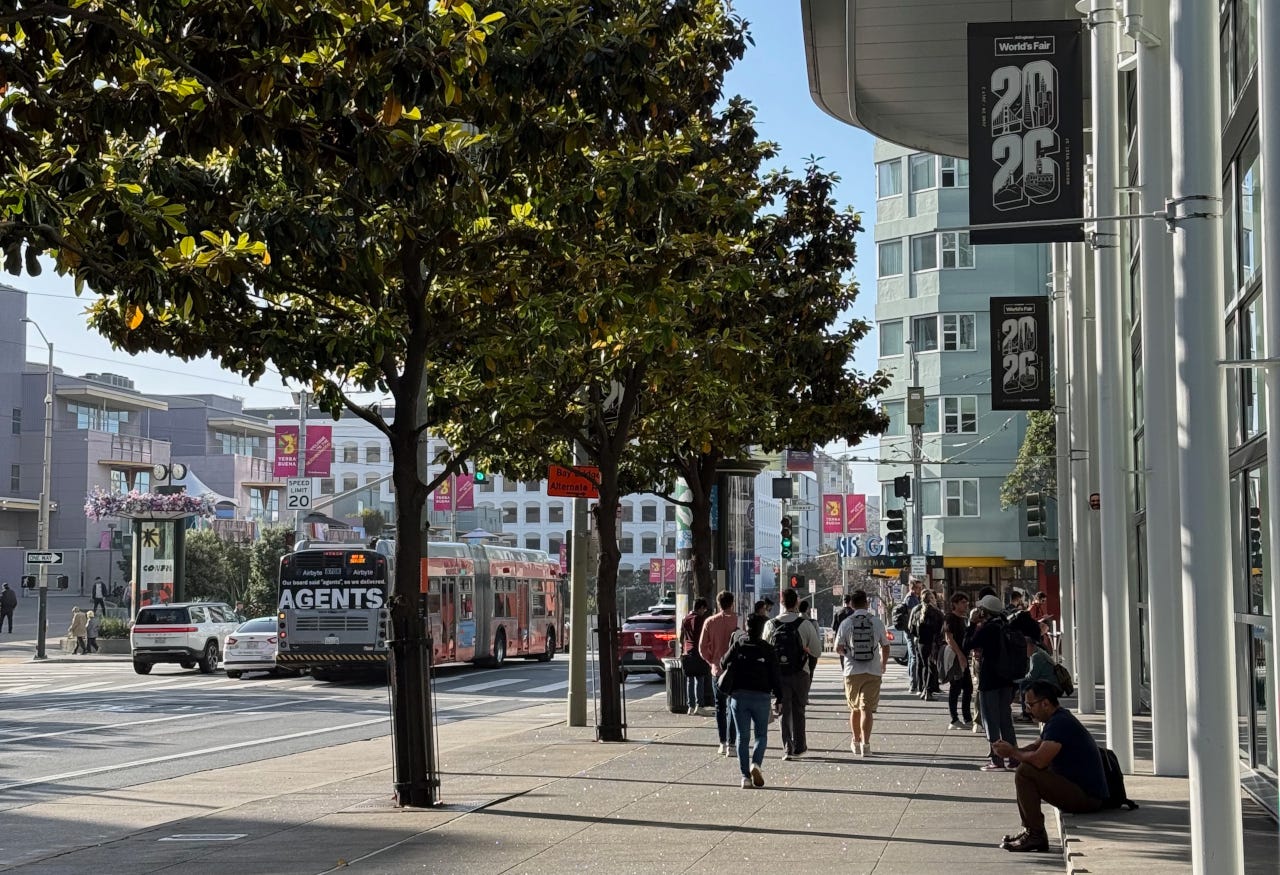
Agents are everywhere now…even on the back of San Francisco buses.

The term “AI engineer” may have started life as a new job title, but at AIEWF 2026 it felt more like a description of where software engineering itself is heading. Whether developers call themselves AI engineers, software engineers or Forward Deployed Engineers, they’re increasingly working with the same set of ideas: coding agents, harness engineering, designing loops, and orchestration.

AIEWF Daily Dispatch: The great loops debate and the state of AI engineering

3 July 2026 at 05:11

One of the highlights of the final day of the AI Engineer World’s Fair was a debate about loops. It nicely captured an argument running through the whole conference: are autonomous software factories viable now, or is the engineering discipline lagging behind the ambition?

Allie Howe from Keycard was the moderator and she opened by asking, “is there or is there not a delta between the hype behind loops and what actually works in practice?”

The pro-loop case was presented by Geoffrey Huntley, creator of the Ralph Loop, and Keycard CEO Ian Livingstone. Huntley opened by saying loops are already here. “It’s inevitable, it’s here to stay,” adding that “I don’t see myself going back to writing code by hand.”

Livingstone said that verifiability is ultimately what it’s about — and you can achieve that with any code, regardless of how it was produced. He also pointed out that loops have always been a core aspect of software development:

“A loop is at the core of ‘I try something, I learn something, I apply something.’ And all we’re really talking about is how quickly we can expedite that process.”

On the skeptical side were Dex Horthy from HumanLayer and Greg Pstrucha from Subroutine. Horthy began by noting that he wasn’t anti-loops. “The basic take here is not whether loops are good or bad,” he said, noting that “Kubernetes is actually built on loops — built on control loops. But they’re deterministic loops.” Horthy’s issue is that “the hype is outrunning the discipline.”

“I haven’t seen proof that we are at a point where we can just step up an abstraction level,” Horthy said, referring to agents controlling the coding. “I actually think we need to step down an abstraction level, if anything.”

Pstrucha was mainly concerned about the economic viability of agentic loops, which he said wasn’t sustainable. You can’t “orchestrate your problems away by buying more tokens,” he said.

“[We’re] kind of like locomotive engineers now. That’s our job: to keep the locomotive on the rails.”
- Geoffrey Huntley, loops advocate

Huntley then offered this wonderful analogy for loopmaxxing: “[We’re] kind of like locomotive engineers now. That’s our job: to keep the locomotive on the rails.”

The discussion turned to software factories, the metaphor that has really taken hold of the industry. Horthy worries that when everything is automated in a factory-like agent environment, “you never touch the problem.” So instead, he advises to start small and iterate with agent loops — to “build up intuition” and not try to automate end to end from the start.

Even Huntley recognized some of the dangers in loops. He said that software factories represent where we are headed in the future, but cautioned that it’s not yet solved in the market. “This is frontier thinking,” he said.

At the end of the hour-long debate, Howe polled the audience to ask which side ‘won’. Ironically, this resulted in a human failure: the stage lights were too bright for Howe or any of the debate participants to see how many hands were raised. If only an agent was in charge of dimming the lights.

Anthropic’s next big thing: Claude Tag

Perhaps one example of a company moving to a software factory model is Anthropic. Mike Krieger, one of the co-founders of Instagram back in Web 2.0 and now Head of Labs at Anthropic, was interviewed by swyx in one of the morning sessions.

Krieger talked about Claude Tag, Anthropic’s internal model which the company announced to the world last week. He described Tag as more delegated, asynchronous and proactive than Claude. It perhaps suggests what an early software factory looks like in practice — not agents replacing a team, but multiple people delegating responsibilities to a system like Claude Tag.

Mike Krieger talking with swyx at AIEWF today.

“Most usage is actually much more delegated,” he said regarding his team’s usage of Tag. He gave an example of how they instruct the agents: “Don’t just fix this bug. Now you are responsible for this part of the codebase, and I want you to monitor this feedback channel and proactively take on tasks.”

“That’s really changed how we operate currently,” he continued. “It’s much more this multiplayer, async, proactive way.”

However, he also indicated there are some negative consequences to becoming more automated. He noted that his team is “bottlenecked on reviews” and on the “human ability to fully conceptualize what we’re doing.”

2026 AI Engineer Survey

Back to the current reality for most AI engineers. This morning, Barr Yaron from Amplify presented her annual survey of the industry.

According to Amplify’s data, 95% of respondents now use agents — roughly double last year’s share. Among teams using agents, 89% said those agents could write data, up from 52% the previous year.

“Agents are no longer reading, summarizing, drafting,” Yaron said. “They’re taking actions inside the systems.”

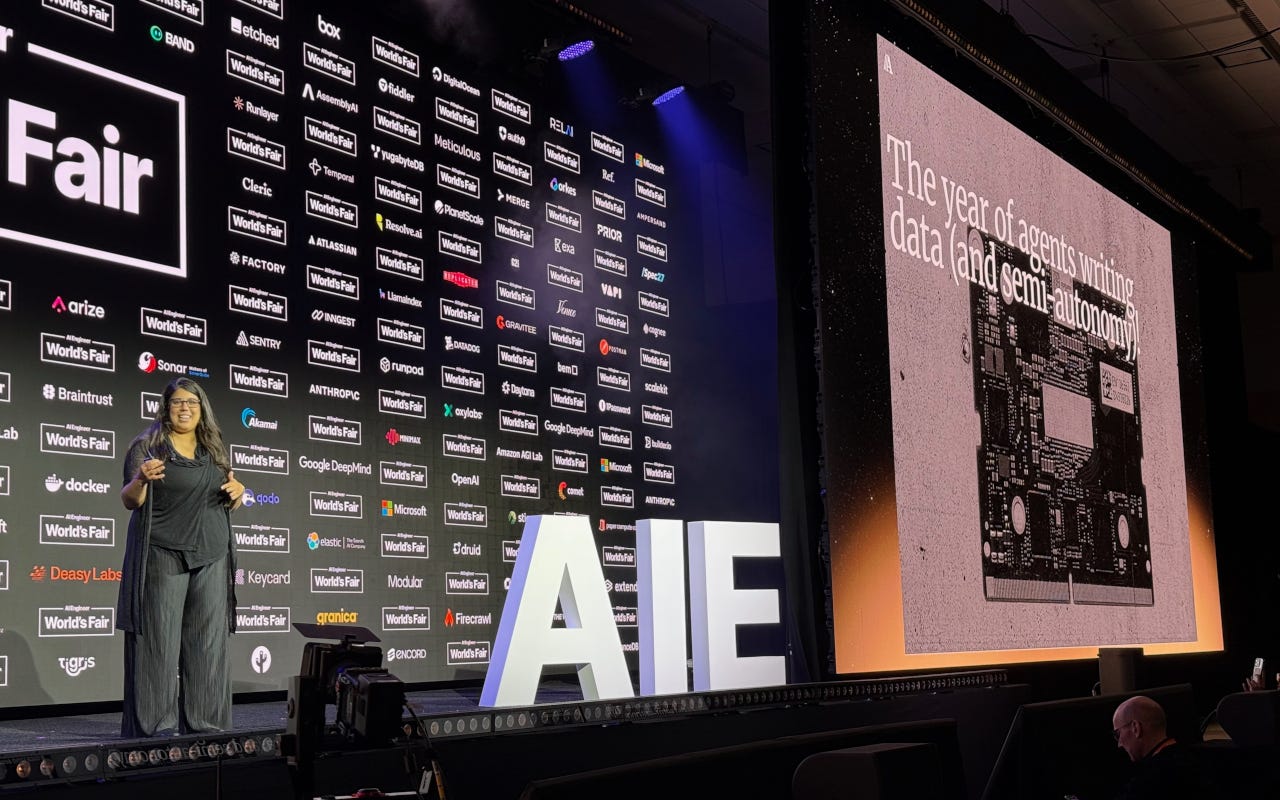
Barr Yaron presenting her AI engineering survey.

The controls, however, remain comparatively primitive. Human approvals and permissions were the two leading safeguards, followed by a scattered collection of task decomposition, retrieval, memory and sandboxing techniques.

“Nobody has settled the control layer for agents,” Yaron said.

Cost is also a concern. Forty percent of respondents said that AI costs regularly limit how ambitiously they use AI, while another 36% said it sometimes does. Token usage is now the second-most monitored production metric, behind quality.

The survey captured the conference’s central contradiction. AI has made experimentation cheaper and enabled teams to produce more software, but 59% of respondents to the Amplify survey fear that today’s AI-generated code is creating long-term liabilities.

Closing keynotes

The final sessions of the conference appropriately took us back to thinking optimistically about AI technology — about building with it. After all, that’s why the AI Engineer World’s Fair exists, and it’s where the fun is!

Theo Browne showcased several software projects he had built, or was still building, with AI. His point was that the scale of what an individual developer can realistically attempt has shifted. “What used to be a startup is now a side project,” he said, while projects he would once have dismissed as “too big” are moving within reach.

Garry Tan, president and CEO of Y Combinator, followed by giving that optimism an organizational form. The fastest-growing founders YC sees, he said, are “not treating AI as autocomplete, they’re treating it as a workforce.”

Garry Tan at AIEWF.

Tan’s closing prescription was: “Build an AI-native company, not a company that just uses AI.”

The debates during the week showed how much engineering remains before the AI-native vision is viable for all. But the closing keynotes offered a reminder of why the engineers who attended this conference are pursuing it: they just want to ride those locomotives!

❌