❌

Reading view

Latest open artifacts (#24): Motif-3, GLM-5.3, Hy4-preview and open model licenses

Avid Artifacts readers know that we have been covering not only models but also their licenses for quite some time. There was a period when custom licenses were all the rage, for example the custom Qwen2.5 72B-Instruct license or the Llama licenses. DeepSeek had a custom license for DeepSeek V3 before R1 changed it to MIT, which has resulted in many (Chinese) model makers adopting MIT or Apache 2.0 licenses in 2025.

In 2026, open models are more competitive than ever, which has led to two interesting developments: Western model makers adopt open licenses, with both Google and Meta switching to Apache 2.0. Chinese model makers at the frontier, however, are becoming more restrictive: Kimi K3 comes with a license which requires commercial agreements for those who run inference or fine-tuning services, and MiniMax M3 requires agreements above a revenue threshold and has prohibited use cases.

The newest addition is Zhipu’s GLM-5.3, which switched from MIT (GLM-5.2 and earlier) to a custom license with the following clause for inference and fine-tuning providers:

If the Licensee or any of its affiliates operates a Model as a Service business, and the aggregate revenue of the Licensee and its affiliates exceeds 10 billion US dollars (or the equivalent in other currencies) in total over any consecutive 12 months, the Licensee must pass Z.AI’s security review before using the Software or its derivative works for any commercial purpose. The scope and method of the security review shall be reasonably determined by Z.AI.

While the 10 billion US dollar threshold is very high compared to other licenses of this kind, “affiliates” is not defined in the license, which adds uncertainty and creates barriers to adoption. Furthermore, the license is provided in both English and Chinese, with the Chinese text using “关联方” for affiliated parties, which does have a definition in Chinese law.

We are by no means legal experts and there are obvious reasons why those licenses are created. However, we want to highlight the issues that come with creating such licenses, especially in a world with a lot of valid open and closed alternatives.

Share

Our Picks

  • Motif-3 by Motif-Technologies: Motif is one of the few hidden gems out there, showcasing innovation in their model training with very limited resources compared to others. Motif-3 comes with an MIT license and impressive scores for its size. Given the trajectory of model releases from Motif 2.6B, which we covered in 2025 and Motif-2-12.7B, the improvements are impressive.

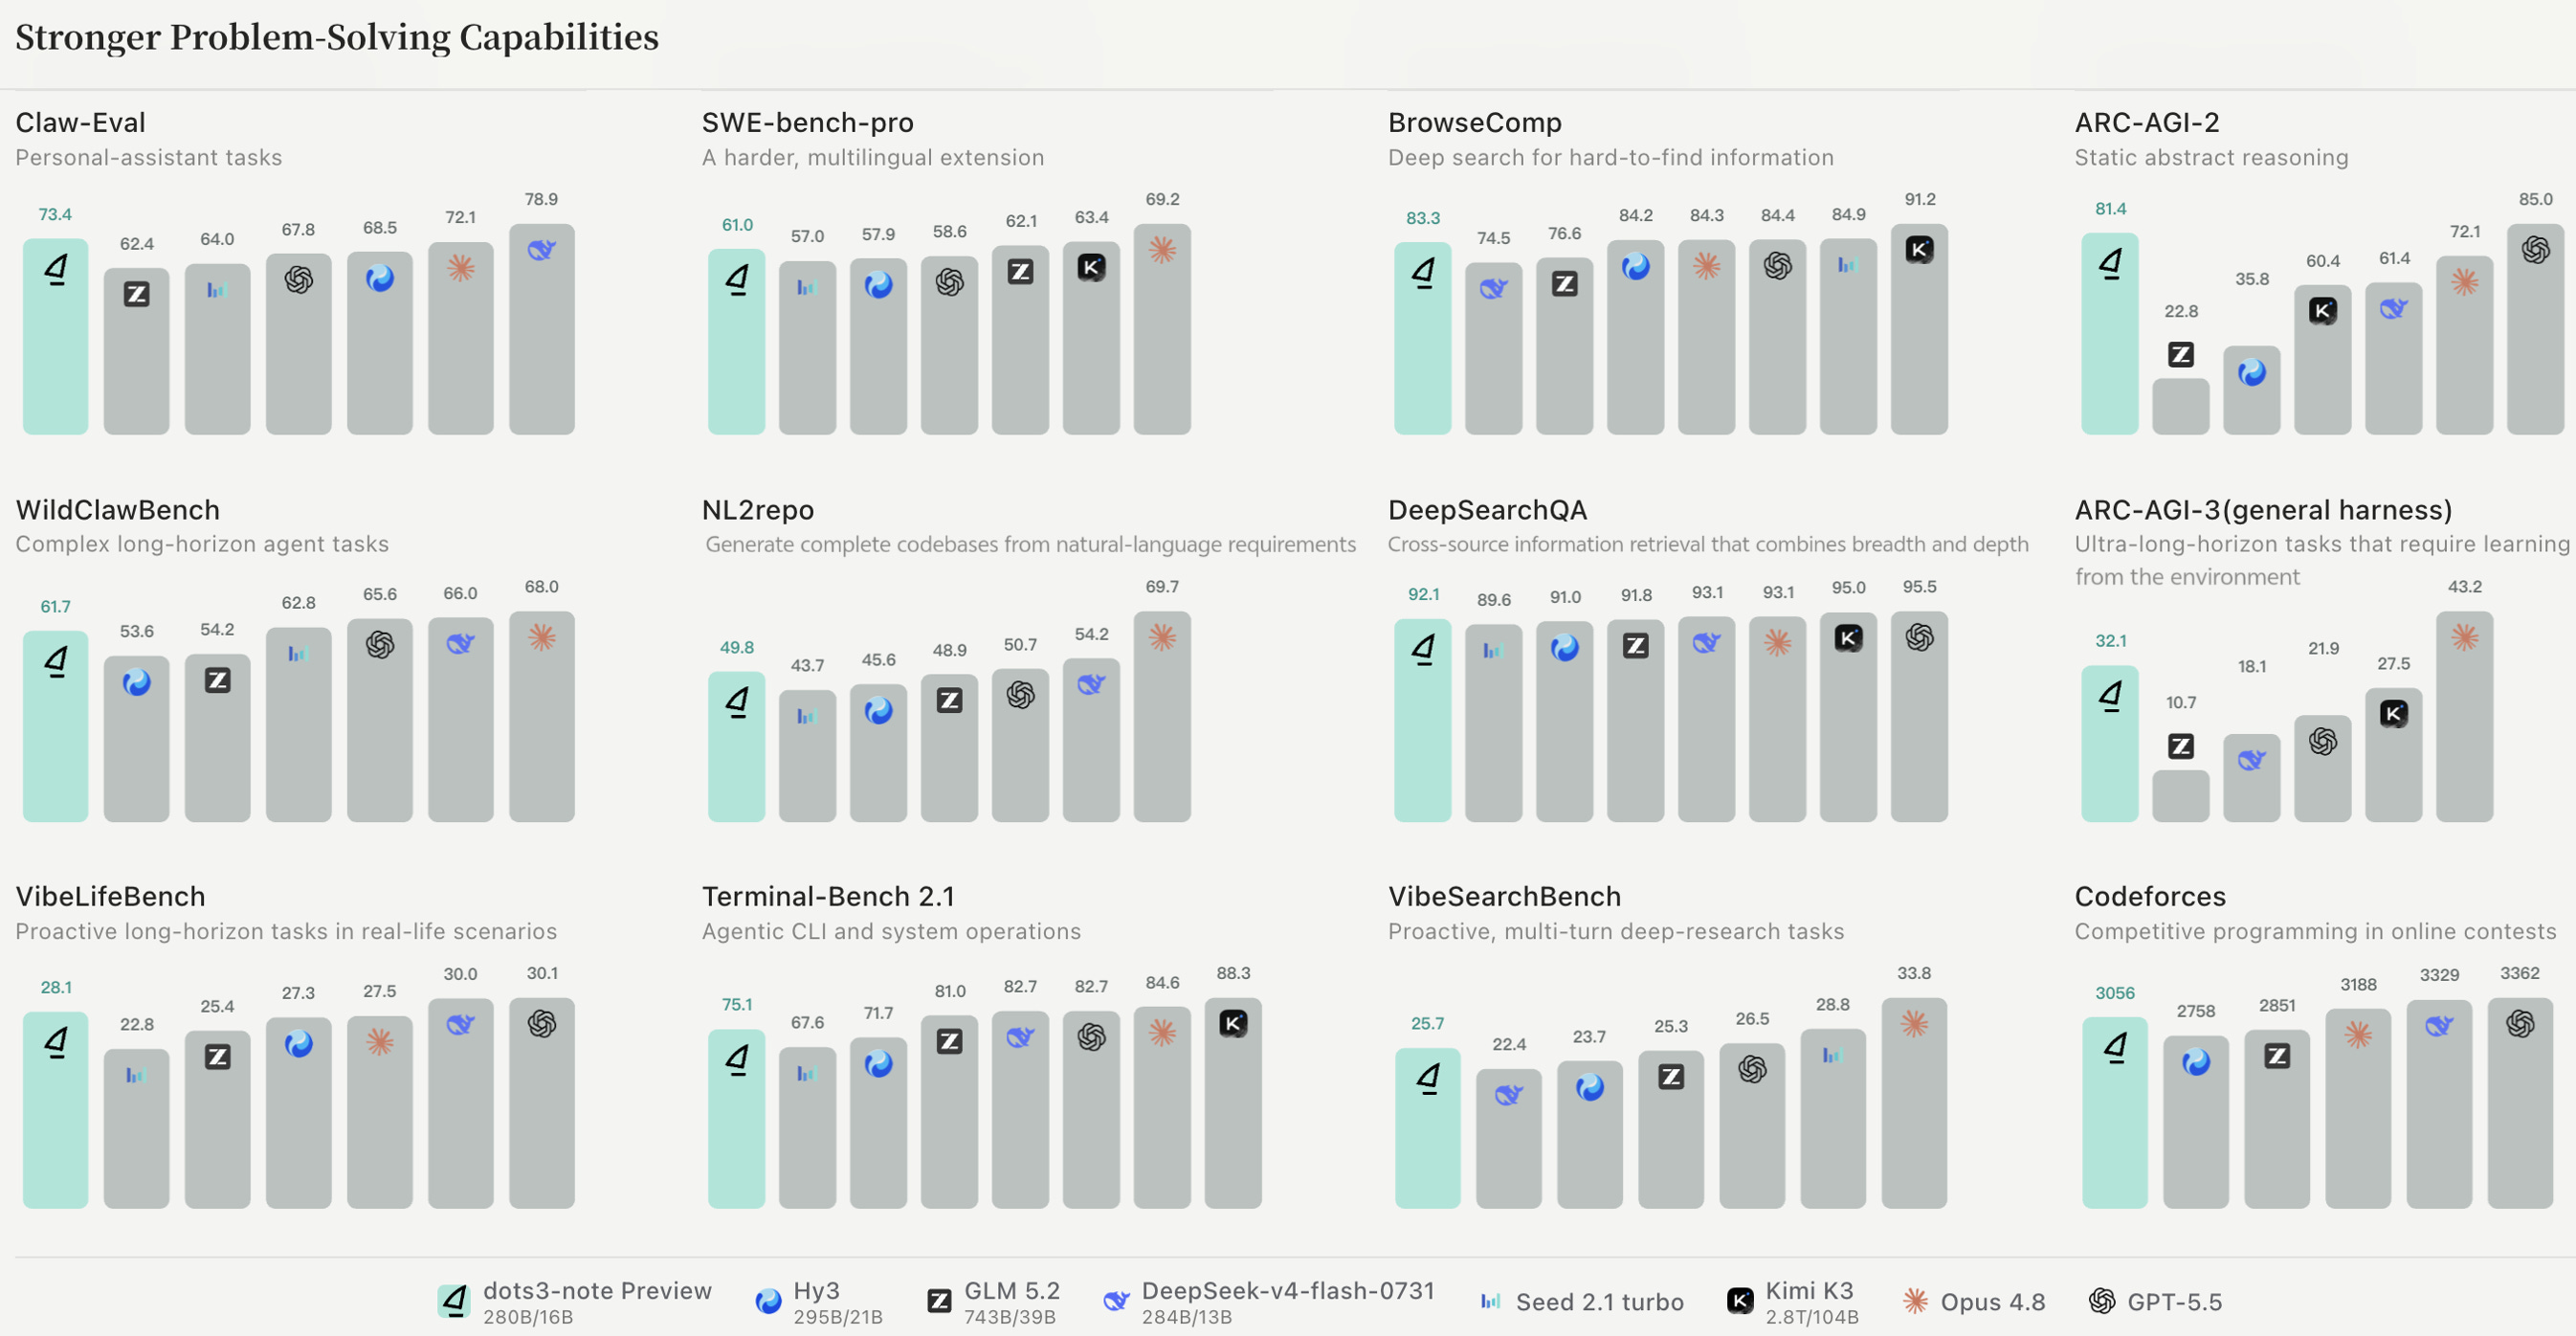
  • dots3-note-prev by dots-studio: RedNote/Xiaohongshu, the Chinese Instagram, is also getting more serious about model training, although they aren’t exactly a newcomer, having released models as early as 2025. dots3 was also able to win the IMO 2026 with a perfect score using an internal harness. We expect more from them in the near future.
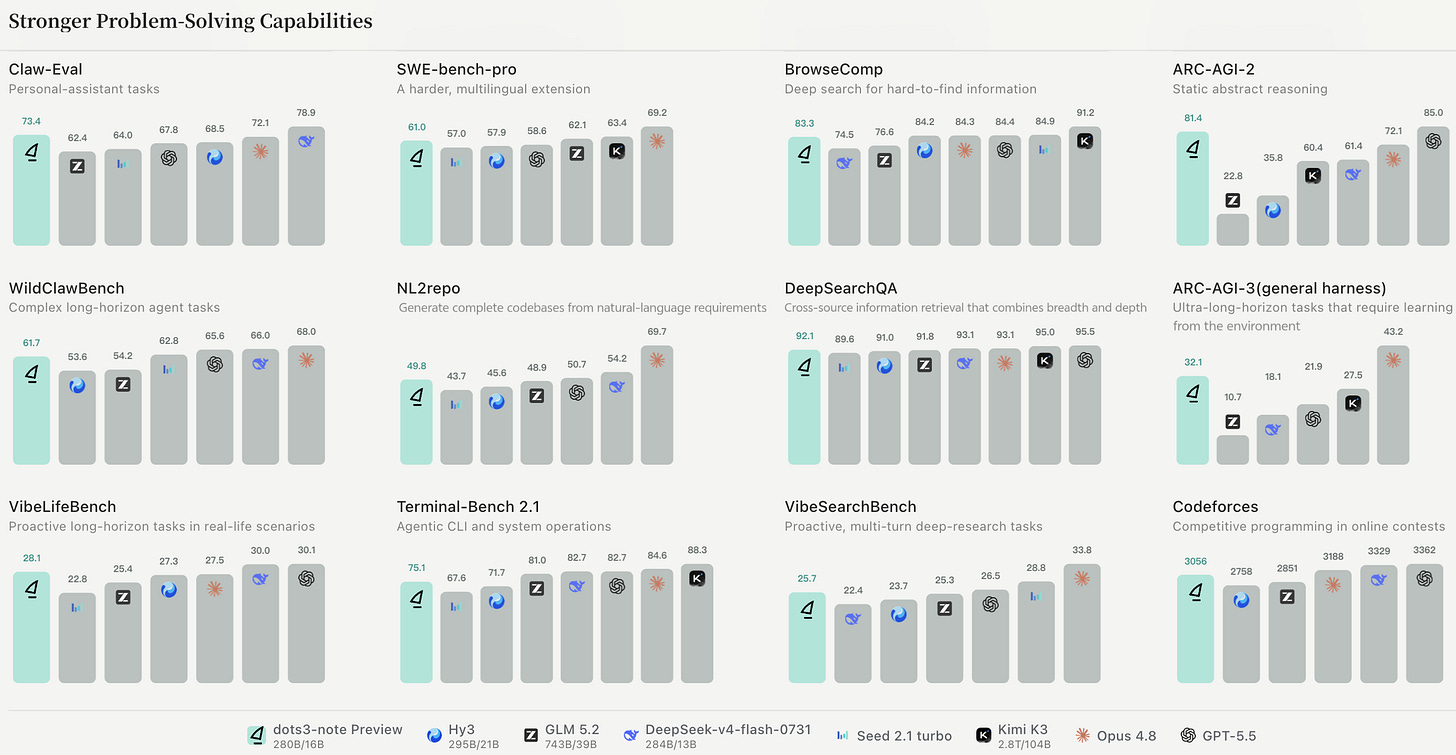
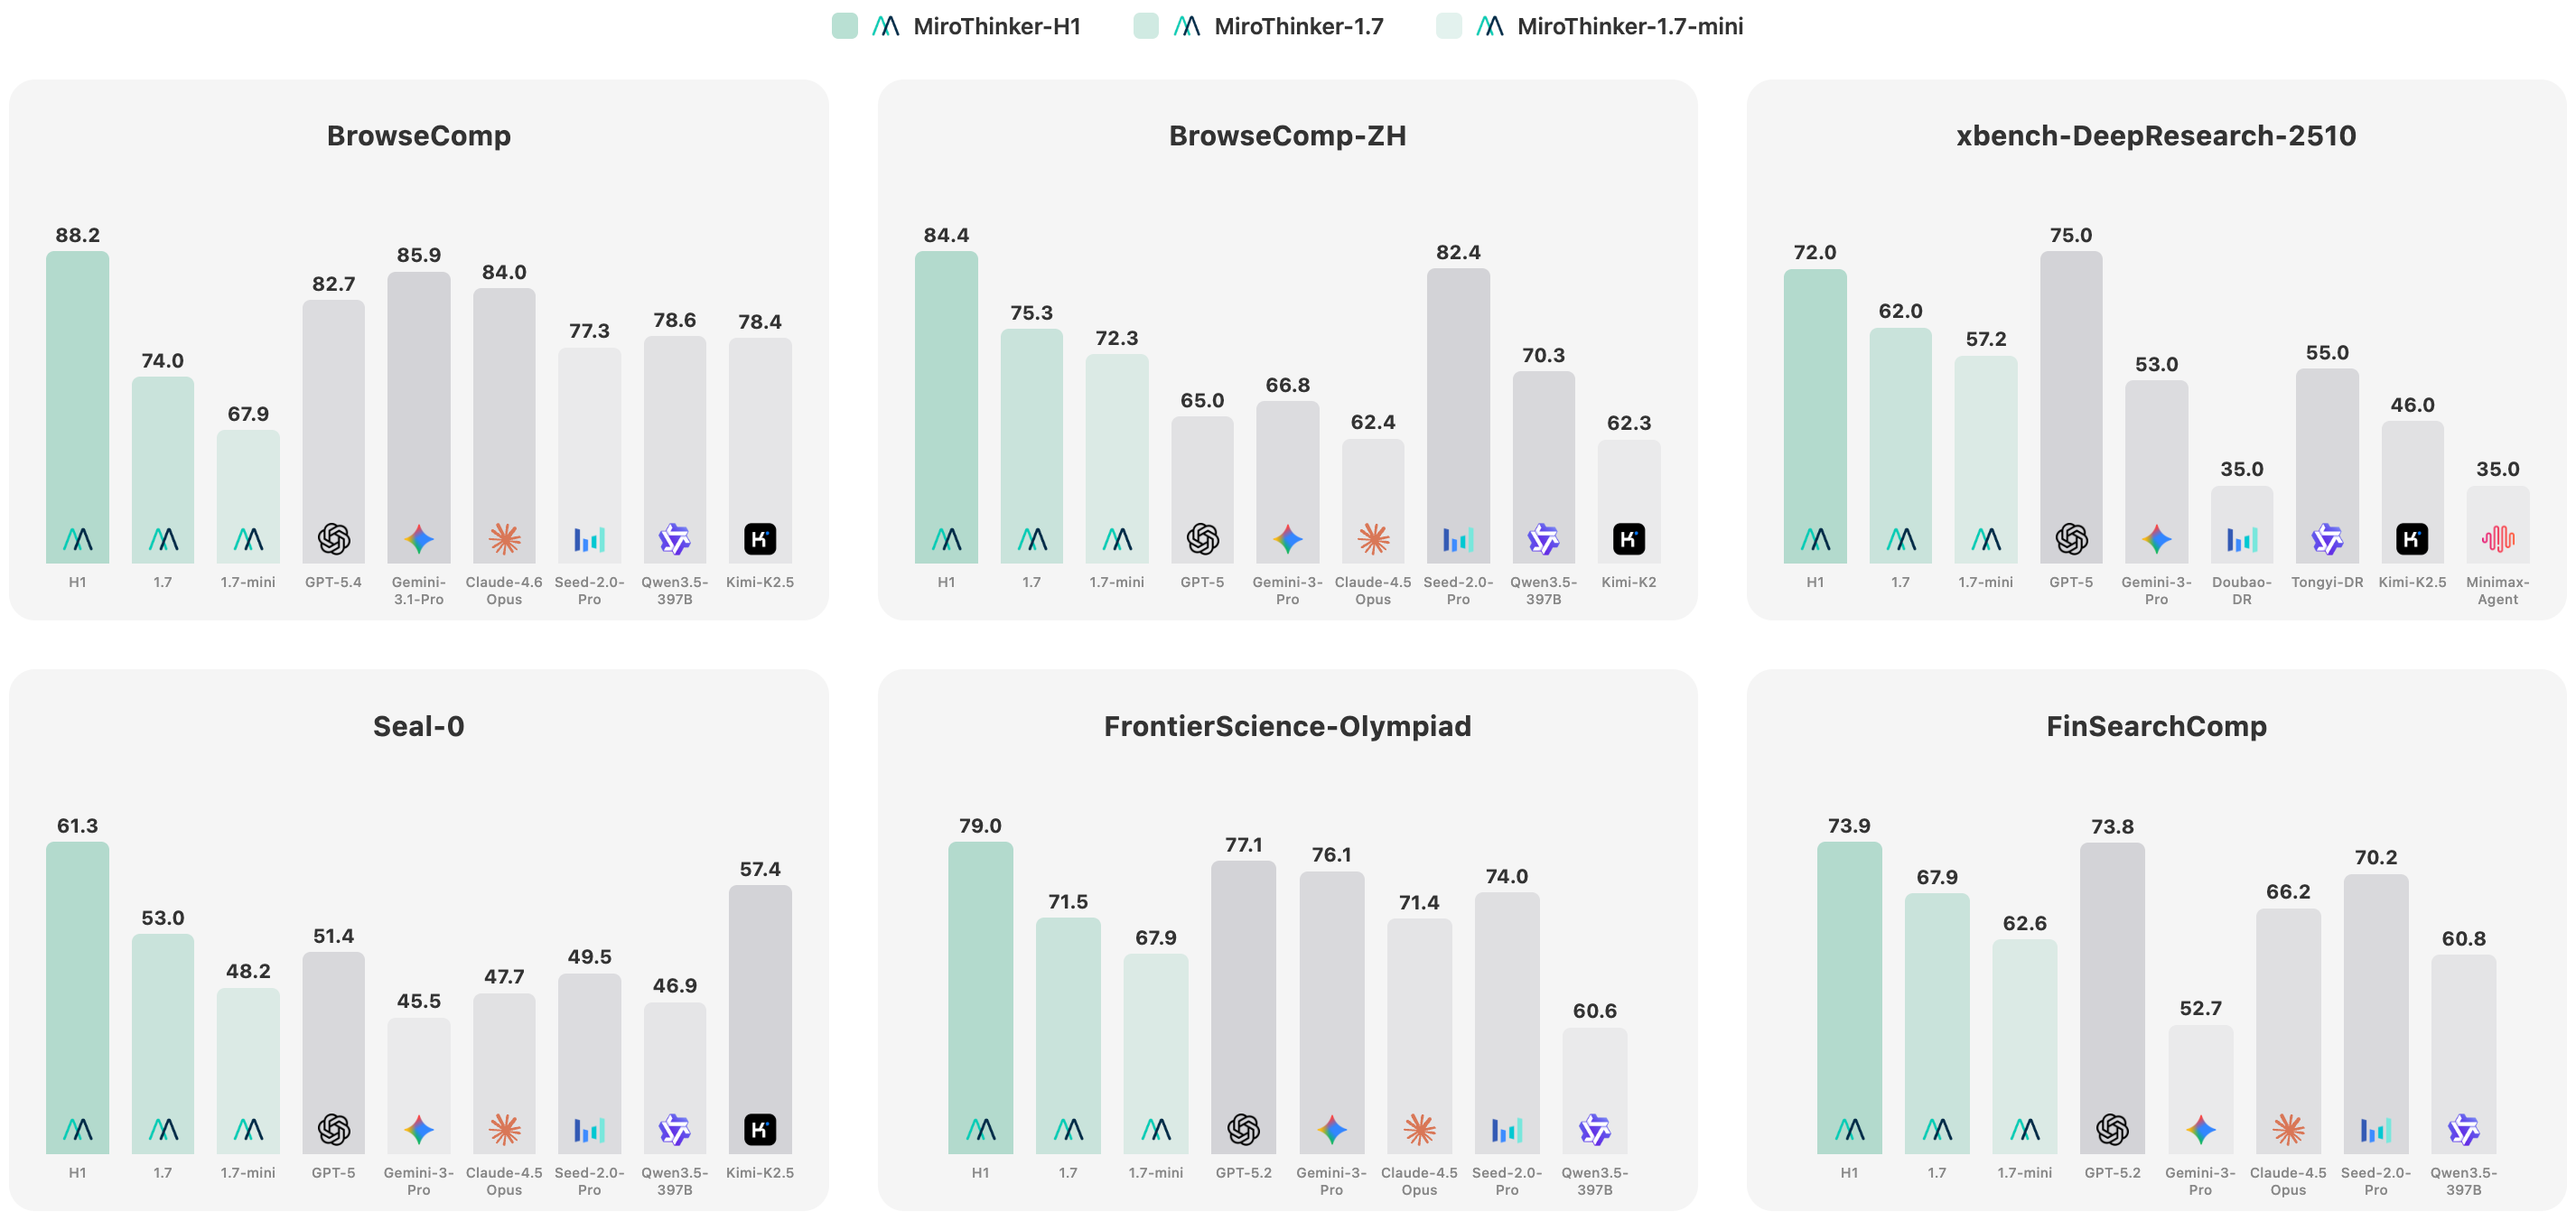
    General Reasoning and Agent evaluation results
  • Qwen3.8-Flash-Next by Qwen: A preview of the next version of Qwen models in terms of architecture: 125B-A6B with 51B n-gram embeddings. It uses GDN and Qwen Sparse Attention. Similar to Qwen3-Next-80B-A3B-Instruct, we expect similar architectures to become more popular and the ecosystem to fix integrations by the time Qwen4 drops.

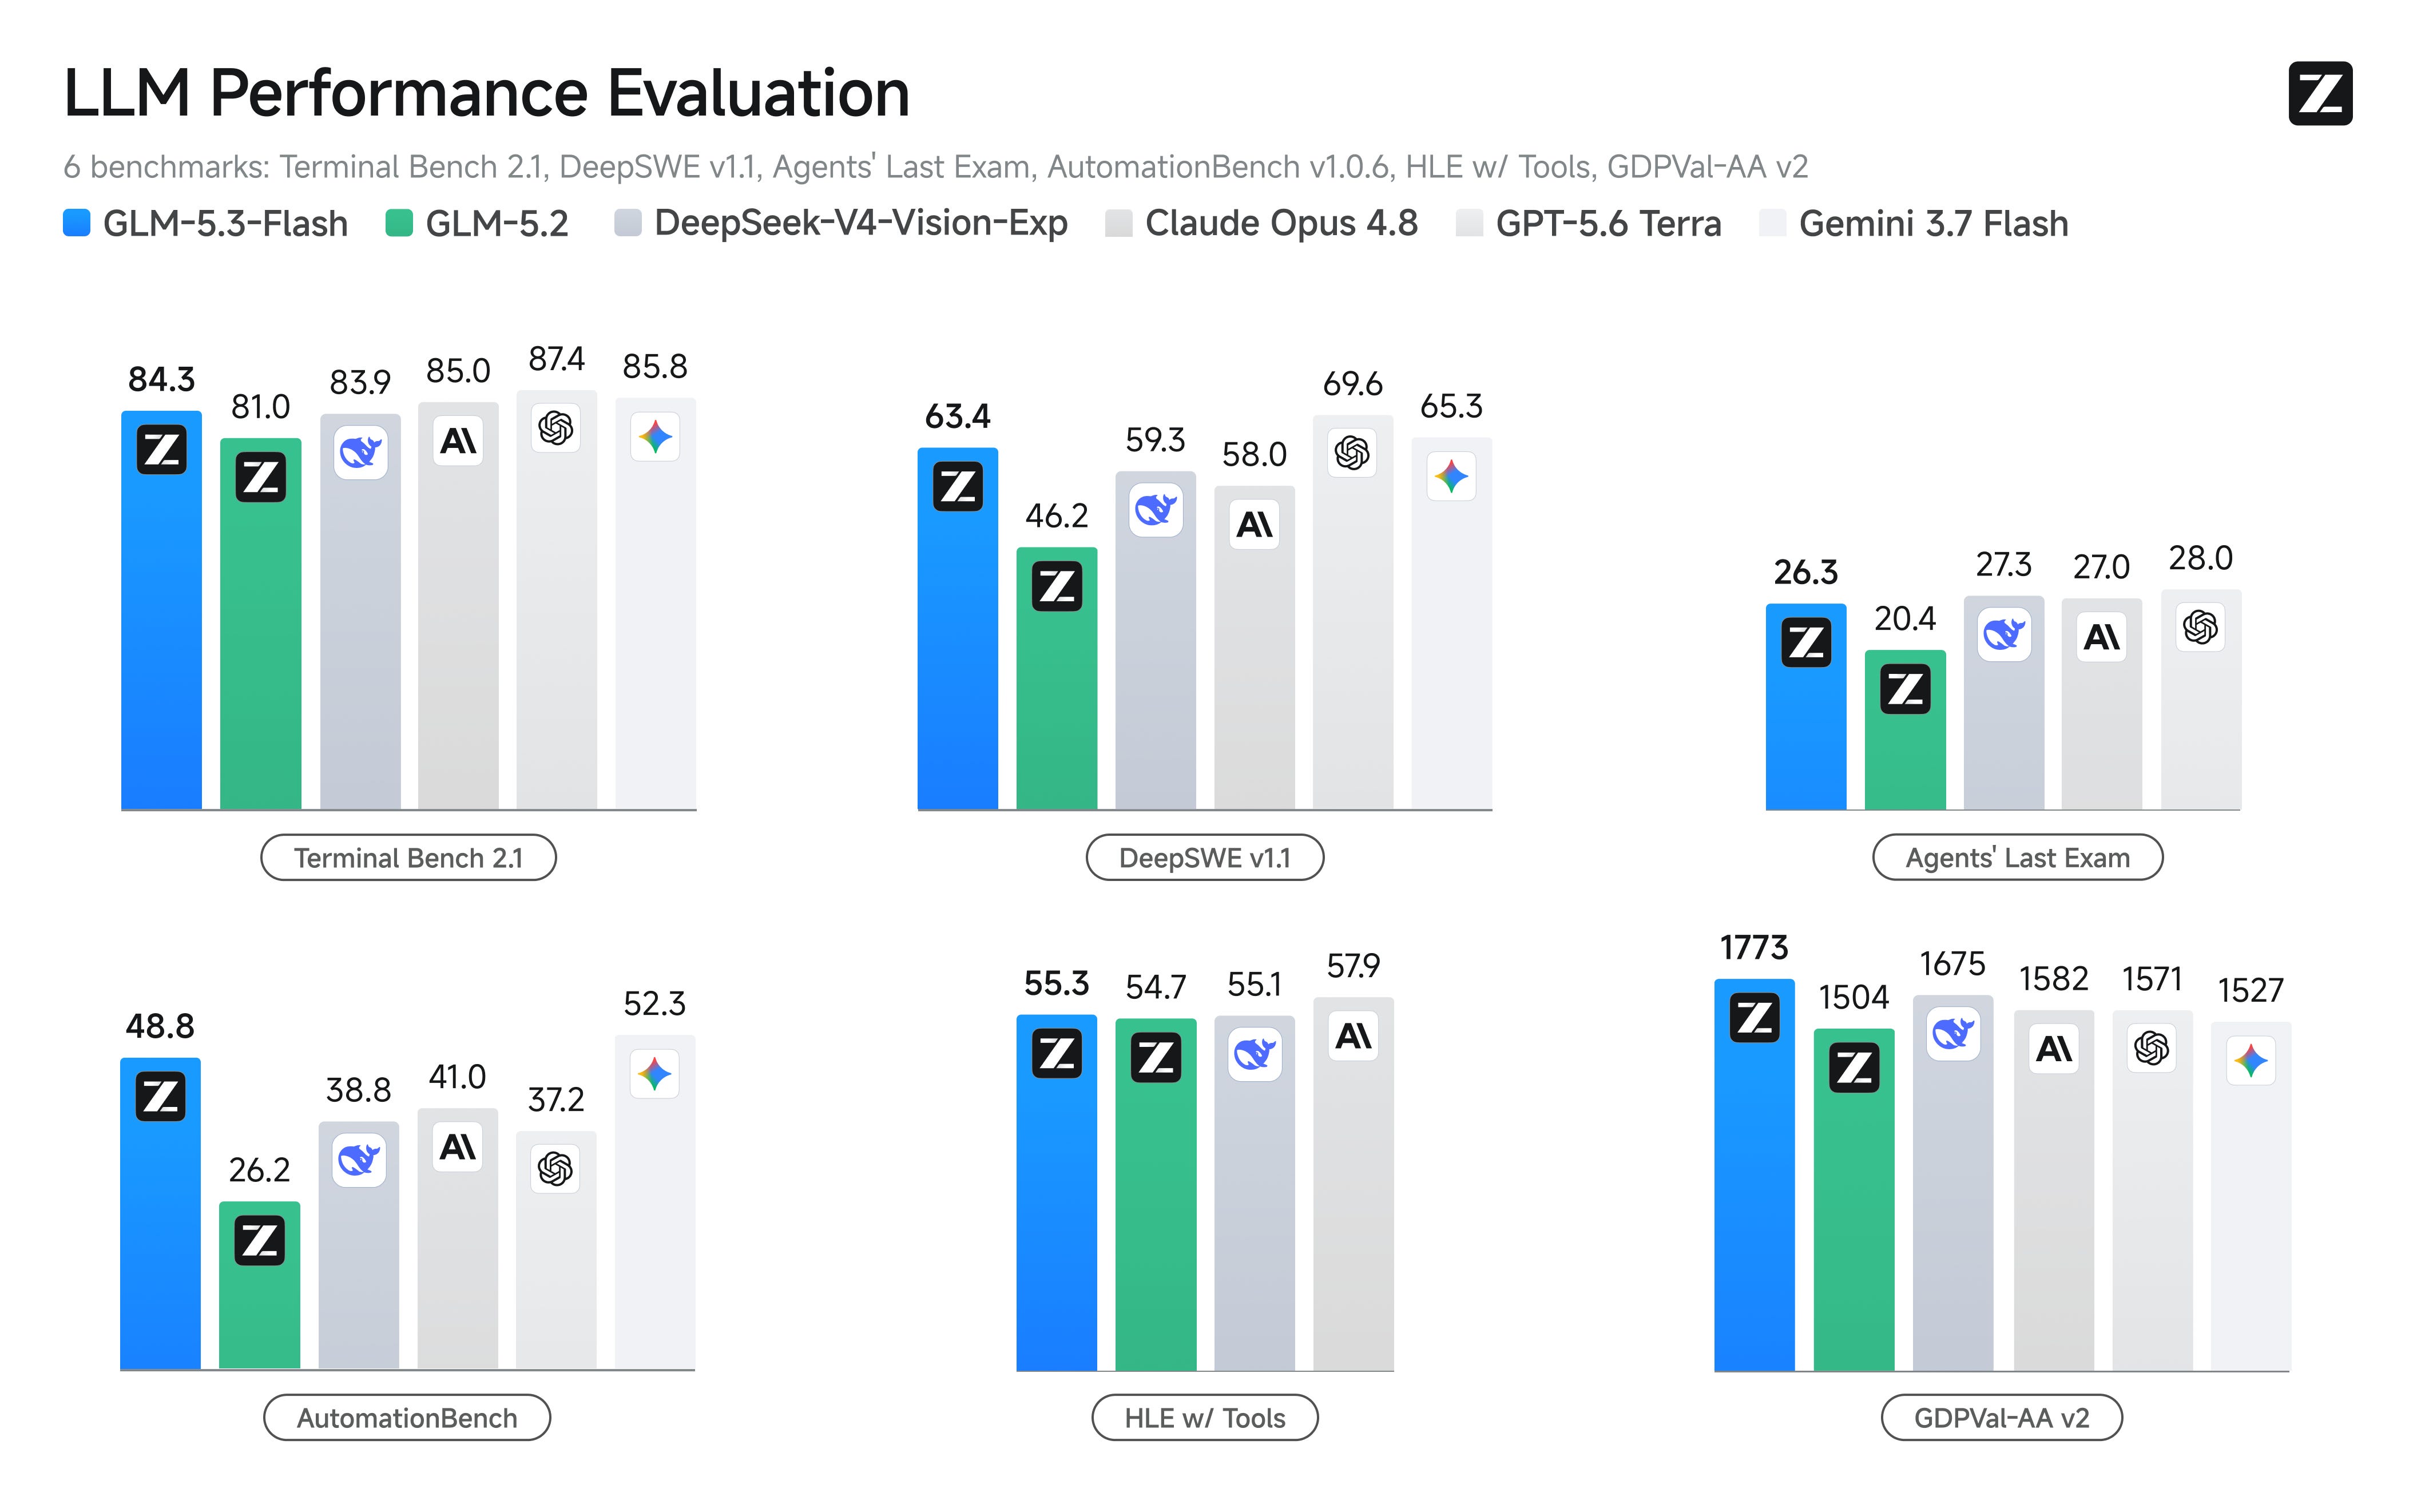
  • GLM-5.3-Flash by zai-org: This release perfected the version of the Chinese model playbook we’ve written about in 2025: The model got released as a free-to-use “stealth model” under the name “Ox-Alpha” on OpenRouter and OpenCode, which got people excited to try it out in the first place. They then speculated about its creator and size, alleging it is a >1T model from Cursor/xAI, Gemini or a new pre-train from open source labs. Because the model is relatively performant, people kept speculating for days about its creator, thus building up hype. It also dampens the accusations of benchmaxxing which accompany every (open) model release.
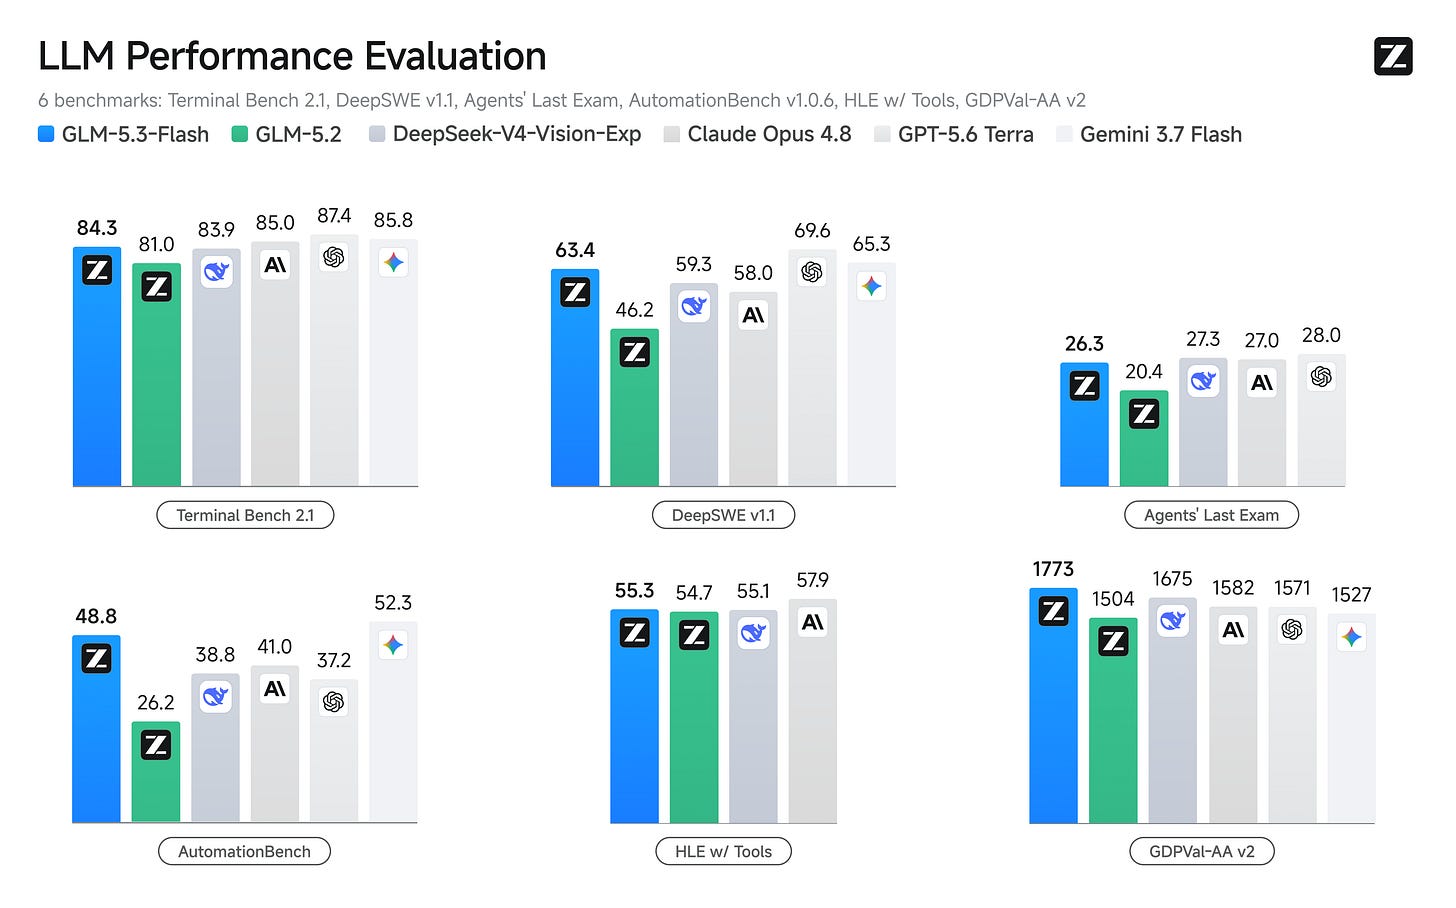
    bench_53
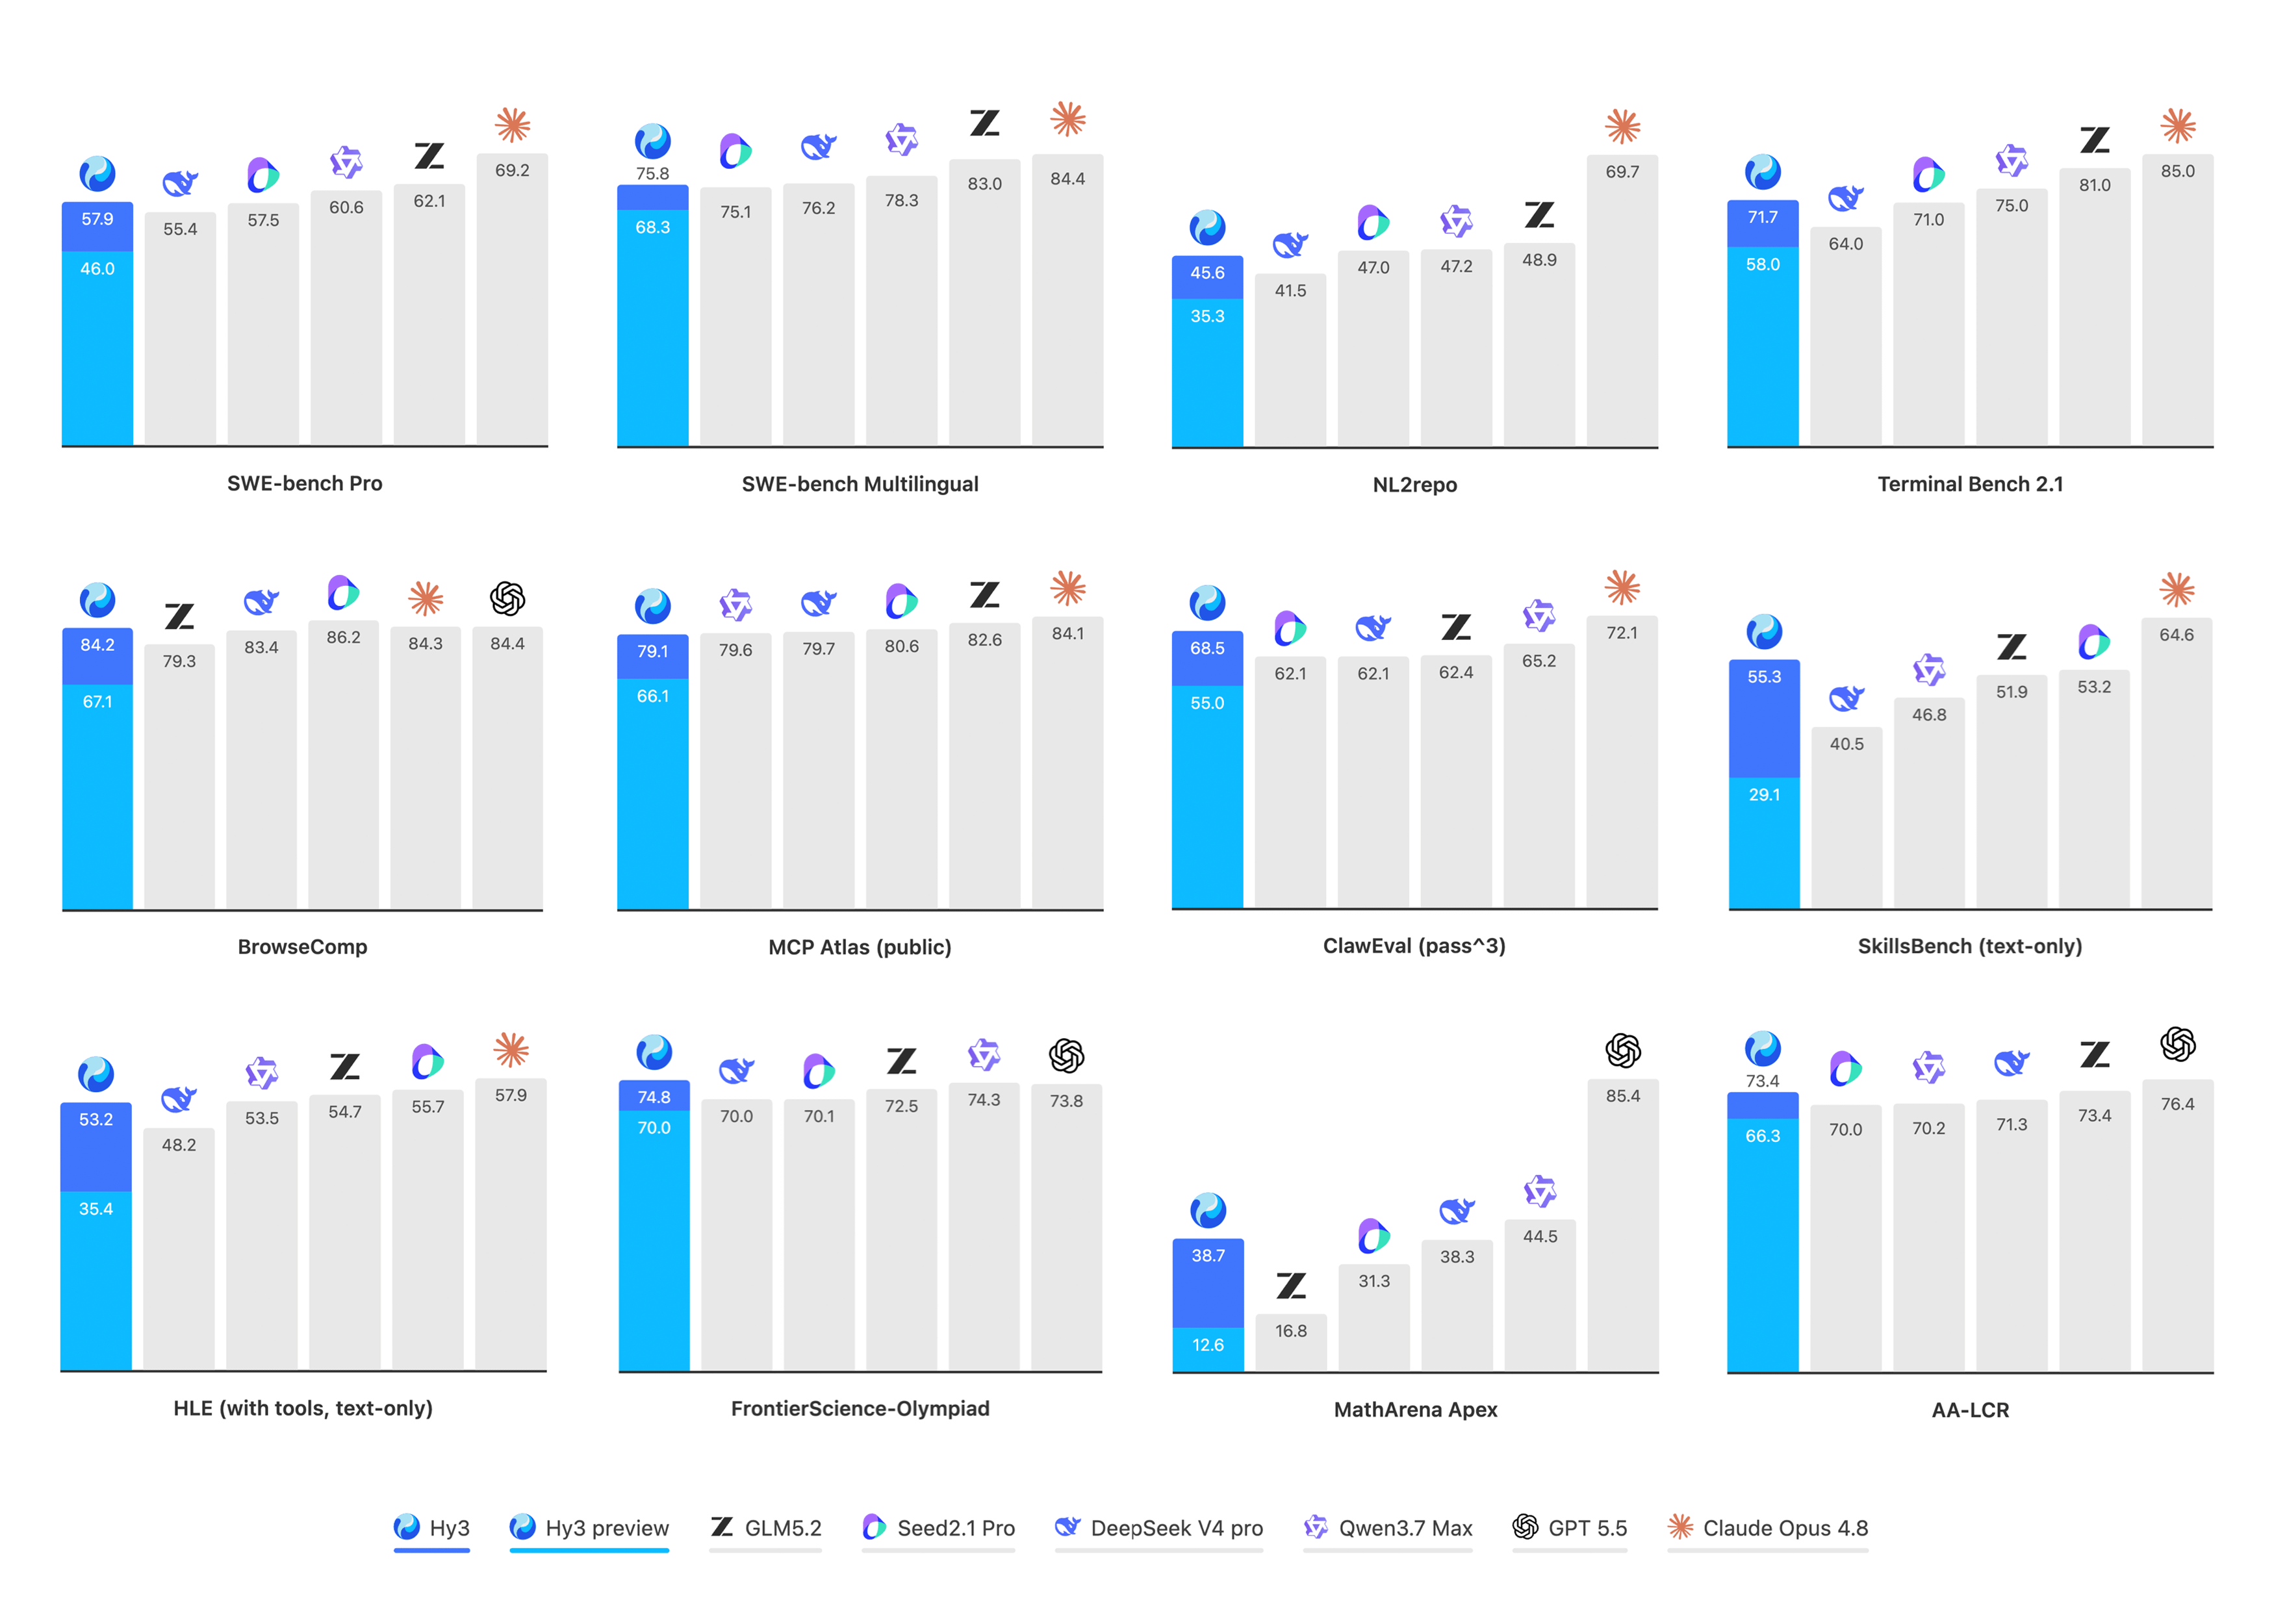
  • Hy4-preview by tencent: Tencent is becoming a serious player in the open model space, increasing the size of their flagship model while spinning the post-training flywheel. The result, Hy4-preview, is a competent model which currently has an issue with overthinking. However, if the trajectory from Hy3-preview to Hy3 is any indication, the final model might be a legit shot at the front ranks of open models.
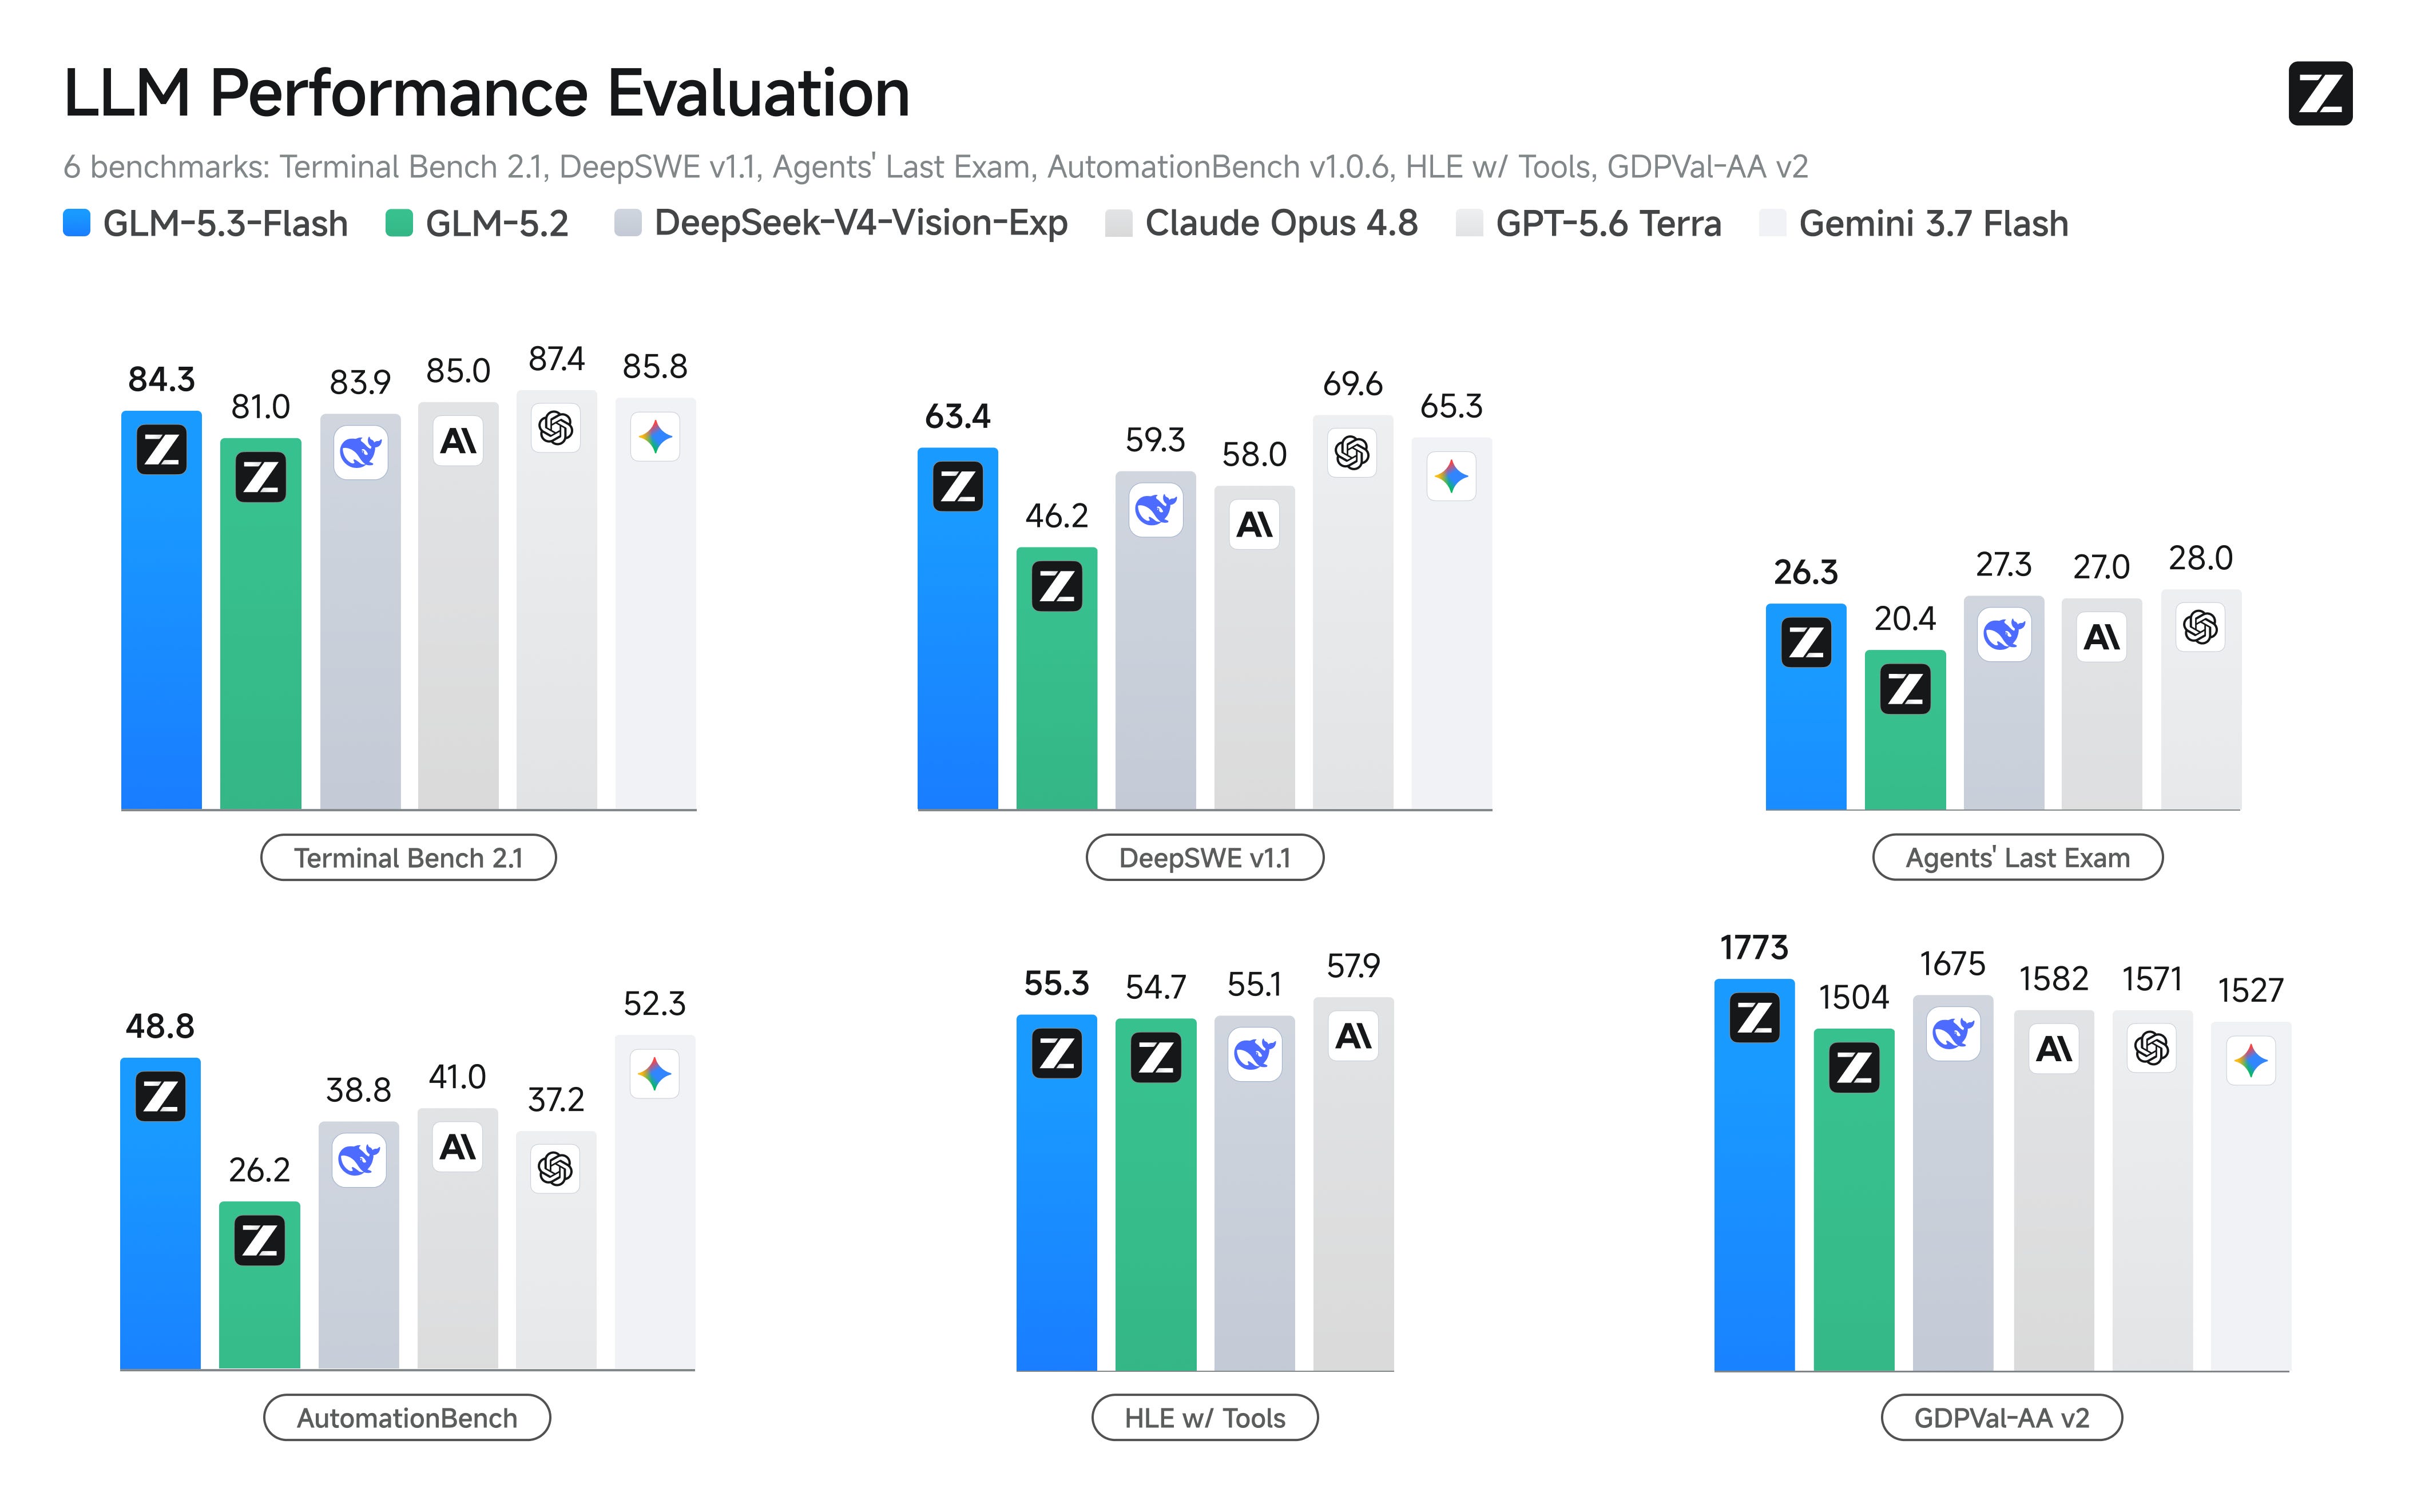
View more details on all the models in this issue at our Artifacts Hub.

Visit artifactshub.ai

Models

General Purpose

  • NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16 by nvidia: An update to Nemotron, which comes with performance — but especially speed improvements — across the board.
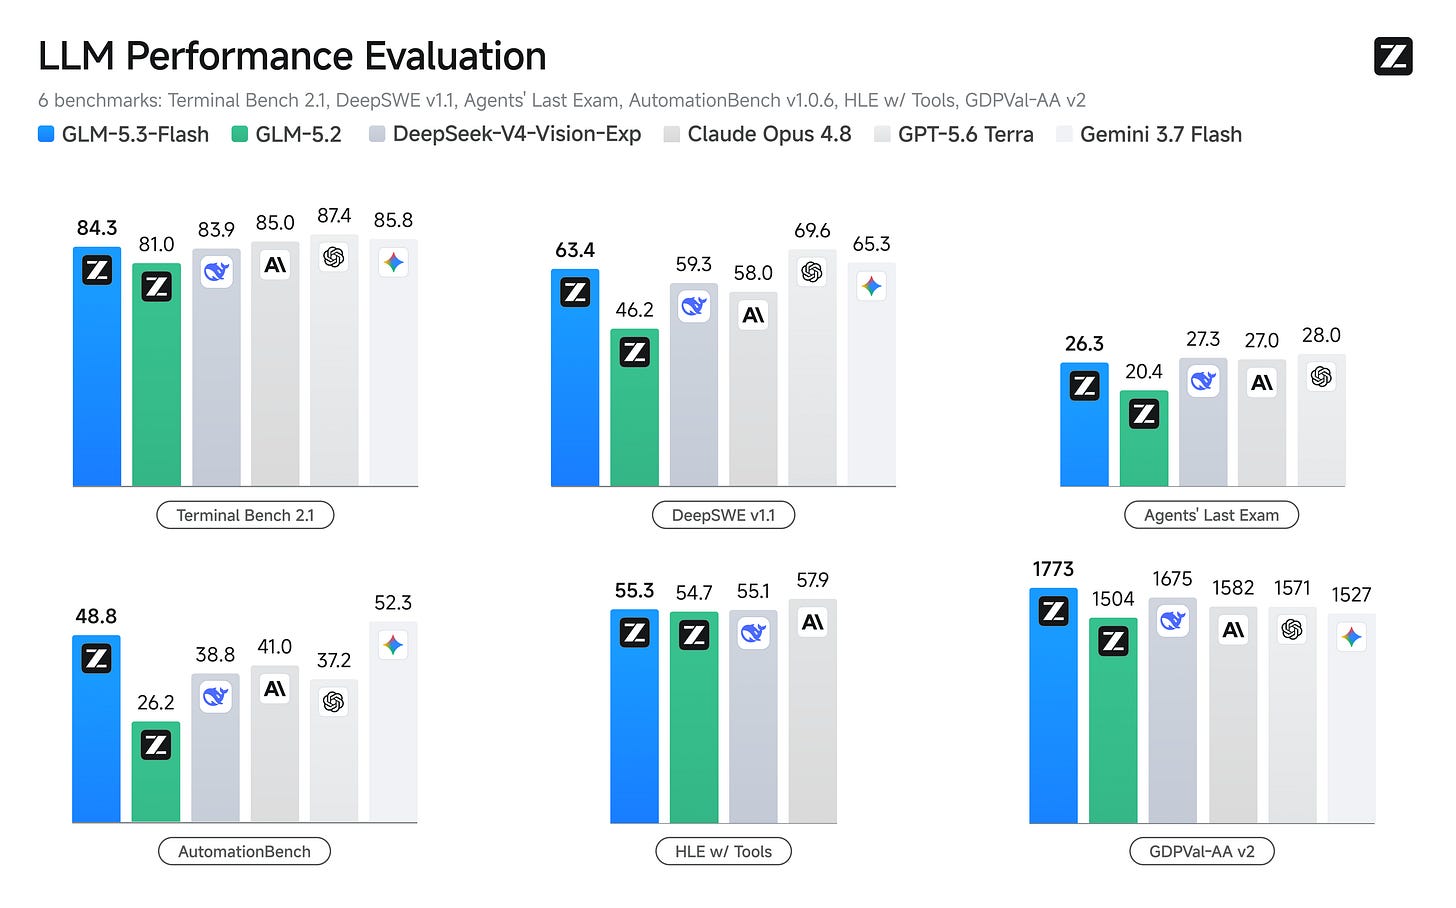
    bench_53
  • Ling-3.0-flash by inclusionAI: Ant Ling is a frequent guest at the Artifacts Log; they are now on their third iteration of models, adopting a hybrid design (KDA + Gated MLA), similar to others. They also release a small 7.9B-A1.3B version.

  • Qwen3.8-2.4T-A95B by Qwen: In a rather surprising turn of events, Alibaba started to openly release their biggest versions of Qwen as well. However, it comes with a custom license and its performance is behind other models of its size.
Read more

  •  

Latest open artifacts (#23): Laguna S2.1, Inkling, & Kimi K3 show the utility of open models on the Pareto frontier

Consolidation has been one of the paths that many astute observers predicted for the near-future of labs training models. It was labelled as inevitable, as training costs are increasing by orders of magnitude every year. Yet, as someone who in 2024 would’ve predicted consolidation really picking up come 2026 or 2027, where are we? We’re at a place where more companies are training strong models — easily investing hundreds of millions to billions of dollars in the total effort still — and an increasing number of organizations are releasing these models openly.

The demand for tokens is incredibly high, and likely to increase as models get more efficient and unlock more possible use cases. All of these labs we thought would need to consolidate are realizing that building token machines is a likely path to value, and more companies will identify that source of value over time.

The prime example is Thinking Machines — when they announced their company in February 2025, very few people would’ve put them in the bucket of an open models company, myself included. Now their open model finetuning service is making hundreds of millions in revenue per year and they’re releasing the best open-weight models built in the U.S.A. — ahead of the early leaders in NVIDIA with Nemotron and Arcee’s Trilogy.

Share

On the other side of the ecosystem is the sustained pace from the Chinese labs, with newer entrants like Xiaomi still accumulating mindshare in the broader AI economy. Having predicted consolidation for a long time, it now seems like a safer bet is to predict continued adoption, and try to imagine the role that open models play there. How much can revenue-share licenses like Kimi K3 stick? How much market share can open models take? We’re entering the decisive era.

This is one of the most packed recaps of open models we’ve ever had, we’re excited!

Our Picks

  • Inkling by thinkingmachines: The first model from Thinking Machines is a 975B-A41B multimodal MoE that supports text, images, and audio as inputs and produces text as output. While it is not the strongest model among peers (in China) in its size class, it is positioned to be a great base for fine-tuning, e.g., through their commercial offering, Tinker. They also release a smaller version (276B-A12B), which is really competitive for its size.

  • Hy3 by tencent: A 295B-A21B MoE from Tencent. It improves over its predecessor across all metrics. Most notable, however, is the license change: While the previous version (covered in Artifacts 21) used a custom and rather restrictive license, Tencent switched to Apache 2 for this release. The model was also able to proof a 50 year old math problem (with a dedicated harness and Sol as a judge, although it is unclear how important the latter really is).

  • Laguna-S-2.1 by poolside: Poolside quickly rose out of nowhere to become a frequent guest at Artifacts, marking its third appearance in three consecutive months. S2.1 is a newly pre- and post-trained version of the 118B-A8B MoE that fits on a DGX Spark, which brought it a lot of attention. Poolside also adopted the OpenMDW license, which is an Apache 2.0-like free license but has better legal backing for AI models specifically. The company also goes into more detail in its blog, which includes all the evaluation trajectories. This is a lot of transparency for an open model release!

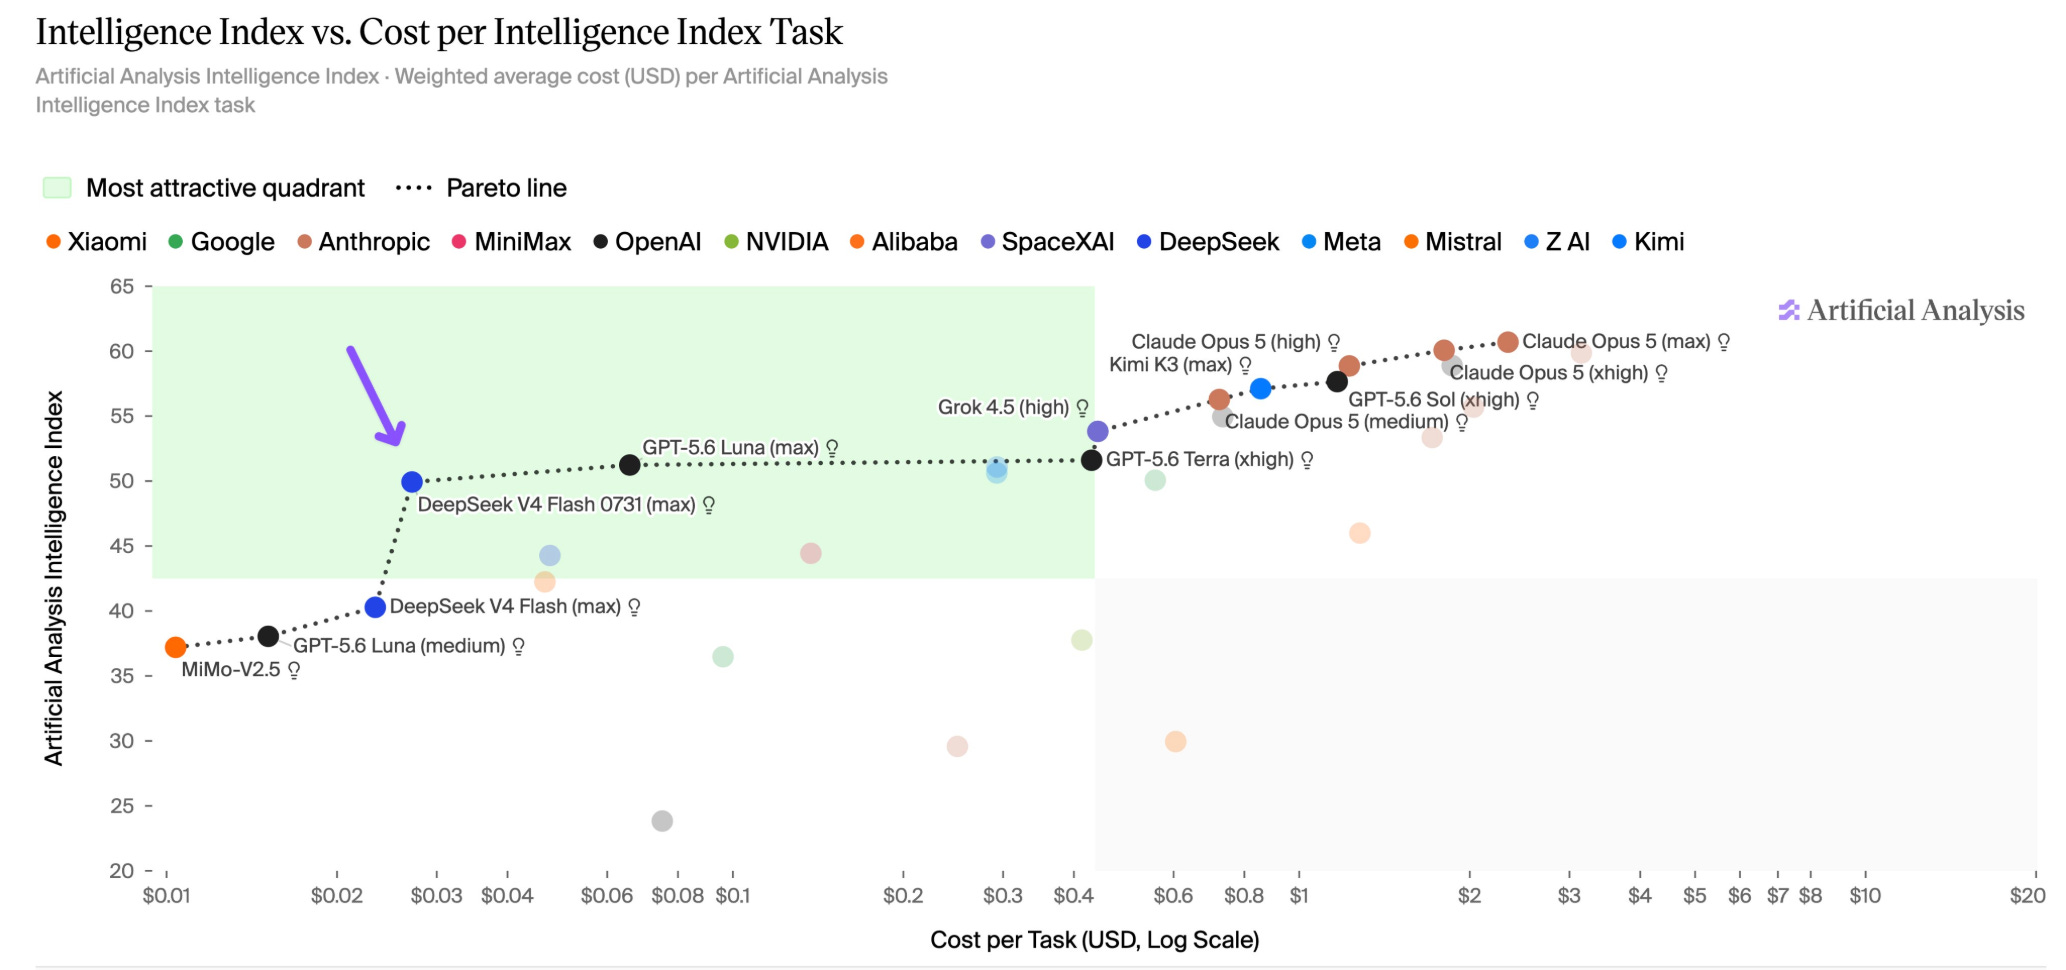
  • DeepSeek-V4-Flash-0731 by deepseek-ai: Just one day after OpenAI has dropped the prices of their smallest model by 80%, the whale dropped an update to their V4 Flash model, beating Luna at the pareto frontier. The bigger model is not updated yet, so it remains to be seen where it will land in terms of performance. For the initial V4 releases, the Flash version was the star of the show in terms of performance per parameter, while Pro was rather underwhelming.

  • Kimi-K3 by moonshotai: This is the biggest open model release in some time, and we covered it in a separate post and a podcast episode. It was released under a noncommercial license, requiring inference and fine-tuning providers to enter into a commercial agreement. Kevin Xu and Graham Webster argue in a post that these licenses enable potential future government action against US entities doing business with Chinese AI companies:

But if a US company needs a contract with Moonshot to provide the inference tokens that Kimi K3 generates, the picture looks different. Some of the policy tools US officials and others have debated as potential levers to restrict Chinese open model use would more clearly apply.

Models

General Purpose

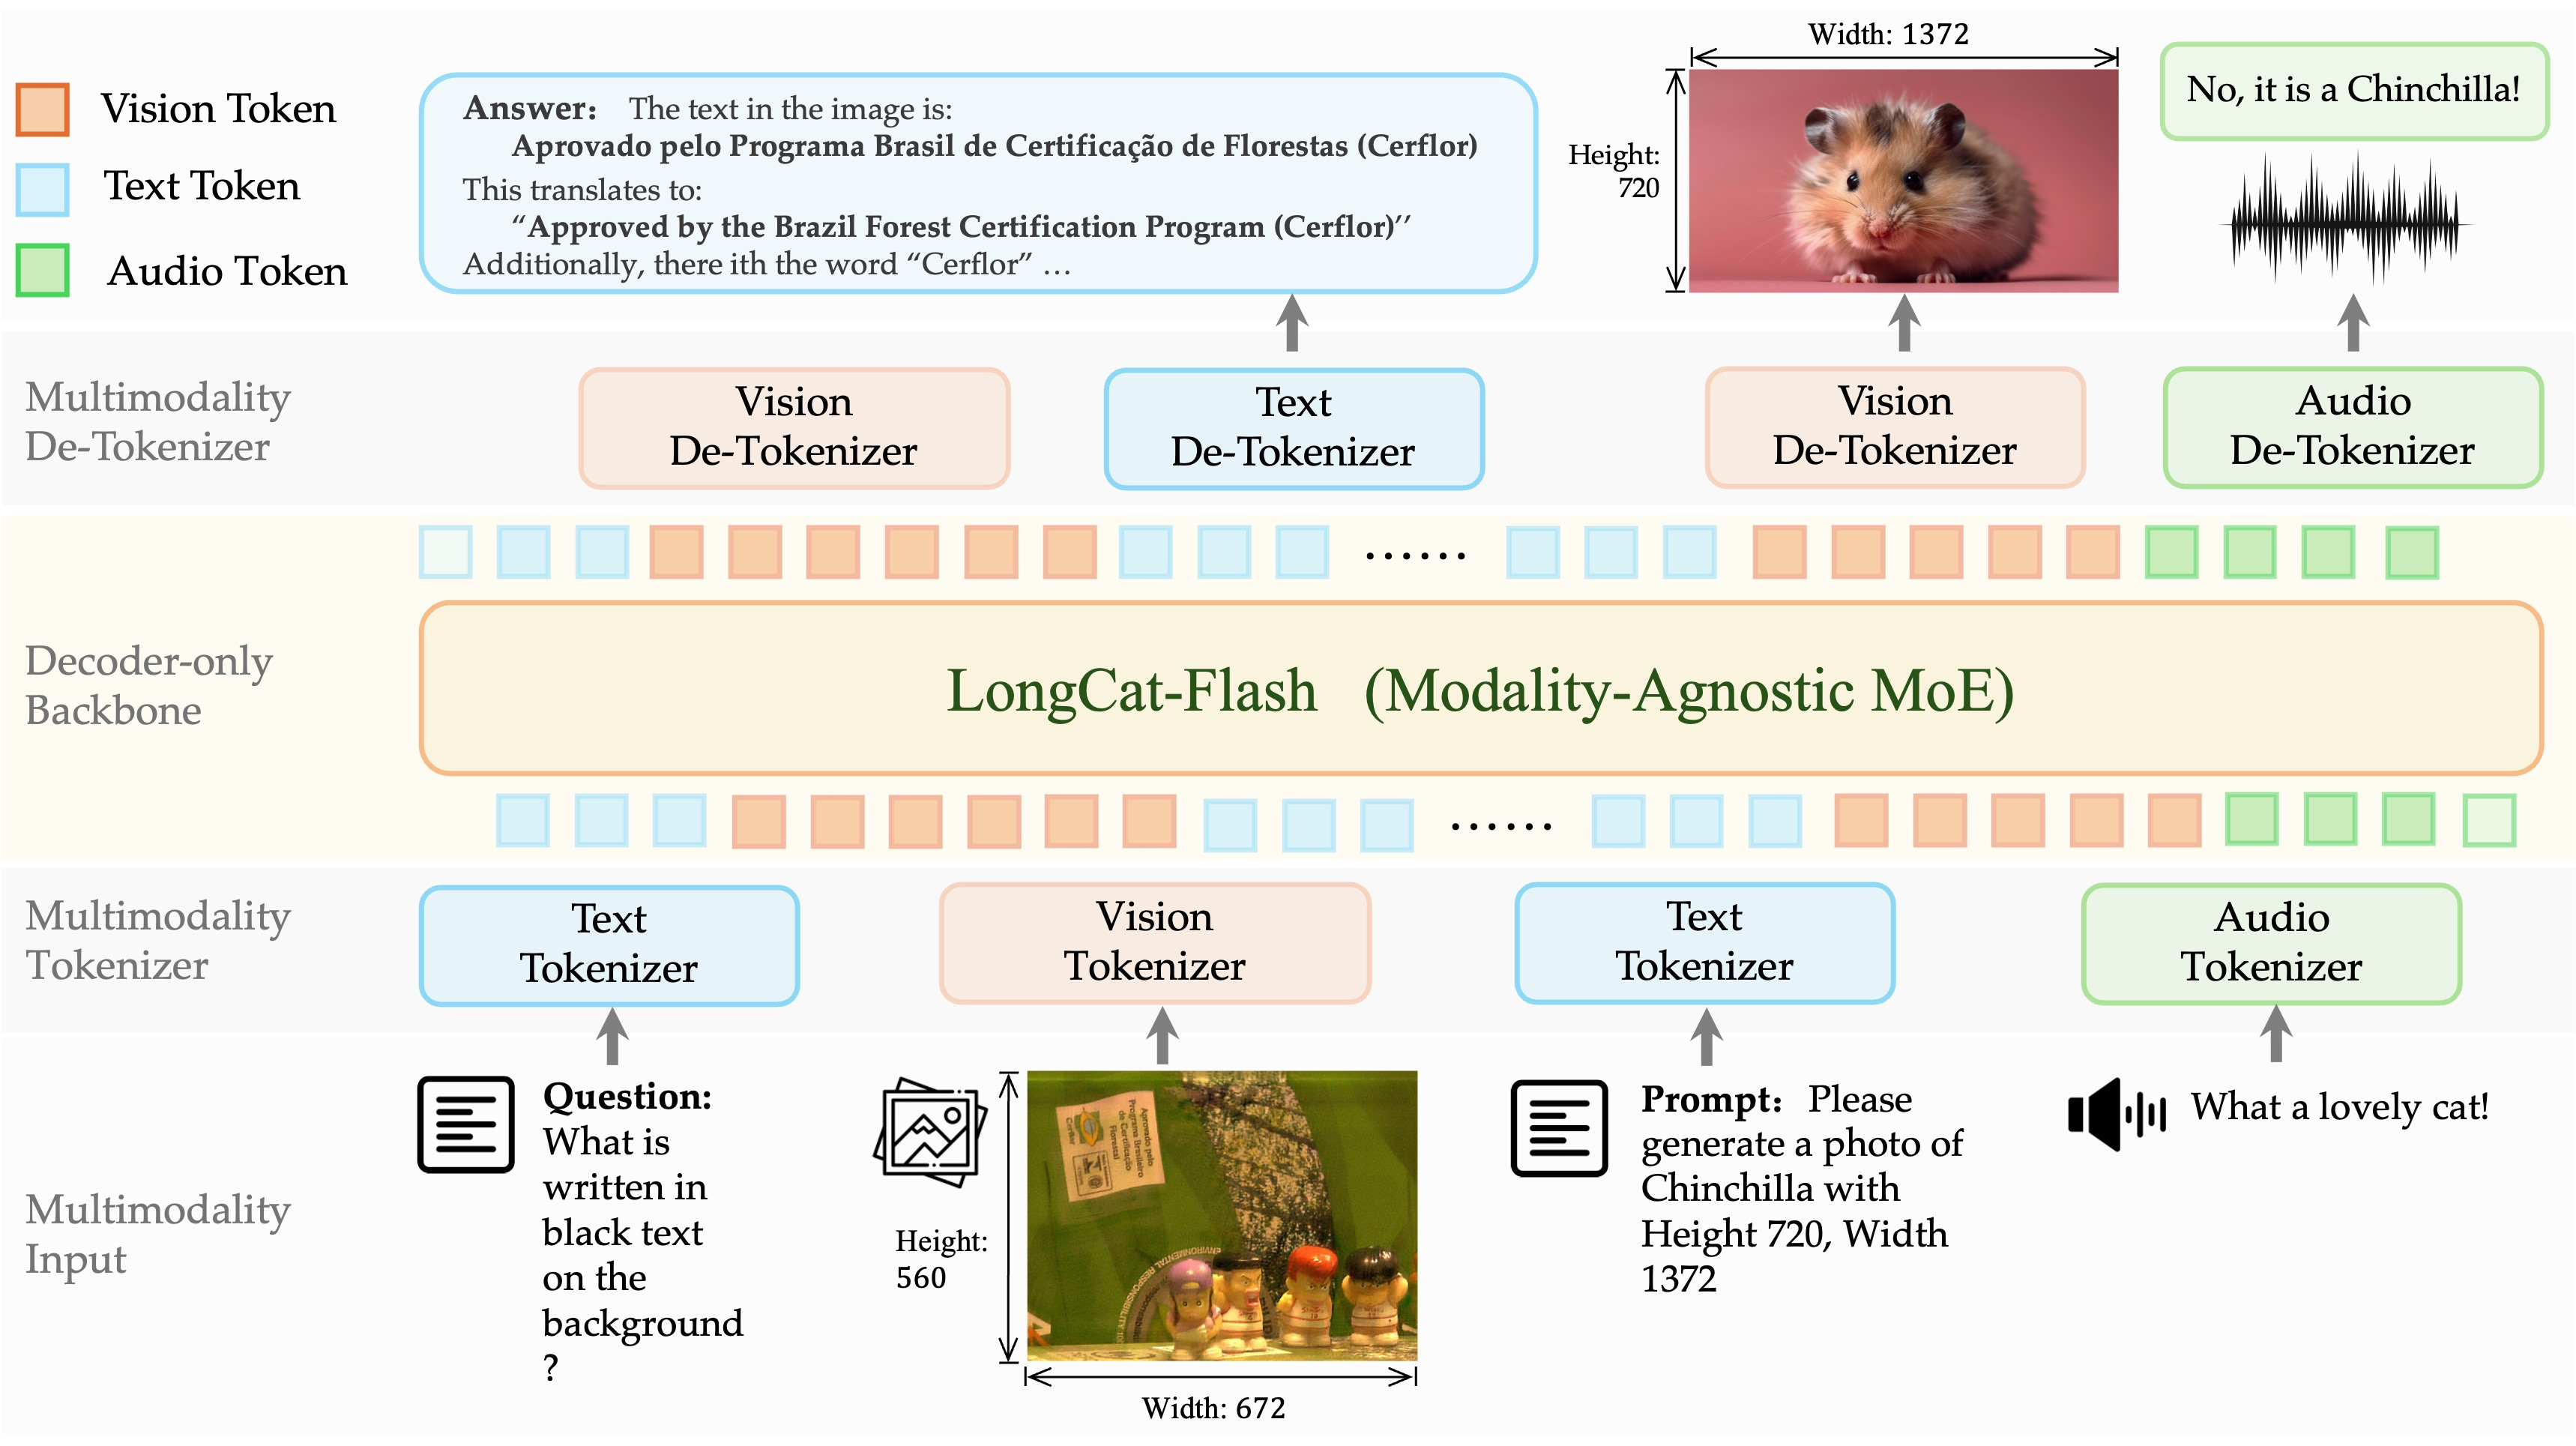
  • LongCat-2.0 by meituan-longcat: The Chinese DoorDash is back again. This time, the company released another big MoE with 1.6T parameters. While the model itself is not the most capable for its size beyond benchmarks, it was trained entirely on Ascend 910s, making it the first non-Huawei, non-toy model trained entirely on Chinese accelerators. Other Chinese chips are mostly used for inference (if at all).

  • Laguna-XS-2.1 by poolside: An update to the small (33B-A3B) MoE from Poolside.

  • Motif-3-Beta by Motif-Technologies: A preview of a 314B-A13B MoE by the Korean Motif. This is by far the company’s most ambitious model, as it is considerably larger and introduces some architectural innovations like GDLA and mHC.

  • Apertus-v1.5-70B by swiss-ai: A continued pre-train of the fully open-source Apertus 1.0, using 2T more tokens.

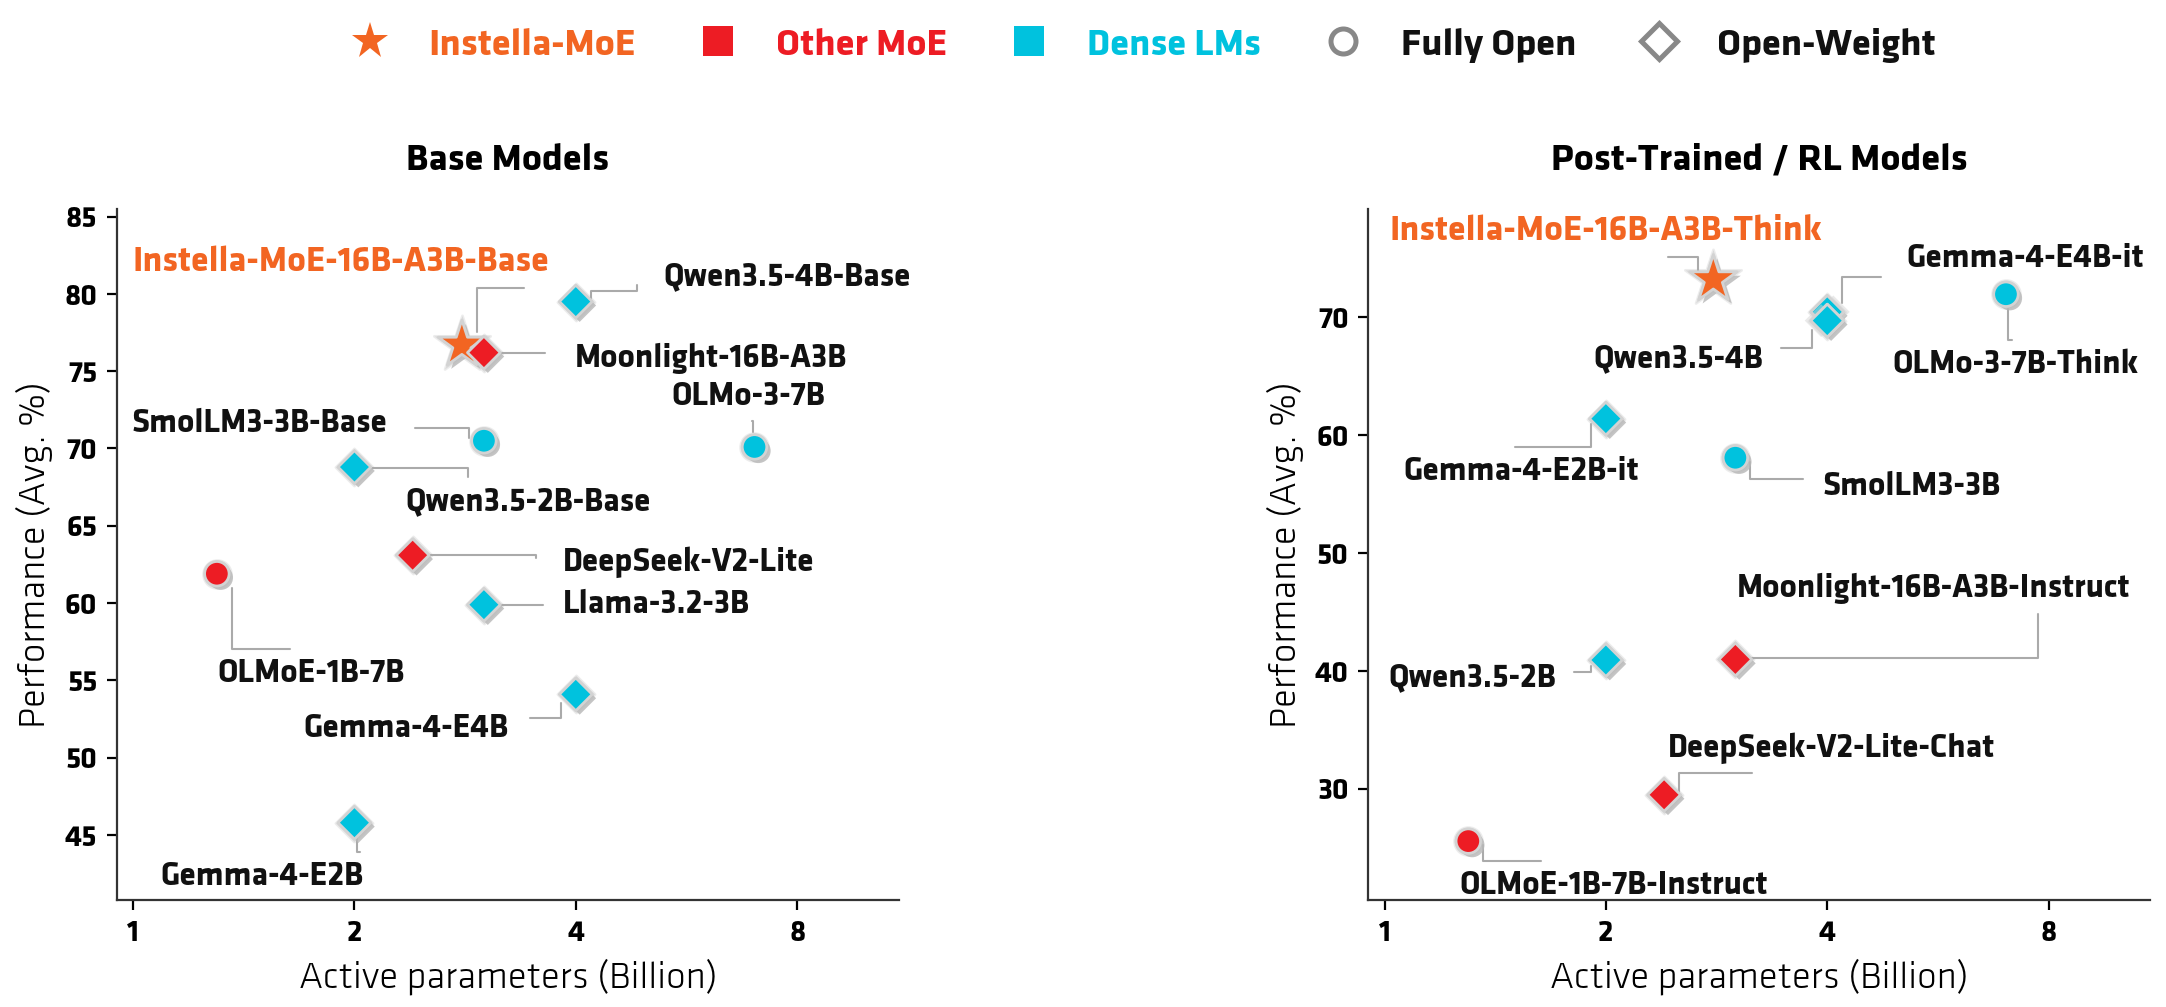
  • Instella-MoE-16B-A3B-Think by amd: A 16B-A3B MoE trained by AMD on Instinct cards. AMD also provides all the different stages, from the base to the SFT checkpoints, as well as MidTrain and DPO.

    Instella-MoE cost vs. performance

Read more

  •  

Latest open artifacts (#22): Zyphra, Cohere, and Poolside are expanding the breadth of the ecosystem

A trend we continue to see in open model releases is that the ecosystem is becoming more diverse, with an increasing number of organizations releasing a wide range of models. A year ago, open artifacts and the open model landscape more broadly were dominated by a handful of (Chinese) players. This has shifted, with us increasingly featuring more niche companies all over the world.

While it is hard to know the exact motivations of the companies themselves, we can broadly observe the following categories:

  • “Pure” model makers: These are companies whose stated goal is to train models that are at the frontier, or at least close to it. This includes many Chinese companies, such as DeepSeek, Zhipu, and Minimax, but also Western ones like Poolside, Arcee, and Zyphra. It also increasingly includes sovereign AI players, such as Cohere, Sovereign, Mistral, and Trillion Labs. The recent Mythos episode has woken up some policymakers, which may lead to increased interest in sovereign model training.

  • Big Tech: For Big Tech companies, including Alibaba’s Qwen, Google’s Gemma, and, to some extent, NVIDIA, the motivations are more diverse. Alibaba uses model releases to upsell its closed models, while NVIDIA benefits from a flourishing open model ecosystem as it increases interest in and usage of its GPUs. This vested interest is different from the Llama era of open Western models, where the motivations for open releases were less clear (and ultimately did not hold).

  • Product companies: Some companies, such as JetBrains, Zed, Krea, and Photoroom, mainly sell products that use AI as a core component. As they don’t want to be cut off from accessing closed models or want to offer something unique, they can train highly specialized, small models that fit their product needs. Thus, open-sourcing those model weights does not hurt their bottom line.

This diversity of makers and models fits our hypothesis that more companies will develop a long-tail of models and the number of companies chasing the absolute, open frontier will diminish.

Share

While not every model release fits neatly into one of these categories, the broader point is that open model development is not driven by a single type of actor or motivation. This diversity is one of the strengths of the open ecosystem and can be seen in the tech reports of model releases, which reuse training methods, architecture choices and data from other open model releases.

Attempts to slow or ban this ecosystem are not only futile, as the history of tech-related bans has shown, but also unsafe and anti-freedom. Such restrictions would concentrate AI development and usage among the select few, which ultimately endangers outsiders’ ability to freely adopt one of the most important technologies of our lifetime.

Our Picks

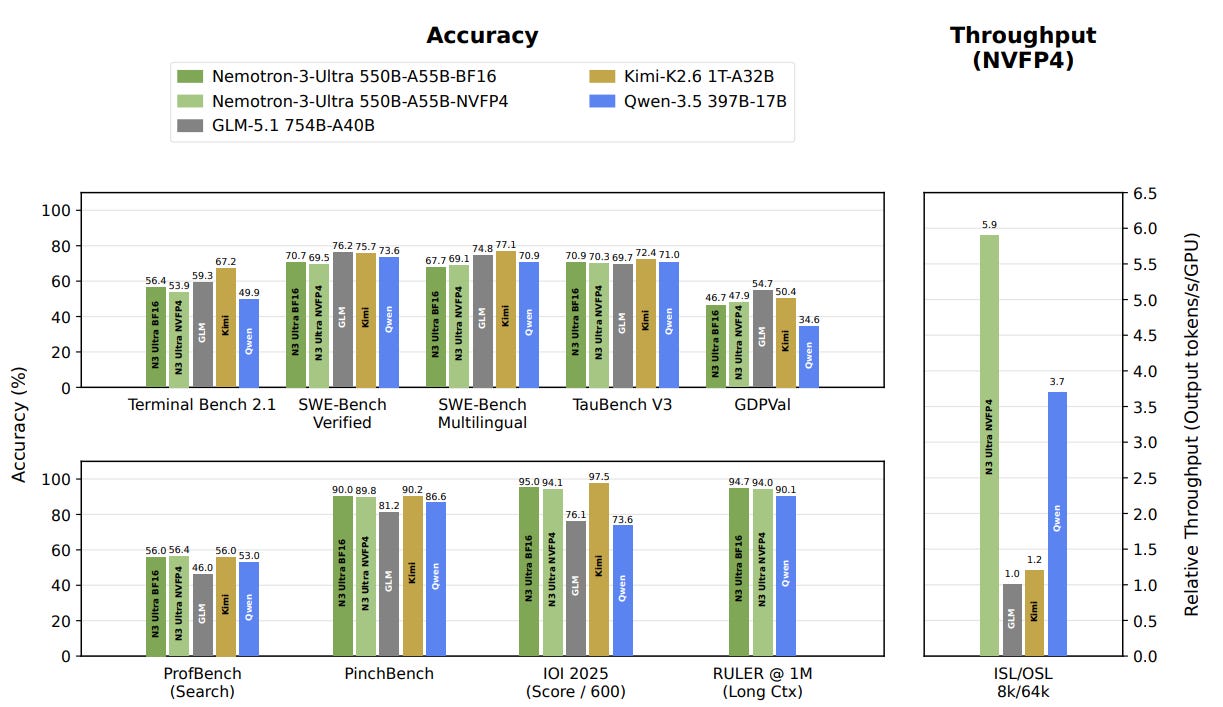
  • NVIDIA-Nemotron-3-Ultra-550B-A55B-BF16 by nvidia: The big version of the Nemotron series, which uses LatentMoE to be even faster than comparable models. Just like the other Nemotron models, the vast majority of the data is open source. And, to top it all off: NVIDIA commits to using the OpenMDW license, which is tailored specifically for model weights (and data) and drops its custom license. While MIT and Apache are in the same spirit as OpenMDW, only the latter really covers model weights, while the former are software licenses that do not really apply to model weights.

  • command-a-plus-05-2026-bf16 by CohereLabs: Cohere, which is becoming more of a regular entrant into Artifacts lately, released their flagship, Command A+, under Apache 2.0. Previous iterations of the series have been released under a non-commercial license, so this change is more than welcome! Command A+ combines multi-modal, multi-lingual and agentic capabilities as a 218B-A25B MoE, making it usable with a single B200 (when using 4-bit).

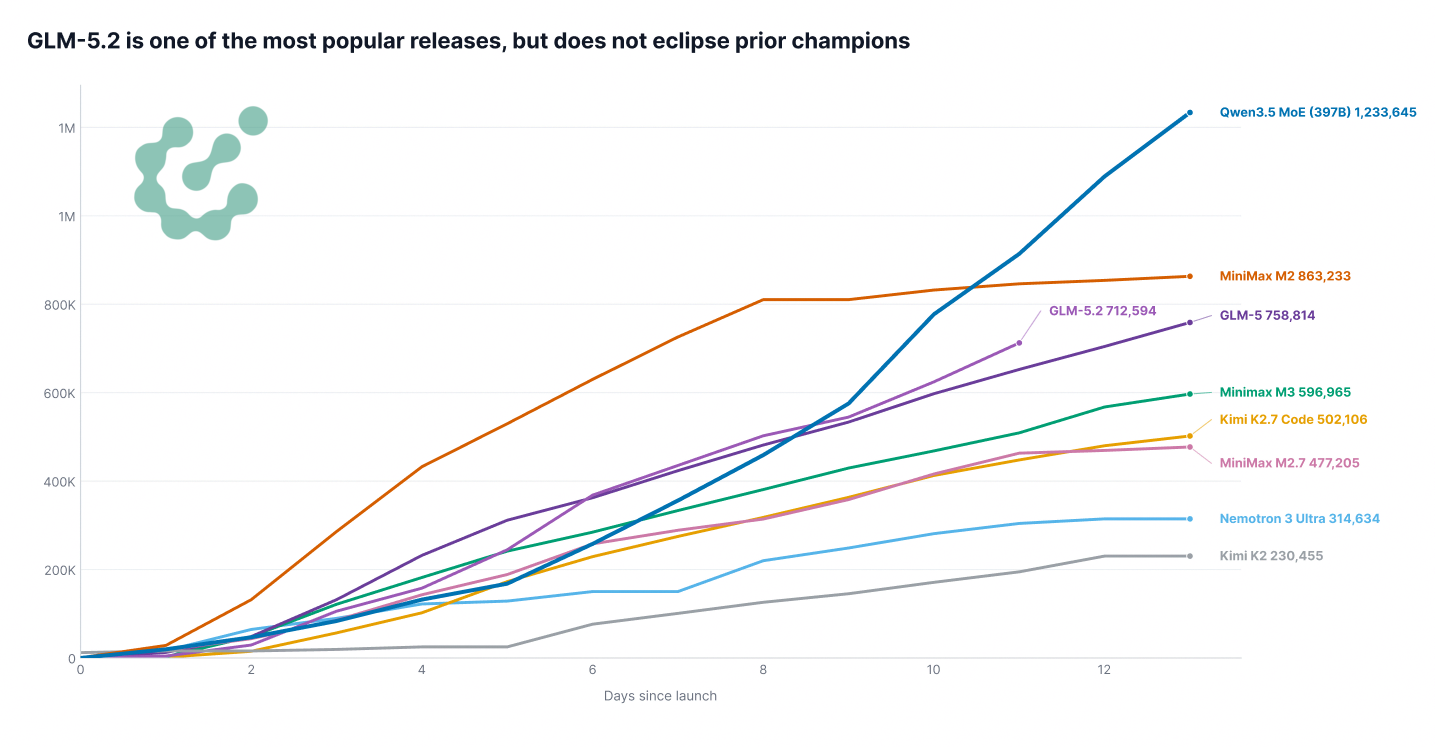
  • GLM-5.2 by zai-org: The biggest story in this Artifacts is GLM-5.2, which we have covered in a separate blog as well. The model continues to impress and is genuinely usable for everyday work, not a huge regression compared to the best closed models available right now. Interestingly enough, the raw download numbers since release are more in line with other model releases, with GLM-5.2 being roughly in line with GLM-5 after release.

  • ZAYA1-74B-preview by Zyphra: Zyphra, which trains on AMD GPUs and is known as some sort of insider tip in the research community due to their tech reports with interesting architecture choices, has released some new models, with a 74B-A4B MoE and an 8B-A0.6B MoE (tech report) being their current flagship releases.

  • Laguna-M.1 by poolside: Poolside, which we covered in the last Artifacts, also released their flagship model under Apache 2.0! They also commit to open releases going forward:

    Open weights are now our default. We’ll keep building toward the frontier and releasing increasingly capable models in the open.

Models

General Purpose

Read more

  •  

Latest open artifacts (#21): Open model bonanza! Gemma 4, DeepSeek V4, Kimi K2.6, MiMo 2.5, GLM-5.1 & others. On CAISI's V4 assessment.

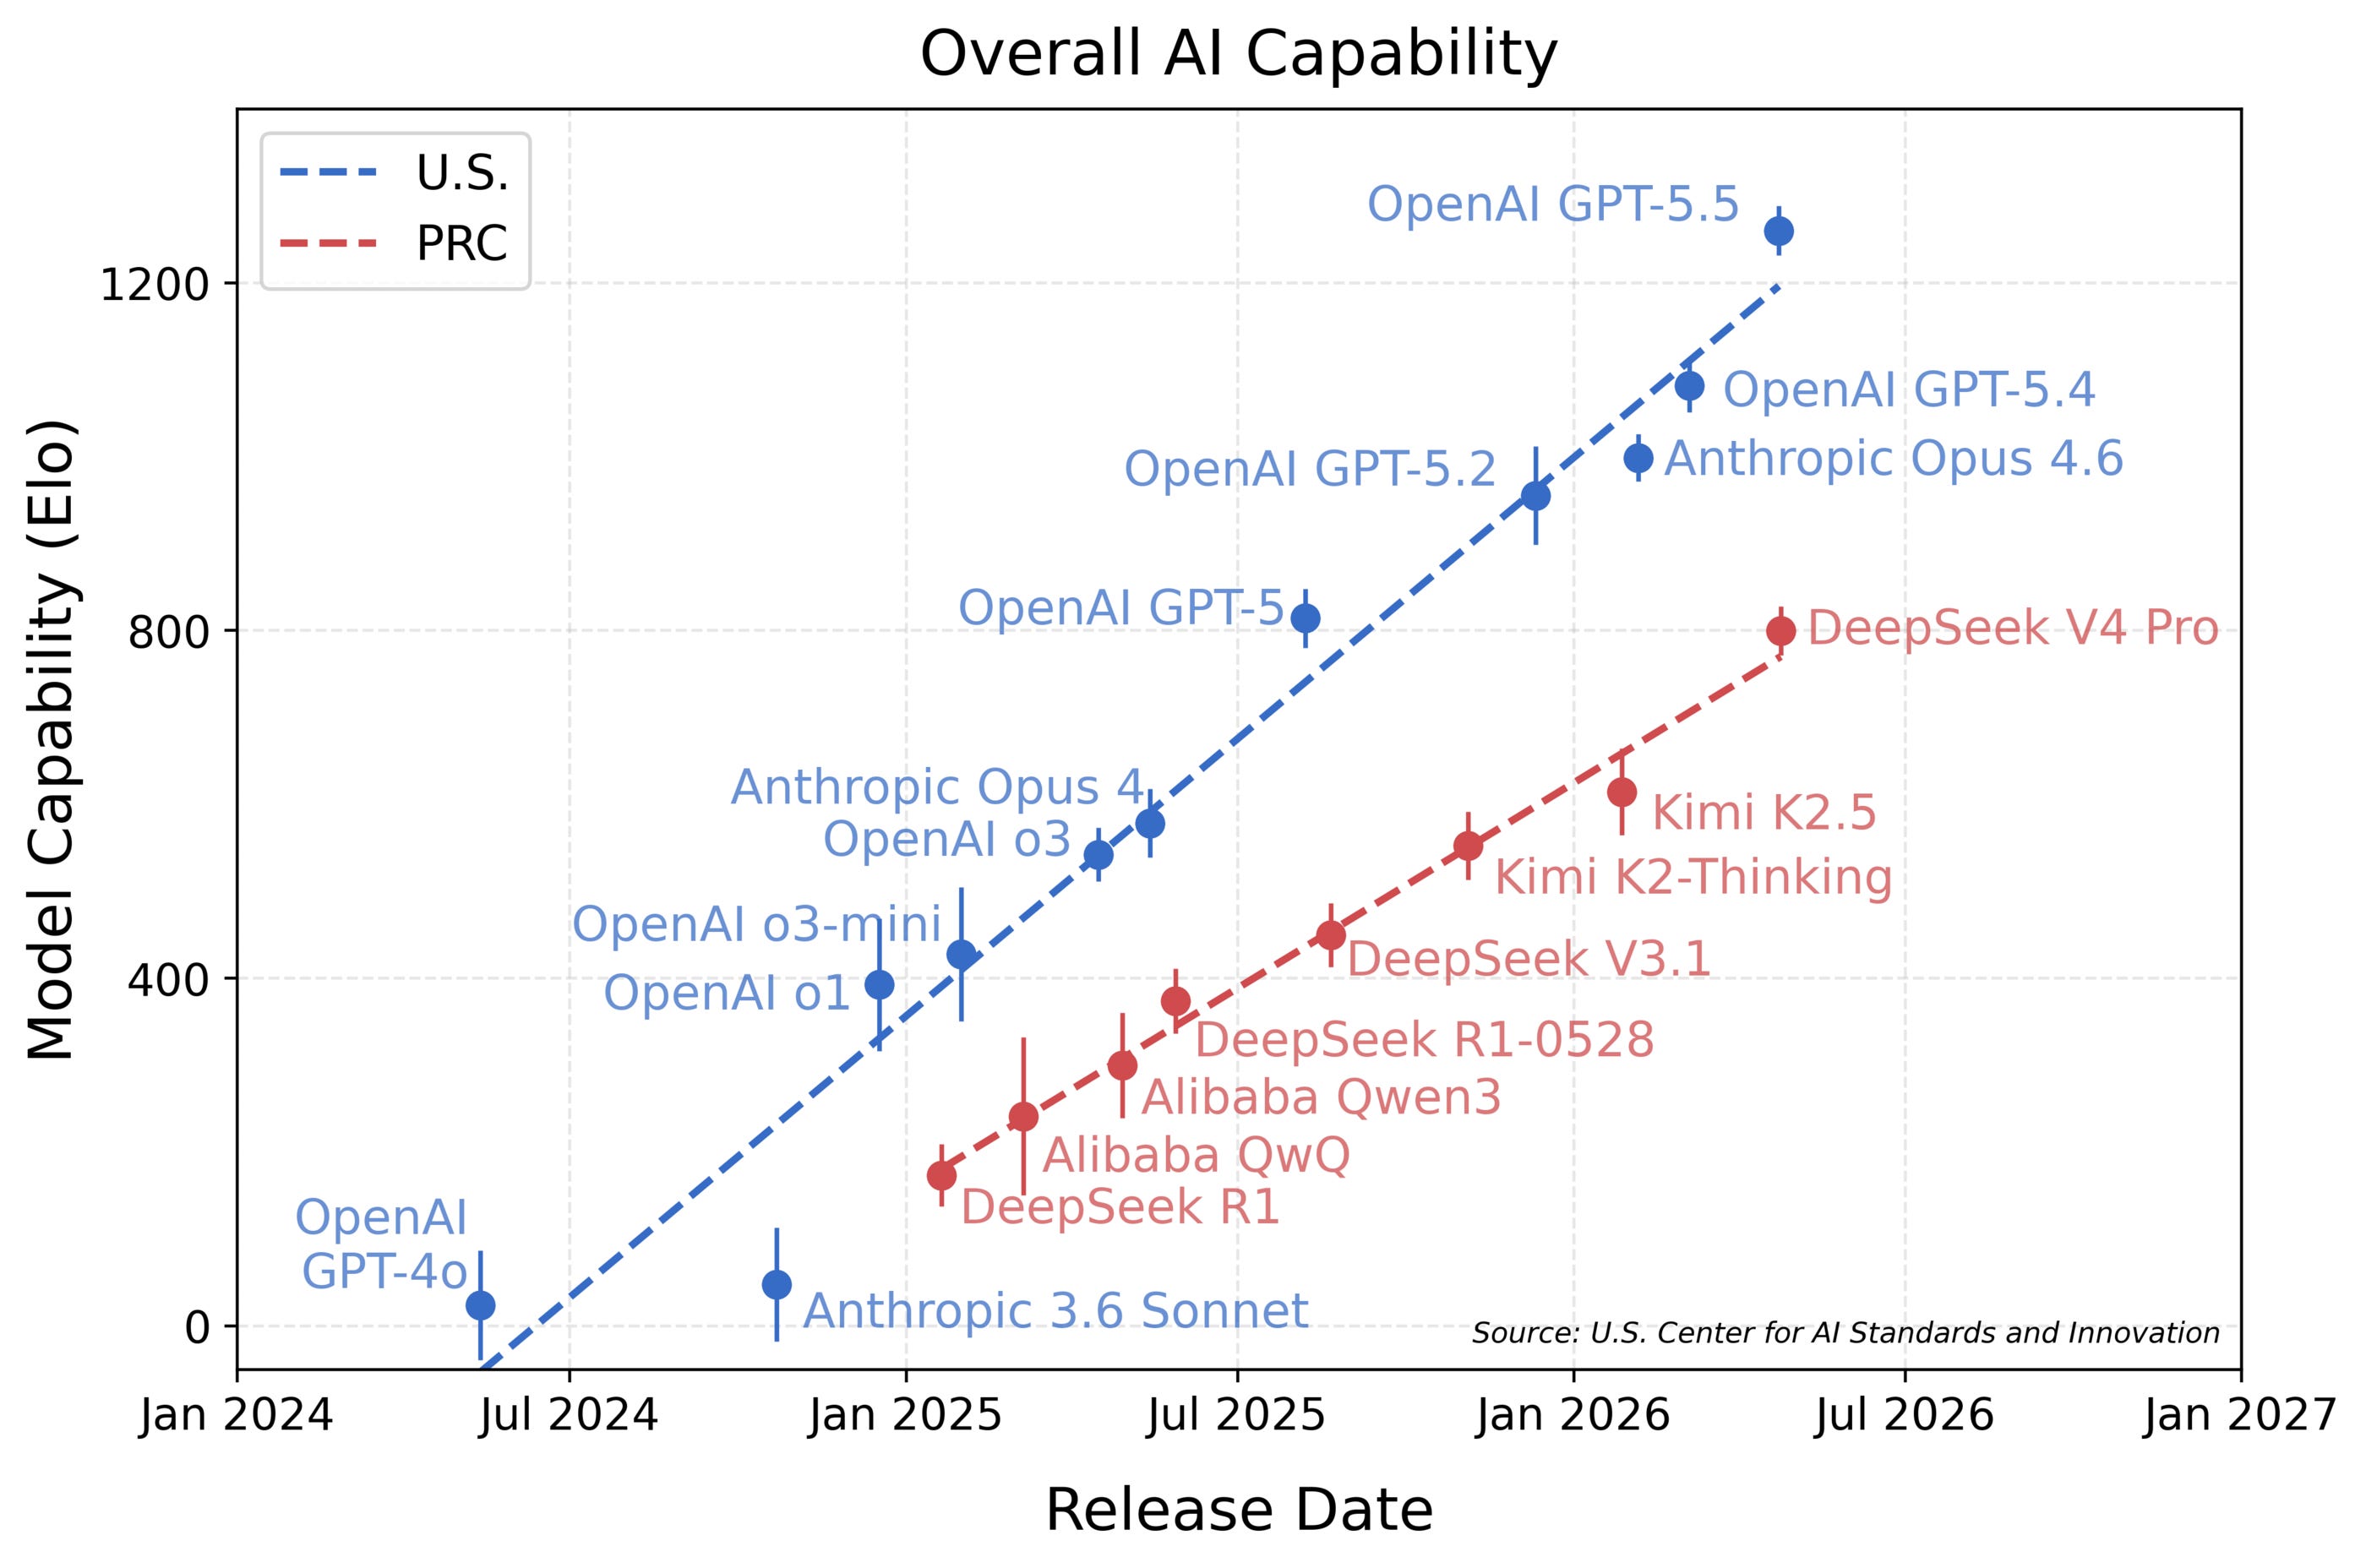
This month was packed, with all open frontier labs, including DeepSeek, releasing new models. The latter prompted an evaluation by the Center for AI Standards and Innovation (CAISI), which has evaluated open models and their risks in the past. Their result is that open models lag behind the American frontier, with the gap becoming wider over time:

Comparison of aggregate capabilities over time of the most capable publicly released U.S. and PRC models according to a suite of benchmarks covering five domains.

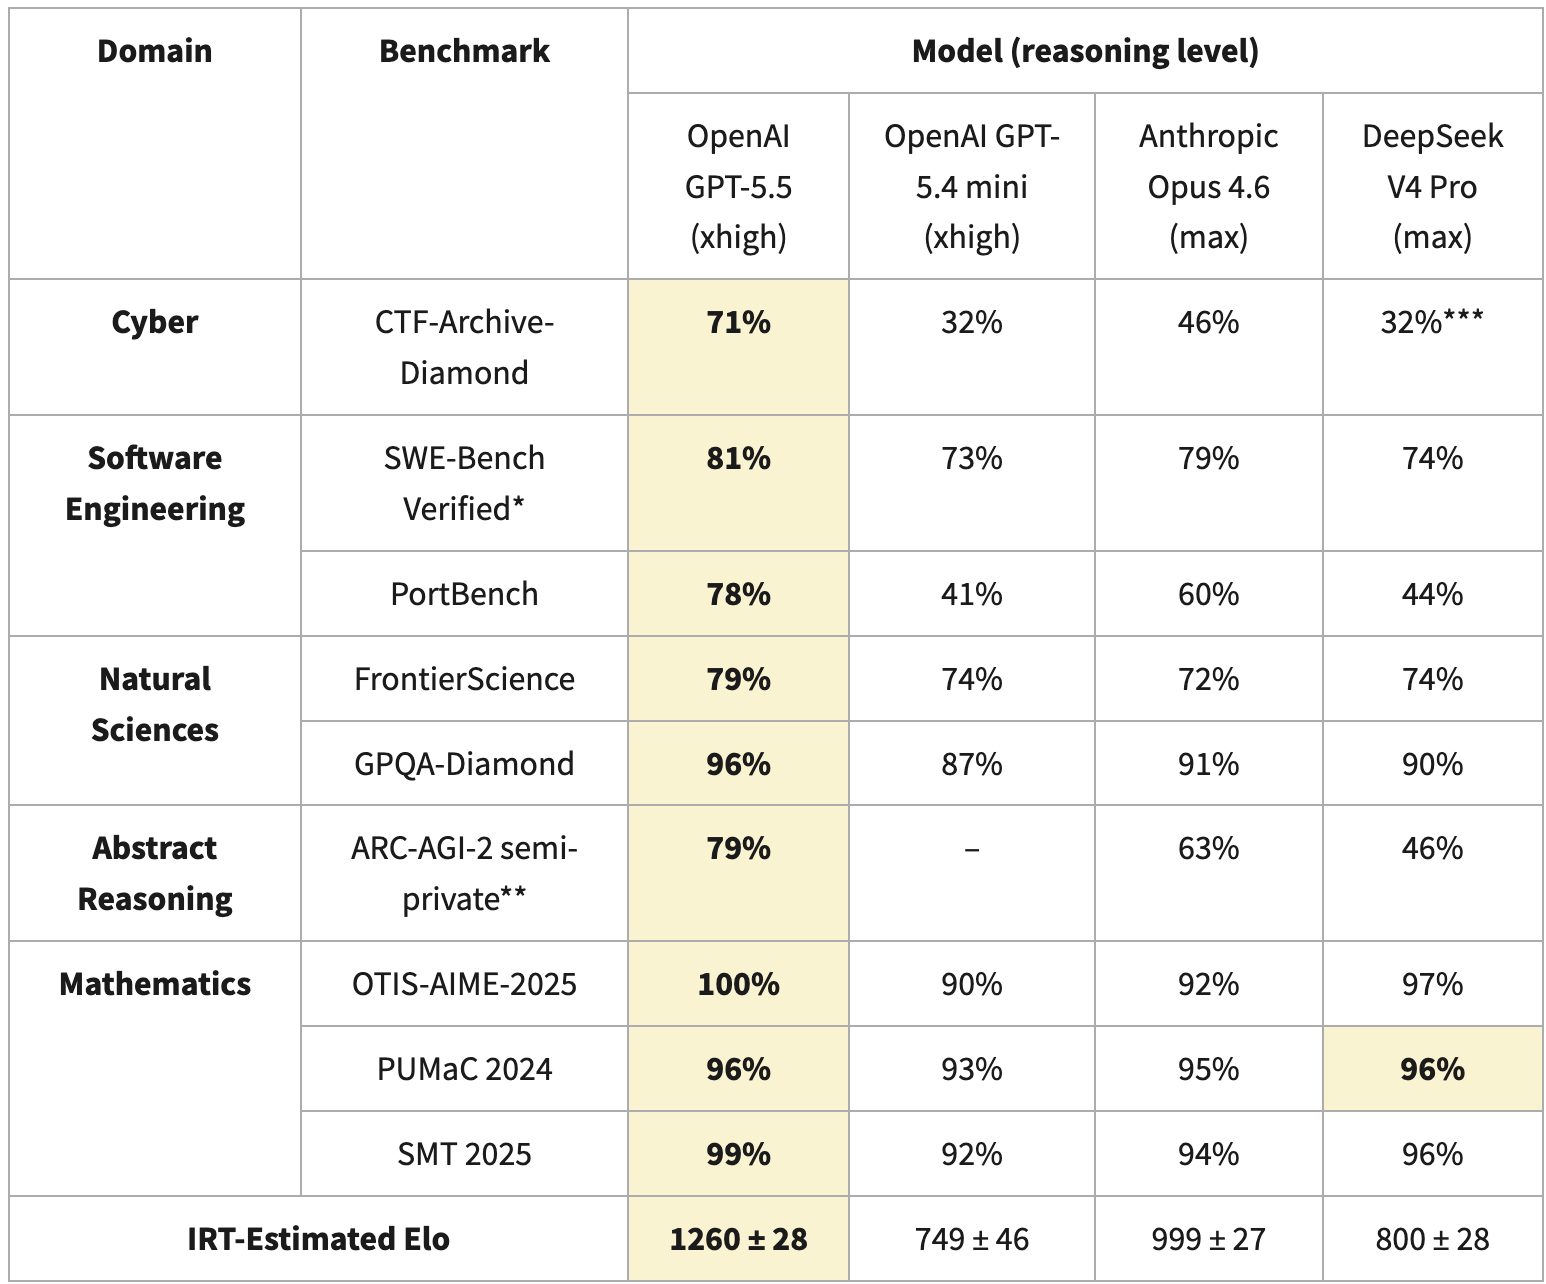
For the report, they calculate an Elo score based on Item Response Theory, which is commonly used to compare different models, even when they were tested on a different set of benchmarks. For V4, CAISI used nine different benchmarks:

The huge Elo difference is explained by DeepSeek V4s bad score in CTF-Archive-Diamond (which was only run with a subset of the benchmark and extrapolated with IRT for V4), PortBench (a CAISI-private benchmark) and ARC-AGI-2 (with a different scoring method than the public leaderboards). The differences in these benchmark have a huge impact on the overall Elo, which can exacerbate the difference in capabilities.

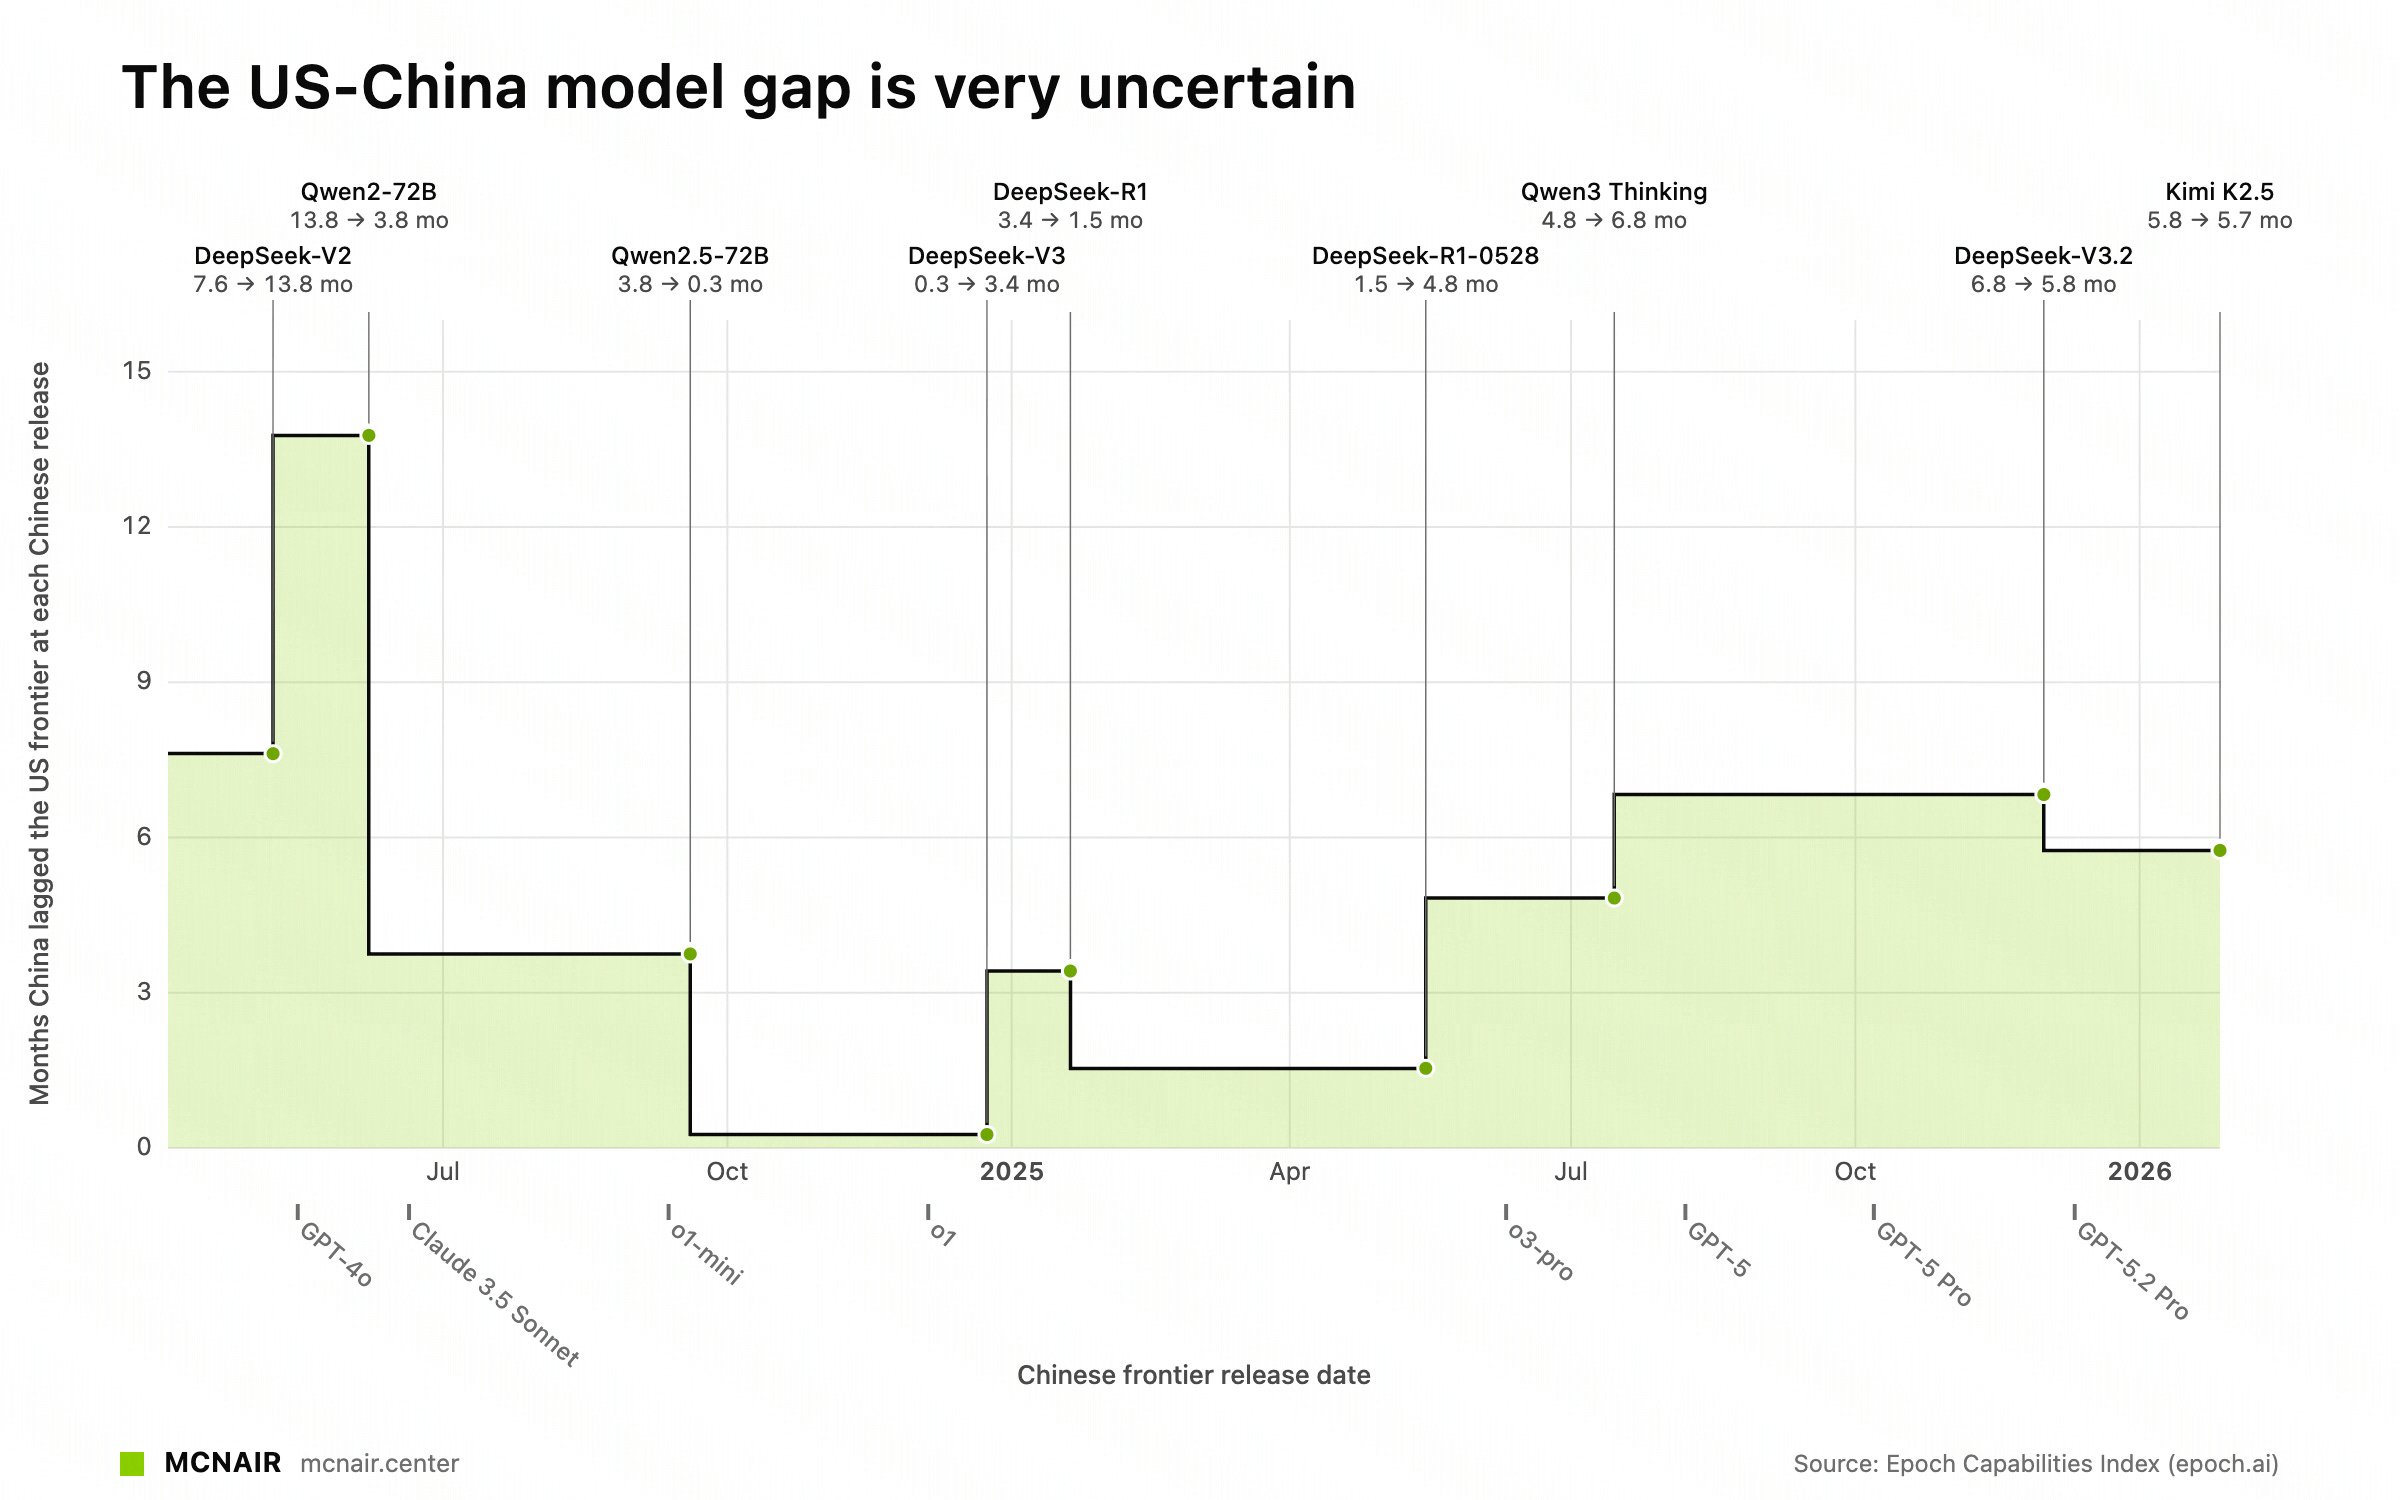
When using Epoch AI’s ECI, which also uses IRT over a set of different benchmarks, we see that the gap roughly stays between 3-7 months since R1:

The open<>closed gap in ECI (from https://mcnair.center/china/)

However, both CAISI and ECI paint an incomplete picture, as both use standardized (and simple) setups to compare the capabilities of models. To be more concrete: Coding tasks are evaluated using access to bash and a for-loop with a fixed budget of tokens, not with a harness such as Claude Code or OpenCode, which models are trained in! These setups result in benchmarks claiming that porting applications to another language is currently not possible, while Bun has been ported from Zig to Rust with 1 million LOC changes1.

Therefore, we would argue that a frontier comparison of open and closed models would also need to elicit the capabilities of all models better, which means the usage of the preferred harnesses, as well as model-specific prompting.

This section was written primarily by Florian. An interesting dynamic within Interconnects is that Florian believes more in the proximity of open frontier models to closed alternatives in true performance. Nathan thinks the benchmarks are imperfect as well, but thinks the closed models are ahead by more. We’re going to continue to unpack this in our future content.

Share

Our Picks

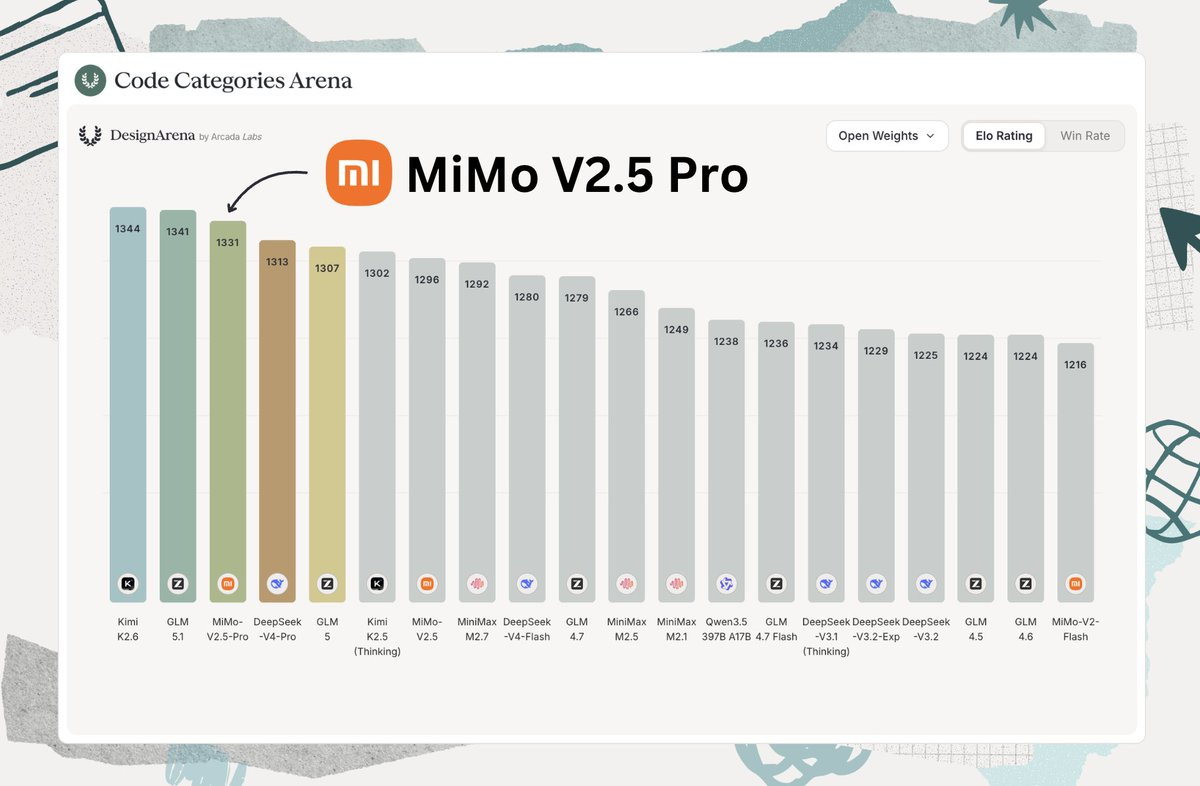
  • MiMo-V2.5-Pro by XiaomiMiMo: Avid Artifacts readers know that Xiaomi has been working on open models for a while; its debut was exactly one year ago. The progress of its releases is remarkable, with 2.5 Pro (released under Apache 2.0) being neck and neck with other flagship models such as Kimi K2.6 and GLM-5.1 in both benchmarks and real-world usage.

    Image
  • gemma-4-26B-A4B-it by google (full Interconnects post here): The long-awaited update to the Gemma series, featuring multiple sizes: 4B, 9B, and 31B dense models, as well as a 26B-A4B MoE. Even more importantly, with Gemma 4, Google has decided to use Apache 2.0 as its license, which removes the uncertainty and legal challenges around interpreting custom licenses.

  • Kimi-K2.6 by moonshotai: An update to the Kimi series, delivering stronger performance across the board and making it one of the best open models out there yet again. They also focus on long-horizon performance, showing that open models are capable of running over hours to complete tasks or optimize performance. Given the focus of everyone to build autoresearch-like systems, seeing open models catch up is important.

    K2.6 Qwen3.5-0.8B Mac inference optimization case
  • Laguna-XS.2 by poolside: Poolside AI has released its first public coding-focused models, including the open-weight XS.2. Its size (33B-A3B) makes it attractive for local use, with performance on par with other models in that size range. The accompanying blog post is worth a read, as is the deep dive into reward hacking during coding evaluations.

  • DeepSeek-V4-Flash by deepseek-ai: DeepSeek has finally released its successor to the V3 series, which it kept updating for months. It comes in two sizes: Pro, which is a 1.6T-A49B MoE, and Flash, a 284B-13B model. Based on others’ experience, the latter model seems to be the real star of the show, as its performance is relatively strong, while Pro seems to underdeliver relative to its size. The tech report goes into great detail, including the architectural changes used to achieve better and cheaper long-context performance.

Models

General Purpose

  • Qwen3.6-35B-A3B by Qwen: An update to the Qwen 3.5 series targeting one of the most widely used sizes.

  • LFM2.5-350M by LiquidAI: With 28T tokens for 350M parameters, this model might be the most overtrained model out there.

  • Trinity-Large-Thinking by arcee-ai: The reasoning version of Trinity, one of the best Western open models. It has topped the OpenRouter charts for a while and can power agentic applications such as OpenClaw.

  • GLM-5.1 by zai-org: An update to GLM-5, improving scores across the board. The focus for this update is on long-horizon tasks.

Read more

  •  

Latest open artifacts (#20): New orgs! New types of models! With Nemotron Super, Sarvam, Cohere Transcribe, & others

This Artifacts Log post is unusual in how many diverse, quirky models there are across use-cases and modalities. Normally these model roundups are dominated by big models from the likes of Qwen, DeepSeek, Kimi, etc. There are models for all sorts of different use-cases in this post, from optical character recognition (OCR), RAG search, audio transcription, computer-use, code-editing, math theorem proving, and more. The artifacts covered this month also come from a much broader list of open model builders.

This gives us a lot of hope for the future of open models, where we see the need for domain-specific, cheap models as being crucial tools to complement the strongest, closed agents. When the top few models get the headlines, this vast, industry-scale tinkering can easily be forgotten. Reading this post gives a technically grounded, broad coverage of the many directions the industry is pushing specific models for. Expect more like this!

Share

To encourage people to take a look at the diversity of models in this issue, the core part of the update is not paywalled. An otherwise quiet month at the top end of open models really delivered.

Artifacts Log

Our Picks

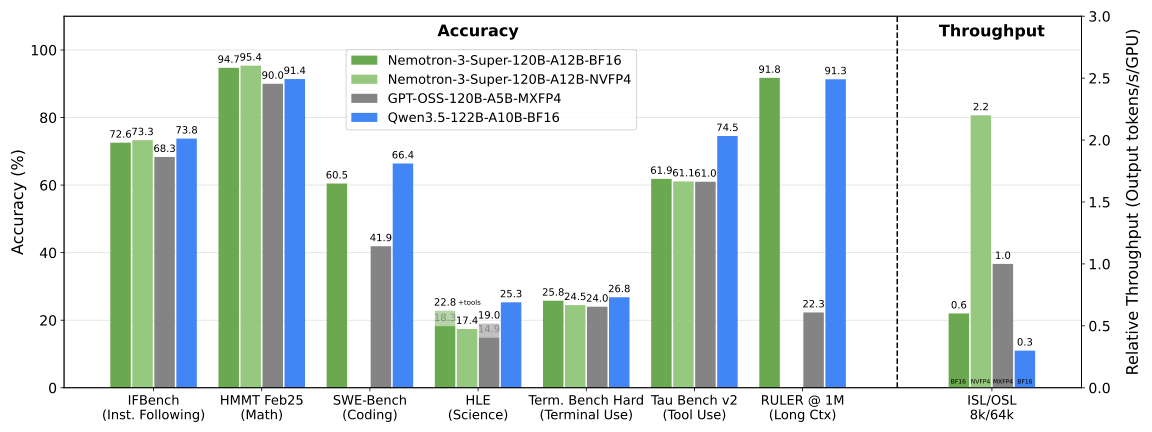
  • NVIDIA-Nemotron-3-Super-120B-A12B-NVFP4 by nvidia: The long-awaited mid-sized model from NVIDIA is finally here: 120B total params with 12B active, a 1M context window, and support for multiple popular languages. Furthermore, the model is based on LatentMoE and uses NVFP4 during pre-training, which is a first for open models. Like other things from NVIDIA, it comes with an in-depth tech report plus pre-training and post-training datasets, with the vast majority of the data being openly released.

  • cohere-transcribe-03-2026 by CohereLabs: A speech-to-text model by Cohere based on the conformer architecture, similar to NVIDIA’s Parakeet. It features 14 different languages, including some AIPAC languages and Arabic. Performance-wise, Cohere claims it beats similarly sized open and closed models. To top it all off: The model is released under Apache 2.0! Previous open models by Cohere were released under a non-commercial license.

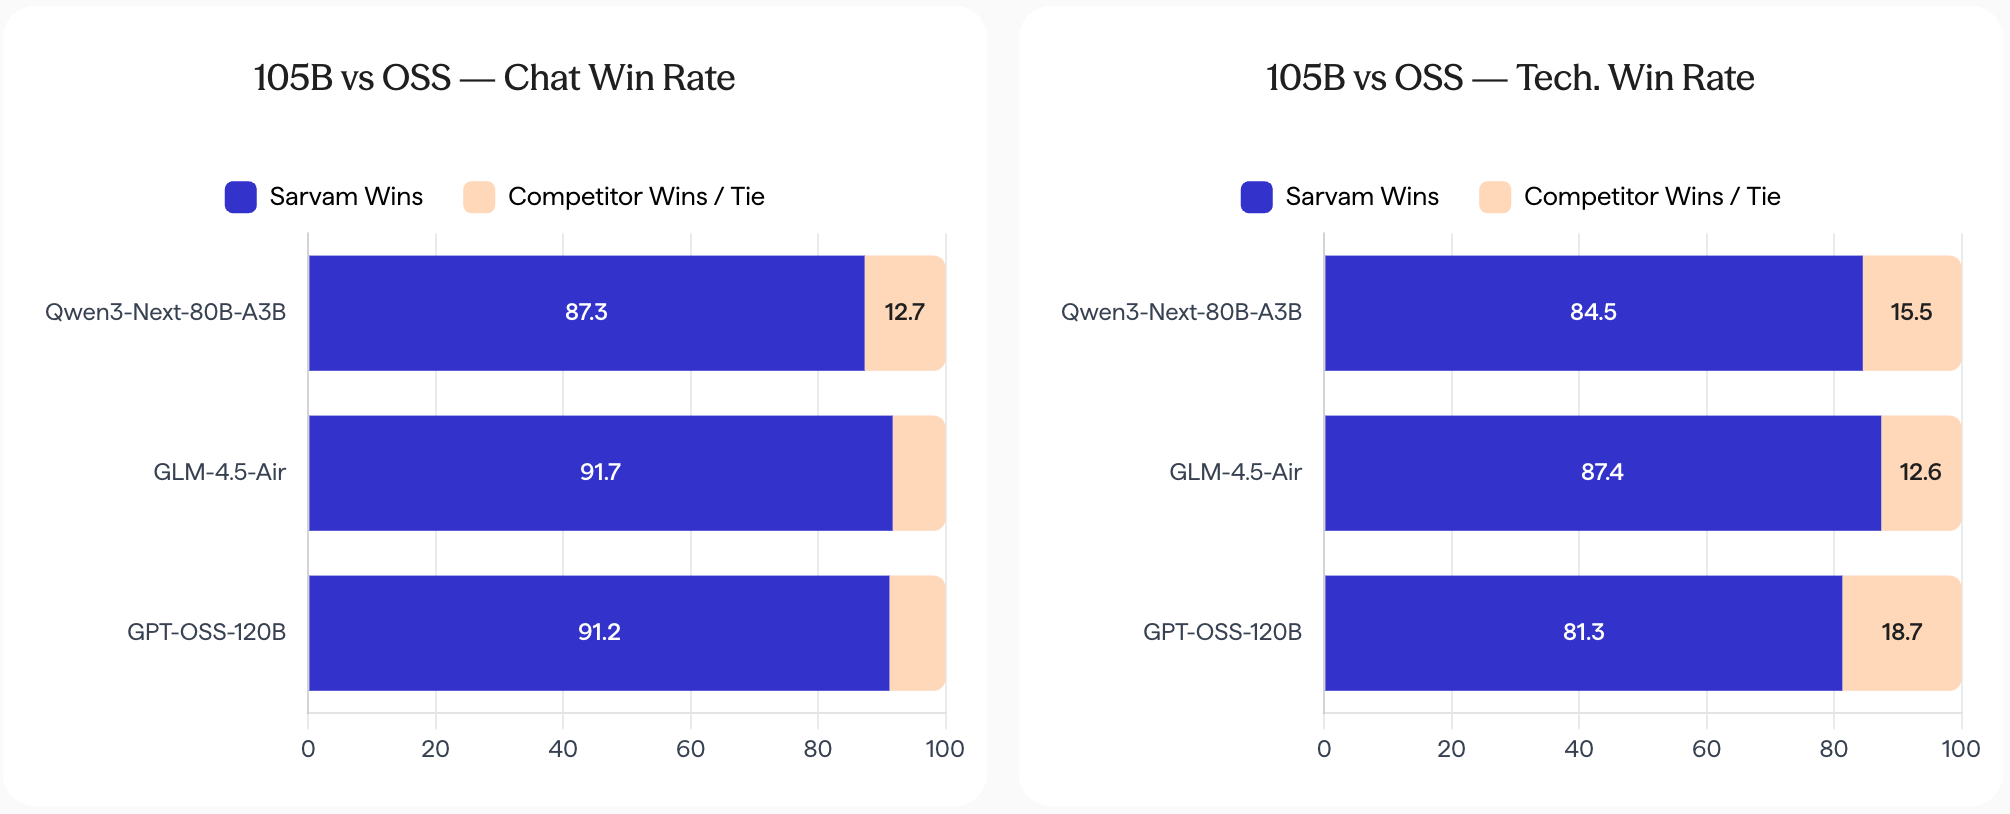
  • sarvam-105b by sarvamai: The Indian startup Sarvam, which trained open models in the past, has scaled up everything for its new flagship models in terms of dataset size (12-16T tokens) and model size (30B-A2B, 105B-10A). As a result, they come close to or even surpass a lot of open models with similar sizes. The release also shows why sovereign AI is so important, something that few other countries have internalized yet: In comparison with SOTA open models, the Sarvam models are vastly more preferred in Indic languages.

  • Mistral-Small-4-119B-2603 by mistralai: A 119B-A7B model by Mistral, combining their previous model generations into one as a hybrid reasoning model with coding abilities.

  • zeta-2 by zed-industries: The open source code editor Zed has released their edit prediction model openly in the past, which we featured a year ago. While the previous version was based on open data, the new version, based on Seed-Coder-8B, is trained on open source code by users who explicitly opted into data collection.

Models

General Purpose

  • gpt-oss-puzzle-88B by nvidia: A pruned expert version of GPT OSS 120B. It also replaces some global attention layers with window attention. Puzzle is “a post-training neural architecture search (NAS) framework, with the goal of significantly improving inference efficiency for reasoning-heavy workloads while maintaining or improving accuracy across reasoning budgets.”

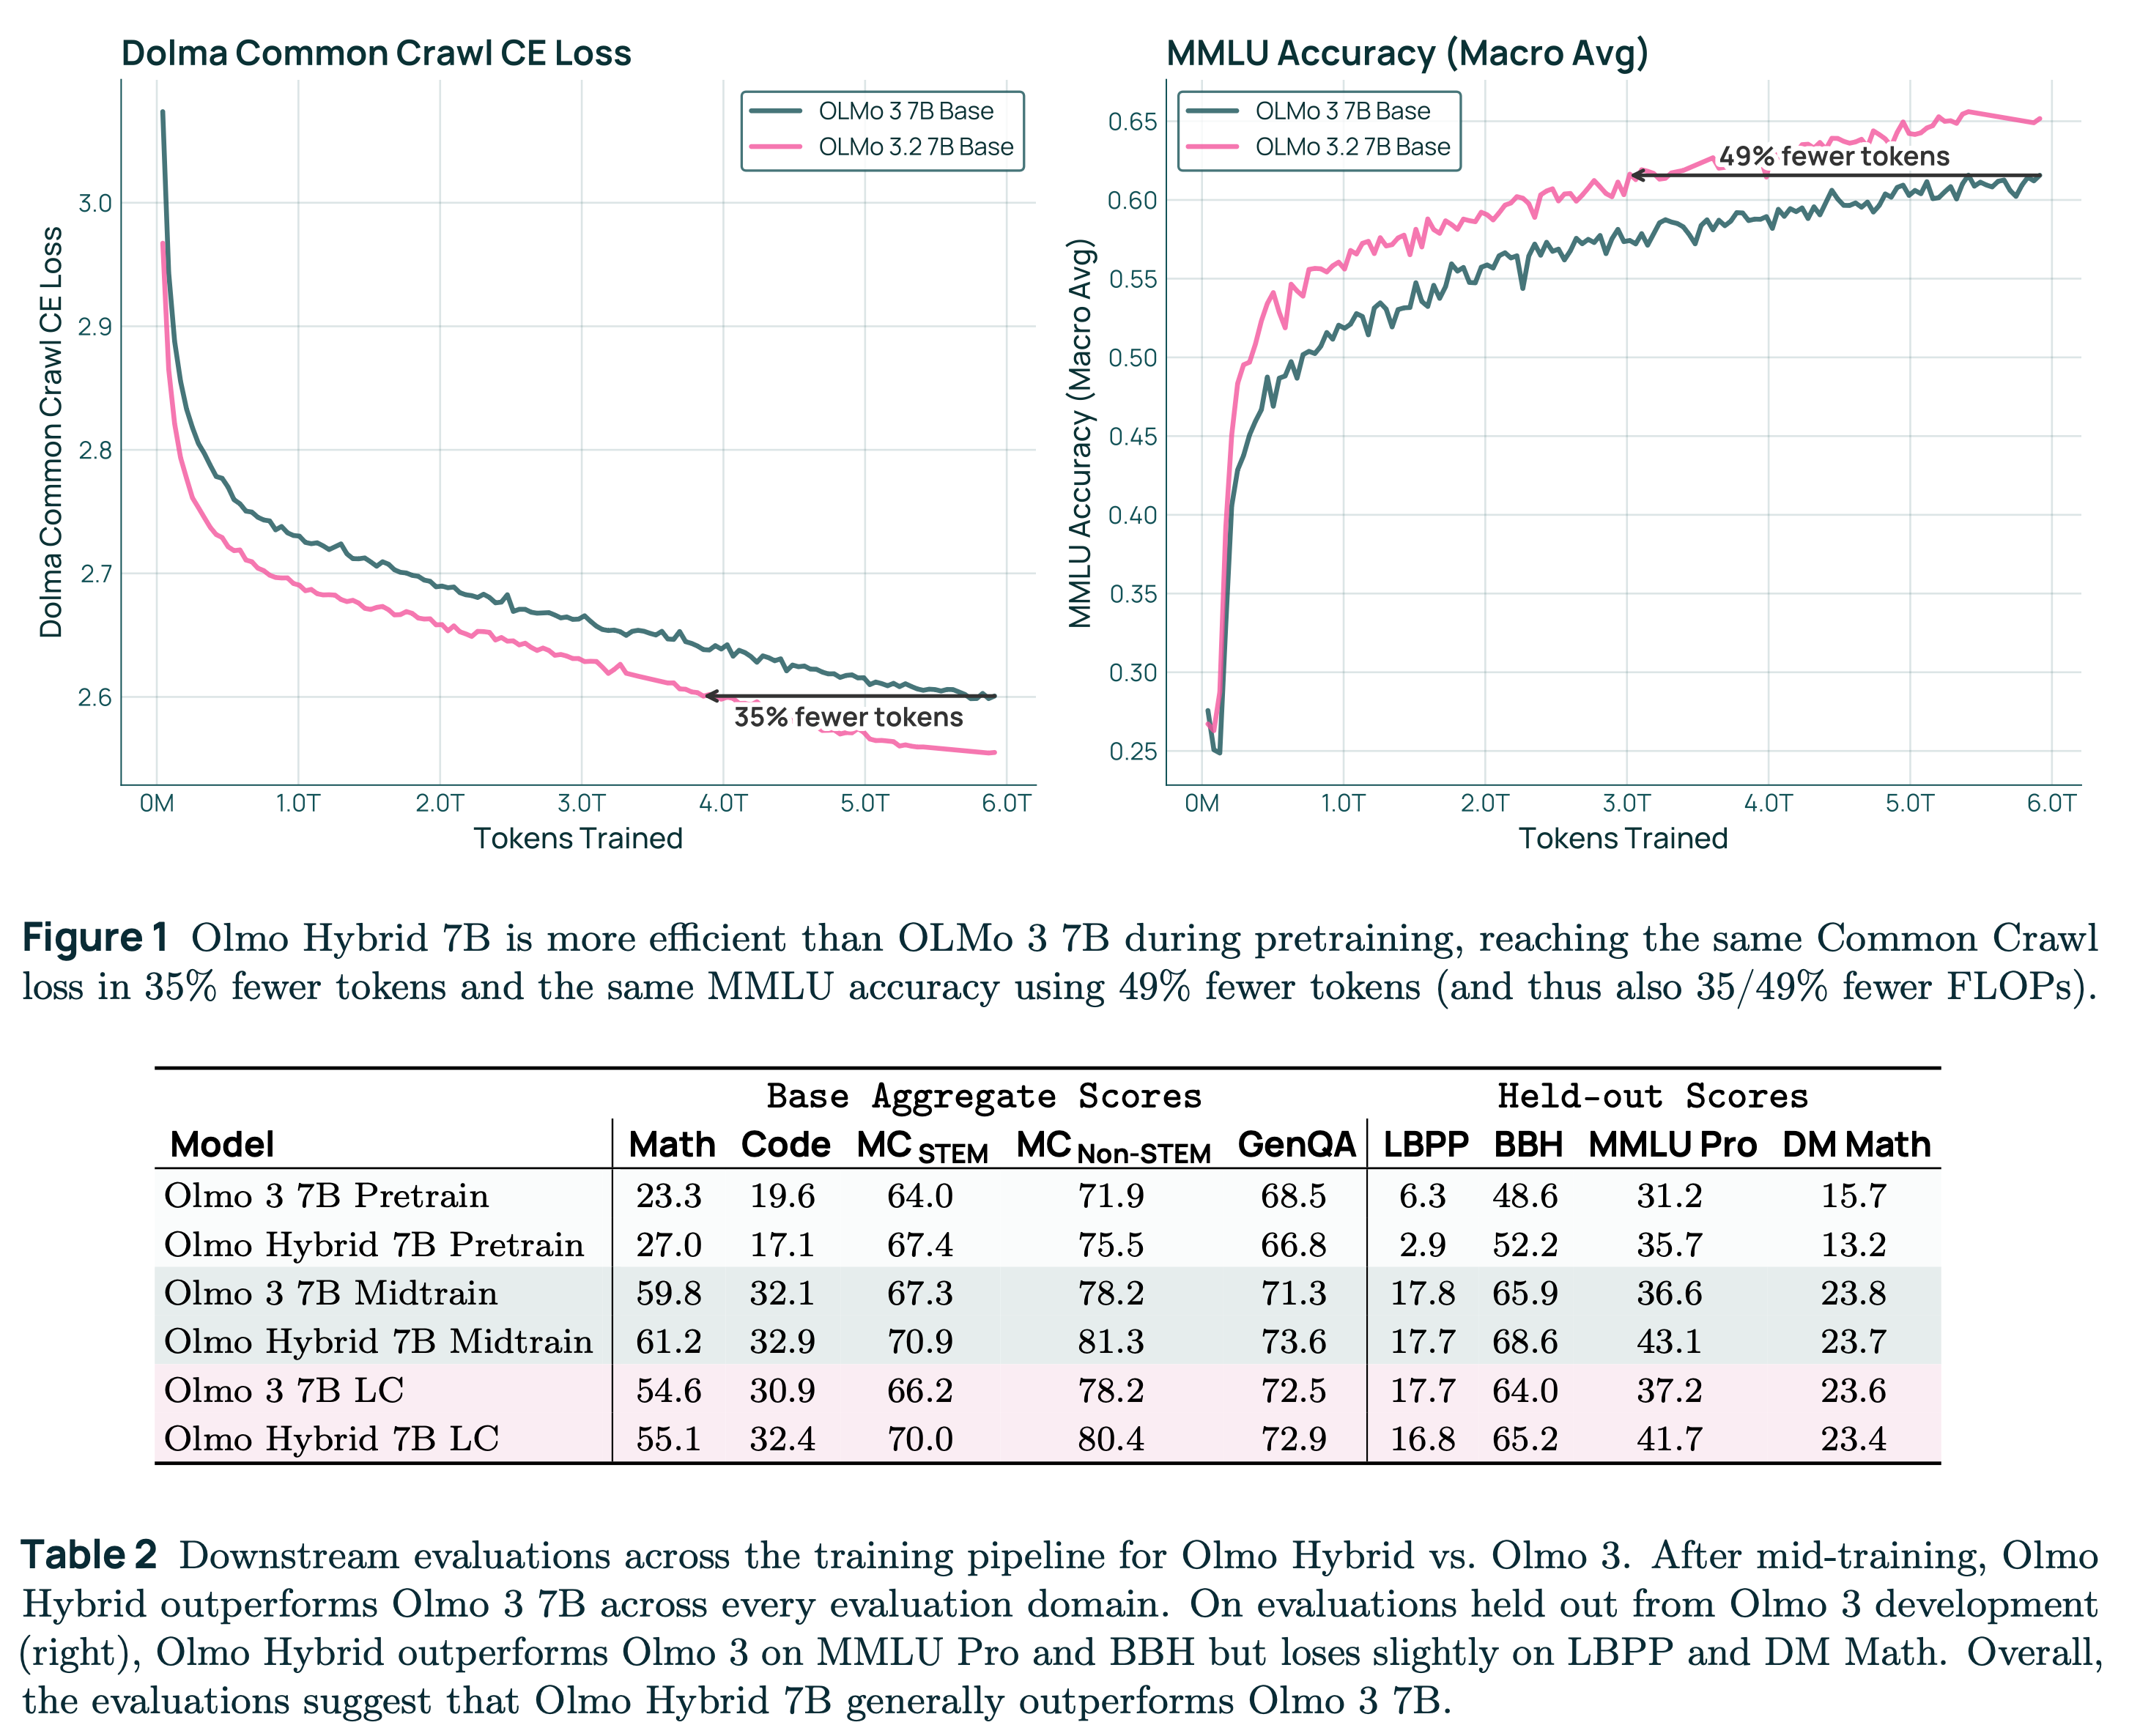
  • Olmo-Hybrid-7B by allenai: A hybrid attention + GDN (gated DeltaNet) model. See our blog post for more insights about the architecture and its challenges.

  • NVIDIA-Nemotron-3-Nano-4B-BF16 by nvidia: A compressed version of NVIDIA-Nemotron-Nano-9B-v2, which itself is a compressed version of NVIDIA-Nemotron-Nano-12B-v2. Nvidia has been pushing this direction more than anyone else with open models.

Multimodal

Special Purpose

RAG

  • Qianfan-OCR by baidu: There have been a lot of great OCR models lately. This one is from Baidu and is licensed under Apache 2.0.

  • chandra-ocr-2 by datalab-to: An update to the Chandra OCR model, released under a restrictive license.

  • Reason-ModernColBERT by lightonai: A SOTA retrieval model released under a non-commercial license. However, there is also code to re-generate the data, allowing the training of a commercially viable version.

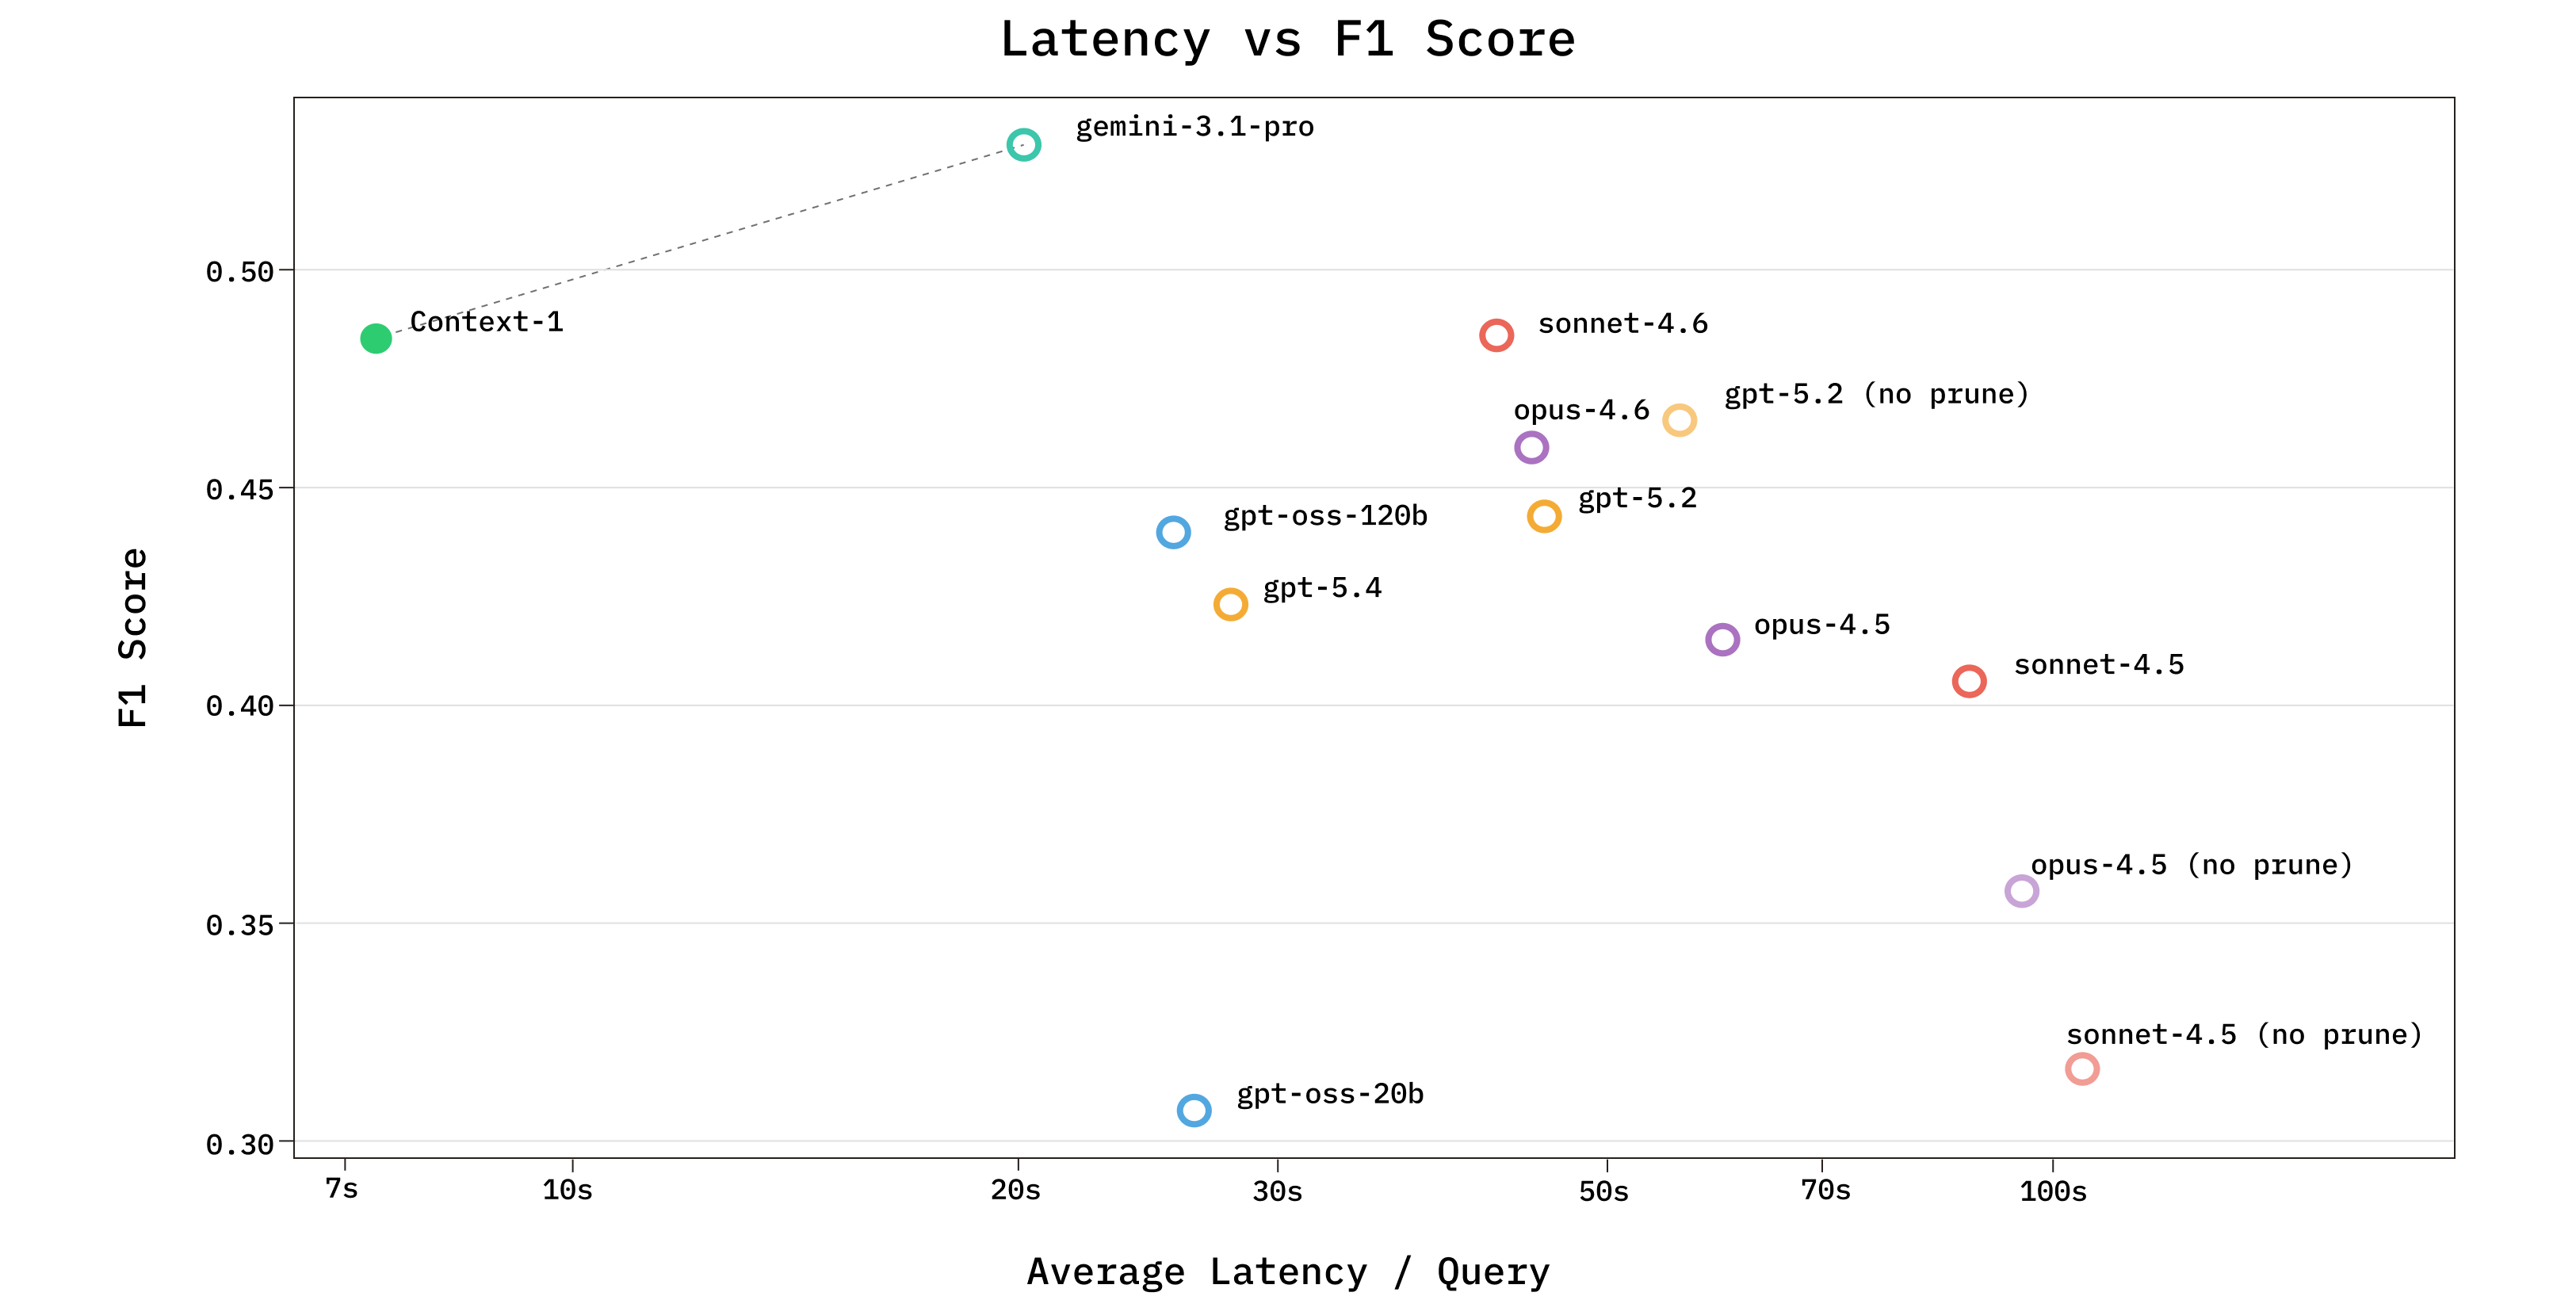
  • context-1 by chromadb: A fine-tuned version of GPT-OSS for agentic search with an in-depth tech report. It also marks the debut of Chroma into the open model space. Trained with Thinking Machine’s Tinker.

    Chroma Context-1: Training a Self-Editing Search Agent
  • dots.mocr by rednote-hilab: The beloved dots.ocr model has been updated and supports SVG outputs. However, on top of the general MIT license, the model comes with additional usage restrictions, just like its predecessor.

Read more

  •  

Latest open artifacts (#19): Qwen 3.5, GLM 5, MiniMax 2.5 — Chinese labs' latest push of the frontier

It’s been a busy month at the top end of open-weights AI — with new flagship models from all of Qwen, MiniMax, Z.ai, Ant Ling, and StepFun. Still, all eyes are on DeepSeek V4’s pending release, which rumors continue to accelerate towards. Outside of the large, frontier models, this issue is a bit lighter on the long-tail of niche modalities and model sizes.

Share

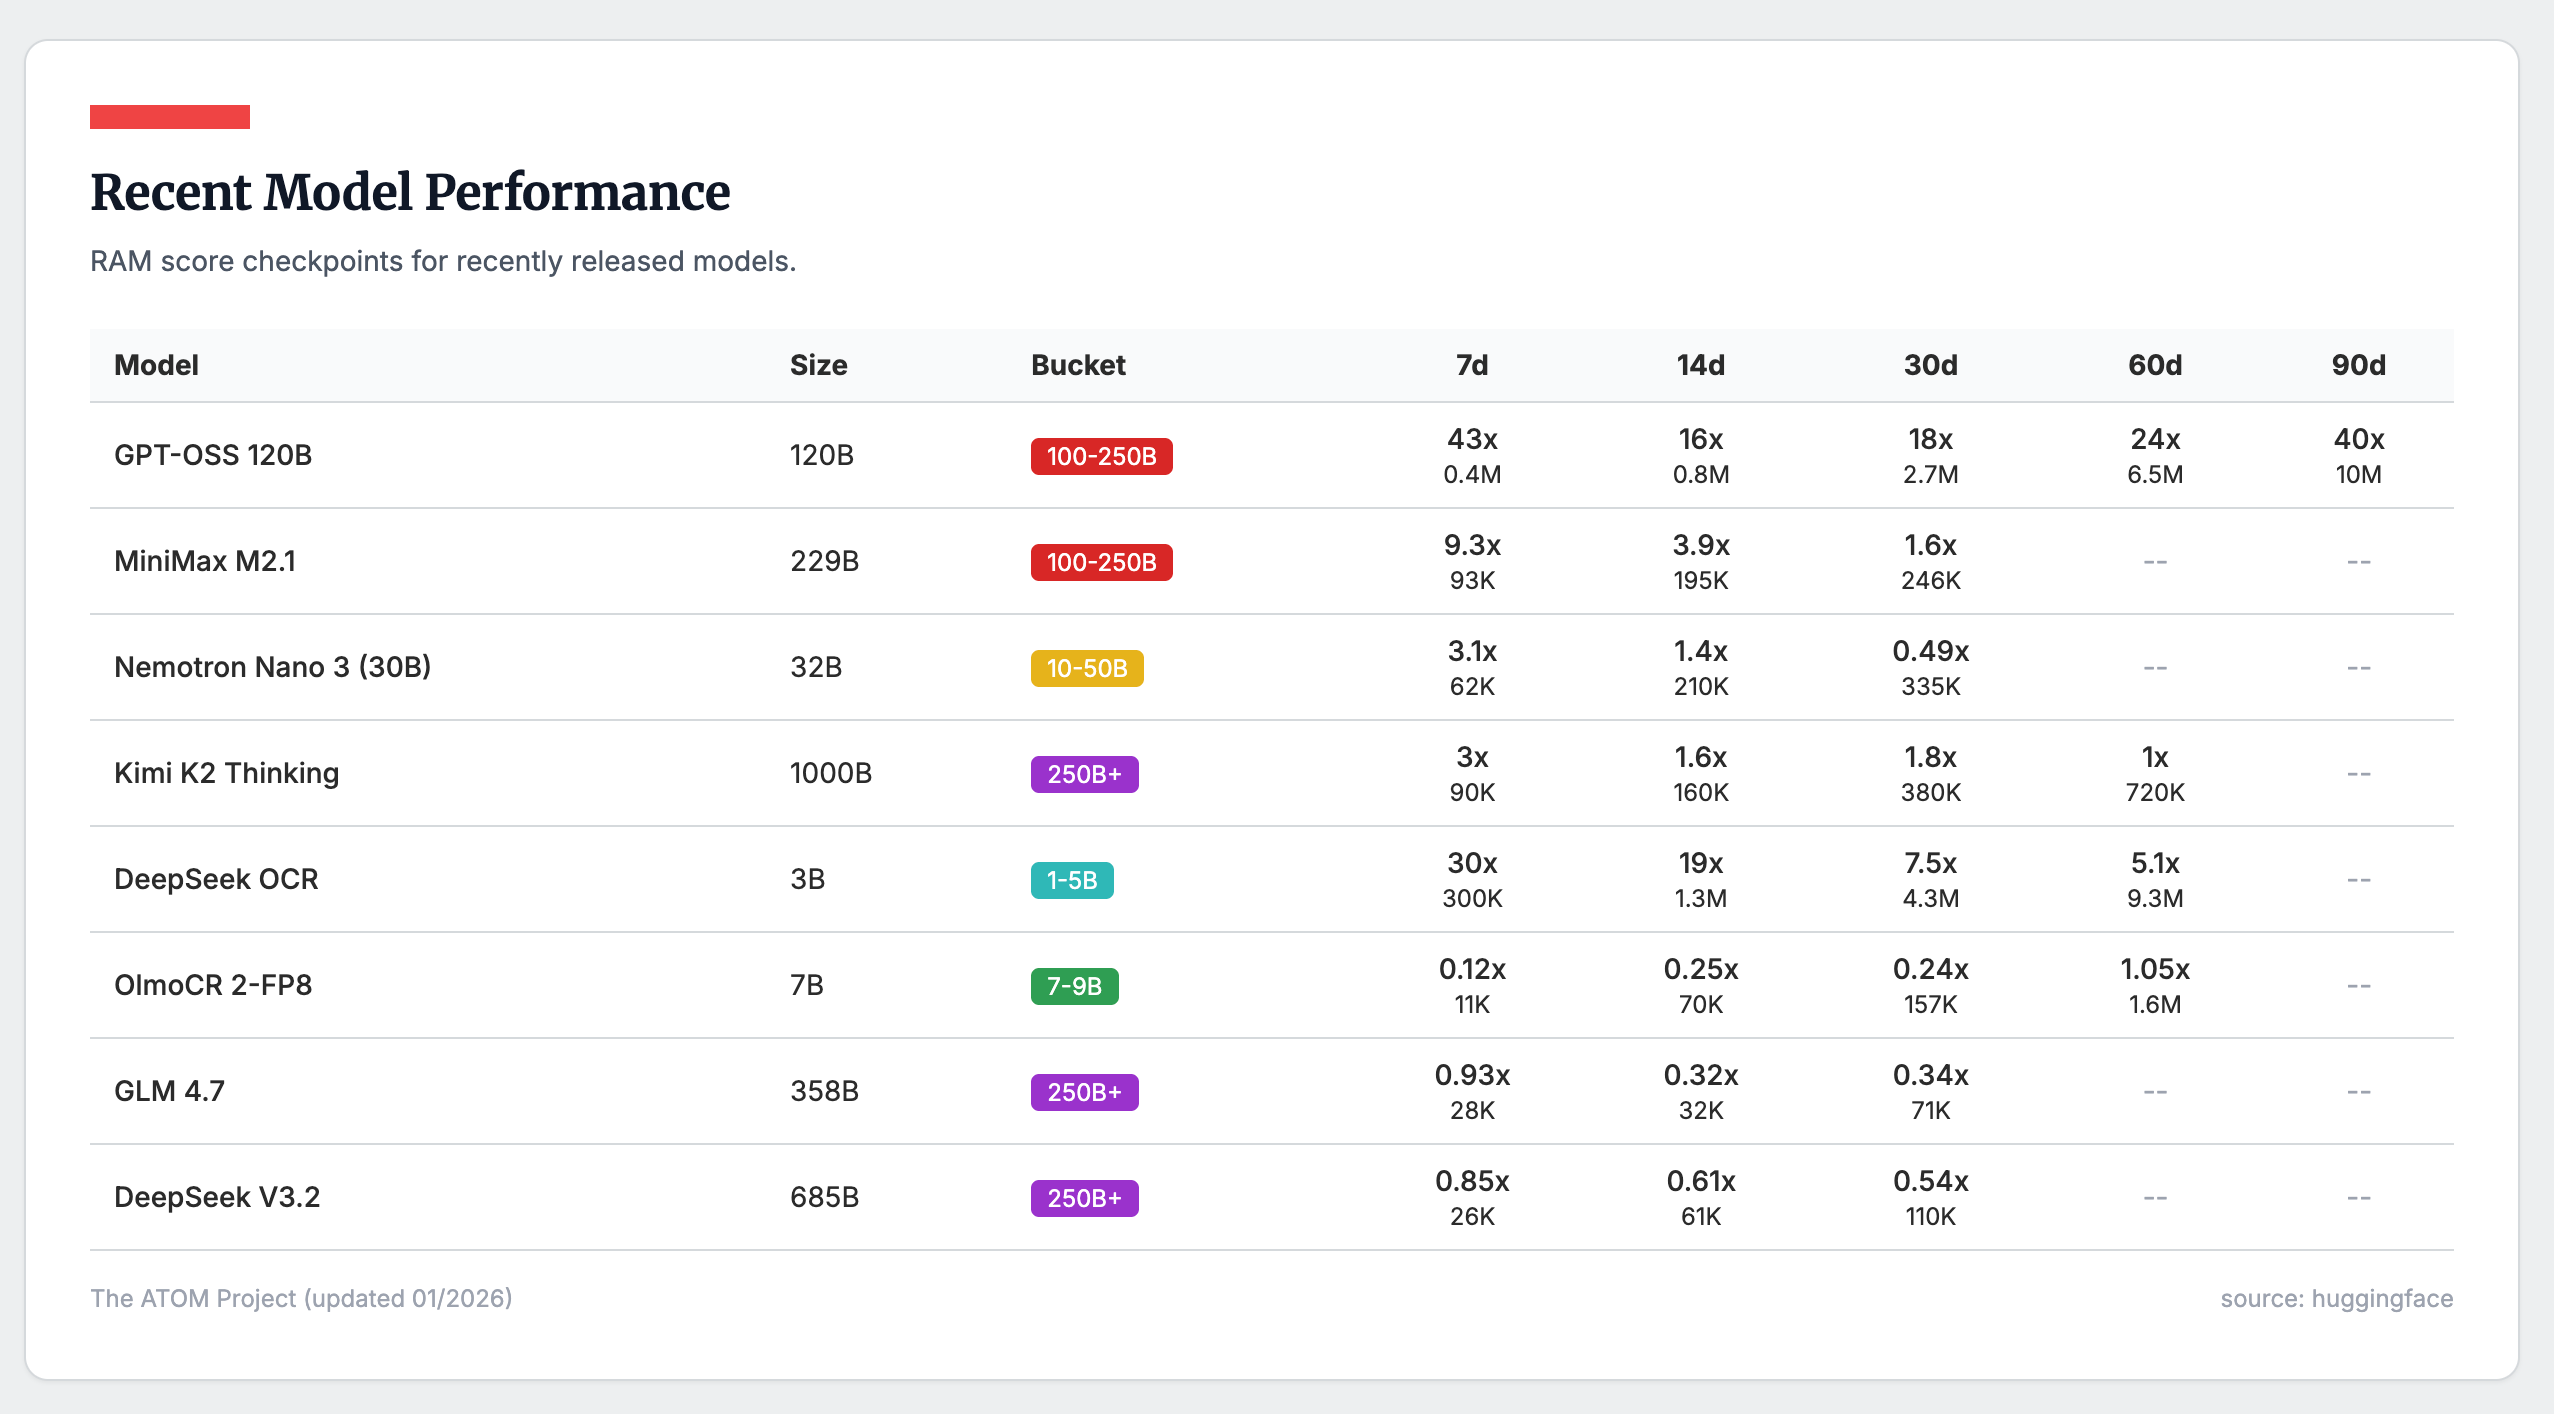
With all these new releases, we’re tracking them with our new Relative Adoption Metrics (RAM), a measurement tool that normalizes model downloads relative to peer models in their size class. This has already been an extremely useful tool for us, highlighting underrated models like GPT-OSS, which is literally off the charts in how downloaded it is — the most popular American open-weights model since Llama 3.1. A RAM score >1 means the model is on track to be a top 10 all-time downloaded model in its size class. We’re particularly interested to see how the early adoption of the smaller Qwen 3.5 dense models will go relative to Qwen 3 — balancing Qwen’s ever growing brand with a trickier, hybrid model architecture that can push the limits of some open-source tools.

A summary of the RAM scores for some of the popular models released late in 2025 is below, highlighting Kimi K2 Thinking and some OCR models as clear winners. DeepSeek V3.2, and their other recent large models, have wildly underperformed DeepSeek’s earlier releases in 2025.

The time here is days since release.

Artifacts Log

Our Picks

  • Qwen3.5-397B-A17B by Qwen: The long-awaited update to Qwen is finally here. It comes in various sizes from 0.8B to 27B (dense) and 35B-A3B to 397B-A17B (MoE), some of them even with base models. All of them are multi-modal, use reasoning by default and are based on the Qwen-Next architecture with GDN layers.

    We tested these models over the last few days, and they are a clear upgrade over the previous version: There are a lot of substantial improvements across the board, making them perfect workhorses for a wide range of tasks.
    Their style and instruction-following have improved, and the models are even better at multilingual tasks, covering more languages.

    However, at least the small models (still) tend to overthink. You can turn off reasoning by disabling it in the chat template.

    Benchmark Results
  • Step-3.5-Flash by stepfun-ai: StepFun really stepped up its game (no pun intended), releasing a 196B-A11B MoE with strong metrics across the board. It is especially strong in math benchmarks, beating out models that are several times larger than it.

  • GLM-5 by zai-org: A 744B-A40B release from the Zhipu team, which has resulted in such a big increase in demand that they raised prices for their coding plan. It also comes with an accompanying tech report.

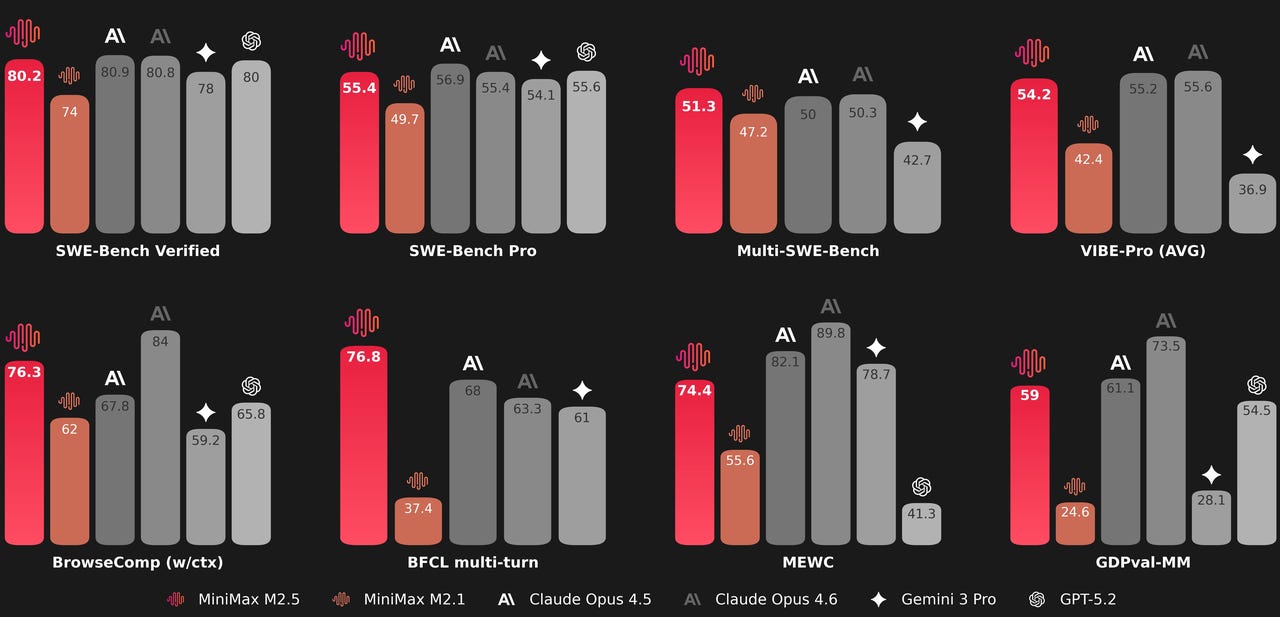
  • MiniMax-M2.5 by MiniMaxAI: Despite the relatively small size, Minimax-M2.5 can rival models such as GLM-5 and Kimi K2.5 and has quickly become one of the favorites of the community.

  • OpenThinker-Agent-v1 by open-thoughts: OpenThinkers, known for their open reasoning releases (such as OpenThoughts 3) are now tackling agentic reasoning. Their initial release includes SFT and RL data, as well as a “lite” version of terminal-based tasks to evaluate smaller models.

The subtle differences in architecture of these models are covered in detail in the similar, more technically focused, round-up from — it’s a good complement if you’re looking to go deeper:

Models

General Purpose

  • Tri-21B-Think by trillionlabs: The Korean Trillion Labs is a repeated guest at the Artifacts series. This time, they are releasing a 21B reasoning model with support for English, Korean and Japanese.

  • MiniCPM-SALA by openbmb: An English and Chinese 8B model with sparse attention, supporting a 1M context window.

Read more

  •  
❌