
❌

Reading view

🔬 An Oscar, Two Asteroids, and the Algorithm in Your sklearn: John Platt on AI for Science

How often do you get to talk to a guest who has both an Academy Award and who invented textbook machine learning algorithms? John Platt has an Oscar, two textbook algorithms, two named asteroids, and an Erdos-Bacon number of 6. This was easily the most fun bio of all the guests we’ve read to date. And the result was an epic and fun chat covering Google’s Empirical Research Assistance (ERA), how AI can help battle climate change, and tons of great stories about the co-evolution of science and AI.

John’s colleague Dave Bacon likes to tease John that his career has been defined by being twenty years early to the next big thing. This may be convolutional neural networks (some credit him with coining the term), fusion research, quantum computing. John and Google have been working on solving some of humanity’s hardest problems with AI and computation for well over a decade now. Recently John and his team set their sights on using AI to solve any scientific problem that can be written down as a score.

Google’s Empirical Research Assistance (ERA)

John’s team has taken on many hard scientific problems over the years. In solving these, they noticed a pattern, many scientific problems can be reduced to what John calls a “scoreable task”. Once you have the score function, the goal is to find some code that maximizes the score. The hard part is in formulating the score, but once you have the score finding the maximizer can still be quite a lot of effort.

John’s team set out to automate solutions to this general problem. This came out of the idea of an “auto-Kaggle” AI, which can solve any Kaggle problem you can throw at it. Kaggle is owned by Google, so all the data was ready and easily available to them!

The result is Google’s Empirical Research Assistance or ERA (paper, github, blog).1 ERA is surprisingly simple conceptually. Gemini (or your LLM of choice) keeps a running tree of past experiments (notebooks) and where they’re going. It’s a close cousin of Monte Carlo Tree Search: at each iteration the Upper Confidence Bound rule picks which notebooks are most promising to mutate. This is optimistic, not greedy, so sometimes even the fifth-best notebook gets chosen. Gemini then proposes mutations for each one, about ten at a time. The history of each branch is shared, so different leaves can learn from each other.

“It’s almost like having a hyper-eager grad student who doesn’t sleep.”

Evolutionary algorithms have been around since the 70s, but this works because Gemini actually knows where to look! What’s even more interesting is that there was a step change between Gemini 2.0 and 2.5, and this went from just not working to working great.

ERA is so powerful that John and his team solved many outstanding problems with it, resulting in at least ten papers. Some of these were climate change related, which we talk about in the next section.

So, we had to ask: if you have an optimization god how do you avoid fooling yourself? John’s answer is that ERA provides predictive models. It’s up to the scientist to make sure they’re truly descriptive. Some of this just involves good old-fashioned careful machine learning science. “It’s a power tool. It can slice your fingers off.” This led to some fun discussion about Kaggle competitions, and the fun ways people can overfit to datasets without meaningfully solving the problem you actually care about: Google’s contrail-detection competition was won by entrants who noticed a half-pixel error in the labels (is the origin at the corner of the pixel or the center?) and this turned out to be a part of the winning special sauce. Great for winning $15,000, not so helpful if you actually want to solve contrails.

“People themselves will act like these LLMs and try to reward hack. It goes back to Goodhart’s law: any metric that becomes a target is no longer good as a metric.”

His advice for where to start instead?

“Always just fit linear regression. Just do it. Just do it. Just do it. Or SVM.”

Tackling Climate Change with AI

John and his team have worked extensively to mitigate the effects of climate change. We talked about several of their initiatives.

Perhaps the most interesting result we talked about was reducing the effects of condensation trails (contrails) from airplanes. Those little streaks you see running behind planes somehow account for 1% of all human-induced global warming?!? Some of these trails of ice crystals can hang out for days. These crystals are black in the infrared, acting like a thermal blanket that traps heat day and night.

It’s easy to understand what’s happening here, a region of atmosphere becomes “ice supersaturated”,2 and a tiny bit of exhaust seeds water vapor that instantly crystallizes. The scale here is astounding, with a single gram of exhaust resulting in ten kilograms of ice crystals.

The solution to all of this is quite simple, in principle! We know what parts of the atmosphere are most likely for the trails to form. Just have the planes drop a flight level or two. Problem solved, right? Well, the hard part is accounting for how much warming was prevented. This is a counterfactual problem, parts of which stumped John’s team for over two years. They had a working model for the heat-trapping half, but not for the reflected sunlight. ERA was able to find a simple model with some confounders they hadn’t considered. Cracked it!

Modeling climate generally is a hard problem. Climate is best thought of an attractor of many different possible weather outcomes.3 This makes it much harder to model.

“Weather is where you are on the attractor, and climate is the statistics of the attractor. The problem with climate is that we’re altering it. The attractor itself is changing, it’s moving.”

John and his team have worked on treating both the symptoms and the disease of climate change, with several other works in the area. Another fun example we briefly cover is FireSat, a way of using a constellation of satellites to rapidly identify fires before they grow too big to put out. For anyone living in California, you understand the problem. In dry years a small fire can result in hundreds of thousands of acres. If you could find this fire when it’s the size of a room, it could be put out. By the time it hits an acre we have a much harder problem.

Where is this all going? Looking forward by looking back

By now it should be clear John has an incredible and unique view over the intersection of science, computation, and AI. John talked about a class on physics of computation4 he took with Richard Feynman back in 1982. This was when quantum computing was an ill-defined concept with no theory or experimental backing. John recalls every Tuesday was a guest lecture, and every Thursday was Feynman explaining why the Tuesday guest was wrong. John also recalls doing science back when there was essentially no compute, a million operations per second was cutting edge.

What is John’s recommendation: the most important skill is developing deep domain expertise. There’s no other way to develop taste than to tackle hard problems. One surprising part of this is that John recommends spending time doing things the old fashioned way. Play with tools, and just implement things yourself.

“You could drive up the mountain, or you could hike up the mountain, and maybe it’s okay, even fun, to occasionally hike.”

Summing it up, John’s message to the audience is that there will still be a place for scientists, and that if anything it will just open up more opportunities for “the creative stuff, the rigorous stuff, the philosophy stuff.” But don’t forget to spend time doing the grunt work.

“There just seems to be this strong impetus in the world to optimize and squeeze everything out. But you do lose something when you hyper-optimize. It’s overfit.”

And whatever tools you end up using, John’s advice is the same one Feynman gave him forty years ago: you must not fool yourself, and you are the easiest person to fool.

We had a great time talking with John. We hope you enjoy!

Also in this episode

  • Fusion is three years away, not thirty, if you ask John. And why the Lawson criterion means every fusion approach has an Achilles heel.

  • Why superconducting qubits are still finicky.

  • The asteroid he named after his mom, which turned out to have a moon.

  • The looming helium shortage nobody talks about.

  • How NeurIPS started as people crashing a private workshop at Snowbird, and why Hopfield networks are all you need.

  • Being Carver Mead’s sysadmin on a VAX with an 80 MB disk the size of a dishwasher.

  • Finding asteroids in 1985 with film, a stereoscope, and a letter to Brian Marsden. The Vera Rubin Observatory found 11,000 in six weeks.

  • The Feynman effect: total clarity in the room, none once you leave.

  • Quantum echoes, the NISQ era, and why he thinks quantum is neither thirty years away nor tomorrow.

  • A startup that wants to inject mercury into a fusion reactor and sell the transmuted gold. “It might not work.”

  • John’s 20% time rule for his own group: do stuff for learning, and you don’t even have to tell him what.

1

The ERA GitHub repo features an open source implementation that ran Gemini but can be used with any LLM. ERA is not currently available as a Google product.

2

“Ice-supersaturated” is about water vapor, not liquid water. Cold air can hold a given amount of vapor, and there are two different limits: the amount in equilibrium with liquid water, and the smaller amount in equilibrium with ice. Below freezing, a pocket of air can sit between those two limits. It has more vapor than ice can tolerate, but not enough to condense into droplets, and ice won’t form directly from vapor without a seed. So the vapor just hangs there, metastable, sometimes for days, until something seeds it.

3

We recently covered the weather-climate crossover in our episode with Anima Anandkumar, and we plan on covering both weather and climate more in future episodes.

4

This was really about quantum computing, but in the early days before anyone really knew what this meant and it was just a vague idea Feynman and a few others were kicking around.
💾

  •  

🔬“We have foundation models for language, not for physics” — Anima Anandkumar, Bren Professor of Computing

A few years ago, Caltech Prof. and co-founder of Accelerated Understanding, Anima Anandkumar set out to develop the first open-source weather model with AI. Talking to experts in the field, she was met with skepticism. Weather is chaotic, physics simulations are hard, have been developed for decades, and require supercomputers, the data just isn’t there. Despite reservations, Anima went forth and built. Within a year her team had developed FourCastNet, a predictive model that is competitive with the best physics-based simulations available. Thanks to Anima, and her follow up work, anyone can now predict weather accurately over a short timescale using consumer grade GPUs.1

In the fifteen or so science episodes we’ve released on Latent.Space, we’ve covered atoms, molecules, materials, biology, and math. Anima is a pioneer in studying physical systems that are continuous. Weather, fusion, and fluid or heat flow are huge areas of science that are extremely difficult to model: they are large, chaotic, and fundamentally multi-scale. This is a field the AI community has somewhat neglected, but one we expect will grow fast. We plan to cover large physical systems more in coming episodes.

One thing you can glean from Anima’s work is that this area of AI resists the scaling ideas that have permeated the rest of the field. The data isn’t there: open source datasets in many of these domains are limited to tens or hundreds of thousands of examples, far from what token-hungry transformers need. Even worse, the resolution that physics demands pushes the context length into the hundreds of billions, so you can’t just throw more tokens at the problem. That isn’t a ceiling though, just a slower road: progress here comes from building in structure and inductive biases. Sorry for all you bitter-lesson-pilled language modelers.

“If each dimension is even a few hundred grid points, which is where industrial scale starts... we’re talking hundreds of billions to even a trillion context length. So forget ever having a transformer for anything of this scale, all of the world’s compute will not be enough.”

The math underneath

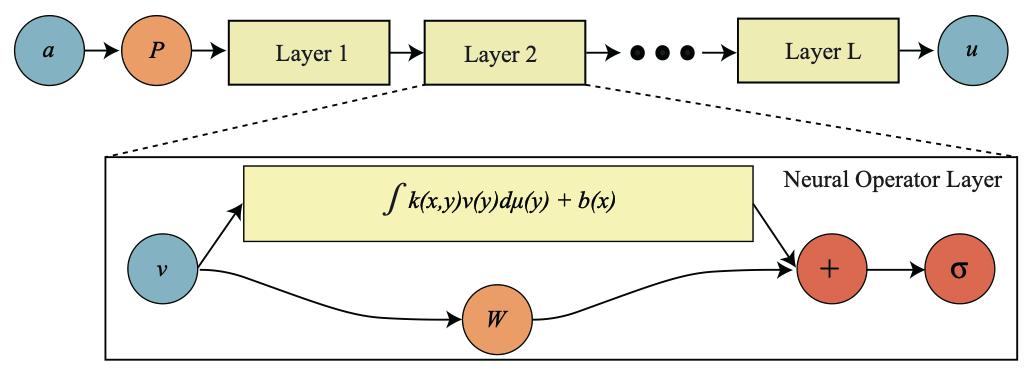
To tackle these systems, Anima pioneered a technique known as Neural Operators, one of the most beautiful theoretical developments in AI of the last decade.2 These allow you to combine data and physical laws to enable multi-scale inputs and outputs. We’re no longer modeling a grid, we’re modeling a function that evolves over many scales. This allows Anima and crew to build in priors based upon physical intuition.

Neural Operators What if we created a neural network where every layer was itself a function?

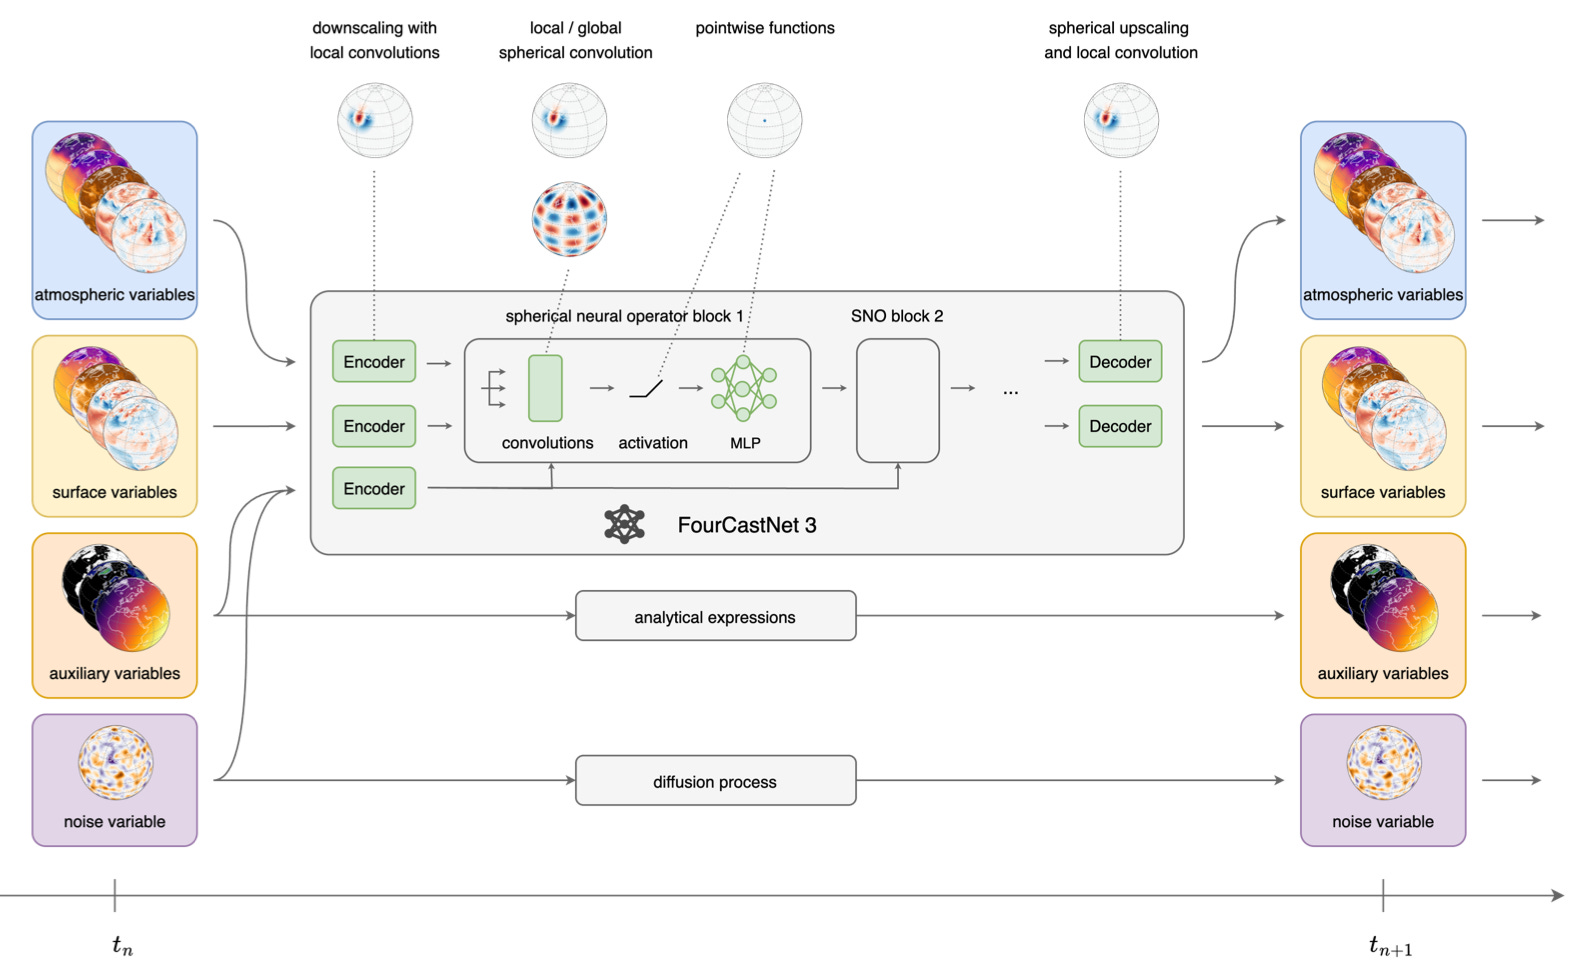
To see how physical priors are still helpful for AI modeling, let’s revisit the problem of weather forecasting on a global scale. The earth is a sphere, which meant that accurate modeling involved using the right basis set —3 the Spherical Harmonics. Run a weather model on a grid and it blows up fast. Move to the natural basis for the problem and it stays stable far longer, long enough to roll out months ahead instead of days. Anima’s Fourier Neural Operator learns directly in this frequency domain, and its spherical variant powers FourCastNet 3, which models the weather across the whole globe and keeps running stably far into the future.

FourCastNet 3 The earth is (almost) a sphere — bake the spherical harmonics into your network!

The physical world is forgiving

Anima explored Neural Operators across other physical domains too, and one striking observation is that the physical world is more forgiving than you’d expect. In fusion, a few thousand samples are enough to predict plasma disruptions, and to do it a million times faster than traditional simulation.

None of this is a rejection of scale, it is a different route to it. Anima ultimately still wants to build a “foundation model for physics”, a model that spans many phenomena and does both simulation and design. You get there by building in the structure the physical world already has, not by waiting for data that will never exist. It is a start, and it will take longer than the token-driven parts of AI, because for the physical world tokens were never the answer.

“All of the things that work with deep learning, let’s take them, but make them a bit more principled.”

Weather is only the beginning

Neural operators and weather modeling were a personal passion of mine, so we’ve spent much of this blog and the episode exploring this work. Anima has done so much more! In the episode, we cover several other recent developments from Anima:

  • Anima has a series of works integrating neural networks and automated proof techniques. We talk about TorchLean, a new framework that lets you write PyTorch-style networks inside the proof assistant Lean and formally verify them. This is a major step for proving bounds on neural networks, something that would be really important for someone trying to, e.g., add a neural network as part of the control loop to their fusion reactor!

  • Anima was recently appointed to the United Nations Scientific Advisory Board! We talk with her about her goals of bringing evidence-based viewpoints to policy, and how AI in scientific domains can improve people’s lives all over the world.

This episode has something for every AI or science nerd! Elegant math? ✅ Old school harmonic analysis? ✅ Fundamental developments in modern AI? ✅ Practical ways of modeling the physical world? ✅

Give it a watch!

1

Work that has blossomed into an entire field of AI forecasting, a theme we will cover more on the podcast in coming months.

2

This is an elegant and very technically deep paper. Excellent nerd snipe if you have a big block of time to study!

3

All emdashes were human generated.

💾

  •  

🔬 The Coolest Diffusion Research Isn't in LLMs — Evan Feinberg & Sergey Edunov, Genesis Molecular AI

This episode has a fun personal twist: There’s a counterfactual world where I was employee #1 at Genesis Molecular AI,1 the company behind today’s episode. A certain introduction happened a few weeks too late and I had already happily signed at Atomwise2, another ML-for-drug-discovery startup. Same problem, different company. I was certain ML was going to transform small molecule drug discovery. Early results were underwhelming. Useful at times, but nowhere near revolutionary. In the last year I’ve seen signs that ML is finally ready to deliver on my convictions from a decade ago. Genesis is one of the places that might have finally cracked this problem. I was super excited to come full circle and catch up with co-founder Evan Feinberg and CTO Sergey Edunov.

If you are at all interested in small molecule drug discovery, we think you will find this fascinating!

In our nearly two hour chat we cover:

  • What is small molecule drug discovery, and why is it hard

  • Structure prediction as a hotbed of innovation in AI algorithms

  • How advances in AI elsewhere have enabled stepwise improvements in predictive power

  • How the community benchmarks are essentially calling AI slop good enough

  • The Genesis flagship model (PEARL) can routinely hit a threshold that is necessary for real-world applications

  • New agentic workflows enabled by these highly accurate models

Read on for more, and also some personal thoughts on the future at the end.

The coolest diffusion research is happening at Genesis

Sergey Edunov came to Genesis from Meta where he led Llama 2 training and Llama 3 pretraining. Sergey was a former physicist who thought he was done with physics after many years of training LLMs. Then, he discovered Genesis, and was blown away with all the novel architecture work they’ve been developing.

It probably surprises no one that modern LLM research has not resulted in fundamentally novel or exciting updates in architectures since almost the advent of the transformer — the entire field is using variants on the same idea that came out in the original “Attention is all you need” paper. Sure, some were quite useful (mixture-of-experts in particular allowed for the massive model paradigm we’re at today), but there was very little conceptually exciting.

“We sort of had to wait for the right primitive to get created, and that turned out to be diffusion… Actually, some of the most innovative diffusion research that’s happening in our field is happening in 3D structure prediction right now.” — Evan Feinberg

The field of 3D structure prediction on the other hand has been a hotbed of research. Genesis’ recent model PEARL (Place Every Atom at the Right Location) is able to understand protein flexibility, and model not just where the ligand goes, but also make small adjustments of the protein so that the two fit better than either alone. The field knew this was missing for a long time, but it was really hard to model until now.

Agentic Discovery

What makes this problem so hard? As Sergey points out, there are 10^60 possible drug-like small molecules. You’ll never be able to search them all, and trying to find the good ones is something like finding a needle in a haystack — except everything except your needle is dangerous.

“There are 10 to the 60 drug-like small molecules in the universe… it’s like finding a needle in a haystack, where everything except your needle is very, very dangerous.” — Sergey Edunov

“Or finding hay in a needle stack might be a more apt analogy.” — Evan Feinberg

Trying to solve the multi-parameter optimization problem is even worse. What makes a strong binder and a molecule with good “ADMET Properties”3 are oftentimes at tension with each other. For example, a good binder is likely greasy, but a greasy molecule is likely insoluble so it won’t enter the bloodstream and get to where it needs to go!

Genesis’ advances in generative AI have now pushed them beyond the threshold where they believe agentic drug discovery loops are finally possible. We all remember the early days of LLMs. They were great chatbots but terrible agents, as small errors compounded rapidly into uselessness. As LLMs got better, the usefulness of agents rapidly improved. Evan and Sergey argue that their models at Genesis recently passed a similar threshold. Their internal agentic drug-discovery system (code named SAPPHIRE) can now iterate like a chemist: look at and reason about poses, form hypotheses, read literature, use internal tools, create candidates for the next iteration. Combining this with automated lab partnerships like the one Genesis has with Incyte, we’re rapidly approaching a time of drug discovery agents running 24/7 making/testing new molecules. Exciting times!

Benchmark crisis: Everyone’s favorite benchmark is slop

One surprising point that isn’t talked enough about: the academic field of “co-folding” has settled on a benchmark value of “2 Angstrom RMSD” as a metric for a “good pose”. Evan does not mince words: this threshold is just bad. Perhaps even deceptively bad. For many strong binders, there’s a very clear pose, one that you can even directly resolve in the PDB electron density! And yet, with a 2Å RMSD threshold, you can get the pose quite wrong in ways that might even mislead a medicinal chemist. For example, flip around an aromatic ring, and everything looks reasonable, but you’re no longer modeling the right interactions.

Evan makes the strong claim that 1Å RMSD is really the threshold necessary to ensure the core of the molecule is sitting where it needs to be, and models all interactions.

“If your model is sitting at 1.8, 1.9 Angstrom RMSD, that’s slop, most likely.” — Evan Feinberg

As a simple example, he points out hydrogen bonds which are responsible for many of the most important interactions in protein-ligand systems. Hydrogen bonds only have a 0.6Å range to be valid! Clearly if you’re accurately resolving all H-bonds, you generally have to be doing much better than the 2Å threshold.

This is clearly a hard-fought lesson for Evan and Genesis. In their opinion, the community is stuck on these benchmarks because academics developing methods were not users. Evan does see signs of life, with the use of new metrics such as lDDT for co-folding. Hopefully soon the community can agree that “1.8Å RMSD is slop”, and start hill climbing on this much harder task.

For a more thorough exploration of the weaknesses in conventional benchmarks, see the PEARL technical report.

PEARL tops OpenBind

Which makes what happened next all the more striking. Near the end of the podcast, we talked about a recent “proof-is-in-the-pudding” moment for Genesis — evaluating their PEARL model on a recently released OpenBind benchmark. This benchmark featured 802 never before seen co-complexes on a target protein EV-A71. This target seems almost custom-chosen to give most classical docking methods a problem. When a ligand binds to the main binding site, the protein moves around to close off the path the ligand used to enter the binding pocket. This process, known as “induced fit” is notoriously hard for traditional methods to model. The tradeoff is easy to understand: treating the protein as a static structure, it becomes difficult to place a ligand in a binding pocket. Treat the protein as dynamic, and now you have to simulate complicated processes that take a long time to resolve.

PEARL was able to model the induced fit of the ligand without running long MD simulations. Across the different evaluation metrics, PEARL came out not just ahead, but oftentimes well ahead of any public model. A truly impressive result.

“Where PEARL was exceptionally good is figuring out how to move this loop. We are basically correct for every single pose.” — Sergey Edunov

Even more exciting, this was done without any fine-tuning, or using any data on the target or homologous targets — the template PDB was released after PEARL’s training cutoff.

Where does co-folding go now?

As someone who has followed or participated in ML techniques for protein-ligand interactions for almost a decade, I was genuinely impressed with the results that Genesis has released recently. This has been many years in development, and I’m sure Evan and the team had many sleepless nights trying to get to this point. I also think other teams are making similar progress — both Isomorphic and Deep Origin have released results that seem spiritually similar and combine computation, wetlab data, ML, to achieve genuine predictive power that seemed impossible a decade ago. Sadly, all of the above are closed source so there’s no way to honestly compare them. Looking at the results I think there might be a time in the not so distant future where we can consider protein-ligand binding “solved”.

I sincerely hope that the academic community can take inspiration from these developments. Once you know something can be done, it’s much easier to execute. Still, I believe that the key enabler in all of the above was the tight integration of ML, large-scale computation, and real-world drug discovery applications. Sadly academia is just not structured in a way that makes such a development easy.

With those parting thoughts, we hope you give the podcast a listen!

1

At the time called Genesis Therapeutics

2

Now called Numerion

3

ADMET stands for Absorption, Distribution, Metabolism, Excretion, and Toxicity. This set of about 30 properties all need to be optimized in order for a molecule to be considered a “good drug”.

💾

  •  
❌