
 Login

Federated Learning Without the Refactoring Overhead Using NVIDIA FLARE
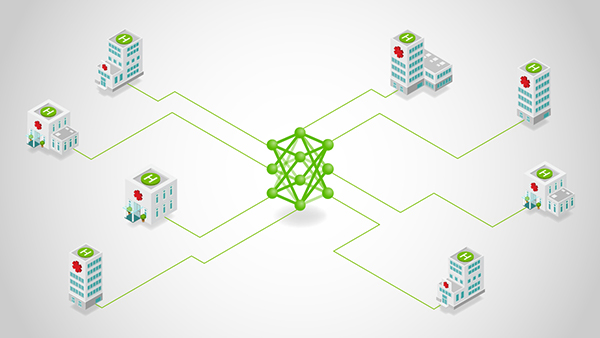 Federated learning (FL) is no longer a research curiosity—it’s a practical response to a hard constraint: the most valuable data is often the least movable....
Federated learning (FL) is no longer a research curiosity—it’s a practical response to a hard constraint: the most valuable data is often the least movable. Regulatory boundaries, data sovereignty rules, and organizational risk tolerance routinely prevent centralized aggregation. Meanwhile, sheer data gravity makes even permitted transfers slow, expensive, and fragile at scale.
 When you’re writing CUDA applications, one of the most important things you need to focus on to write great code is data transfer performance. This applies to...
