
 Login

Memory-Enforced GPU Sharing in Kubernetes with NVIDIA CUDA 13.4
 Many AI workloads need only a fraction of a GPU. Giving each one an entire device can leave capacity idle; sharing GPUs lets platform teams serve more workloads...
Many AI workloads need only a fraction of a GPU. Giving each one an entire device can leave capacity idle; sharing GPUs lets platform teams serve more workloads with the infrastructure they already have. NVIDIA GPUs already support several approaches to sharing. Multi-instance GPU (MIG) splits a GPU into hardware-isolated instances that are transparent to the application…
 AI Factories are some of the most technologically complex operational environments ever created. Hundreds of thousands of GPUs, NVIDIA Spectrum-X Ethernet...
 Training large-scale AI models on thousands of GPUs is a high-stakes operation where monitoring and automation must be built-in to optimize cluster resiliency...
 The Global Performance Tuner is a feature for automatic performance tuning released in NVIDIA TensorRT 11.1. It provides automatic, accuracy-aware and...
 Deploying a trained neural network involves more than translating each operator into a GPU kernel. It is a compilation problem with many legitimate answers. For...
 GPU applications are processing ever-growing datasets with increasingly powerful accelerators. According to the 2025 Stanford AI Index, compute for notable AI...
 Protein design is a search problem. Choose amino acids for an eight-residue protein sequence and more than 25 billion combinations are possible. Choose amino...
 Building an AI factory digital twin requires developers to bring site plans, equipment assets, and engineering requirements into a consistent model that teams...
 AI factories turn energy into intelligence. But before an AI workload can produce its first token, operators must bring an interconnected system of compute,...
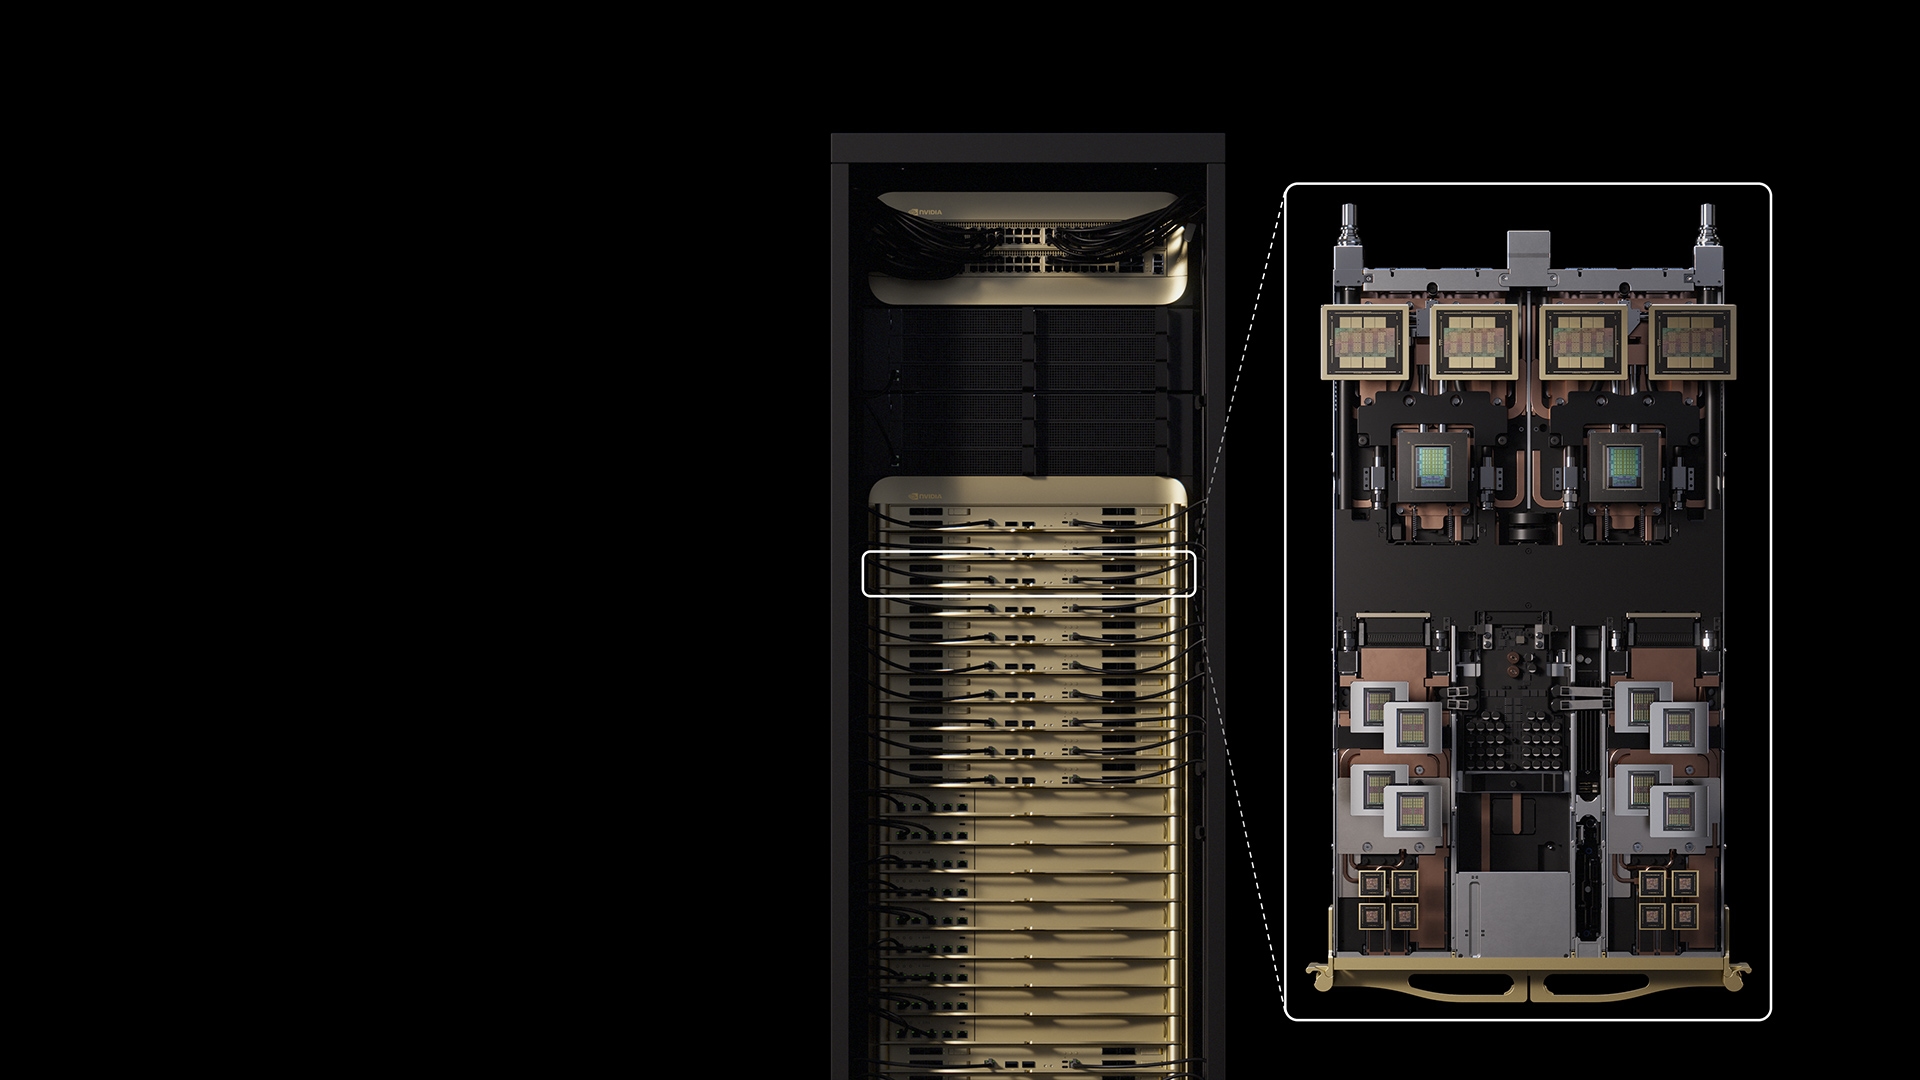
 NVIDIA is making the full NVIDIA Run:ai platform available as open source software, giving customers, developers, and ecosystem partners access to...
 Bitwise determinism makes large-scale pretraining easier to debug, validate, and resume reproducibly. These benefits become especially valuable when training...
 AI factories are some of the most complex operations in the world, combining GPUs, CPUs, switches, DPUs, and SuperNICs alongside schedulers, orchestration...
 GPU applications increasingly need networking and data movement to behave like first-class GPU-controlled operations rather than host-driven services. When the...
 GPU-accelerated Kubernetes clusters depend on compatible versions across dozens of components, each on its own release cycle: host kernels, GPU drivers,...
 GPU applications increasingly consist of multiple independent components running at the same time within a single process: a latency-sensitive operator...
 AI agents are becoming a standard part of development workflows, but general-purpose agents weren't built with specialized infrastructure software such as...
